# Overview

ODD is an open-source, community-driven data discovery platform — ML-first, end-to-end microservices lineage, flexible data quality integration, and catalogs ML experiment metadata and lineage.

## About ODD

The open-source Data Discovery Platform improves productivity, collaboration, and governance of modern data products and teams:

* Free open-source and community-driven
* ML first citizen
* End-to-end microservices lineage support
* Flexible data quality integration options
* ML experiment metadata and lineage cataloged end-to-end (generated by the collectors, rendered in the catalog)

To use Platform solutions more effectively apply [**ODD Specification**](https://github.com/opendatadiscovery/opendatadiscovery-specification/blob/main/specification/specification.md). It contains best practices for managing your metadata. Its theoretical topics and examples help to build an effective data discovery process. Also the Spec covers data engagement and data federation problems.

### The platform for your business

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-3d23aeec284e2b3ff1d91b3dbfd7adde88baf59a%2Faudience.png?alt=media) ODD's **target audience** is any data team regardless of its' size. It can be enterprises or large-scale companies challenging data mesh concept, small and mid-scale companies seeking OSS data catalogue solution and also DS teams aiming at better data governance.\
\
![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-e2996884869ca3c2313143d1d898221a571484c4%2Falltogether.png?alt=media) **An ecosystem for all data team members**. Platform functionality covers requirements of Data Scientists and Engineers, Product and Project Managers as well as Data Analysts, Architects, QA and BI Engineers.

### Solution matrix

ODD can benefit a team at the following SDLC stages and team functions:

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-90a3947df89294293ba31d651edb0e5e5c3d6176%2Fsdlc.png?alt=media)

## Pain points

### Onboarding to data

Every time a newcomer joins a data team, one faces a challenge of data management processes learning. Unfortunately, it may provoke overcommunication, reading irrelevant documentation and spending much time to pick out meaningful information.\
ODD solutions help figure out data sources, find owners of this data, check DBs structures and get many other attributes that are necessary for working activities.

### Data discovery

The more data a team has the more complicated connections occur between assets and components. ODD provides a search tool with AI-powered suggestion and flexible filters. Also the Platform supports a description option, so you can get detailed info about data entities.

### Data observability

A problem of observability lack starts when irrelevant data appears in one's production cycle. To clarify when and where this data is and avoid delay use ODD's lineage diagram and flexible alert system.

## Features

Dive into ODD opportunities with a [list of ODD features](/features/features).

## Use cases

See the [most popular use cases](/use-cases/use-cases) for different titles of your data team.


# Main Concepts

Core vocabulary and mental model for the Open Data Discovery project — what the pieces are, how they fit together, and where to dive deeper.

This page introduces the core vocabulary of the Open Data Discovery (ODD) project. It is a **map** — each concept gets a short definition and a link to its canonical deep-dive page.

> **Not the Business Glossary.** ODD Platform ships an in-app **Business Glossary** feature (term entities you can link to datasets, term-to-term relationships, ownership). That is a different thing from this docs page. See the [Business Glossary](/features/data-glossary/business-glossary) feature page for the product feature.

## The architecture chain

Metadata flows from data systems into the platform along two paths — **pull** (a collector polls the source) and **push** (an adapter embedded inside the source's runtime emits directly to the platform):

* **Pull path:** Data source ← Pull adapter (wrapped as a **Plugin** inside a **Collector**) → ODD Platform
* **Push path:** Data source's application runtime → **Push adapter** → ODD Platform

The producer-side concepts:

* **Data source** — a system holding data or data-adjacent metadata: a database, a warehouse, a BI tool, an ML training registry, an orchestrator.
* **Adapter** — a set of scripts that map metadata from a source system (PostgreSQL, MySQL, Airflow, Kafka, …) to the ODD specification — Data Entities, data types, lineage edges, quality tests. An adapter's job is **extract-and-map**, nothing more. Adapters come in two flavours: **pull** (reads from the source on a schedule) and **push** (emits from inside the source's runtime). An adapter never runs alone; it is either hosted by a collector (pull) or packaged as a push adapter (push).
* **Plugin** — a *configured* adapter instance inside a collector. One plugin carries one adapter's connection and schedule settings (source host, database, credentials, cadence). A single collector can host many plugins — multiple instances of the same adapter type (e.g., two PostgreSQL plugins pointing at different hosts or databases) or plugins for different adapter types.
* **Collector** — a container of **pull** adapters plus the runtime around them: adapter launcher, logging system, Platform-API client, configuration reader, scheduling. A collector is what you deploy; the pull adapters inside it are the mappers, and each one is configured via a plugin. The canonical implementation is `odd-collector` with 40+ bundled pull adapters; specialist collectors exist for AWS, GCP, Azure, and data profiling. A collector is **not** a synonym for "pull adapter". The collector authenticates to the platform with a static, plaintext shared-secret token (no expiry, no overlap window — rotating it instantly breaks the running collector until it is reconfigured); see [Build and run collectors](/developer-guides/build-and-run/build-and-run-odd-collectors) for the token's full security contract.
* **Push adapter** (also known as **push-client**) — a push-strategy adapter; the source initiates the data flow and the adapter knows the platform's endpoint. Push adapters ship in three deployment shapes:

  * **In-process plugin / extension** — embedded in the source system's own runtime: a dbt plugin, a Great Expectations checkpoint action, an Airflow plugin, a Spark listener. The most common shape today.
  * **Standalone gateway** — a separate service that source systems push to (today's only example: [`odd-tracing-gateway`](/integrations/integrations/odd-tracing-gateway), which receives OpenTelemetry traces). Operator-mental-model is "push"; the Platform-side leg is a pull hidden behind the gateway's standalone deployment.
  * **Direct SDK / CLI use** — push via a CLI or library call from custom code (`odd-cli` invocation, custom Python using `odd-models-package`).

  All three shapes are extract-and-map adapters; what differs from a pull adapter is deployment topology — the adapter does not live in a collector container.
* **ODD Platform** — the central server: stores the metadata, provides search, lineage, ownership, alerts, DQ dashboards, and the UI.

Pick **pull** when the source is a data store and you want point-in-time snapshots on a cadence — most data-source integrations work this way, since the source is passive and the collector drives. Pick **push** when the source is an application already running code we can instrument — Airflow DAGs, dbt runs, Spark jobs, Great Expectations validations — and you want each run's lineage and results reported as they happen. Some ecosystems combine both: a pull collector indexes the catalog while a push-client reports per-run lineage.

See [Architecture.md](/introduction/architecture) for the diagram, [developer-guides/build-and-run/build-and-run-odd-collectors.md](/developer-guides/build-and-run/build-and-run-odd-collectors) for deployment detail, and the [specification's push-model note](https://github.com/opendatadiscovery/opendatadiscovery-specification/blob/main/specification/specification.md#push-model) for protocol-level detail.

## ODDRN

**ODDRN** (**Open Data Discovery Resource Name**) is the unique, stable string that identifies every entity in the system — a dataset, a column, a data source, a pipeline run, a transformer. Producers (collectors, push adapters, custom agents) must generate an ODDRN for each entity they report so the platform can recognise the same entity across ingests, across producers, and over time. ODDRNs are what make cross-system lineage possible.

**Format.** Every ODDRN starts with a double slash and the data-source family, followed by the connection coordinates that uniquely locate the entity in the world — host for self-hosted databases, AWS account ID + region for cloud services, etc. The format follows REST URL conventions:

```
//postgresql/host/1.2.3.4/databases/ex_database/schemas/public/table/ex_table
```

where:

* `1.2.3.4` — the PostgreSQL instance host
* `ex_database` — the target database
* `public` — the target schema
* `ex_table` — the target table

**Usage.** ODDRNs power the [Ingestion API](#odd-specification) — the same string identifying the same entity across ingests is what lets the platform decide whether to create new entities, update existing ones, or delete obsolete ones on each payload. Operators rarely see ODDRNs directly; they become relevant when writing a custom agent. To assist, ODD ships open-source generator libraries for [Python](https://pypi.org/project/oddrn-generator/) and [Java](https://mvnrepository.com/artifact/org.opendatadiscovery/oddrn-generator-java); the [Build a custom collector](/developer-guides/build-and-run/custom-collectors) walkthrough covers the Python pattern end-to-end, including which `Generator` subclass to use per source family.

**Known limitation.** All consumers of the Ingestion API must use the **same** ODDRN string for the **same** entity. Since ODDRNs encode connection coordinates, this means agents reporting on the same data infrastructure must agree on hostnames or static IPs — coordinate identifiers across your deployment if multiple agents touch the same source.

A malformed ODDRN does not fail loudly on the consumer side: an entity whose ODDRN prefix the platform cannot recognise as a known data-source family is grouped under a catch-all **Other** bucket in the [Directory](/features/data-discovery/directory) browse view rather than under its real source type. Generate ODDRNs with the producer-side libraries above, which enforce the format; a typo in a hand-built ODDRN surfaces as a misfiled entity, not an error.

## ODD Specification

The [**ODD Specification**](https://github.com/opendatadiscovery/opendatadiscovery-specification) is the wire contract between producers (collectors, push-clients) and the platform — the Ingestion API schema. It decouples the two sides: any producer that speaks the specification can feed any compliant platform. This is what makes custom agents and third-party collectors possible.

## Data Governance map

A structured view of how ODD's functionality maps onto recognised data governance pillars. Use this to answer "does ODD do X?" for your governance framework.

* **Data Discovery** — *available.* The core of the platform: catalog search with multiple facets, entity pages (datasets, transformers, consumers, quality tests, ML models), tags, ownership, and the Directory view. See the [Data Discovery](/features/data-discovery) pillar landing for the four entry paths (Search, Directory, Tagging, Data Entity Groups & Domains) and the Catalog Overview home page.
* **Data Lineage** — *available.* Upstream and downstream lineage across the full entity model, not just datasets — pipelines, ML experiments, and quality tests all participate, plus microservices traced through OpenTelemetry. See the [Data Lineage](/features/data-lineage) pillar landing.
* **Data Quality** — *available.* Per-entity test results surfaced on entity pages, the catalog-wide Data Quality dashboard, and operator-set Minor / Major / Critical SLA statuses. See the [Data Quality](/features/data-quality) pillar landing and [Visibility for Data Quality Engineer](/use-cases/use-cases/dq-visibility).
* **Data Modeling** — *partially available.* [Data Entity Groups](/features/data-discovery/groups-domains) (DEGs) for logical grouping and entity relationship / ERD views today. Schema evolution signals (backwards-incompatible change triggers) are surfaced in alerts. See [Dataset schema diff](/features/data-discovery/schema-diff) and the [Data Modelling](/features/data-modelling) pillar.
* **Data Glossary** — *available.* The in-app **Business Glossary** feature — term entities with term-to-term and term-to-data-entity linking, ownership, tags. Distinct from this Main Concepts page: Business Glossary is a product feature, Main Concepts is documentation. See the [Data Glossary](/features/data-glossary) pillar landing and the [Business Glossary](/features/data-glossary/business-glossary) reference.
* **Master Data Management (incl. Reference Data Management)** — *partially available.* **Lookup Tables** provide operator-managed reference data as first-class entities in the catalog. Full MDM semantics (golden records, survivorship rules, stewardship workflows) are not part of ODD today — what ships is reference-data management. See the [Master Data Management](/features/master-data-management) pillar landing and the [Lookup Tables](/features/master-data-management/lookup-tables) feature page.
* **Data Cost** — *roadmap.* Cost attribution to datasets, pipelines, and owners is not implemented today.
* **Data Security (governance-level)** — *roadmap.* Data classification, sensitivity tagging, PII/PHI handling, and fine-grained data-access control sit on the roadmap. **This is different from platform-access security** (who can log in, what roles they have, what policies apply to the UI/API) — that is already shipped and documented under [configuration-and-deployment/enable-security/README.md](/configuration-and-deployment/enable-security).

### Pillar differentiation

The six available / partially-available pillars are conceptually distinct because each captures a different *operator workflow*:

* **Data Discovery** is **location-oriented** — finding existing entities by search, browse, or home-page surfacing. Entities come from collectors and push adapters; this pillar provides the navigation paths into the catalog.
* **Data Modelling** is **contract-oriented** — describing how a dataset is queried ([Query Examples](/features/data-modelling/query-examples)) and connected ([Relationships / ERDs](/features/data-modelling/relationships)). The dataset itself comes from outside; the platform records intent and structure on top.
* **Master Data Management** is **operator-curated reference data** — the canonical lookup tables managed inside the platform. There is no external source; the platform is the system of record.
* **Data Lineage** is **connection-oriented** — describing how entities flow into and out of each other across pipelines and microservices. The lineage is the cross-pillar record because every entity has a structure, a meaning, a location, a quality signal, *and* a lineage.
* **Data Glossary** is **meaning-oriented** — naming and describing the concepts the data represents. Terms are first-class catalog entities with their own lifecycle, ownership, RBAC, and search surface; not metadata attached to other entities.
* **Data Quality** is **correctness-oriented** — test results, anomaly classes, dataset SLAs. Every catalogued dataset has a quality story, even if it is only "no checks defined".

That difference shows up in where the data lives: Data Modelling artefacts attach to existing entities; Master Data artefacts *are* entities (Lookup Tables exist as Data Entities of type `LOOKUP_TABLE`); Data Quality results are pushed in by external frameworks; Lineage edges are computed from the connection graph. The six pillars sit alongside each other in the Data Governance map above, not nested.

## AI aspects

ODD integrates AI/GenAI capabilities in a few places:

* **GenAI assistant** — opt-in proxy from a single platform endpoint to an external AI service the operator runs (the platform does not embed an LLM). API-only today. One naming hazard worth flagging here: `genai.request_timeout` is the **wait-for-model-response** timeout (in minutes) — how long the platform waits for the external service's reply, not a send/request budget — and it is read once at startup, so a change requires a restart. See the [GenAI assistant](/features/active-platform-features/genai) page for configuration, the external service contract, and operator caveats.
* **Data profiling** — automatic statistical profiles for datasets (null ratios, distributions, cardinality) via `odd-collector-profiler`. Surfaces on entity pages.
* **ML experiment / model lineage** — experiments and trained models are first-class entities with their own lineage edges; useful for reproducibility and governance of ML pipelines.

## Terms & Aliases

A living record of synonyms and aliases users may search for. If you know a feature by a different name, start here.

| Canonical term                        | Also known as                                                                                        | What it is                                                                                                                                                                                                                                                                                                                                                                                                                           | Details                                                                                                                                 |
| ------------------------------------- | ---------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | --------------------------------------------------------------------------------------------------------------------------------------- |
| Server-to-server (S2S) authentication | Machine-to-machine (M2M) tokens, M2M auth                                                            | Static API-key authentication for programmatic clients                                                                                                                                                                                                                                                                                                                                                                               | [s2s.md](/configuration-and-deployment/enable-security/authentication/s2s)                                                              |
| Ingestion authentication filter       | Ingestion filter, ingestion API key                                                                  | Token-based auth for `/ingestion/**` — independent of UI auth, off by default                                                                                                                                                                                                                                                                                                                                                        | Ingestion authentication in [Enable security](/configuration-and-deployment/enable-security)                                            |
| Collector secrets backend             | Alternative secrets backend                                                                          | Store collector credentials in an external secret store (AWS SSM) instead of YAML                                                                                                                                                                                                                                                                                                                                                    | [collectors-secrets-backend.md](/configuration-and-deployment/collectors-secrets-backend)                                               |
| Health endpoint                       | Health check, healthcheck, monitoring endpoints, liveness/readiness probe target, `/actuator/health` | Unauthenticated Spring Boot Actuator endpoint reporting platform health; the probe target for load balancers and Kubernetes. Sibling `/actuator/prometheus` serves runtime metrics.                                                                                                                                                                                                                                                  | [Health and monitoring](/configuration-and-deployment/health-and-monitoring)                                                            |
| ODDRN                                 | Open Data Discovery Resource Name                                                                    | Stable string identifying every entity in the system                                                                                                                                                                                                                                                                                                                                                                                 | [ODDRN section above](#oddrn)                                                                                                           |
| Business Glossary (feature)           | Glossary, Terms                                                                                      | In-app feature for managing term entities and linking them to datasets — not this Main Concepts page                                                                                                                                                                                                                                                                                                                                 | [Business Glossary](/features/data-glossary/business-glossary) under [Data Glossary](/features/data-glossary)                           |
| Data Entity Group                     | DEG                                                                                                  | Logical grouping of data entities inside the catalog                                                                                                                                                                                                                                                                                                                                                                                 | [Data Entity Groups & Domains](/features/data-discovery/groups-domains) under [Data Discovery](/features/data-discovery)                |
| ML Experiments                        | ML Experiment Logging (deprecated)                                                                   | A Data Entity Group collecting the entities produced by one training run — inputs, jobs, models, artifacts. Catalog view, not a metrics tracker.                                                                                                                                                                                                                                                                                     | [Data Entity Groups & Domains → Relationship to ML Experiments](/features/data-discovery/groups-domains#relationship-to-ml-experiments) |
| ODD Specification                     | Ingestion API spec, ingress API                                                                      | Wire contract between producers and the platform                                                                                                                                                                                                                                                                                                                                                                                     | [opendatadiscovery-specification](https://github.com/opendatadiscovery/opendatadiscovery-specification)                                 |
| Integration                           | —                                                                                                    | Umbrella term for any path metadata takes from a source into the Platform — collectors (pull) and push adapters (push). Prefer in user-facing prose unless direction (pull/push) matters.                                                                                                                                                                                                                                            | [Integrations hub](/integrations/integrations)                                                                                          |
| Adapter                               | —                                                                                                    | Source→spec mapper (push or pull); extract-and-map only, never runs alone. Classified by **strategy** (pull / push) and **deployment shape**.                                                                                                                                                                                                                                                                                        | [The architecture chain](#the-architecture-chain)                                                                                       |
| Pull adapter                          | —                                                                                                    | Pull-strategy adapter — reads from the source on a cadence; the adapter knows the source endpoint and credentials. Today always paired with the collector-hosted deployment shape (configured via a plugin).                                                                                                                                                                                                                         | [The architecture chain](#the-architecture-chain)                                                                                       |
| Plugin                                | Adapter instance, adapter config                                                                     | A configured pull-adapter instance inside a collector. Push adapters do not use the plugin term.                                                                                                                                                                                                                                                                                                                                     | [The architecture chain](#the-architecture-chain)                                                                                       |
| Collector                             | Pull-adapter container (informal)                                                                    | Container of pull adapters + runtime; the collector-hosted deployment shape. **Not** a synonym for "pull adapter".                                                                                                                                                                                                                                                                                                                   | [The architecture chain](#the-architecture-chain)                                                                                       |
| Push adapter                          | Push-client (client-server framing)                                                                  | Push-strategy adapter — the source initiates the data flow. Three deployment shapes: **in-process plugin / extension** (dbt, GE, Airflow, Spark), **standalone gateway** (`odd-tracing-gateway`), **direct SDK / CLI use** (`odd-cli`). Used when the discussion is about extract-and-map mechanics.                                                                                                                                 | [The architecture chain](#the-architecture-chain)                                                                                       |
| Push-client                           | Push adapter (extract-and-map framing)                                                               | Same component as **Push adapter**, framed from client-server topology — a producer-side client of the Platform server using push strategy. Used when the discussion is about deployment topology or network position.                                                                                                                                                                                                               | [Architecture.md](/introduction/architecture)                                                                                           |
| Standalone gateway                    | Push-adapter standalone shape, OTel gateway, tracing gateway                                         | A push-adapter deployment shape: a separate service that source systems push to over an externally-defined wire protocol (today: OpenTelemetry/OTLP), with the Platform pulling the inferred entities. Today's only example is [`odd-tracing-gateway`](/integrations/integrations/odd-tracing-gateway). Distinct from in-process plugins (which live inside a source tool's runtime) and from collectors (which host pull adapters). | [`integrations/auxiliary/odd-tracing-gateway.md`](/integrations/integrations/odd-tracing-gateway)                                       |
| Catalog Overview page                 | Overview page, Main page, Data Entity Report (deprecated as page synonym)                            | The catalog's home page — main search, top tags, domains, the per-class **Entities** report, directory, and (when auth is on) owner association. Distinct from a data entity's own **Overview tab**, which is the per-entity landing view inside a detail page.                                                                                                                                                                      | [Data Discovery](/features/data-discovery) (the bucket landing the home page surfaces)                                                  |
| Master Data Management                | MDM, Reference Data Management, Reference Data                                                       | The Data Governance pillar covering operator-curated reference data managed inside the platform. ODD ships the Reference-Data subset (Lookup Tables); golden records / survivorship / stewardship workflows are not part of ODD today.                                                                                                                                                                                               | [master-data-management.md](/features/master-data-management)                                                                           |
| Lookup Tables                         | Reference tables, Master Data tables                                                                 | Operator-curated reference tables managed inside the platform — schema, data, RBAC, API surface. Exposed in the catalog as Data Entities of type `LOOKUP_TABLE`. UI section: **Master Data** top-level tab.                                                                                                                                                                                                                          | [lookup-tables.md](/features/master-data-management/lookup-tables)                                                                      |
| Slack alert webhook                   | Slack notifications, Slack incoming webhook                                                          | Outgoing-only HTTP POST of alert messages into a Slack channel via `notifications.receivers.slack.url`. One-way write — no thread state, no replies read back. **Distinct** from the Slack collaboration app. Consumer: `SlackNotificationSender` (gated by `@ConditionalOnProperty(name = "notifications.receivers.slack.url")`).                                                                                                   | [Enable Alert Notifications](/configuration-and-deployment/odd-platform#enable-alert-notifications)                                     |
| Slack collaboration app               | Slack Events API, Slack OAuth integration, Data Collaboration Slack                                  | Full Slack app for in-app per-entity discussion threads — OAuth (`datacollaboration.slack-oauth-token`) plus the [Slack Events API](https://docs.slack.dev/apis/events-api/) webhook to read replies back into the platform; bidirectional. **Distinct** from the Slack alert webhook. Routes gated by `@ConditionalOnDataCollaboration` (returns `404 Not Found` when `datacollaboration.enabled=false`).                           | [Enable Data Collaboration](/configuration-and-deployment/odd-platform#enable-data-collaboration)                                       |
| Multilingual UI                       | i18n, internationalisation, locale switching, language switching                                     | Seven-locale (en/es/ch/fr/ua/hy/br) UI shell translation bootstrapped at SPA startup; the active locale persists per browser device in `localStorage`. API surface and operator-authored content stay in their source language.                                                                                                                                                                                                      | [Multilingual UI](/features/multilingual-ui)                                                                                            |

New aliases get added as they're discovered. If you notice a term that is missing or ambiguous, open an issue or a PR — the goal is that searching any common name lands you on the right page.


# Architecture

The structural mental model of an Open Data Discovery deployment — five-stage data flow, the components that run where, and the architectural concerns that cross every component.

This page is the **structural mental model** of an Open Data Discovery deployment — what runs where, how metadata flows from a source system to a user's screen, and which architectural concerns cross every component. It is the front door before [Features](/features/features), [Integrations](/integrations/integrations), and [Configure ODD Platform](/configuration-and-deployment/odd-platform). For the producer-side vocabulary used here (Adapter, Plugin, Collector, Push adapter), see [Main Concepts → The architecture chain](/introduction/main-concepts#the-architecture-chain); this page operates in **client-server topology framing** (Push-client, Collector, Platform, Server).

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-afdf516ec0a91c5436272691485be0e37b834cb4%2Farchitecture_collector.png?alt=media)

## Data flow

Metadata moves through five stages between a source system and a catalog user:

1. **Produce.** A source system has metadata that needs to surface in the catalog — a database schema, a job graph, a dbt manifest, a Spark lineage event, a Lookup-Table row.
2. **Ingest.** A producer (Collector or Push-client) sends metadata to the platform's Ingestion API. Pull producers (Collectors) poll on a schedule; push producers (in-process plugins, gateways, SDK callers) emit on the source's own cadence. Both speak the [ODD Specification](https://github.com/opendatadiscovery/opendatadiscovery-specification) — the wire contract.
3. **Store.** The platform writes the metadata to PostgreSQL keyed by [ODDRN](/introduction/main-concepts#oddrn). Same-ODDRN means same entity across ingests, across producers, over time — that is what makes cross-system lineage possible.
4. **Query.** UI calls and external scripts hit the Platform API (`/api/...`). Reads serve the catalog (search, lineage, alerts, glossary, query examples, relationships); writes mutate the catalog (ownership, tags, alert status, halt configuration, lookup-table rows). See the [API Reference hub](/developer-guides/api-reference) for the full surface.
5. **Render.** The platform UI (served from the same process) renders the catalog: search, entity pages, lineage graphs, alert tabs, the Directory drill-down, the Catalog Overview home page.

The Push-client / Collector split is **only at stage 2** — every later stage is identical regardless of which producer family fed the catalog.

## Deployment topology

| Component                            | What it is                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                   | What an operator deploys                                                                                                     | Configuration home                                                                                                                        |
| ------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | ---------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------- |
| **Platform (Server)**                | The Spring-Boot application: Ingestion API, Platform API, UI, scheduled jobs (housekeeping, alerting, data-collaboration sender).                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                            | One Platform process plus PostgreSQL.                                                                                        | [`configuration-and-deployment/odd-platform.md`](/configuration-and-deployment/odd-platform).                                             |
| **Collector**                        | Container of **pull** adapters plus the runtime around them (adapter launcher, logger, Platform-API client, scheduler). The canonical implementation is [`odd-collector`](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector); cloud-specific siblings are [`odd-collector-aws`](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-aws), [`odd-collector-azure`](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-azure), [`odd-collector-gcp`](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-gcp), and [`odd-collector-profiler`](https://github.com/opendatadiscovery/odd-collector-profiler). | One Collector container per cloud / source-family group, each holding many configured **plugins** (one per source instance). | [`developer-guides/build-and-run/build-and-run-odd-collectors.md`](/developer-guides/build-and-run/build-and-run-odd-collectors).         |
| **Push-client (in-process plugin)**  | A push-strategy adapter that runs **inside** the source system's runtime — a dbt plugin, an Airflow plugin, a Great Expectations checkpoint action, a Spark listener, an `odd-cli` invocation.                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                               | Installed alongside the source application; emits metadata on the source's own cadence.                                      | Per-tool repos under [opendatadiscovery on GitHub](https://github.com/opendatadiscovery); see [Integrations](/integrations/integrations). |
| **Push-client (standalone gateway)** | A push-strategy adapter that runs as its own service. Source systems push over an externally-defined wire protocol (today: OpenTelemetry/OTLP for [`odd-tracing-gateway`](/integrations/integrations/odd-tracing-gateway)); the gateway processes the input and exposes the inferred entities for the Platform / a collector to pull through the standard adapter-contract entities API.                                                                                                                                                                                                                                                                                                                     | One gateway process per network perimeter that needs aggregated push ingress.                                                | [`integrations/auxiliary/odd-tracing-gateway.md`](/integrations/integrations/odd-tracing-gateway).                                        |
| **UI**                               | Single-page React application served from the Platform process at `/`.                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                       | Same process as the Platform — operators do not deploy the UI separately.                                                    | (Configured indirectly through `odd.platform-base-url`; see [Configure ODD Platform](/configuration-and-deployment/odd-platform).)        |

Centralised: the Platform (one server, one PostgreSQL) and the UI (served from the same process). Distributed: every Collector and every Push-client lives in or beside its source system. The reason ODD scales to many sources is that the producer side is horizontally distributable while the catalog stays a single coherent surface.

## Cross-cutting concerns

A landing-level pointer per concern; every link below has its own canonical home with the full operator detail.

* **Authentication.** UI / Platform-API auth (Disabled / Login form / OAUTH2 / LDAP) plus separate Server-to-server (S2S) tokens for programmatic clients plus an independent Ingestion-API filter for producer traffic. See [Enable security](/configuration-and-deployment/enable-security) — the three surfaces are deliberately decoupled.
* **Alerting.** Platform-detected (failed jobs, failed DQ tests, schema-incompatible changes, distribution anomalies) and externally-injected (Prometheus AlertManager via `/ingestion/alert/alertmanager`). Dispatch goes to in-app tabs, optional Slack webhook, optional email. See [Active platform features → Alerting](/features/active-platform-features/alerting) and [Active platform features → Notifications](/features/active-platform-features/notifications), with the operator-side configuration on [Configure ODD Platform → Enable Alert Notifications](/configuration-and-deployment/odd-platform#enable-alert-notifications).
* **Lineage.** Cross-system upstream / downstream graphs at entity granularity, plus group lineage for Data Entity Groups (including ML experiments). See [Data Lineage → Data Objects Lineage](/features/data-lineage/data-objects) and the [API Reference → Lineage](/developer-guides/api-reference/lineage) sub-page.
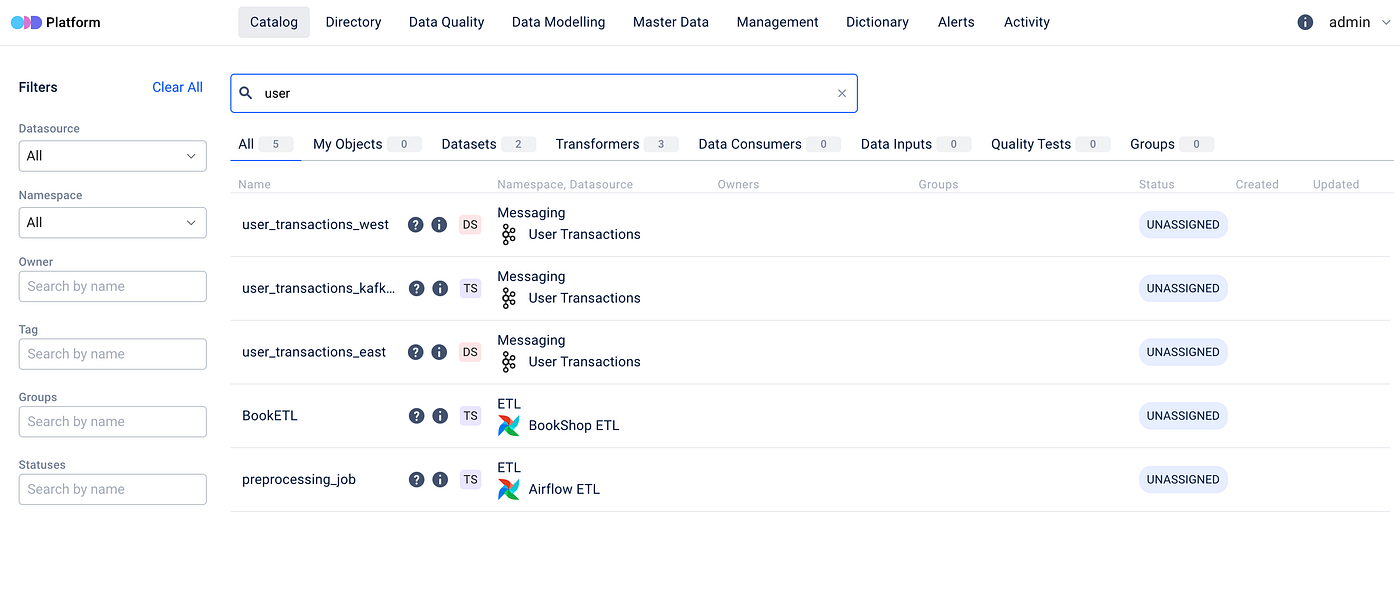
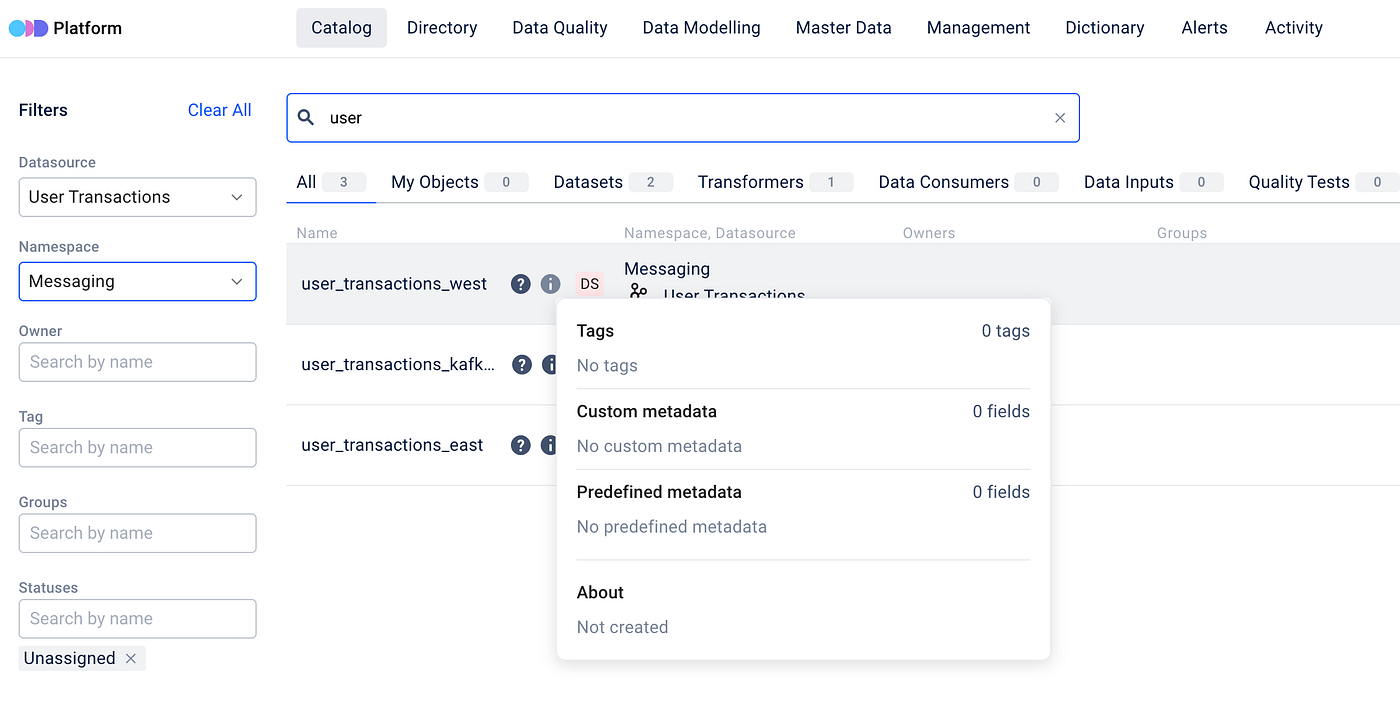
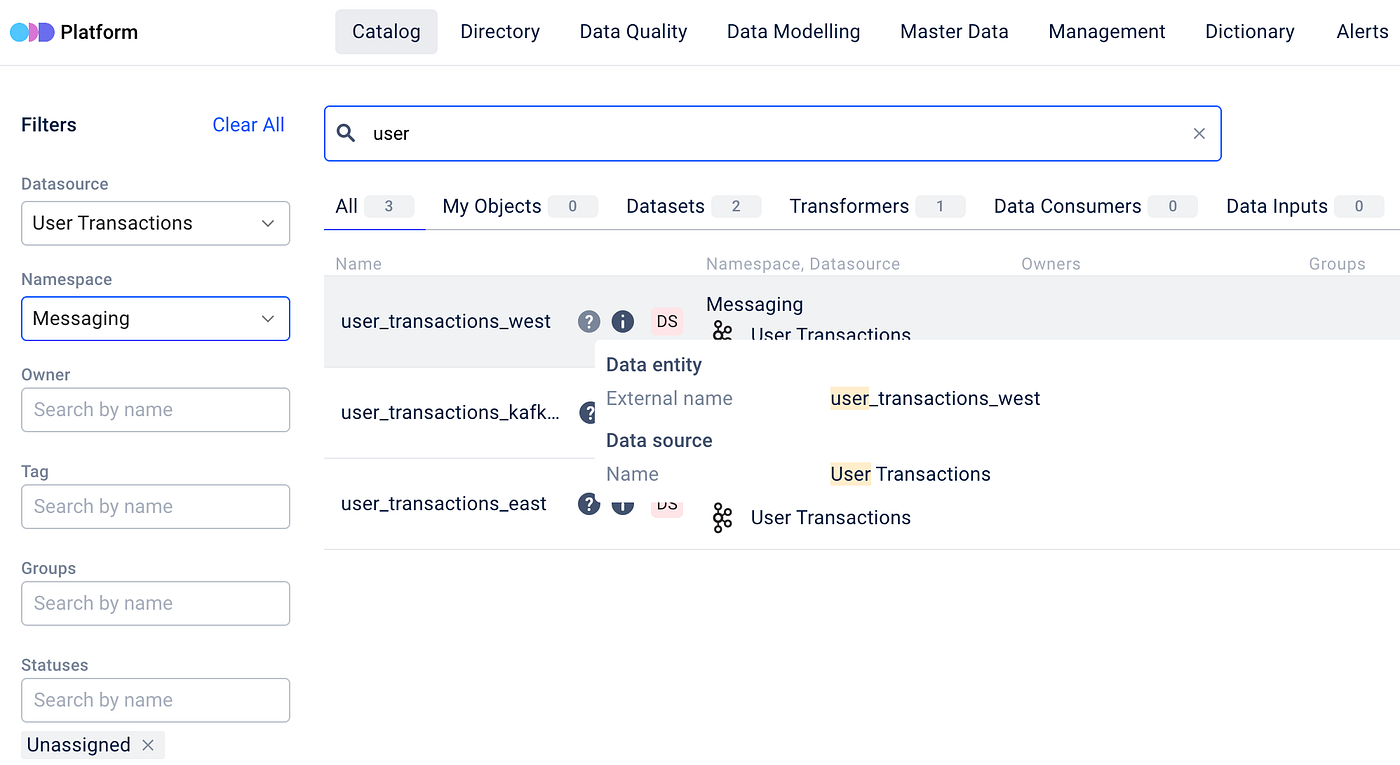
* **Search.** Free-text plus seven facets — Datasource, Type, Namespace, Owner, Tag, Groups, Statuses. Complemented by the Directory's hierarchy-driven browse. See [Data Discovery](/features/data-discovery) and the dedicated [Search and Filtering](/features/data-discovery/search) page for the per-facet semantics and the per-result transparency icons.
* **Attachments.** Per-entity files (PNG / PDF / docs) stored locally or to a REMOTE S3-compatible bucket. The default is the **local file system** at `/tmp/odd/attachments` — a path under `/tmp` that container runtimes typically wipe on restart, so attachments saved under the default do not survive a platform restart. Switch to `REMOTE` (S3-compatible) storage for any deployment where attachments must persist. See [Configure ODD Platform → Attachment storage](/configuration-and-deployment/odd-platform#attachment-storage) for the operator caveats.
* **Data Collaboration.** Optional Slack-based per-entity discussion threads (full Slack app via OAuth + Events API webhook). Distinct from the alert webhook. See [Active platform features → Data Collaboration](/features/active-platform-features/data-collaboration) and [Configure ODD Platform → Enable Data Collaboration](/configuration-and-deployment/odd-platform#enable-data-collaboration).
* **GenAI proxy.** Optional thin proxy from the platform to an external AI service the operator runs. The platform itself does not embed an LLM. See [Active platform features → GenAI assistant](/features/active-platform-features/genai).

## Pull vs Push — when to choose which

Both topologies feed the same catalog through the same Ingestion API. The choice is operational:

* **Pull (Collector)** when the source is a **passive data store** (database, warehouse, BI tool, ML registry, message broker) and you want **point-in-time snapshots on a cadence**. The Collector drives; the source has no awareness of the catalog. Most data-source integrations work this way.
* **Push (Push-client)** when the source is an **already-running application** that you can instrument — Airflow DAGs, dbt runs, Spark jobs, Great Expectations validations, your own services calling `odd-cli` — and you want **per-run lineage and results reported as they happen**. The source drives; latency from event to catalog is bounded by the producer's own emit cadence.
* **Both at once** is normal: a pull Collector indexes the warehouse catalog while an Airflow Push-client reports per-run lineage on top of it.

For the in-the-spec view of push-strategy producers, see the [push model section of the ODD Specification](https://github.com/opendatadiscovery/opendatadiscovery-specification/blob/main/specification/specification.md#push-model).

## ODDRN

**ODDRN** (Open Data Discovery Resource Name) is the stable string that identifies every entity in the system — a dataset, a column, a data source, a pipeline run. Producers generate an ODDRN for each entity they emit so the platform can recognise the same entity across ingests, across producers, and over time. ODDRN is what makes cross-system lineage possible, what makes idempotent ingests possible, and what gives the AlertManager webhook its `entity_oddrn` routing key.

Operators rarely interact with ODDRNs directly — they become relevant when authoring a custom adapter. See [ODDRN](/introduction/main-concepts#oddrn) for the format, examples, and the generator libraries for Python and Java; see [Build a custom collector](/developer-guides/build-and-run/custom-collectors) for the end-to-end Python pattern.

## Where to read the code

The mapping from this overview to the actual code lives in the workspace's navigation domain pages — `navigation/domains/{feature}.md` files maintain controller / service / configuration / UI pointers per feature so a reader does not need to grep. The contributor-facing entry points on the public doc tree are:

* [GitHub organization overview](/developer-guides/github-organization-overview) — every ODD repository with a one-line summary.
* [Build and run](/developer-guides/build-and-run) — Platform and Collector build / deploy walkthroughs, plus the [Build a custom collector](/developer-guides/build-and-run/custom-collectors) developer guide.
* [Main Concepts](/introduction/main-concepts) — the producer-side vocabulary (Adapter / Plugin / Collector / Push adapter / Data source) and the Data Governance map (which pillars ODD covers, which are roadmap).
* [API Reference](/developer-guides/api-reference) — the canonical hub for every HTTP endpoint, with per-feature sub-pages.


# Overview

One-page index of ODD Platform's most important features — a quick-scan surface that points each feature at its canonical home, API surface, and operator-configuration keys.

This page is the **one-page index** of ODD Platform's most important features — a quick-scan surface for discovering what the platform does. For step-by-step walkthroughs and configuration detail, follow the cross-links from each feature's section to its dedicated page: each feature below points at (a) its **canonical home** — for read-oriented features, one of the six governance pillars ([Data Discovery](/features/data-discovery), [Data Modelling](/features/data-modelling), [Master Data Management](/features/master-data-management), [Data Quality](/features/data-quality), [Data Lineage](/features/data-lineage), [Data Glossary](/features/data-glossary)); for operator-mutating UI workflows, the [Management](/features/management) section; for the platform's event-driven, opt-in behaviours (alerts, notifications, activity tracking, data collaboration, GenAI), the [Active platform features](/features/active-platform-features) section; (b) its **API surface** under the [API Reference](/developer-guides/api-reference) hub; and (c) its **operator-configuration keys** under [Configure ODD Platform](/configuration-and-deployment/odd-platform). For the broader vocabulary and the [Data Governance map](/introduction/main-concepts#data-governance-map), see [Main Concepts](/introduction/main-concepts).

[Metadata Storage](#metadata-storage)\
[Search and Filtering](/features/data-discovery/search)\
[End-to-end Data Objects Lineage](/features/data-lineage/data-objects)\
[End-to-end Microservices Lineage](/features/data-lineage/microservices)\
[Data Quality Test Results Import](/features/data-quality/test-results-import)\
[Alerting](/features/active-platform-features/alerting)\
[ML Experiments](/features/data-discovery/groups-domains#relationship-to-ml-experiments)\
[Manual Object Tagging](/features/data-discovery/tagging)\
[Data Entity Groups & Domains](/features/data-discovery/groups-domains)\
[Catalog Overview page](/features/data-discovery/catalog-overview)\
[Directory](/features/data-discovery/directory)\
[Dictionary terms](/features/data-glossary/business-glossary)\
[Activity Feed for Monitoring Changes](/features/active-platform-features/activity-feed)\
[Data Collaboration](/features/active-platform-features/data-collaboration)\
[Dataset Quality Statuses (SLA)](/features/data-quality/sla-statuses)\
[Dataset schema diff](/features/data-discovery/schema-diff)\
[Associating Terms with Data Entities through Descriptive Information](/features/data-glossary/business-glossary#term-to-entity-associations)\
[Adding Business Names for Data Entities and Dataset Fields](/features/data-discovery/business-names)\
[Entity description](/features/data-discovery/entity-description)\
[Custom metadata](/features/data-discovery/custom-metadata)\
[Per-column annotation](/features/data-discovery/per-column-annotation)\
[Integrating Vector Store Metadata](/features/data-discovery/vector-stores)\
[GenAI assistant](/features/active-platform-features/genai)\
[Data Modelling](/features/data-modelling)\
[Query Examples](/features/data-modelling/query-examples)\
[Relationships and ERDs](/features/data-modelling/relationships)\
[Data Quality Dashboard](/features/data-quality/dashboard)\
[Filters to Include and Exclude Objects from Ingest](/integrations/integrations/ingestion-filters)\
[Data Entity Statuses](/features/data-discovery/statuses)\
[Alternative Secrets Backend](/configuration-and-deployment/collectors-secrets-backend)\
[Lookup Tables](/features/master-data-management/lookup-tables)\
[Integration Wizards](/integrations/integrations/integration-wizard)\
[Data Entity Attachments](/features/data-discovery/attachments)\
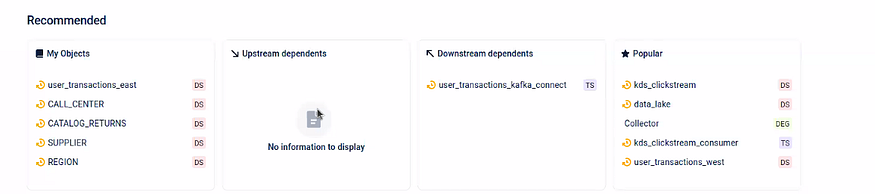
["Recommended" panel on the main page](/features/data-discovery/catalog-overview#recommended)\
[Custom navigation links](https://docs.opendatadiscovery.org/features/pages/YH2ILihhfTPfYTyBhtw2#additional-navigation-links-odd.links)\
[Metadata stale](/features/data-discovery/metadata-stale)\
[Machine-to-Machine (M2M) tokens](/configuration-and-deployment/enable-security/authentication/s2s)\
[Multilingual UI](/features/multilingual-ui)

{% hint style="info" %}
**Looking for the HTTP API?** Every Platform endpoint is documented at [API Reference](/developer-guides/api-reference) — grouped by feature area, with operation IDs, paths, and back-links to each feature page.
{% endhint %}

## Metadata Storage

The platform's metadata storage is a single PostgreSQL database that holds every catalog entity, every lineage edge, every term, and the full-text search index — no extra Elasticsearch / Solr / Neo4j services to deploy. Metadata is processed near-real-time as collectors and push adapters report it; storage capacity scales with the underlying PostgreSQL cluster.

For the deployment topology and how metadata flows from a source system to the catalog screen, see [Architecture → Data flow](/introduction/architecture#data-flow); for the operator-side configuration of the database itself, see [Configure ODD Platform → PostgreSQL Configuration](/configuration-and-deployment/odd-platform#postgresql-configuration).

## Search and Filtering

The catalog's query-oriented entry path — type a term, narrow by seven facets (Datasource / Type / Namespace / Owner / Tag / Groups / Statuses), and find data entities across names and metadata in seconds. Search is available across the Catalog, Query Examples, Master Data, Management, and Dictionary tabs.

See the dedicated [Search and Filtering](/features/data-discovery/search) page under [Data Discovery](/features/data-discovery) for the seven facets, the per-result information / question icons, and the indexing / ranking technical detail.

## End-to-end Data Objects Lineage

Upstream and downstream lineage across the full ODD entity model — datasets, transformers, transformer runs, quality tests, consumers, data inputs, data entity groups (including [ML experiments](/features/data-discovery/groups-domains#relationship-to-ml-experiments)), and entity relationships — rendered as a per-entity Lineage tab plus the dedicated Group lineage endpoint that returns the union of a [Data Entity Group](/features/data-discovery/groups-domains)'s children's lineage.

See the dedicated [Data Objects Lineage](/features/data-lineage/data-objects) page under [Data Lineage](/features/data-lineage) for the entity-class participation table, the `lineage_depth` and `expanded_entity_ids` query parameters, and the Group lineage endpoint.

## End-to-end Microservices Lineage

Microservice call lineage rendered alongside data-object lineage — sourced from OpenTelemetry traces ingested through [`odd-tracing-gateway`](/integrations/integrations/odd-tracing-gateway) (the platform's only [standalone gateway](/introduction/main-concepts#the-architecture-chain) push adapter today).

See the dedicated [Microservices Lineage](/features/data-lineage/microservices) page under [Data Lineage](/features/data-lineage) for the OpenTelemetry-to-ODD path and the gateway's role in the architecture chain.

## Data Quality Test Results Import

The Platform ingests test results from [**Great Expectations**](/integrations/integrations/odd-great-expectations) and [**dbt tests**](/integrations/integrations/odd-dbt) (both push-clients in the ODD ecosystem), plus statistical profiles generated by [**odd-collector-profiler**](/integrations/integrations/odd-collector-profiler) (which uses Capital One's [DataProfiler](https://github.com/capitalone/DataProfiler) under the hood). Custom frameworks can push their own test results through the `POST /ingestion/entities` endpoint of the [ODD Specification](/introduction/main-concepts#odd-specification).

See the dedicated [Test Results Import](/features/data-quality/test-results-import) page under [Data Quality](/features/data-quality) for the per-integration setup paths and the custom-framework escape hatch.

## Alerting

The platform watches each catalogued entity for failed jobs, failed data-quality tests, backwards-incompatible schema changes, and externally-injected distribution anomalies — and tracks every alert through an `OPEN` → `RESOLVED` lifecycle with per-entity halt configuration and four navigation views (All / My Objects / Downstream / Upstream). For the alert types and what triggers each, the lifecycle and auto-cleanup rules, the halt-notification UI and its `Distribution anomaly` caveat, and the API surface, see the dedicated [Alerting](/features/active-platform-features/alerting) page under [Active platform features](/features/active-platform-features). For how alerts get out of the platform — Slack, email, generic webhook, plus the Prometheus AlertManager inbound webhook — see [Notifications](/features/active-platform-features/notifications).

## ML Experiments

In ODD, an **ML experiment** is a [Data Entity Group](/features/data-discovery/groups-domains) of class `ML_EXPERIMENT` that collects the entities produced by a training run — input datasets, feature tables, training jobs, model instances, and resulting model artifacts — into one logical container. ML Experiments are not a separate feature surface; they reuse the DEG primitive for a specific workflow.

See [Data Entity Groups & Domains → Relationship to ML Experiments](/features/data-discovery/groups-domains#relationship-to-ml-experiments) under [Data Discovery](/features/data-discovery) for the framing, the catalog-view-not-experiment-tracker positioning, and the lineage cross-link.

## Manual Object Tagging

Lightweight labelling for data entities and columns — apply tags to drive faceted search, surface `Important`-flagged labels visually, and feed the Catalog Overview's Top tags chip strip.

See the dedicated [Manual Object Tagging](/features/data-discovery/tagging) page under [Data Discovery](/features/data-discovery) for the tag application workflow, the three `TAG_*` RBAC permissions, and the read-side / Management-side split (this page is read-side; vocabulary curation lives at [Management → Tags](/features/management)).

## Data Entity Groups & Domains

Logical containers that gather related entities (datasets, transformers, quality tests, consumers) under one umbrella with their own metadata, owners, tags, and terms. Flagging a DEG as a **domain** surfaces it on the [Catalog Overview page](/features/data-discovery/catalog-overview)'s Domains section as a top-level discovery surface.

See the dedicated [Data Entity Groups & Domains](/features/data-discovery/groups-domains) page under [Data Discovery](/features/data-discovery) for the DEG metadata model, the Domain framing, the relationship to ML Experiments, and the Group lineage cross-link.

## Catalog Overview page

The **Overview page** is the catalog's home page — a unified surface that combines [Search](/features/data-discovery/search), the [Directory](/features/data-discovery/directory) level-1 cards, [Top tags](/features/data-discovery/tagging), [Domains](/features/data-discovery/groups-domains), the per-class **Entities** report, the **Recommended** quick-jumps, and (when authentication is on) an Owner-association request.

See the dedicated [Catalog Overview page](/features/data-discovery/catalog-overview) page under [Data Discovery](/features/data-discovery) for the per-section walkthrough, the Recommended panel sub-surface, and the disambiguation between the catalog's Overview *page* and a data entity's Overview *tab*.

## Directory

The **Directory** is the catalog's browse-oriented entry point. It complements [Search](/features/data-discovery/search): where Search is query-driven, the Directory walks down a four-level hierarchy — **data source types → data sources → entity types → entities** — so an operator can drill into the catalog without typing a query. Reach for it when you know the kind of source you want to explore (PostgreSQL, Snowflake, Kafka, ...) but not the specific entity, or when you want a per-source coverage view.

See the dedicated [Directory](/features/data-discovery/directory) page under [Data Discovery](/features/data-discovery) for the level-by-level walkthrough, the four backing API endpoints (`/api/directory`, `/api/directory/datasources`, `/api/directory/datasources/{id}/types`, `/api/directory/datasources/{id}`), and the relationship to the [Catalog Overview page](/features/data-discovery/catalog-overview) (which surfaces the Directory's level-1 cards inline on the home page).

## Dictionary terms

Operator-curated term entities that name and describe the concepts your data represents. Terms are first-class catalog citizens with their own descriptions, owners, namespaces, RBAC, and links to data entities (description-text mentions and direct term-to-term links).

See the dedicated [Business Glossary](/features/data-glossary/business-glossary) page under [Data Glossary](/features/data-glossary) for the full term-creation flow, the seven `TERM_*` permissions, term-to-term linking modes, the term-to-entity descriptive walkthrough, and the API surface.

## Activity Feed for Monitoring Changes

The platform records every metadata change as a typed event on a global **Activity** page and on each entity's own **Activity** tab — entity lifecycle transitions, ownership changes, tag and term assignments, dataset-field edits, data-entity-group changes, and the alert-state transitions described above. The feed is the catalog's audit trail and its change-driven discovery surface.

See the dedicated [Activity Feed](/features/active-platform-features/activity-feed) page under [Active platform features](/features/active-platform-features) for the seven facets on the global filter panel, the full event-type catalogue (grouped by the metadata area each event describes), and the configuration entry for retention partitioning.

## Data Collaboration

ODD Platform's **Data Collaboration** feature lets users start in-app discussion threads anchored to specific data entities, with replies tracked back from a Slack workspace via OAuth + the [Slack Events API](https://docs.slack.dev/apis/events-api/). Conversations stay attached to the entity that anchored them, so an operator returning to a dataset months later can read the original threads — context, decisions, and follow-ups — without leaving the catalog. The feature is disabled by default (`datacollaboration.enabled=false`); for the per-entity Discussions-tab visibility caveat when disabled, the message-flow model, the disambiguation between this Slack app and the [Slack alert webhook](/features/active-platform-features/notifications#slack-incoming-webhook), and the operator-side setup, see the dedicated [Data Collaboration](/features/active-platform-features/data-collaboration) page under [Active platform features](/features/active-platform-features).

{% hint style="warning" %}
**Platform-feature toggles are captured at JVM boot and the top-level navigation chrome is invariant to the toggle state.** Three related properties operators should know:

* **Boot-immutable.** The active feature set is read from configuration at JVM startup (`@Value` injection on the feature resolver's constructor) and frozen for the lifetime of the process. Runtime configuration changes — for example via Spring Boot Actuator's `/actuator/refresh` endpoint — are not reflected by the platform's feature-active endpoint or by the sub-page feature gates. To change a platform feature's enabled state, edit the configuration and **restart the JVM process**.
* **Both keys must be present, or the platform fails to start.** The two feature flags `datacollaboration.enabled` and `notifications.enabled` are injected without a fallback default. A stock install is safe — the bundled `application.yml` supplies both keys set to `false` — but if you supply your own externalised `application.yml` (exactly the "edit the configuration and restart" workflow above) and **omit either key**, the platform aborts startup with an opaque `BeanCreationException: Could not resolve placeholder 'datacollaboration.enabled'` (or `notifications.enabled`). When overriding configuration, always carry both keys forward explicitly rather than copying only the line you want to change.
* **Chrome-invariant.** The platform's top-level navigation tabs (Data Modelling, Data Collaboration-flavoured surfaces, etc.) are rendered regardless of the corresponding feature-flag setting. Feature-gated functionality **inside** those tabs honours the active feature set — sub-page affordances, write endpoints, and gated panels behave correctly when the flag is off — but the tab itself stays visible. Users disabling `datacollaboration.enabled=false`, for example, still see the Data Modelling tab on the toolbar; clicking it lands on a page whose feature-gated affordances are correctly hidden, but the tab itself is not removed.

The operator-visible consequence is "the platform feature gating is consistent at the per-affordance level, not at the chrome level." Operators expecting "disabling a feature removes its tab" should know this is not how the platform's UI shell behaves today. The two configuration keys covered by this caveat are `datacollaboration.enabled` and `notifications.enabled` — the only two that flow through the boot-time feature resolver — plus any future platform-feature flag added under the same `@Value` boot-injection pattern.

**`genai.enabled` is not one of them.** Despite sitting next to the two flags above in configuration, the GenAI assistant toggle does not flow through the feature resolver: it is re-read on every call at the service layer rather than snapshotted at boot, and it is not part of the active-feature set the chrome consults. A `genai.enabled` change therefore takes effect on the next request without a restart — but, like the two flags above, it does not add or remove a top-level navigation tab.
{% endhint %}

## Dataset Quality Statuses (SLA)

Operator-set **Minor / Major / Critical** severities on dataset test results, aggregated into a single dataset-level **SLA colour** (Green / Yellow / Red) that downstream BI reports import directly via the `/api/datasets/{id}/sla` endpoint.

See the dedicated [Dataset Quality Statuses (SLA)](/features/data-quality/sla-statuses) page under [Data Quality](/features/data-quality) for the severity-setting workflow, the BI-report URL pattern, and the actual SLA-colour computation logic (which is **not** a direct severity-to-colour mapping — colours come from `SLACalculator` based on aggregate severity weights).

## Dataset schema diff

The platform compares each dataset's metadata between revisions and surfaces every change — added columns, removed columns, type changes, renames — as a visual side-by-side diff on the dataset's Structure tab. Backwards-incompatible changes additionally raise a [Backwards-incompatible schema change](/features/active-platform-features/alerting#backwards-incompatible-schema-change-what-triggers-it) alert.

See the dedicated [Dataset schema diff](/features/data-discovery/schema-diff) page under [Data Discovery](/features/data-discovery) for the revision history walkthrough, the diff illustrations, and the link to the alert rule.

## Associating Terms with Data Entities through Descriptive Information

The Wikipedia-About-style walkthrough — adding business terms to the Dictionary, designating term owners, authoring rich descriptions, linking terms inline using the required format, and the reverse-search capability that surfaces every entity and column linked to a term.

See the dedicated [Business Glossary → Term-to-entity associations](/features/data-glossary/business-glossary#term-to-entity-associations) section under [Data Glossary](/features/data-glossary) for the full step-by-step walkthrough with screenshots.

## Adding Business Names for Data Entities and Dataset Fields

Operators can assign **business names** to data entities and to individual dataset fields — alternative human-readable labels that surface alongside the original technical names everywhere the entity is rendered.

See the dedicated [Business names for data entities and dataset fields](/features/data-discovery/business-names) page under [Data Discovery](/features/data-discovery) for the per-entity and per-field workflows, the activity-feed audit-trail event, and the RBAC permissions.

## Entity description

The platform's per-entity **Description** panel is a Markdown-authored prose surface — operators write rich descriptions of what an entity represents, with linked glossary terms inline. The rendered description surfaces on the entity's Overview tab and on several adjacent surfaces (search-result previews, lineage-node hovers, group cards) so the same authored prose travels with the entity wherever it appears.

See the dedicated [Entity description](/features/data-discovery/entity-description) page under [Data Discovery](/features/data-discovery) for the Markdown authoring and render pipeline, the `DATA_ENTITY_DESCRIPTION_UPDATE` permission, the activity-feed event, and the cross-surface stored-XSS family admonition operators should review before opening the surface to less-trusted authors.

## Custom metadata

Operators can attach typed custom fields to data entities — strings, integers, booleans, dates, URLs, JSON, and arrays — with the field definitions managed as a separate catalog and per-entity values authored on the entity's Metadata panel. INTERNAL fields are operator-curated; EXTERNAL fields arrive from collector-ingested metadata.

See the dedicated [Custom metadata](/features/data-discovery/custom-metadata) page under [Data Discovery](/features/data-discovery) for the two-half architecture (FIELD catalogue read + per-entity VALUE write), the 7 supported types, the INTERNAL / EXTERNAL origin distinction, the per-entity permissions, and the 4 known limitations operators should know before depending on the feature.

## Per-column annotation

On every dataset's **Structure** tab, each column carries a per-column composer that lets operators author five distinct annotations — column description, column tags, glossary terms, enum values, and a column-level business name — each gated by its own RBAC permission and emitting its own activity-feed event.

See the dedicated [Per-column annotation](/features/data-discovery/per-column-annotation) page under [Data Discovery](/features/data-discovery) for the 5 sub-editors, the per-sub-editor permissions and audit-feed coverage, and the 3 operator-visible write-path caveats (including the silently-`403`s wiring-bug pair on `DATASET_FIELD_ADD_TERM` and the empty-array-clears-all-tags shape of `updateDatasetFieldTags`).

## Integrating Vector Store Metadata

The platform recognises **vector-typed datasets** as a first-class catalog primitive — a dedicated `Vector Store` dataset type plus a `Vector` column data type — so vector tables sit alongside relational ones in search, lineage, and ownership. Today the recognition is wired up for PostgreSQL `pgvector` columns via [`odd-collector`](/integrations/integrations/odd-collector); other adapters can emit the same types by following the [specification](https://github.com/opendatadiscovery/opendatadiscovery-specification/blob/main/specification/entities.yaml).

See the dedicated [Vector Store metadata](/features/data-discovery/vector-stores) page under [Data Discovery](/features/data-discovery) for the specification source, the adapter coverage, and how the type surfaces in the catalog.

## GenAI assistant

The platform ships an opt-in **GenAI assistant** that proxies natural-language questions to an external AI service the operator runs separately. Disabled by default (`genai.enabled=false`); when turned on, exposes a single platform endpoint `POST /api/genai/ask` that forwards each question to `POST {genai.url}/query_data` and returns the answer. API-only today — no in-app UI affordance currently calls it.

See the dedicated [GenAI assistant](/features/active-platform-features/genai) page under [Active platform features](/features/active-platform-features) for the configuration keys (with the operator-relevant defaults caveat — `genai.url` empty + `genai.request_timeout=0` will silently misconfigure if only `enabled=true` is set), the external AI service contract (`POST /query_data` with JSON `{"question": "..."}`), and the platform's `/api/genai/ask` request / response schemas.

## Data Modelling

The **Data Modelling** section of the platform houses operator-curated artefacts that describe how data is intended to be used — canonical query examples and the entity-to-entity relationships that collectors extract or that operators define. It opens from the top-level navigation **Data Modelling** and exposes two sub-surfaces: **Query Examples** (the snippets below) and **Relationships / ERDs**.

See the [Data Modelling overview](/features/data-modelling) for the section's structure, the UI entry points, and the RBAC permissions that gate each surface.

## Query Examples

**Query Examples** are operator-curated SQL / KQL / Spark snippets attached to data entities and glossary terms — the canonical "how this dataset is used" surface. Snippets carry a description that doubles as a prompt-style explanation of intent, link to one or more datasets, and link to terms; a dedicated faceted search and a per-entity / per-term lookup surface them across the catalog.

See the dedicated [Query Examples](/features/data-modelling/query-examples) page under [Data Modelling](/features/data-modelling) for the UI walkthrough, the seven `QUERY_EXAMPLE_*` RBAC permissions, the 16-endpoint API surface, and the term-linking workflow.

## Relationships and ERDs

ODD Platform tracks entity-to-entity relationships as first-class catalog objects: **ERD edges** between table-class entities (derived from foreign-key constraints in the source) and **graph edges** between graph-store nodes. The dedicated **Data Modelling → Relationships** surface lists every relationship across all data sources, with a tab strip for filtering by ERD vs graph and a search input scoped to relationship names.

See the dedicated [Relationships](/features/data-modelling/relationships) page under [Data Modelling](/features/data-modelling) for the cardinality model (`ONE_TO_EXACTLY_ONE` / `ONE_TO_ZERO_OR_ONE` / `ONE_TO_ONE_OR_MORE` / `ONE_TO_ZERO_ONE_OR_MORE`), the API surface, and the per-adapter ingestion coverage (PostgreSQL and Snowflake adapters surface ERD today; no adapter currently emits graph relationships).

## Data Quality Dashboard

Catalog-wide quality view at `/data-quality` — three breakdown rings (Table Health / Test Results / Monitored Tables), six anomaly-class metrics (Assertion Tests / Column Values Anomalies / Freshness Anomalies / Schema Changes / Unknown Category / Volume Anomalies), and per-side filter sets (one for tables, one for tests; `AND`-only conjunction).

See the dedicated [Quality Dashboard](/features/data-quality/dashboard) page under [Data Quality](/features/data-quality) for the per-anomaly-class definitions, the monitored-vs-unmonitored breakdown, and the two-side filtering model.

## Filters to Include and Exclude Objects from Ingest

Pull adapters in ODD's collectors ingest **everything they can see** by default. Per-plugin **ingestion filters** scope a plugin to a regex-defined slice — `schemas_filter` (PostgreSQL, Snowflake), `filename_filter` (S3, Azure Blob, GCS), `datasets_filter` (BigQuery), `pipeline_filter` (Azure Data Factory), and similar — so the catalog stays focused on what teams care about.

See the dedicated [Ingestion filters](/integrations/integrations/ingestion-filters) page under [Integrations](/integrations/integrations) for the include / exclude shape, the worked PostgreSQL example, and the per-adapter coverage matrix.

## Data Entity Statuses

Every catalogued entity carries a status — `UNASSIGNED` (default), `DRAFT`, `STABLE`, `DEPRECATED`, or `DELETED` — that signals where it sits in its lifecycle. Statuses surface as a [Search](/features/data-discovery/search) facet, drive an Activity-feed event, and trigger a soft-delete TTL handled by the platform's housekeeping job.

See the dedicated [Data Entity Statuses](/features/data-discovery/statuses) page under [Data Discovery](/features/data-discovery) for the per-status semantics, the operator workflow, the soft-delete TTL configuration, and the RBAC permission.

## Alternative Secrets Backend

Store collector configuration — the Platform token, per-plugin database passwords, cloud-provider credentials — in an external secrets backend instead of plaintext in `collector_config.yaml`. Currently the AWS Systems Manager Parameter Store provider is supported; values from the backend override values set in the local YAML file.

This feature is also known as the **collector secrets backend**. For the configuration reference, the region-resolution order, a worked SSM example, the required IAM permissions, and the known limitations (10-parameter pagination cap, no custom SSM endpoint, no timeout / retry override), see [Collector secrets backend](/configuration-and-deployment/collectors-secrets-backend).

## Lookup Tables

**Lookup Tables** are operator-curated reference tables that live inside the ODD Platform itself rather than in an external source system — managed end-to-end (schema, data, versioning, RBAC), exposed in the catalog as standard Data Entities, and reachable both through the platform API and directly via PostgreSQL's `lookup_tables_schema`. Find them in the platform UI under the **Master Data** top-level tab → **Lookup Tables**.

See the dedicated [Lookup Tables](/features/master-data-management/lookup-tables) page under [Master Data Management](/features/master-data-management) for the creation flow, supported field types, the Data tab walkthrough, the 9 `LOOKUP_TABLE_*` RBAC permissions, and the full `/api/referencedata/` API surface.

## Integration Wizards

The **Integration Wizard** is an in-app UI under [**Management → Integrations**](/features/management) that helps operators bootstrap `collector_config.yaml`. Pick an integration, fill in a handful of source-specific fields, copy the rendered YAML snippet into your collector config — the wizard is a template generator, not an installer.

See the dedicated [Integration Wizard](/integrations/integrations/integration-wizard) page under [Integrations](/integrations/integrations) for the per-card flow, the `META-INF/wizard/*.yaml` registry that backs it, the API surface (`GET /api/integrations`, `GET /api/integrations/{integration_id}`), the static-parameter substitution context (today only `platform_url`, sourced from `odd.platform-base-url`), and the wizard-vs-`collector_config.yaml` boundary.

## Data Entity Attachments

Operators and users can attach **files** (images, PDFs, CSVs, TXT) and **links** (remote URLs) to any data entity for additional context — runbook PDFs, sample CSVs, dashboard screenshots, ticketing references. Attachments persist across re-ingests and can be edited or deleted at any time.

See the dedicated [Data Entity Attachments](/features/data-discovery/attachments) page under [Data Discovery](/features/data-discovery) for the upload workflow, the storage-backend caveat (LOCAL is ephemeral; use REMOTE S3 / MinIO in production), and the [Attachment Storage Configuration](/configuration-and-deployment/odd-platform#attachment-storage-configuration) operator reference.

## "Recommended" panel on the main page

The Recommended panel is a sub-surface of the [Catalog Overview page](/features/data-discovery/catalog-overview) that surfaces personalised quick-jumps for the signed-in user — recently-ingested owned entities, lineage neighbours, and the catalog's most-popular entities.

See [Catalog Overview page → Recommended](/features/data-discovery/catalog-overview#recommended) under [Data Discovery](/features/data-discovery) for the four-column layout, the freshness indicator, the disambiguation from the Alerts → My Objects tab, and the [User-owner association](/configuration-and-deployment/enable-security/authorization/user-owner-association) prerequisite.

## Custom navigation links

Operators can populate the App Info menu (the popup behind the information icon in the top-right toolbar) with their own links — runbooks, internal wikis, support channels, anything that helps users navigate from the catalog into the rest of the platform's surrounding ecosystem. Links are configured once on the platform side via the `odd.links[]` setting and surface to every signed-in user.

For the configuration detail (YAML and env-var form, including the visibility caveat that every signed-in user can read the configured URLs), see [Configure ODD Platform → Additional navigation links](https://docs.opendatadiscovery.org/features/pages/YH2ILihhfTPfYTyBhtw2#additional-navigation-links-odd.links). Operationally part of the [Management](/features/management) section.

## Metadata stale

Entities that have not been re-ingested for longer than `odd.data-entity-stale-period` (integer days; default `7`) are flagged with an orange clock icon next to their name everywhere they appear in the catalog — a discovery-time prompt that the metadata's freshness is uncertain.

See the dedicated [Metadata stale](/features/data-discovery/metadata-stale) page under [Data Discovery](/features/data-discovery) for the freshness window's meaning, what the indicator does (and doesn't) signal, and the operator-side reference for tuning the value.

## Machine-to-Machine (M2M) tokens

ODD Platform supports **server-to-server (S2S) API-key authentication** — a single shared static token presented in the `X-API-Key` header — for non-UI programmatic callers such as CI/CD jobs, ingestion pipelines, and automation scripts. Disabled by default; designed for trusted non-human callers and grants ADMIN-role access.

For configuration, the header contract, the curl example, and security considerations (token rotation, HTTPS, blast radius), see [Server-to-server (S2S) authentication](/configuration-and-deployment/enable-security/authentication/s2s). Operationally part of the [Management](/features/management) section.

## Multilingual UI

The platform's UI ships with seven locale translations — English (default), Spanish, Chinese, French, Ukrainian, Armenian, and Brazilian Portuguese (from 0.28.0) — loaded at SPA bootstrap and switchable from the **Select language** entry in the user-account menu on the toolbar. The active locale persists per browser device in `localStorage`; the API surface and operator-authored content (entity descriptions, glossary terms, custom-metadata field names, namespaces, tag names) remain in their source language regardless of the active locale.

See the dedicated [Multilingual UI](/features/multilingual-ui) page for the 7 supported locales, the language-picker affordance in the user-account menu, the per-device-not-per-user persistence model, the missing-key fall-through behaviour, and the contribution workflow for adding new locales.


# Data Discovery

Top-level UI section for the catalog's two entry paths — query-oriented Search and hierarchy-oriented Directory — surfaced together on the Catalog Overview page.

The **Data Discovery** section of ODD Platform is the home for finding entities in the catalog. The role is durable: anything that helps a user **locate** existing data — by typing a term, by walking a known structure, or by landing on the home page — belongs here. The section sits at the **operator-and-user front door**: most catalog interactions begin with one of the two entry paths surfaced from this pillar.

ODD covers Data Discovery fully — both entry paths ship today, and the platform's home page renders them side by side as the catalog's first-encounter view. See the [Data Governance map](/introduction/main-concepts#data-governance-map) for the position of Data Discovery in the overall pillar set.

Open it from the top-level navigation **Catalog** (Search-first landing) or **Directory** (hierarchy-first level-1 view). The Catalog Overview page surfaces both entry paths inline.

![Catalog Search results — entity-class tabs along the top (All / My Objects / Datasets / Transformers / Data Consumers / Data Inputs / Quality Tests / Groups / Relationships) with per-class counts; the Filters left-rail exposes Datasource / Namespace / Owner / Groups / Statuses facets. The result list shows mixed entity classes (LOOKUP\_TABLE, ENTITY\_RELATIONSHIP, DEG, DATASET, TRANSFORMER) — search and faceted filtering are how operators move from "I want a user-related entity" to a specific row.](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-9b425b1e87023001da81274872ac46c7939c388f%2Fsearch-facets.png?alt=media)

## Subsections

The catalog's two entry paths plus the per-feature surfaces that mark up, classify, and signal freshness on the entities they reach.

**Discovery entry paths**

* [**Catalog Overview page**](/features/data-discovery/catalog-overview) — the catalog's **home page**. A unified surface that combines Search, the Directory's level-1 cards, Top tags, Domains, the per-class Entities report, the Recommended quick-jumps, and (when authentication is on) the Owner-association request. Most catalog sessions start here.
* [**Directory**](/features/data-discovery/directory) — the catalog's **browse-oriented** entry point. Four-level drill-down (data source types → data sources → entity types → entities) backed by `/api/directory`. Use it when you know the *kind* of source but not the specific instance, when you're auditing per-source coverage, or when you're walking a teammate through the catalog.
* [**Search and Filtering**](/features/data-discovery/search) — the catalog's **query-oriented** entry point. Free-text search across entity names plus seven facets (Datasource / Type / Namespace / Owner / Tag / Groups / Statuses). The query-driven counterpart to the Directory.

**Per-entity detail surface**

* [**Data entity detail page**](/features/data-discovery/entity-detail-page) — the destination of every catalog discovery. Covers the Overview tab composition, the class-driven panel matrix that decides which panels and tabs appear, the class/type badges in the header, the sidebar list truncation (Tags / Terms / Groups), and the per-panel permission map. The container surface that the annotation features below render onto.

**Annotating discovered entities**

* [**Entity description**](/features/data-discovery/entity-description) — operator-authored Markdown description on every data entity. The primary free-text annotation surface; rendered on the Overview tab and surfaced as the preview snippet on search-result rows, Recommended-tile cards, and Directory-level-4 entity rows. Carries a load-bearing security caveat on the platform's no-write-time-sanitisation posture across six Markdown surfaces.
* [**Custom metadata**](/features/data-discovery/custom-metadata) — operator-curated typed key/value fields per data entity, plus the deployment-shared field catalogue that backs the autocomplete picker. Covers the seven supported field types, INTERNAL versus EXTERNAL (collector-ingested) origin, and four load-bearing caveats (silent no-op write, dropped `active` flag, unauthenticated catalogue enumeration, forensic silence on mutations).
* [**Per-column annotation**](/features/data-discovery/per-column-annotation) — the column-level counterparts to the entity-level annotation surfaces on a dataset's Structure tab — description, tags, glossary terms, enum values, and business name editors per column. Covers the per-sub-editor permissions, the audit-feed events each sub-editor emits, and three operator-visible write-path caveats (a SecurityConstants wiring bug that silently 403s the field-level Add-term button for users with the documented permission, a bulk-replace enum-values endpoint disguised as create-one, and a tags PUT that silently clears every operator-curated tag on empty submission).
* [**Manual Object Tagging**](/features/data-discovery/tagging) — apply tags to data entities and columns; the read-side counterpart to the Management → Tags vocabulary curation. Tags drive the Tag facet on Search and the Top tags chip strip on the Catalog Overview.
* [**Data Entity Groups & Domains**](/features/data-discovery/groups-domains) — logical containers for related entities, plus the Domain framing that surfaces flagged DEGs on the Catalog Overview's Domains section. Includes the relationship to ML Experiments.
* [**Business names**](/features/data-discovery/business-names) — alternative human-readable labels for data entities and dataset fields, surfaced alongside the technical name everywhere the entity is rendered.
* [**Data Entity Statuses**](/features/data-discovery/statuses) — `UNASSIGNED` / `DRAFT` / `STABLE` / `DEPRECATED` / `DELETED` lifecycle markers; surface as a Search facet, drive an Activity-feed event, and trigger a soft-delete TTL handled by the housekeeping job.
* [**Data Entity Attachments**](/features/data-discovery/attachments) — files (PDFs, CSVs, images) and remote-URL links attached to data entities for additional context. Storage backend operator-configurable; LOCAL is ephemeral.

**Specialty cataloguing**

* [**Vector Store metadata**](/features/data-discovery/vector-stores) — vector-typed datasets recognised as a first-class catalog primitive (dedicated `Vector Store` dataset type plus `Vector` column data type), surfaced today via the PostgreSQL `pgvector` adapter.

**Change and freshness signals**

* [**Dataset schema diff**](/features/data-discovery/schema-diff) — visual side-by-side comparison of dataset schema revisions, with backwards-incompatible changes additionally raising an alert.
* [**Metadata stale**](/features/data-discovery/metadata-stale) — per-entity orange clock icon flagging entities not re-ingested for longer than `odd.data-entity-stale-period` (default 7 days). A discovery-time freshness prompt; not a runtime alert.

## Why this is a separate pillar

For how Data Discovery relates to the other governance pillars (Data Modelling, Master Data Management, Data Lineage, Data Glossary, Data Quality), see [Main Concepts → Data Governance map → Pillar differentiation](/introduction/main-concepts#pillar-differentiation) — the canonical home for the six-pillar framing.

## Where to next

* If you know what you're looking for and want to type a term → [Search and Filtering](/features/data-discovery/search).
* If you don't know the exact name and want to drill down through known structure → [Directory](/features/data-discovery/directory).
* For the surface that every discovery lands on — Overview tab composition, class-driven panels, badges, sidebar truncation, permissions → [Data entity detail page](/features/data-discovery/entity-detail-page).
* If you want to label an entity for cross-cutting discovery → [Manual Object Tagging](/features/data-discovery/tagging).
* If you want to gather related entities into a logical group or surface a domain on the home page → [Data Entity Groups & Domains](/features/data-discovery/groups-domains).
* For the broader catalog vocabulary (Data Entity, Plugin, Push adapter, …) → [Main Concepts](/introduction/main-concepts).
* For the position of Data Discovery among the other governance pillars → [Main Concepts → Data Governance map](/introduction/main-concepts#data-governance-map).


# Catalog Overview page

The catalog's home page — a unified surface combining Search, Directory cards, Top tags, Domains, the per-class Entities report, Recommended quick-jumps, and (when auth on) Owner association.

The **Catalog Overview** is the catalog's home page — a single landing surface that combines every Data Discovery entry path the platform offers. A first-time user opening the platform lands here and reaches Search, the Directory's first level, the catalog's most-used tags, the Domains drill-down, a per-class Entities report, and (once they own data) personalised quick-jumps from one screen.

The Catalog Overview is the user's first encounter with the catalog and the unified pivot that links every other Data Discovery surface. It does not introduce new functionality of its own — it surfaces the existing pillars in one place.

![Catalog Overview page rendered on a populated deployment — main search, top tags, the per-class Entities report, the source-type Directory, and the Recommended quick-jumps.](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-86818485b1aa72cc98ff548ef25a94244782cb37%2Fcatalog-overview.png?alt=media)

## Sections

The page renders the following sections top-to-bottom. Three sections are conditional — Domains appears only when at least one [Data Entity Group](/features/data-discovery/groups-domains) is flagged as a domain; Directory appears only when at least one DataSource has been registered (a fresh deployment hides the band); and Owner association appears only when authentication is enabled and the signed-in user is not yet linked to an Owner.

### Main search

Full-text search bar across the catalog. The same Search facets that the [Search and Filtering](/features/data-discovery/search) page exposes are reachable from here — typing a term lands on the Catalog page with the query pre-populated.

### Top tags

The most-used tags across the deployment, rendered as one-click filter chips. Selecting a chip pre-filters the catalog to entities carrying that tag. Tag vocabulary is curated under [Management → Tags](/features/management); this surface is read-only.

### Domains *(conditional)*

A list of [Data Entity Groups](/features/data-discovery/groups-domains) that have been flagged as domains, rendered as quick-jump tiles. The section appears only when at least one DEG is domain-flagged; on a fresh deployment it is hidden.

### Entities

The per-class usage report — one card per [Data Entity class](/introduction/main-concepts) registered on the platform (Datasets, Transformers, Transformer Runs, Quality Tests, Quality Test Runs, Consumers, Inputs, [Groups](/features/data-discovery/groups-domains), Relationships — the list is platform-driven and grows when new classes ship). Each card shows the total number of entities of that class, the number of "unfilled" entities (those with only a title and no metadata, owners, tags, or related terms), and is clickable — clicking runs a pre-filtered search for that class.

The Entities card grid is the catalog's coverage-at-a-glance surface: an operator scanning it sees per-class counts and the unfilled fraction, which together signal which classes need stewardship attention.

### Directory *(conditional)*

Quick links into the source-system [Directory](/features/data-discovery/directory), grouped by data source type. This surface renders the same level-1 cards the standalone Directory page renders — clicking a card drills directly into level 2.

The band appears only when at least one DataSource is registered on the platform. On a fresh deployment with no DataSources, the band is hidden; the standalone [Directory](/features/data-discovery/directory) page remains reachable through navigation but is empty until a DataSource starts producing entities.

### Recommended

Personalised quick-jumps for the signed-in user, grouped into four columns. Surfaces recently-ingested owned entities and entities related to them through lineage, helping a returning user pick up where they left off without typing a search.

The Recommended panel requires the signed-in user to be linked to an [Owner](/configuration-and-deployment/enable-security/authorization/user-owner-association); without the user-owner association in place, the Recommended panel is empty. On auth-disabled deployments (`auth.type=DISABLED`) the panel is **hidden from the home page entirely** — there is no user-owner identity to filter on, so the entire surface is removed rather than rendered with unfiltered data. The underlying `GET /api/dataentities/popular` REST endpoint that backs the Popular column remains reachable under DISABLED for any caller on the network.

The four columns:

1. **My Objects** — the most recently ingested five data entities where the user is mentioned as an owner.
2. **Upstream Dependencies** — data entities that serve as direct origins to those the user owns.
3. **Downstream Dependencies** — entities that are direct targets of those the user owns.
4. **Popular** — the most-viewed data entities across the catalog, ranked by view count alone (highest first). See the caveat below — this ranking is trivially inflatable.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-3a1c87d2a4e44159ddc123aa5d98c709bde8e307%2Fmedium-0-9ly1UvgunFDqEK_E.png?alt=media" alt="" height="155" width="700"><figcaption><p>Wizards on Recommended panel</p></figcaption></figure>

{% hint style="warning" %}
**The Popular column ranks by view count alone, and view count is trivially inflatable — treat it as a rough popularity hint, not a trustworthy signal.** The only input to the Popular ranking is each entity's view count, sorted highest-first; there is no weighting by recency, ownership, or any other signal. View count, in turn, is bumped by **+1 every time a detail page is fetched**, with no rate limit, no per-user de-duplication, and no authentication required (one page-open registers one view as of 0.28.0 — releases up to 0.27.x double-counted each open; see [Data entity detail page → view count](/features/data-discovery/entity-detail-page#general-panel-view-count-caveats)). Because the `GET /api/dataentities/popular` endpoint and the detail-page read are both reachable on a deployment with authentication disabled (`auth.type=DISABLED`), a short scripted read loop can push any chosen entity to the top of the Popular column. Do not use the Popular ranking as evidence of real usage in audits or capacity decisions; cross-check against your own access logs.
{% endhint %}

Each tile carries a freshness indicator — an orange "time" icon signals stale entities (see [Metadata stale](/features/data-discovery/metadata-stale) for the freshness window and how operators tune it) and a per-class icon on the right indicates the entity type. Clicking a tile opens that entity's [detail page](/features/data-discovery/entity-detail-page), defaulting to the Overview tab.

All four columns are rendered by a single shared list component, so they share rendering, sort, refetch, and pagination semantics. Each column shows up to five entries; there is no per-column "view more" affordance and no per-column sort or filter. A change that affects column rendering affects all four uniformly.

{% hint style="warning" %}
**`exclude_from_search` is a full-text-search signal only — it does not hide entities from the Recommended panel or from any other list surface.** The platform's nine list-shape consumers (the Popular column, the By-Owner list, the By-Term list, the DEG-experiment runs view, the entity dimensions surfaces, the entity-detail GET, and the query-suggestions endpoint) all read through a shared SQL helper that filters on soft-delete and hollow flags only — it does **not** apply the `exclude_from_search` predicate. The flag IS honoured on the full-text search path and on the count / statistics aggregates. An operator who toggles `exclude_from_search=true` on a staging or internal entity expecting it removed from the Recommended panel discovers it still appears there (and on By-Owner / By-Term / lineage list surfaces) until a platform-side fix lifts the predicate into the shared helper. Until that ships, treat the flag as a search-engine signal, not a platform-wide hide signal.
{% endhint %}

This surface is **distinct from the Alerts → My Objects tab**, which is a different feature with the same name (Alerts → My Objects scopes the alert list to the user's owned entities; Recommended → My Objects surfaces recently-ingested owned entities). See [Alerting → Alert views](/features/active-platform-features/alerting#alert-views-all-my-objects-downstream-upstream) for the distinction.

### Owner association *(conditional)*

When authentication is enabled and the signed-in user is not yet linked to an [Owner](/configuration-and-deployment/enable-security/authorization/user-owner-association), this surface renders one of three states depending on whether the user has previously submitted a request. Once the user is bound to an Owner, the surface is replaced with the [Recommended](#recommended) panel (the four-column quick-jumps live in the same vertical band).

| Branch       | Trigger condition                              | What the user sees                                                                                                                                                                                                                                      | Path forward                                                                                                                                                                                                                                                                                                                |
| ------------ | ---------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Form**     | Signed in, no Owner binding, no prior request. | The Owner-association form with the Owner-name autocomplete and the **Send a request** button (see [User-owner association → For regular users](/configuration-and-deployment/enable-security/authorization/user-owner-association#for-regular-users)). | Submit the form; the request enters the admin-approval flow.                                                                                                                                                                                                                                                                |
| **Pending**  | Request submitted, status `PENDING`.           | A "Request is being checked" screen with no cancel affordance — the request is one-shot.                                                                                                                                                                | Wait for an admin to approve or decline on Management → Associations → New requests. There is no self-service cancel today; see [User-owner association → Changing or removing your association](/configuration-and-deployment/enable-security/authorization/user-owner-association#changing-or-removing-your-association). |
| **Declined** | Most recent request returned `DECLINED`.       | A dismissable banner with the declined notice, followed by the request form so the user can submit a new request.                                                                                                                                       | Dismiss the banner and submit a new request; note the banner dismiss is **per-session and not persisted** — see [User-owner association → If your request is declined](/configuration-and-deployment/enable-security/authorization/user-owner-association#if-your-request-is-declined).                                     |
| **Approved** | User bound to an Owner.                        | The four-column Recommended panel takes over the same vertical band — see [Recommended](#recommended) above.                                                                                                                                            | The form is gone; quick-jumps replace it.                                                                                                                                                                                                                                                                                   |

Pending Owner-association requests are routed to [Management → Associations](/features/management) for an operator with the `OWNER_ASSOCIATION_MANAGE` permission to approve. On auth-disabled deployments (`auth.type=DISABLED`) the section is hidden (no user identity, nothing to associate).

## Catalog Overview vs entity Overview tab

{% hint style="info" %}
**Two distinct things share the name "Overview".** The **Catalog Overview** described on this page is the catalog's home page — the unified surface combining Search, Directory, tags, Domains, Entities, Recommended, and the optional Owner association request. The [per-entity **Overview tab**](/features/data-discovery/entity-detail-page) is the landing tab inside any data entity's detail page — entity description, owners, tags, terms, custom metadata. They are different surfaces; do not confuse them when reading docs or filing bug reports.
{% endhint %}

## Where to next

* [Search and Filtering](/features/data-discovery/search) — the query-driven entry path the Catalog Overview surfaces at the top.
* [Directory](/features/data-discovery/directory) — the hierarchy-driven entry path the Catalog Overview surfaces inline (level-1 cards).
* [Data entity detail page](/features/data-discovery/entity-detail-page) — the destination of every Recommended tile, every Search result row, and every Directory entity row.
* [Manual Object Tagging](/features/data-discovery/tagging) — the source data behind the Top tags chip strip.
* [Data Entity Groups & Domains](/features/data-discovery/groups-domains) — the source data behind the Domains section.
* [Metadata stale](/features/data-discovery/metadata-stale) — the freshness signal Recommended tiles render via the orange "time" icon.
* [User-owner association](/configuration-and-deployment/enable-security/authorization/user-owner-association) — the operator-side configuration the Owner association section + the Recommended panel both depend on.
* [Data Discovery overview](/features/data-discovery) — the bucket landing this page sits under.


# Directory

Directory — the browsable catalog. Walk down data source types → data sources → entity types → entities without typing a query.

The **Directory** is the catalog's **browse-oriented** entry point. Where [Search](/features/data-discovery/search) is query-driven (you know what you're looking for and type a term), the Directory is hierarchy-driven (you don't yet know the exact entity name and want to drill down through known structure). It's the second of the two top-level navigation paths into the catalog.

## When to use the Directory

Reach for the Directory when:

* You want to see **what data sources are registered** in the platform without scrolling through search facets.
* You know the **kind of source** (PostgreSQL, Snowflake, Kafka, Airflow, ...) but not the specific instance or entity.
* You're auditing **per-source coverage** — how many entities did the collector pull from each source, and which entity types are present.
* You're onboarding a teammate and want to walk them through the catalog visually before showing them search.

For everything else — full-text lookup, faceted filtering by tags / domains / owners — use the [Search](/features/data-discovery/search) tab.

![Directory level 1 — one card per ODDRN-prefix data source type registered in the platform; each card carries the type's display name and the total entity count across every data source of that type. Clicking a card drills down to level 2.](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-f39ef315235f8cd527f7d220d3f44a8fe0254426%2Fdirectory.png?alt=media)

## Navigation hierarchy

The Directory is a four-level drill-down. Each level is its own UI page (and its own API endpoint — see below).

| Level                                                           | What you see                                                                                                                                                                                                                                                  | URL                                                                                               |
| --------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------- |
| 1. **Data source types**                                        | One card per ODDRN prefix that the platform's registered data sources resolve to (`postgresql`, `snowflake`, `kafka`, `airflow`, `mysql`, ...). Each card shows the type's display name and a total entity count across every registered source of that type. | `/directory`                                                                                      |
| 2. **Data sources** of the selected type                        | The list of registered data source instances for the chosen type — name, ODDRN-derived properties (host, port, database, ...), and per-source entity count.                                                                                                   | `/directory/{type-prefix}`                                                                        |
| 3. **Entity types** within the selected data source             | The distinct [Data Entity types](/introduction/main-concepts) present in the chosen data source (`TABLE`, `FILE`, `KAFKA_TOPIC`, `JOB`, `JOB_RUN`, `DASHBOARD`, `VIEW`, `ML_MODEL_INSTANCE`, ...) — the type dimension, not the broader entity class.         | `/directory/{type-prefix}/{data-source-id}/all` (UI surfaces this on the data-source detail page) |
| 4. **Entities** of the selected (data source, entity type) pair | The paged list of data entities matching both filters; click an entity to land on its detail page (Overview tab).                                                                                                                                             | `/directory/{type-prefix}/{data-source-id}/{type-id}`                                             |

The Directory's **first level** also surfaces in a condensed form on the Catalog Overview home page under the "Directory" section — a quick-jump card grid that links directly into level 2.

## Known limitations and operator caveats

The Directory's read posture and URL conventions carry several behaviours operators need to know before relying on them in a multi-team deployment.

### Level 2 reflects every ODDRN path property to every authenticated caller

The level-2 response is built by walking each registered data source's ODDRN and emitting every property that contributes to the address as a column in the response. For PostgreSQL that means `host` and `database`; for Snowflake `account` and `warehouse`; for Kafka `cluster` and `topic`; for MySQL `host` and `database`; for BigQuery `project`. The level-2 table on `/directory/{type-prefix}` is the operator-visible projection of this reflection — the table's columns are derived from the first row's properties at render time, so the column set changes per data-source type but always reflects everything the collector chose to encode in the ODDRN.

{% hint style="warning" %}
**Anyone with read access to the catalog can enumerate this inventory.** The Directory endpoints carry no owner-scoping; any authenticated user can drill `/api/directory/{type-prefix}` and reach the full list of registered data sources of that type together with their reflected host / database / port / account / warehouse / cluster / topic / project strings. Under `auth.type=DISABLED` the same endpoint is anonymously reachable. The strings frequently double as DNS targets, firewall-rule names, cloud-account identifiers, or VPC names — treat catalog read access as you would access to that inventory. See [Enable security](/configuration-and-deployment/enable-security) for the deployment-side stance.
{% endhint %}

### The level-4 count badge can disagree with the level-4 result list

The level-4 list endpoint (the paged result) and the level-4 count endpoint (the badge showing total entities) apply different filter predicates. In deployments that use the `EXCLUDE_FROM_SEARCH` flag to hide intermediate or transient entities from search but keep them browsable in the Directory, the count drops those entities while the list still shows them — so the page renders, for example, 30 rows under a "25 entities" header (or the reverse, depending on which page you land on). The mismatch is silent; there is no warning that the X-of-Y display has diverged from the row count you can scroll through.

If your collector layer uses `EXCLUDE_FROM_SEARCH` for entity hygiene, treat the level-4 count badge as advisory rather than authoritative when auditing per-source completeness.

### The level-3 URL's third segment is the literal string `all` — not a numeric placeholder

Level-3 and level-4 URLs differ in shape:

* `/directory/{type-prefix}/{data-source-id}/all` — level 3 (every entity type of this source).
* `/directory/{type-prefix}/{data-source-id}/{numeric-type-id}` — level 4 (entities of one specific type).

The `all` segment is a load-bearing literal — the routing hook coerces the third segment to "no type filter" only when it matches `all` exactly, otherwise it runs it through a numeric parse. A typo (`postgresql/123/dataset` instead of `postgresql/123/all`) parses to `NaN`, which propagates as the type filter through the level-4 query — silently rendering a broken or empty view rather than a 404. Hand-constructing level-3 URLs is therefore brittle; the recommended path is to navigate via the UI's `All` tab (which always builds the URL correctly) and to bookmark the result.

If the level-3 URL is missing the third segment entirely (`/directory/{type-prefix}/{data-source-id}`), the platform redirects to `/all` automatically — that fallback is the safest hand-construction shape if you must type the URL.

## API surface

The Directory's four backing endpoints are documented at [API Reference → Directory](/developer-guides/api-reference/directory) — one `GET` endpoint per drill-down level under `/api/directory`, with the level-1 ODDRN-parsing implementation detail included alongside.

## Where it sits in the UI

* **Top-navigation `Catalog`** drops the user on the Search-first landing.
* **Top-navigation `Directory`** opens the standalone level-1 view (`/directory`).
* **Catalog Overview page → Directory section** renders the same level-1 cards inline (so the home page surfaces both Search and Directory entry points side by side).

## Where to next

* [Search and Filtering](/features/data-discovery/search) — the query-oriented counterpart, with seven facets.
* [Data entity detail page](/features/data-discovery/entity-detail-page) — what you land on when you click an entity in the level-4 list.
* [ODDRN](/introduction/main-concepts#oddrn) — the addressing scheme whose prefix is what the level-1 cards group by, and whose properties are what the level-2 columns reflect.
* [Enable security](/configuration-and-deployment/enable-security) — the deployment-side surface for restricting catalog read access in multi-team environments.
* [Main Concepts → Data Discovery](/introduction/main-concepts) — where Search and the Directory sit in the broader governance map.


# Search and Filtering

Search and Filtering — the catalog's query-oriented entry point. Free-text search across entity names plus seven faceted filters.

**Search** is the catalog's primary query-oriented entry path — type what you are looking for, and ODD finds entities matching across names, descriptions, and metadata. Where the [Directory](/features/data-discovery/directory) walks the catalog hierarchically, Search is free-text + faceted.

With the user-friendly search interface, finding the information you need is easier than ever. Type your search query into the search bar and ODD does the rest.
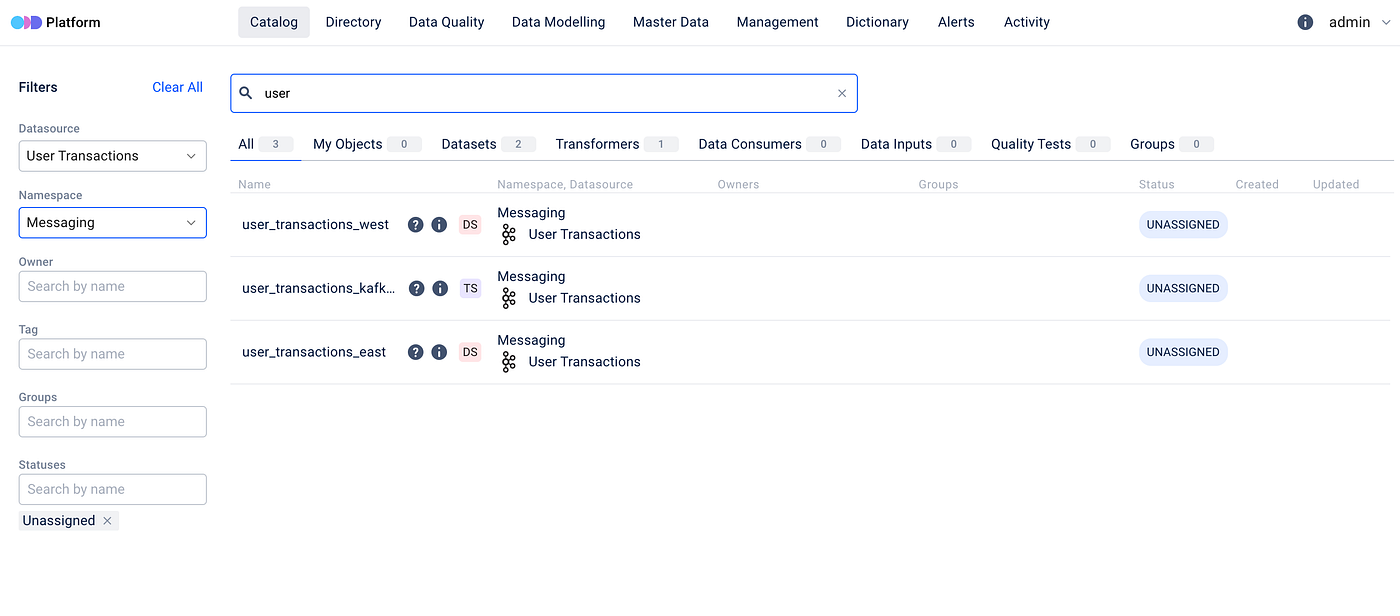
To get started, navigate to the main page of ODD Platform and select the **Catalog** tab. There you will find the **Search bar** and **Filter** options.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-e556fc1bdeae2debfe5d5fcecd3e4daee6e3e749%2Fmedium-1-gBaX_FNU94IV_VXFBqt_5Q.png.png?alt=media" alt="" height="308" width="700"><figcaption><p>Type your search query into the search bar</p></figcaption></figure>

## Faceted search

The platform incorporates **faceted** search capabilities. This means you can refine your search results based on specific attributes, ensuring that you find exactly what you are looking for.

The Filters panel on the Catalog page exposes seven facets:

* **Datasource** — restrict results to entities ingested from a specific datasource (single-select).
* **Type** — restrict results to one or more data entity types (e.g., `TABLE`, `JOB`, `DASHBOARD`; multi-select). Only shown after an entity-class tab is selected at the top of the Catalog (Datasets / Transformers / Data Consumers / Data Inputs / Quality Tests / Groups / Relationships).
* **Namespace** — restrict to entities in a given namespace (single-select). Useful in multi-team setups where each team owns its own namespace and wants to see only its own datasets, jobs, and quality tests in one click.
* **Owner** — show entities owned by one or more selected owners (multi-select).
* **Tag** — show entities carrying one or more selected [tags](/features/data-discovery/tagging) (multi-select).
* **Groups** — show entities that are members of one or more selected [Data Entity Groups](/features/data-discovery/groups-domains) (multi-select). Useful for narrowing the search to a logical project, domain, or pipeline group rather than a flat datasource list.
* **Statuses** — show entities in one or more selected statuses (multi-select; e.g., `STABLE`, `DEPRECATED`).

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-a57ec892273e9f49fd85309cb66a2a644283a6b3%2Fmedium-1-6aUPoqTEE17kgUcvVHewKg.png.png?alt=media" alt="" height="308" width="700"><figcaption><p>Filters</p></figcaption></figure>

## Result-class tabs

Above the result list the Catalog page renders a tab strip — a second filter axis, independent of the Filters sidebar. Selecting a tab narrows the result list to entities of that class (or the personal scope, for `My Objects`) and unlocks the **Type** sidebar facet, which is hidden until a specific class is chosen.

The nine tabs, left to right:

| Tab                | What it scopes to                                                                                                                             |
| ------------------ | --------------------------------------------------------------------------------------------------------------------------------------------- |
| **All**            | Every entity matching the query and the active facets, regardless of class.                                                                   |
| **My Objects**     | The subset of the above owned by the authenticated user. The personal-namespace tab.                                                          |
| **Datasets**       | Entities of class `SET` (tables, views, files, topics).                                                                                       |
| **Transformers**   | Entities of class `TRANSFORMER` (jobs, pipelines, dbt models).                                                                                |
| **Data Consumers** | Entities of class `CONSUMER` (microservices, BI dashboards).                                                                                  |
| **Data Inputs**    | Entities of class `INPUT` (source data feeds).                                                                                                |
| **Quality Tests**  | Entities of class `QUALITY_TEST` (test definitions; per-run history lives on the [detail page](/features/data-discovery/entity-detail-page)). |
| **Groups**         | Entities of class `ENTITY_GROUP` (Data Entity Groups, including domain-flagged ones).                                                         |
| **Relationships**  | Entities of class `RELATIONSHIP` (ERD relationship metadata).                                                                                 |

The tab counts update with the active query and facet selection. The **Type** facet in the sidebar is class-conditional: it appears only once a specific class tab is selected (because type values are only meaningful within a class).

## Per-result transparency

As you type your search and adjust filters, ODD dynamically responds, delivering results in seconds. Each entity in the search results is accompanied by an information and a question icon, offering additional clarity and insight:

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-c8b149ccff698e29085c9fa5beb897e01a29d21a%2Fmedium-1-N55y0lSj6UPwKn07VZONfA.png.png?alt=media" alt="" height="359" width="700"><figcaption><p>The information icon shows you what you see in your search results</p></figcaption></figure>

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-1ec052b87ceae846a141baa940ec9ccb8f291b80%2Fmedium-1-KhfWVWp-6FAVYvIcLTF7yw.png.png?alt=media" alt="" height="383" width="700"><figcaption><p>The question icon shows you why you see it in your search results</p></figcaption></figure>

## Technical details

The underlying constants used by the search engine are defined in [FTSConstants.java](https://github.com/opendatadiscovery/odd-platform/blob/main/odd-platform-api/src/main/java/org/opendatadiscovery/oddplatform/repository/util/FTSConstants.java).

**Step 1.** Metadata ingested into the platform goes through indexing to improve search efficiency.

**Step 2.** When you search or apply filters, the search engine processes your inputs by recognizing search terms, applying relevant constraints, and identifying metadata entries closely related to the query.

**Step 3.** Next, ODD ranks these matching metadata entries based on a specific criteria and their relevance to your search.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2FQ7ocKVSleF5eDeH1Ill2%2Fimage.png?alt=media&amp;token=f10c2e23-d8e1-4dc2-a0ea-d351675f72a6" alt=""><figcaption><p>Metadata ranking for search within ODD</p></figcaption></figure>

## Known limitations and operator caveats

The catalog search runtime carries several behaviours that are non-obvious from the UI alone. Each item below states what an operator might assume, what actually happens, and what to do today.

### The `/search/{id}` URL is a server-side session, not a frozen query

The address bar on the Catalog page is `/search/{uuid}` once you've typed a query. The UUID is the primary key of a row in the platform's `search_facets` table — a server-side **session** that carries the query string, the facet selections, and the current page state. It is **not** an encoded snapshot of your search and **not** a saved search.

Three consequences operators routinely bump into:

* **Sharing a `/search/{uuid}` URL with a teammate hands them an interactive cursor, not a snapshot.** When they open the link they reach the same server-side row; if you keep clicking facets, their view drifts with yours. To share a frozen result, send the entity URLs (`/dataentities/{id}`) directly. (Opening a shared link — and reloading the page — loads the session as of 0.28.0; earlier releases had a front-end defect that silently discarded the pasted id and started a fresh empty session.)
* **The session UUID is not bound to a user.** Any authenticated caller who has the UUID reaches the row; under `auth.type=DISABLED` the row is reachable anonymously. Treat the URL as you would any other unguarded internal link.
* **Clicking the `Catalog` top-nav tab drops the UUID and starts a fresh session.** The "Catalog" link points at bare `/search`, which mints a new server-side row on the next keystroke. There is no "go back to my last search" affordance on the top nav — use the browser back button instead, or re-paste the previous URL.
* **The session row is evicted by the housekeeping job.** A session row lives until 30 days after its last access (configurable via [`housekeeping.ttl.search_facets_days`](/configuration-and-deployment/odd-platform#housekeeping-settings-configuration)). Opening an evicted URL shows a "This search has expired" notice with a one-click **Start new search** recovery (as of 0.28.0; earlier releases silently dropped the dead id and opened a fresh empty session). Bookmarking a `/search/{uuid}` URL for long-term reference is still unreliable — for durable references, share entity URLs instead.

### Facet aggregators enumerate cross-owner data by default

The Filters sidebar facets — Datasource, Namespace, Owner, Tag, Groups, Statuses, Type — list every value visible to the platform, with per-value counts that span the entire catalog. The Owner facet in particular returns the full Owner directory and per-owner counts to any authenticated caller; under `auth.type=DISABLED` the same lists are reachable anonymously.

This is the catalog's **read-collaborative posture**: anyone who can read the catalog can see who owns what, which sources have how many entities, and which tags are most common. If your deployment must avoid exposing the Owner directory or cross-source enumeration to all authenticated users, treat catalog access as a privileged role and do not enable `auth.type=DISABLED` in production.

{% hint style="info" %}
**`tsquery` operator characters in the search box are treated as word separators.** PostgreSQL full-text search parses the query as a `tsquery`, so characters such as `( ) : & | ! '` are not searchable literals — the search box strips them and matches the remaining words as prefixes. A name like `user(id)` is searched as `user` and `id` (and still matches an entity called `user(id)`); a query made up of only these characters returns **No matches found**. The same handling applies to the Dictionary (term) search box. (As of 0.28.0; in earlier releases these characters were not stripped — such a query failed with HTTP 500 and persisted a broken `/search/{uuid}` session, reproduced on every later read of that URL until the housekeeping job evicted the row.)
{% endhint %}

### The Datasource and Namespace dropdowns cap at 100 options

The Filters sidebar fetches at most 100 datasources and 100 namespaces for the Datasource and Namespace single-select dropdowns. In a deployment with more than 100 of either, the dropdown silently shows the first 100 the API returned — with no `+N more`, no pagination, and no search-within-dropdown affordance. To filter by a source that does not appear, use the Search bar with a query that pre-narrows the result set (e.g. typing the namespace name as free text), then apply remaining facets.

### `exclude_from_search` is a full-text-search signal only

The `exclude_from_search` flag on a data entity does what its name implies — it removes the entity from the platform's full-text search results — but **it does not remove the entity from the catalog's other list surfaces**. The predicate that honours the flag is added only on the full-text-search query paths. The Recommended panel's Popular column, the By-Owner list, the By-Term list, the DEG-experiment runs view, the entity dimensions surfaces, the entity-detail GET, and the query-suggestions endpoint each build their own list query and several of those queries never add the `exclude_from_search` predicate at all. An operator setting the flag on a staging or internal entity should expect it to disappear from search results but still appear on every other list surface in the platform. See the same caveat from the catalog-front-door angle on [Catalog Overview → Recommended](/features/data-discovery/catalog-overview#recommended).

### Clicking a result row records a view — and feeds the Popular ranking

Each click on a result row navigates to the entity's [detail page](/features/data-discovery/entity-detail-page), which records a view on the entity's `viewCount` — exactly one per open as of 0.28.0 (releases up to 0.27.x double-counted each open as +2; see [Data entity detail page → view count](/features/data-discovery/entity-detail-page#general-panel-view-count-caveats)). The Catalog Overview's **Popular** and **Recommended** tiles read from the same counter, so routine browsing through search results still biases those rankings toward whatever entities you happened to open from search — every open counts, however you arrive (a search-row click and direct navigation to `/dataentities/{id}` record the same single view). Returning to the results with the browser back button does not add another view.

## Where else search appears

Search and filtering are available not only in the Catalog tab, but in **Query examples**, **Master Data**, [**Management**](/features/management), and **Dictionary** tabs as well — each Management sub-tab (Datasources, Owners, Tags, …) has its own list-level filter. The Catalog-level full-text search across data entities is exclusive to the Catalog tab.

## Where to next

* [Directory](/features/data-discovery/directory) — the hierarchy-driven counterpart for browsing without typing a query.
* [Data entity detail page](/features/data-discovery/entity-detail-page) — the destination of every result-row click; explains the Overview tab composition you land on and the class-driven panel matrix.
* [Manual Object Tagging](/features/data-discovery/tagging) — the Tag facet's source data.
* [Data Entity Groups & Domains](/features/data-discovery/groups-domains) — the Groups facet's source data.
* [Housekeeping Settings Configuration](/configuration-and-deployment/odd-platform#housekeeping-settings-configuration) — the `housekeeping.ttl.search_facets_days` knob that controls how long a `/search/{uuid}` session lives.
* [Main Concepts → Data Governance map](/introduction/main-concepts#data-governance-map) — where Data Discovery (Search + Directory) sits among the governance pillars.


# Data entity detail page

The data entity detail page — composition of the Overview tab, class-driven panel matrix, badges, sidebar list truncation, and per-panel permission map. Where every catalog discovery lands.

Clicking a data entity in [Search](/features/data-discovery/search), in the [Directory](/features/data-discovery/directory), in a [Catalog Overview](/features/data-discovery/catalog-overview) tile, in a lineage node, or in the [Activity feed](/features/active-platform-features/activity-feed) lands the user on the same per-entity detail page. The **Overview tab** is the default landing surface — a single composed page showing everything the catalog knows about the entity, with edit affordances gated by per-panel permissions and per-class composition rules.

This page is the canonical reference for the detail-page composition itself. For the aspect-level deep dives — authoring the [Markdown description](/features/data-discovery/entity-description), curating [custom metadata](/features/data-discovery/custom-metadata), annotating [individual columns](/features/data-discovery/per-column-annotation) on a dataset's Structure tab, applying [tags](/features/data-discovery/tagging), curating [business names](/features/data-discovery/business-names), wiring [statuses](/features/data-discovery/statuses), attaching [files](/features/data-discovery/attachments), reading the [stale indicator](/features/data-discovery/metadata-stale), and grouping into [Data Entity Groups](/features/data-discovery/groups-domains) — follow the per-aspect pages cross-linked below.

## Overview tab composition

The Overview tab renders a two-column grid for every catalogued entity:

* **Main column (left)** — class-driven stats, Description, Attachments, Metadata, optional Expectations, optional Metrics.
* **Sidebar (right)** — General identity + Owners, optional Data Quality panels, Groups, Tags, Terms.

Twelve sub-panels combine on the surface:

| Panel              | Column                | What it shows                                                                                                                                                                                                                                     | Aspect page                                                                                                                                                         |
| ------------------ | --------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Class-driven stats | Main                  | A class-specific summary block — dataset structure card, transformer source/target list, consumer input list, quality-test datasets, data-input output list, relationship endpoints, or entity-group member set, depending on the entity's class. | [Main Concepts → Data Entity Class](/introduction/main-concepts)                                                                                                    |
| Description        | Main                  | The entity's human-readable Markdown description, with linked terms inline.                                                                                                                                                                       | [Entity description](/features/data-discovery/entity-description); [Business Glossary](/features/data-glossary/business-glossary) for the inline term-link surface. |
| Attachments        | Main                  | Files and remote-URL attachments uploaded for the entity.                                                                                                                                                                                         | [Data Entity Attachments](/features/data-discovery/attachments)                                                                                                     |
| Metadata           | Main                  | Custom (operator-curated) and predefined (collector-ingested) metadata fields in one combined list.                                                                                                                                               | [Custom metadata](/features/data-discovery/custom-metadata)                                                                                                         |
| Expectations       | Main (conditional)    | Renders only when the entity has quality-test expectations — parameters and linked URLs from the test definition.                                                                                                                                 | [Test Results Import](/features/data-quality/test-results-import)                                                                                                   |
| Metrics            | Main (conditional)    | Renders only for datasets — column-level stats and metrics.                                                                                                                                                                                       | —                                                                                                                                                                   |
| General            | Sidebar               | Namespace, datasource link, source-side timestamps, view count (see the [view count caveats](#general-panel-view-count-caveats) below), ODDRN, and the Owners list.                                                                               | [Authorization → Owners](/configuration-and-deployment/enable-security/authorization/owners)                                                                        |
| DQ SLA report      | Sidebar (conditional) | Renders only for datasets with at least one quality-test report; shows the SLA roll-up.                                                                                                                                                           | [Quality Dashboard](/features/data-quality/dashboard)                                                                                                               |
| DQ test report     | Sidebar (conditional) | Renders alongside the SLA report; shows the latest passed / failed / aborted totals.                                                                                                                                                              | [Quality Dashboard](/features/data-quality/dashboard)                                                                                                               |
| Groups             | Sidebar               | Data entity groups this entity belongs to.                                                                                                                                                                                                        | [Data Entity Groups & Domains](/features/data-discovery/groups-domains)                                                                                             |
| Tags               | Sidebar               | Tags applied to the entity.                                                                                                                                                                                                                       | [Manual Object Tagging](/features/data-discovery/tagging)                                                                                                           |
| Terms              | Sidebar               | Linked business-glossary terms.                                                                                                                                                                                                                   | [Business Glossary](/features/data-glossary/business-glossary)                                                                                                      |

The page header above the tabs shows the entity name, the class badges, the type badge, the [stale indicator](/features/data-discovery/metadata-stale), the [status](/features/data-discovery/statuses), and (where applicable) the "Edit business name" / "Edit group" / "Share" buttons. Header affordances follow the same per-class and per-permission rules as the Overview composition; see [Class and type badges](#class-and-type-badges) below.

Below the Overview tab, additional class-driven tabs appear — **Structure** (datasets only; see [Per-column annotation](/features/data-discovery/per-column-annotation) for the column-level composer that lives on this tab), **Lineage** (most classes; see [Data Lineage](/features/data-lineage)), **Test reports** and **History** (quality tests, transformer runs), **Linked entities** (per-class linkage), **Discussions** (when [Data Collaboration](/features/active-platform-features/data-collaboration) is enabled), and **Activity** (the [per-entity Activity feed](/features/active-platform-features/activity-feed) audit trail). Which tabs appear depends on the entity's class set; the next section names the mapping.

### General panel — view count caveats

The General panel's **view count** is the running total of times this entity's detail page has been fetched. One version note and one caveat are worth knowing before you read or rely on the number.

{% hint style="info" %}
**One page-open registers one view as of 0.28.0 — releases up to 0.27.x counted +2.** In earlier releases each page-open fetched the entity detail twice (a front-end double-fetch), so a single visit added **2** to the number. From 0.28.0 a visit adds exactly 1. Counts accumulated on earlier releases overstate real visits by roughly a factor of two, and the counter is not rebased on upgrade — treat pre-0.28.0 numbers as a relative popularity hint, not an exact visit tally.
{% endhint %}

{% hint style="warning" %}
**View count is the sole signal behind the home-page Popular ranking, and it is trivially inflatable.** The [Catalog Overview → Popular column](/features/data-discovery/catalog-overview#recommended) ranks entities by view count alone, highest first. View count is bumped on every detail-page fetch with no rate limit, no per-user de-duplication, and no authentication required, and on a deployment with authentication disabled (`auth.type=DISABLED`) both the detail-page read and the `GET /api/dataentities/popular` endpoint are reachable by any caller on the network. A short scripted read loop can therefore push any chosen entity to the top of the Popular column. Do not treat the view count or the Popular ranking as trustworthy usage evidence in audits or capacity decisions; cross-check against your own access logs.
{% endhint %}

## Per-class panel matrix

The set of panels and tabs visible on a detail page depends on the entity's **class** — the categorical taxonomy that drives every composition decision. A single entity can carry multiple classes (e.g. an ML training pipeline that is both `TRANSFORMER` and `ENTITY_GROUP`); each class contributes its own panels.

| Class                               | Main-column stats panel                                                                                                                     | Tabs beyond Overview                                                                                      |
| ----------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------- |
| `SET` (Dataset)                     | Dataset structure card — column count, row count, source-side schema link.                                                                  | Structure, Lineage, Test reports, History (when test runs exist), Linked entities, Discussions, Activity. |
| `TRANSFORMER` (Job / Pipeline)      | Sources and targets list, with unknown-source / unknown-target counts surfaced separately.                                                  | Lineage, History, Linked entities, Discussions, Activity.                                                 |
| `TRANSFORMER_RUN` (Job run)         | No main-column stats panel renders today — the parent transformer's panel does not propagate to its runs. Per-run details live in History.  | Lineage, History (own row), Linked entities, Discussions, Activity.                                       |
| `CONSUMER` (Microservice / BI tool) | Input list and unknown-input count.                                                                                                         | Lineage, Linked entities, Discussions, Activity.                                                          |
| `INPUT` (Source data feed)          | Output list and unknown-output count.                                                                                                       | Lineage, Linked entities, Discussions, Activity.                                                          |
| `QUALITY_TEST`                      | Suite name, suite URL, tested datasets, test parameters.                                                                                    | Test reports, History, Linked entities, Discussions, Activity.                                            |
| `QUALITY_TEST_RUN`                  | No main-column stats panel renders today — the parent quality test's panel does not propagate to its runs. Per-run reports live in History. | History, Linked entities, Discussions, Activity.                                                          |
| `ENTITY_GROUP` (DEG)                | Member list and the entity-group authoring affordances.                                                                                     | Group Lineage, Linked entities, Discussions, Activity.                                                    |
| `RELATIONSHIP` (ERD)                | Source / target endpoints, cardinality, and join semantics.                                                                                 | Linked entities, Discussions, Activity.                                                                   |

For the canonical class taxonomy and how collectors assign classes during ingestion, see [Main Concepts → Data Entity Class](/introduction/main-concepts).

{% hint style="warning" %}
**An entity may render no main-column stats panel — silently — for two distinct reasons.** First, if the entity's class array is empty, undefined, or contains a value the UI does not recognise. Second, if the entity is one of the **run** classes (`TRANSFORMER_RUN` or `QUALITY_TEST_RUN`) — both are recognised enum values but the panel switch has no case for them, so they fall through to the default no-render branch. In either case the rest of the Overview (Description, Attachments, Metadata, sidebar panels) still loads, but the class-specific summary block is absent with no visible placeholder. When an Overview is missing its expected stats panel, first check the per-class matrix above (run-classes are expected to be empty here); if the class is none of the run-classes, check the entity's class assignment at the collector — that is the most likely cause.
{% endhint %}

{% hint style="warning" %}
**The right-column Data Quality section is hidden when a dataset has zero test reports — and when the report is still loading.** The DQ panels appear only when the entity is a dataset AND its test-report total is non-zero. A dataset with no quality tests configured renders no DQ section. A dataset whose test-report fetch is still in flight also renders no DQ section. Both states produce the same empty space in the sidebar; the only way to tell them apart today is to wait and re-check, or to inspect the network tab. Treat sidebar DQ absence as "no tests **or** still loading" rather than as a confirmed "this dataset has no quality coverage" signal.
{% endhint %}

## Class and type badges

The detail-page header renders the entity's class taxonomy as a row of badges next to the name:

* **Class badges** — one chip per entry in the entity's class array. Each chip is colour-coded per class (palette resolved from the platform's UI theme — the colour identifies the class at a glance once you've learned the mapping). Hovering a badge surfaces the canonical class label (the short label is on the chip; the longer "normal" label is in the tooltip).
* **Type badge** — one chip immediately to the right of the class badges, showing the entity's specific type (`TABLE`, `VIEW`, `JOB`, `DASHBOARD`, `ML_MODEL_TRAINING`, etc.). The type label is the formatter-stripped underscore-free upper-case form of the underlying enum value.

{% hint style="info" %}
**Class is the load-bearing taxonomy; type is descriptive.** The class array drives every per-class composition decision on the page — which stats panel renders, which tabs are visible, whether the DQ sidebar appears. The type is a finer-grained descriptive label collectors set alongside the class; it does not gate UI surfaces today.
{% endhint %}

A few operator-visible behaviours of the badge row to be aware of:

* **No tooltip explains per-class consequences.** A badge names the class (e.g. `Dataset`, `Transformer`) but does not say "this class is why you see a Structure tab" or "this class is why this entity has source/target panels." The mapping is in [Per-class panel matrix](#per-class-panel-matrix) above; the header surface does not surface it directly.
* **The type badge is not colour-coded.** Class badges use per-class colours; the type badge uses a uniform background regardless of type. A dense list (search results, directory list) is therefore class-coloured but type-uniform — operators scanning a list distinguish entities by class colour at a glance, by type only after reading the label.
* **An entity with no recognised class renders no class badge — silently.** Combined with the matching stats-panel absence noted above, an unclassified entity is structurally indistinguishable from an entity whose class payload was lost in transit. If the badge row shows only a type badge and no class chips, treat the entity as ingestion-incomplete and check the collector.
* **Multi-class entities overflow horizontally.** The badge row uses no-wrap layout, so an entity carrying four or more classes overflows the horizontal allocation rather than wrapping to a second line. In practice multi-class entities are uncommon; an ML model that is both `ENTITY_GROUP` and `TRANSFORMER` is the canonical case. The "Edit business name" button shares the same row, so heavy class overflow can compress the visible name.
* **The `DCT` type is a deliberate special case.** The type-name slot accepts the standard collector enum plus the literal string `'DCT'` — the dbt-cloud type, surfaced on the badge alongside the collector-side enum. If you see a `DCT` type on a `TRANSFORMER`-class entity, that is the [`odd-dbt`](/integrations/integrations/odd-dbt) push-adapter ingestion chain.

## Sidebar list truncation (Tags / Terms / Groups)

The sidebar's **Tags**, **Terms**, and **Groups** panels cap visible items to keep the surface from stretching vertically. The cap is panel-specific and a `View All (N)` toggle expands the full list inline:

| Panel      | Initial visible            | Toggle                                                            |
| ---------- | -------------------------- | ----------------------------------------------------------------- |
| **Tags**   | First 20 tags              | `View All (N)` button at the panel foot when the list exceeds 20. |
| **Terms**  | First 20 linked terms      | Same.                                                             |
| **Groups** | First 10 group memberships | Same.                                                             |

When a panel is truncated it shows an inline **`Showing 20 of N`** hint above the list (alongside the `View All (N)` toggle's count), so the truncation is visible at a glance without clicking. An entity with 20 or fewer tags shows neither the hint nor the toggle.

{% hint style="info" %}
**Tags are importance-ordered across the truncation cap.** The Tags panel sorts the **whole** tag set by importance (important tags first), then alphabetically, and *then* takes the visible window — so an entity's important tags appear in the first 20 even when it carries many more, and `View All` continues the same single ordering. The same importance ordering applies to the tag lists on the term detail page and on a dataset field.
{% endhint %}

{% hint style="info" %}
**The Groups and Terms panels show the server's order.** These panels carry no importance signal, so the visible window (10 for Groups, 20 for Terms) and the expanded list render in the order the platform returns them. Do not rely on this order being alphabetical.
{% endhint %}

## Permissions surface

Every editable panel on the Overview tab evaluates its own permission set locally. The detail page does not declare a single "what can I edit on this entity?" permission map — each panel is gated independently.

| Panel             | Permissions evaluated for edit affordance                    |
| ----------------- | ------------------------------------------------------------ |
| Description       | `DATA_ENTITY_DESCRIPTION_UPDATE`                             |
| Attachments       | `DATA_ENTITY_ATTACHMENT_MANAGE`                              |
| Metadata (custom) | `DATA_ENTITY_CUSTOM_METADATA_CREATE`, `…_UPDATE`, `…_DELETE` |
| General — Owners  | `DATA_ENTITY_OWNERSHIP_CREATE`, `…_UPDATE`, `…_DELETE`       |
| Groups            | `DATA_ENTITY_ADD_TO_GROUP`, `DATA_ENTITY_DELETE_FROM_GROUP`  |
| Tags              | `DATA_ENTITY_TAGS_UPDATE`                                    |
| Terms             | `DATA_ENTITY_ADD_TERM`, `DATA_ENTITY_DELETE_TERM`            |

The page header carries its own per-affordance permission gates:

| Header affordance                                                                                | Permission                                                                      |
| ------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------- |
| Business name (Add / Edit)                                                                       | `DATA_ENTITY_INTERNAL_NAME_UPDATE`                                              |
| [Status](/features/data-discovery/statuses) change                                               | `DATA_ENTITY_STATUS_UPDATE`                                                     |
| [Data Entity Group](/features/data-discovery/groups-domains) edit (manually-created groups only) | `DATA_ENTITY_GROUP_UPDATE`                                                      |
| [Share to Slack](/features/active-platform-features/data-collaboration)                          | No separate permission — gated only by the `DATA_COLLABORATION` feature toggle. |

When auditing "what does role X see on this entity," cross-reference each row of the two tables above against the role's permissions via [Permissions](/configuration-and-deployment/enable-security/authorization/permissions). The detail page does not surface the role-to-affordance map in the UI; the audit lives in the role definitions.

When the entity's [status](/features/data-discovery/statuses) is `DELETED`, several Overview-tab and header edit affordances are hidden regardless of the operator's permissions — soft-deleted entities are read-only in the UI until the status is reverted. See [Data Entity Statuses → DELETED-state read-only surface](/features/data-discovery/statuses) for the per-affordance breakdown.

## Where to next

* [Catalog Overview page](/features/data-discovery/catalog-overview), [Search](/features/data-discovery/search), [Directory](/features/data-discovery/directory) — the three discovery entry paths that land an operator on this page.
* [Entity description](/features/data-discovery/entity-description), [Custom metadata](/features/data-discovery/custom-metadata), [Per-column annotation](/features/data-discovery/per-column-annotation), [Manual Object Tagging](/features/data-discovery/tagging), [Business names](/features/data-discovery/business-names), [Data Entity Statuses](/features/data-discovery/statuses), [Data Entity Groups & Domains](/features/data-discovery/groups-domains), [Data Entity Attachments](/features/data-discovery/attachments), [Metadata stale](/features/data-discovery/metadata-stale) — per-aspect deep dives for the panels and header affordances on this page.
* [Data Lineage](/features/data-lineage) — the Lineage tab on every entity detail page (class-dependent visibility).
* [Activity Feed](/features/active-platform-features/activity-feed) — the per-entity Activity tab; the audit trail for every change applied through this surface.
* [Main Concepts → Data Entity Class](/introduction/main-concepts) — the canonical class taxonomy whose enum values drive every per-class composition decision above.
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the role-definition surface where the per-affordance permissions on this page resolve.
* [Data Discovery overview](/features/data-discovery) — the bucket landing this page sits under.


# Entity description

Operator-authored Markdown description on each data entity — the platform's primary free-text annotation, persisted verbatim and rendered through the same component as terms and columns.

Every data entity in the catalog carries an **operator-authored description** — free-form Markdown that documents what the entity is for, who reads from it, what the columns mean, and any in-house context that the source system does not carry. The description appears on the entity's detail page as the primary narrative surface above the structural panels (schema, lineage, tags, terms), and it surfaces in search-result rows and the Recommended-tile previews as the first-encounter snippet.

This page covers the authoring workflow, the supported Markdown surface, the permissions that gate editing, the audit trail, and a load-bearing security caveat that applies to **six** of the platform's free-text Markdown surfaces.

## Where to find it

Open any data entity's detail page → **Overview** tab. The description occupies the top of the Overview body. Operators with the [`DATA_ENTITY_DESCRIPTION_UPDATE`](/configuration-and-deployment/enable-security/authorization/permissions) permission see an **Edit** affordance; readers without the permission see the rendered description and nothing else.

The same description text is also surfaced as the **preview snippet** on:

* [Search](/features/data-discovery/search) result rows.
* The Recommended-tile cards on the [Catalog Overview](/features/data-discovery/catalog-overview) home page.
* The [Directory](/features/data-discovery/directory)'s level-4 entity list rows.

The full Markdown rendering happens on the Overview tab; the preview surfaces above render an abbreviated plain-text projection.

## Authoring the description

The Edit affordance opens an inline Markdown editor (`@uiw/react-md-editor`) with split-pane preview. Operators type the description in Markdown; saving issues `PUT /api/dataentities/{id}/description` with a JSON body carrying the new description string. The platform persists the text **verbatim** into the `data_entity.internal_description` column (PostgreSQL `text`, no length cap, no transformation other than mapping the empty string to `null`).

Supported Markdown surface — what the renderer understands and the editor previews:

* Headings (`#`, `##`, `###`, …).
* Bold, italic, strikethrough.
* Inline and fenced code blocks (syntax highlighting on the fenced form via the renderer's highlighter).
* Bulleted and numbered lists, including nested lists.
* Links — `[text](https://...)` plus the auto-link convention `[[Namespace:Term]]` that resolves to a glossary term (see [Manual Object Tagging](/features/data-discovery/tagging) and the [Business Glossary](/features/data-glossary/business-glossary) for the term-linking workflow).
* Tables (GitHub-flavored).
* Raw HTML — the renderer parses embedded HTML (`rehype-raw`); as of 0.28.0 it then sanitises the parsed HTML (`rehype-sanitize`) before display, stripping scripts and event-handler / `javascript:` vectors. See the security caveat below.

The editor is the only place to author the description; there is no API-only path that bypasses the editor's preview. Third-party API clients calling `PUT /api/dataentities/{id}/description` directly write the same field — the stored value is verbatim either way (HTML sanitisation happens at render time, not on write).

## Permissions

Editing the description is gated by **one** permission:

| Permission                                                                                                  | What it gates                                                                                       |
| ----------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------- |
| [`DATA_ENTITY_DESCRIPTION_UPDATE`](/configuration-and-deployment/enable-security/authorization/permissions) | The Edit affordance on the Overview tab plus the `PUT /api/dataentities/{id}/description` endpoint. |

The permission is bound to the data entity in the URL (per the platform's RBAC model — see [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) for the full per-resource gating story). Operators without it see the rendered description but no Edit affordance.

## Activity trail

Description edits emit a `DESCRIPTION_UPDATED` event on the [Activity Feed](/features/active-platform-features/activity-feed). The event carries the entity id, the editor's identity, and the timestamp — and, in its old-state / new-state payload, the **full previous description and the full new description**. The Activity Feed is therefore a content-diff log for description edits, not merely an audit-of-occurrence: the per-entity Activity tab on the detail page reconstructs both *that* a description changed and *what* it changed from and to.

## Security caveat — stored-XSS family across six Markdown surfaces

The platform's description-authoring surfaces apply **no write-time HTML sanitisation** — operator-typed Markdown is persisted verbatim. Rendering is the defence point: as of **0.28.0** the platform's shared Markdown renderer sanitises parsed HTML (`rehype-raw` → `rehype-sanitize`) before display, so `<script>`, `<img onerror="…">`, `<svg onload="…">`, `<a href="javascript:…">`, and CSS-expression vectors embedded in a description are stripped at render time on the surfaces that use that shared renderer (see the table below). Releases up to 0.27.x rendered the parsed HTML as live markup for every reader.

{% hint style="danger" %}
**Treat description-authoring permissions as trusted-write authority.** The platform persists description text verbatim; the same description-shaped Markdown field appears in **six** places across the platform:

The **first four** surfaces — entity description, column description, term definition, and Query Examples (`definition` + `query`) — share the catalog's Markdown renderer, and **0.28.0 added render-time HTML sanitisation (`rehype-sanitize`) to it**, closing the embedded-HTML/script vector on those four. The remaining **two** reach different rendering layers that fix does not cover: Lookup Tables renders cell values into the table viewer, and Slack uses its own `mrkdwn` parser on the notification side. All six write paths persist the operator-supplied text verbatim.

**For the four shared-renderer surfaces the defence is now platform-side**: the `rehype-sanitize` pass added in 0.28.0 strips `<script>`, inline event-handler attributes (for example `onerror`), `javascript:` URLs, and the `<svg onload>` / CSS-expression vectors before display. **For the two remaining surfaces (Lookup Tables, Slack) there is no platform-side sanitisation** — they rely on the rendering tier's own behaviour (Chromium's `<script>`-execution policy, React stripping inline event-handler attributes) plus operator trust, and the residual `<svg onload>`, CSS-expression, and `javascript:`-URL vectors are not blocked by the platform on those two paths. Sanitisation everywhere is a render-time defence: the stored value is persisted unchanged on all six write paths.

**Mitigation today.** The four shared-renderer surfaces are sanitised at render time as of 0.28.0. For the two remaining surfaces (Lookup Tables, Slack) — and as defence-in-depth on every write path — restrict the `DATA_ENTITY_DESCRIPTION_UPDATE` permission (and its five siblings on the table above) to operators reviewing the source of every value they paste in, the same posture you would apply to any "free-text into the database" surface, and avoid bulk-importing descriptions from external systems without a sanitisation pre-pass.
{% endhint %}

| Surface                                                                            | Canonical home                                                          | Authoring path                                                                         |
| ---------------------------------------------------------------------------------- | ----------------------------------------------------------------------- | -------------------------------------------------------------------------------------- |
| Entity description                                                                 | this page                                                               | `PUT /api/dataentities/{id}/description`                                               |
| Dataset field (column) description                                                 | [Per-column annotation](/features/data-discovery/per-column-annotation) | `PUT /api/datasetfields/{id}/description`                                              |
| Business glossary term definition                                                  | [Business Glossary](/features/data-glossary/business-glossary)          | `POST /api/terms` / `PUT /api/terms/{id}`                                              |
| Query Example `definition` + `query`                                               | [Query Examples](/features/data-modelling/query-examples)               | `POST /api/queryexample`                                                               |
| Lookup Table cell values + column names + table name                               | [Lookup Tables](/features/master-data-management/lookup-tables)         | `POST /api/referencedata/table/{id}/data`                                              |
| Slack-notification body (alert chunk descriptions rendered through Slack `mrkdwn`) | [Notifications](/features/active-platform-features/notifications)       | `POST /ingestion/alert/alertmanager` (the inbound webhook embeds description verbatim) |

## Where to next

* [Data entity detail page](/features/data-discovery/entity-detail-page) — the per-entity surface where the description renders alongside the schema, lineage, tags, and terms panels.
* [Per-column annotation](/features/data-discovery/per-column-annotation) — the column-level counterpart with the same authoring + rendering pipeline (and the same security caveat).
* [Business Glossary](/features/data-glossary/business-glossary) — term definitions, the `[[Namespace:Term]]` auto-link target, and the term-mention side-channel.
* [Custom metadata](/features/data-discovery/custom-metadata) — operator-curated metadata field catalogue and per-entity value assignments; a sibling per-entity surface on the Overview tab.
* [Manual Object Tagging](/features/data-discovery/tagging) — the lightweight labelling counterpart for cross-cutting groupings.
* [Permissions → DATA\_ENTITY\_DESCRIPTION\_UPDATE](/configuration-and-deployment/enable-security/authorization/permissions) — the canonical permission row for the Edit affordance.
* [Activity Feed → DESCRIPTION\_UPDATED](/features/active-platform-features/activity-feed#event-types) — the audit-feed event emitted on every description edit.


# Custom metadata

Operator-curated metadata on data entities — a paired surface combining a deployment-wide field catalogue with per-entity value assignments. Surfaced on the entity's Overview tab.

Every data entity in the catalog carries a **Custom metadata** panel — a key/value list operators populate to capture per-entity facts the source system does not provide (cost-centre allocation, regulated-PII flag, downstream-consumer team, freshness SLA, anything you want to attach as a typed annotation). Two halves sit behind the panel: a **field catalogue** that defines the available keys for the deployment, and a per-entity **value set** that binds each key to a value for one specific entity.

This page covers both halves — how the catalogue is populated, how per-entity values are authored, how the two origins (operator-curated **INTERNAL** vs collector-ingested **EXTERNAL**) differ, the permission gates, and the load-bearing caveats: the silent-no-op write path, the dropped `active` flag, the absence of server-side type validation, the API path that overwrites EXTERNAL values, the unauthenticated catalogue enumeration, and the absence of activity-feed events on metadata mutations.

## Where to find it

Open any data entity's detail page → **Overview** tab. The **Metadata** panel renders in the main column below the [description](/features/data-discovery/entity-description) and [attachments](/features/data-discovery/attachments) panels. The panel shows a combined list — operator-curated fields and collector-ingested fields rendered side by side, distinguished by the field's **Origin** badge.

Operators with the [`DATA_ENTITY_CUSTOM_METADATA_CREATE`](/configuration-and-deployment/enable-security/authorization/permissions) permission see an **Add** affordance for assigning a new field value to the entity; the affordance opens an autocomplete picker over the deployment's field catalogue (with the option to type a new field name on miss — see the catalogue side-channel caveat below). Operators with `_UPDATE` see an in-place edit affordance on each existing value; operators with `_DELETE` see a remove affordance.

## The two halves

**Field catalogue (deployment-scoped vocabulary).** A `metadata_field` table holds one row per field name + type pair the deployment knows about. The catalogue is shared across every entity in the deployment — the same `cost_centre` field name resolves to the same `metadata_field.id` for every entity that uses it. Reading the catalogue is what powers the autocomplete picker when an operator adds a new value to an entity, and the catalogue read is the **only** read of the metadata surface that does not go through the per-entity endpoint.

**Per-entity value set (entity-scoped binding).** A `metadata_field_value` table holds one row per `(data_entity_id, metadata_field_id)` pair — the binding that says "this entity has this field set to this value." Operators author each row through the per-entity write endpoints listed below; the read side ships the bound values back as part of the entity's detail-page payload.

## Field types and origin

Fields carry two pieces of metadata beyond the name: a **type** (the value's shape) and an **origin** (who owns the field's existence in the catalogue).

**Supported field types** — the type is set when the field is first minted in the catalogue and is immutable thereafter. Seven types are selectable when authoring a field:

* `STRING` — free-text.
* `INTEGER`, `FLOAT` — numeric.
* `BOOLEAN` — `true` / `false`.
* `DATETIME` — ISO-8601 timestamp.
* `ARRAY` — a list of strings (each element rendered as a chip in the value display).
* `JSON` — arbitrary JSON document (rendered as collapsible tree in the value display).

The platform's internal type enum carries one more value, `UNKNOWN`, beyond the seven above (the public API `MetadataFieldType` enum exposes only the seven). `UNKNOWN` is a defensive fallback the ingestion parser assigns when it cannot classify a collector-supplied value into one of the seven shapes — it is not offered when authoring a field and is not a type an operator chooses.

The per-entity value side stores the value as a JSON-encoded string regardless of declared type; the type drives the value-editor's input shape and the display formatter. **The API does not enforce the declared type on write** — see the caveat below.

**Origin** — two values, mutually exclusive per field:

* **INTERNAL** — operator-curated. The field was minted by a catalog user authoring a value on an entity (see the auto-create-on-miss side-channel below) or by an explicit catalogue mutation. INTERNAL fields are the only ones surfaced in the autocomplete picker on the Add-value affordance.
* **EXTERNAL** — collector-ingested. The field came in attached to an entity via the ingestion pipeline (a collector's adapter mapped a source-side property into ODD's metadata schema). EXTERNAL fields render alongside INTERNAL fields in the entity's Metadata panel but cannot be edited or added from the **UI** — they are owned by the source system and refreshed on every ingestion pass. The **API** does not enforce that boundary, though — see the EXTERNAL-origin caveat below.

When an operator views an entity's Metadata panel, both origins render in the same list. The UI distinguishes them with an inline origin marker; the Add affordance only writes INTERNAL.

## Field naming is case-sensitive

Field names in the catalogue are **case-sensitive**. `cost_centre` and `Cost_centre` are two distinct rows in `metadata_field`; an operator who types `Cost_centre` into the autocomplete picker, sees no match, and accepts the auto-create-on-miss side-channel (below) mints a parallel field that operators searching for `cost_centre` will not find. The autocomplete query uses a case-insensitive substring match for the suggestion list, but the resolution against the catalogue is by exact-string match — autocomplete saves a few keystrokes; it does not protect against case-drift duplicates.

Treat field names as a controlled vocabulary that benefits from a documented naming convention (`snake_case` is the most common in deployments we have seen). A naming-convention drift is the most common source of "I added this field on entity X yesterday but I can't find it in the autocomplete on entity Y today" reports.

## Authoring per-entity values

Three operations exist on the per-entity side, each gated by a distinct permission:

| Operation                                                                                      | Endpoint                                                     | Permission                           |
| ---------------------------------------------------------------------------------------------- | ------------------------------------------------------------ | ------------------------------------ |
| Create one or more new field values on an entity (each carrying the field name + type + value) | `POST /api/dataentities/{id}/metadata`                       | `DATA_ENTITY_CUSTOM_METADATA_CREATE` |
| Update an existing field value on an entity (by field id)                                      | `PUT /api/dataentities/{id}/metadata/{metadata_field_id}`    | `DATA_ENTITY_CUSTOM_METADATA_UPDATE` |
| Delete a field value from an entity (by field id)                                              | `DELETE /api/dataentities/{id}/metadata/{metadata_field_id}` | `DATA_ENTITY_CUSTOM_METADATA_DELETE` |

The Create path takes a list of field objects (`name`, `type`, `value`) in the request body — each entry either resolves against an existing INTERNAL field in the catalogue (matched by exact name + type) or **mints a new INTERNAL field** in the catalogue on the spot. The Update and Delete paths are by field id and operate on the per-entity value row only — they never touch the catalogue.

There is no operator-facing catalogue-maintenance UI: INTERNAL field rows are created as a side effect of the Create-value path, and the catalogue read endpoint (`GET /api/metadata/fields`) returns the full INTERNAL set with optional substring-filter parameter for autocomplete.

## Permissions

Three permissions gate the per-entity surface; the catalogue read is **not gated** by a custom-metadata permission (see the unauthenticated-enumeration caveat below).

| Permission                                                                                                      | What it gates                                                                                                                                               |
| --------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------- |
| [`DATA_ENTITY_CUSTOM_METADATA_CREATE`](/configuration-and-deployment/enable-security/authorization/permissions) | The Add affordance + `POST /api/dataentities/{id}/metadata`. Includes the auto-create-on-miss side-channel that mints new INTERNAL fields in the catalogue. |
| [`DATA_ENTITY_CUSTOM_METADATA_UPDATE`](/configuration-and-deployment/enable-security/authorization/permissions) | The edit affordance on each value row + `PUT /api/dataentities/{id}/metadata/{metadata_field_id}`.                                                          |
| [`DATA_ENTITY_CUSTOM_METADATA_DELETE`](/configuration-and-deployment/enable-security/authorization/permissions) | The remove affordance on each value row + `DELETE /api/dataentities/{id}/metadata/{metadata_field_id}`.                                                     |

All three are scoped to the data entity in the URL — granting `_CREATE` on entity X does not grant it on entity Y. The catalogue read (`GET /api/metadata/fields`) is reachable by every authenticated caller and, under `auth.type=DISABLED`, by every anonymous caller (see [DISABLED authentication](/configuration-and-deployment/enable-security/authentication/disabled-authentication)).

## Activity trail

Custom-metadata mutations **emit no Activity Feed event today.** The [`ActivityEventTypeDto`](https://github.com/opendatadiscovery/odd-platform/blob/main/odd-platform-api/src/main/java/org/opendatadiscovery/oddplatform/dto/activity/ActivityEventTypeDto.java) enum carries `CUSTOM_METADATA_CREATED`, `CUSTOM_METADATA_UPDATED`, and `CUSTOM_METADATA_DELETED` values, but no code path emits any of them — they are dead enum entries. Operators looking at an entity's Activity tab will see description updates, tag updates, owner updates, and term assignments, but not metadata-value changes. See the caveat in the next section for the forensic-silence implications.

## Known limitations and operator caveats

{% hint style="warning" %}
**The Update path is a silent no-op when the value row does not pre-exist.** The platform's `PUT /api/dataentities/{id}/metadata/{metadata_field_id}` endpoint declares its operation as `upsertDataEntityMetadataFieldValue` in the OpenAPI spec, but the repository call behind it is a pure SQL `UPDATE` against `metadata_field_value` keyed on `(data_entity_id, metadata_field_id)` — no `INSERT ... ON CONFLICT` fallback. If the row does not exist (the field has never been assigned a value on this entity), the UPDATE matches zero rows, returns nothing, and the controller propagates an empty `Mono`. The HTTP response is `200 OK` with an empty body; the UI toast reads "Metadata successfully updated." even though nothing was written.

**What this means in practice.** Reconciliation pipelines that issue PUTs assuming upsert semantics (the operationId implies replace-or-create) silently lose writes for any field not previously assigned on the target entity. The bootstrap path that does work is `POST /api/dataentities/{id}/metadata` (the Create endpoint), which mints the field on the catalogue and binds the value to the entity in one call.

**Mitigation today.** Issue a GET preflight against the entity's metadata before any PUT — if the field id is not in the response, switch to a POST. The platform-side fix (true upsert semantics, or rejecting the PUT with a meaningful error when no row matches) is on the roadmap; until it lands, the doc-only preflight is the operator-side workaround.
{% endhint %}

{% hint style="warning" %}
**Every successful Update silently sets the `active` column on the value row to `NULL`.** The service layer constructs the persistence pojo without calling `setActive(...)`; the Java `Boolean` field stays null. The repository's UPDATE writes the null verbatim into the row's `active` column, overwriting whatever value the row carried previously. The column's database `DEFAULT TRUE` only fires on INSERT — it does not protect UPDATE — so every edited row ends up with `active IS NULL`.

**What this means in practice.** Any downstream code (in the platform, in a future feature, or in an external query) that filters `WHERE active = TRUE` will silently drop edited rows. The currently-shipping platform code does not appear to filter on `active` for the value rows, so this caveat is latent rather than user-visible today — but it is a foot-gun for anyone querying the table directly, building an external analytics view over it, or relying on future platform code to honour the column. Use `WHERE active IS DISTINCT FROM FALSE` (treats null as active) rather than `WHERE active = TRUE` when querying the table outside the platform's own service code.

The platform-side fix is to either set `setActive(true)` on the service-layer pojo before the UPDATE, or to exclude the `active` column from the UPDATE's SET clause entirely.
{% endhint %}

{% hint style="warning" %}
**The API does not validate a value against its field's declared type.** The declared type (`INTEGER`, `BOOLEAN`, `DATETIME`, and so on) drives the UI value editor and the display formatter, but the write endpoints store whatever string the request body carries — there is no server-side type check. A `POST` or `PUT` can persist `"not a number"` on an `INTEGER` field or `"maybe"` on a `BOOLEAN` field, and the platform accepts it with a `200`.

**What this means in practice.** The UI editor is the only thing enforcing type shape; an SDK client, a `curl`, or a reconciliation pipeline writing directly to the API can land type-violating values that then render through a formatter expecting the declared type. Validate the value shape on the writer side before the call — the platform will not reject a mismatch for you.
{% endhint %}

{% hint style="warning" %}
**The API lets an operator overwrite an EXTERNAL (collector-ingested) value; only the UI hides it.** The UI suppresses edit affordances on EXTERNAL fields, but the per-entity write endpoints (`POST` / `PUT /api/dataentities/{id}/metadata`) do not check the field's origin. An operator with `DATA_ENTITY_CUSTOM_METADATA_UPDATE` can write a value onto an EXTERNAL field through the API directly.

**What this means in practice.** The overwrite is **not durable** — the next ingestion pass for that entity replaces the collector-owned value again, so a hand-edited EXTERNAL value silently reverts on the next collector run. Treat EXTERNAL fields as read-only in any integration even though the API does not enforce it; if a value needs to change permanently, change it at the source the collector ingests from.
{% endhint %}

{% hint style="danger" %}
**The catalogue read is unauthenticated and unbounded, and the per-entity Create path mints new INTERNAL fields visible to every authenticated user.** Two compounding shapes here:

* `GET /api/metadata/fields` has **no entry** in the platform's security rules — the path falls through to the default `.authenticated()` matcher, so every authenticated caller can list the catalogue. Under `auth.type=DISABLED` (no authentication required at all), the endpoint is reachable by every anonymous caller too. The response carries every INTERNAL field name in the deployment.
* The same endpoint's SQL has no `LIMIT`, no `OFFSET`, and no `ORDER BY` clause. Every call returns the entire catalogue. The response's `PageInfo` is theatre — `total` is computed as `items.size()` on every call (so it always equals the response length, not the catalogue size) and `hasNext` is hardcoded `false`. SDK clients written from the OpenAPI spec build "load more" infinite-scroll workflows that never fire; the catalogue ships as a single response per call.

**What this means in practice.** Deployments with operator-named field schemas (`finance_cost_centre`, `marketing_attribution`, `pii_redaction_rule`, `aml_review_status`, anything that names team-internal taxonomy in the field name) leak the full vocabulary to every authenticated user — and to every anonymous user under DISABLED. A user with `DATA_ENTITY_CUSTOM_METADATA_CREATE` on a single entity can mint a new INTERNAL field through the Create-value path that becomes visible to every other user on their next autocomplete keystroke.

Production deployments with 10K+ INTERNAL field rows pay a 1–2 MB response on every autocomplete keystroke (the endpoint accepts a query parameter, but the filter is applied server-side after fetching the unbounded result set; there is no DB-level early termination).

**Mitigation today.** Treat custom metadata field names as deployment-public. If a field name itself encodes sensitive information about a team's workflow or taxonomy, do not put it in custom metadata — author it in a system the platform does not enumerate. Grant `DATA_ENTITY_CUSTOM_METADATA_CREATE` only to operators trusted to mint new vocabulary; the auto-create-on-miss side-channel makes the permission an indirect grant of catalogue-write access. The platform-side fix (introducing a `CUSTOM_METADATA_FIELD_READ` permission + adding a security rule for the catalogue endpoint + paginating the SQL + computing real `total` and `hasNext`) is on the roadmap.
{% endhint %}

{% hint style="info" %}
**Custom-metadata mutations leave no audit trail in the Activity Feed.** Three dead enum values exist in the platform's `ActivityEventTypeDto` — `CUSTOM_METADATA_CREATED`, `CUSTOM_METADATA_UPDATED`, `CUSTOM_METADATA_DELETED` — but no code path emits any of them. The entity's Activity tab shows other mutations (description, tags, owners, terms) but not metadata-value writes or deletes. Same forensic-silence pattern as the [DEG-membership write paths](/features/data-discovery/groups-domains#managing-deg-membership) and the [`DATA_ENTITY_RELATION_UPDATED` dead enum](/features/active-platform-features/activity-feed#known-caveats).

For compliance teams that need a who-changed-what-when trail on custom metadata, instrument it externally — an API-gateway access log records the authenticated POST / PUT / DELETE calls; the PostgreSQL WAL via `pgaudit` records the `metadata_field_value` row writes. See [Audit trail scope](/configuration-and-deployment/enable-security/audit-trail-scope) for the compensating-controls catalogue across every silent-mutation surface the platform carries today.
{% endhint %}

## Where to next

* [Entity description](/features/data-discovery/entity-description) — the sibling per-entity Overview surface; same Add / Edit affordance shape but a single free-text Markdown field rather than a typed key/value catalogue. Carries its own load-bearing caveat (no write-time HTML sanitisation across six Markdown surfaces).
* [Data entity detail page](/features/data-discovery/entity-detail-page) — the parent container for the Metadata panel; covers how the panel composes with the rest of the Overview tab.
* [Activity Feed](/features/active-platform-features/activity-feed) — the audit trail for entity-level mutations, and the canonical home for the forensic-silence framing that custom-metadata writes share with DEG-membership writes.
* [Audit trail scope](/configuration-and-deployment/enable-security/audit-trail-scope) — the compliance-facing summary of what the platform audits today and what it does not, including the compensating controls for the silent-mutation surfaces.
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the canonical home for the three `DATA_ENTITY_CUSTOM_METADATA_*` permissions and the full per-resource gating story.


# Per-column annotation

Per-column annotation on a dataset's Structure tab — description, tags, glossary terms, enum values, and business name editors on each column row, plus the write-path and UI caveats.

Every dataset in the catalog exposes a **Structure** tab next to its Overview tab. The Structure tab lists the dataset's columns and lets an operator annotate each column with a description, tags, business-glossary terms, enum values, and a business name — the column-level counterparts to the entity-level Overview surfaces. Each column row opens a composer that hosts five sub-editors stacked vertically; saving a sub-editor calls a distinct backend endpoint per sub-surface.

This page covers the composer's five sub-editors, the permissions each one is gated by, the audit-trail coverage per sub-surface, and three load-bearing write-path caveats plus two latent UI hazards.

## Where to find it

Open any dataset's detail page → **Structure** tab. The columns table lists every column with its name, type, primary-key flag, source-side description, and the operator-authored annotations (when set). Clicking a column row expands the composer below the row, surfacing five sub-editors in order:

1. **Description** — free-text Markdown rendered with the same pipeline as the entity-level [description](/features/data-discovery/entity-description).
2. **Tags** — column-scoped tag chips, sharing the deployment-wide tag vocabulary with [Manual Object Tagging](/features/data-discovery/tagging).
3. **Glossary terms** — business-glossary terms linked to the column, separately from terms linked to the parent dataset (see [Business Glossary](/features/data-glossary/business-glossary)).
4. **Enum values** — operator-curated enumeration list documenting the column's allowed values (one row per enum entry with a label and a description).
5. **Business name** — a human-readable alternative to the technical column name, surfaced alongside the technical name everywhere the column is rendered (see [Business names](/features/data-discovery/business-names)).

The composer is the only place to author these annotations; the API is the same surface — third-party clients calling the per-sub-editor endpoints listed below write the same fields with the same caveats.

## Permissions

Each sub-editor is gated by a distinct permission:

| Sub-editor    | Permission                                                                                                      | What it gates                                                                                                                                    |
| ------------- | --------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------ |
| Description   | [`DATASET_FIELD_DESCRIPTION_UPDATE`](/configuration-and-deployment/enable-security/authorization/permissions)   | The Description sub-editor + `PUT /api/datasetfields/{id}/description`.                                                                          |
| Tags          | [`DATASET_FIELD_TAGS_UPDATE`](/configuration-and-deployment/enable-security/authorization/permissions)          | The Tags sub-editor + `PUT /api/datasetfields/{id}/tags`.                                                                                        |
| Term — add    | [`DATASET_FIELD_ADD_TERM`](/configuration-and-deployment/enable-security/authorization/permissions)             | The Add-term affordance on the Terms sub-editor. **See the wiring-bug caveat below — this permission is not the one the server enforces today.** |
| Term — delete | [`DATASET_FIELD_DELETE_TERM`](/configuration-and-deployment/enable-security/authorization/permissions)          | The remove-affordance on each term row + `DELETE /api/datasetfields/{id}/terms/{term_id}`.                                                       |
| Enum values   | [`DATASET_FIELD_ENUMS_UPDATE`](/configuration-and-deployment/enable-security/authorization/permissions)         | The Enum-values sub-editor + `POST /api/datasetfields/{id}/enum_values`.                                                                         |
| Business name | [`DATASET_FIELD_INTERNAL_NAME_UPDATE`](/configuration-and-deployment/enable-security/authorization/permissions) | The Business-name affordance + `PUT /api/datasetfields/{id}/name`.                                                                               |

All six are scoped against the dataset that owns the column in the URL, not the column itself — granting any of them on a dataset grants the corresponding edit on every column of that dataset.

## Activity trail

Each sub-editor emits its own Activity Feed event on save:

| Sub-editor           | Activity event                          | Payload                          |
| -------------------- | --------------------------------------- | -------------------------------- |
| Description          | `DATASET_FIELD_DESCRIPTION_UPDATED`     | Before / after description text. |
| Tags                 | `DATASET_FIELD_TAGS_UPDATED`            | Before / after tag-name sets.    |
| Term — add or delete | `DATASET_FIELD_TERM_ASSIGNMENT_UPDATED` | Before / after term-id sets.     |
| Enum values          | `DATASET_FIELD_VALUES_UPDATED`          | Before / after enum-value sets.  |
| Business name        | `DATASET_FIELD_INTERNAL_NAME_UPDATED`   | Before / after business name.    |

All five emit the full before/after payload — column-level annotations have a fuller audit shape than several entity-level mutations (see the [Activity Feed scope summary](/features/active-platform-features/activity-feed) and the [Audit trail scope](/configuration-and-deployment/enable-security/audit-trail-scope) for the platform-wide audit-coverage matrix).

## Known limitations and operator caveats

{% hint style="danger" %}
**The field-level "Add term" affordance silently fails for users holding `DATASET_FIELD_ADD_TERM`.** Two adjacent SecurityConstants entries are crossed in the platform's authorization wiring at `SecurityConstants.java:295-299`:

**Operator-visible effect of the column-term bug.** A user with `DATASET_FIELD_ADD_TERM` on a dataset sees the column-level Add-term button enabled (the UI gates on the documented permission). Clicking it submits the request and the server rejects it as `403 Forbidden`. The UI catches the error silently — the term row never appears in the column's Terms list, and there is no visible error toast. The operator sees the affordance, clicks it, sees nothing happen, retries, sees nothing happen again, and gives up. The workaround today: grant `DATA_ENTITY_ADD_TERM` (the entity-scope permission) instead of, or in addition to, `DATASET_FIELD_ADD_TERM`.

**Operator-visible effect of the alert-status bug.** A user with `DATASET_FIELD_ADD_TERM` can resolve any alert on any entity. The intended permission for alert-status mutation is `DATA_ENTITY_ALERT_RESOLVE` (see [Alerting](/features/active-platform-features/alerting)). Audit a deployment's `DATASET_FIELD_ADD_TERM` grants if alert-resolution audit matters to compliance.

**Mitigation today.** Grant `DATA_ENTITY_ADD_TERM` to operators who need to link terms to columns; treat `DATASET_FIELD_ADD_TERM` grants as also-granting alert-resolution. The upstream fix is two one-line changes to the platform's security-rule wiring; until it ships, the documented permission list and the runtime gate diverge.
{% endhint %}

| Endpoint                                                                    | Documented permission (UI gate) | Server-enforced permission (runtime gate) |
| --------------------------------------------------------------------------- | ------------------------------- | ----------------------------------------- |
| `PUT /api/alerts/{alert_id}/status` (resolve an alert)                      | `DATA_ENTITY_ALERT_RESOLVE`     | `DATASET_FIELD_ADD_TERM`                  |
| `POST /api/datasetfields/{dataset_field_id}/terms` (add a term to a column) | `DATASET_FIELD_ADD_TERM`        | `DATA_ENTITY_ADD_TERM`                    |

{% hint style="warning" %}
**Saving the column's enum-values list silently soft-deletes any pre-existing values not present in the submitted body.** The platform's `POST /api/datasetfields/{id}/enum_values` endpoint declares its operation as `createEnumValue` in the OpenAPI spec (the name implies create-one), but the underlying service is a **bulk replace** — items whose `id` is null are inserted; items whose `id` is present are updated; **every pre-existing row whose id is not in the submitted list is soft-deleted**.

The Structure-tab UI handles this correctly: when the operator edits any single row, the composer submits the **full** current set (preserving all existing rows that the operator did not touch). The hazard is on the **API surface** — a third-party SDK consumer reading the operation name in the OpenAPI spec, assuming create-one semantics, and submitting only the new row will silently soft-delete every other enum value on the column.

The silent soft-delete applies only when the column's enum values are **all operator-curated (INTERNAL)**. If even one **collector-ingested (EXTERNAL)** enum value is present on the column, the endpoint instead **rejects** any submission whose value-name set does not exactly match the values already on the column — the call fails with `400 Bad Request` ("User cannot create or delete external enum values") rather than soft-deleting. On such a column you can only edit the descriptions of the existing values; you cannot add or remove values through this endpoint.

**Mitigation today.** Treat the endpoint as "submit the full target enum set, every time." A GET-then-POST pattern is the safe shape. The upstream fix is a rename to `replaceEnumValues` (or a true append-only `createEnumValue` plus a separate `replaceEnumValues`); the spec's `description` field already acknowledges the actual behaviour ("Creates/updates/deletes enum values with their description").
{% endhint %}

{% hint style="warning" %}
**Saving the column's tag list as an empty array silently clears every operator-curated tag on the column.** The platform's `PUT /api/datasetfields/{id}/tags` endpoint deletes every INTERNAL-origin tag-to-column row first, then re-inserts the submitted set. Submitting `{"tagNameList": []}` succeeds with no error and leaves the column with zero operator-curated tags. The full before/after payload is captured in the `DATASET_FIELD_TAGS_UPDATED` activity event — the deletion is auditable, but a user fast-clicking through the Structure tab does not see it as destructive.

EXTERNAL-origin tags (collector-ingested via the `EXTERNAL_STATISTICS` channel) **survive** the operation — only INTERNAL-origin tag rows are cleared. A column whose tags came entirely from a collector retains them; a column with operator-added tags loses them.

**Mitigation today.** Submit the full target tag set on every save, not an empty list. The Structure-tab UI submits the current tag set correctly; the hazard, again, is on the API surface for third-party SDK consumers.
{% endhint %}

{% hint style="warning" %}
**Fast-switching between columns while a sub-editor is open may submit the previous column's data against the new column's id (unverified hazard).** The composer mounts all five sub-editors unconditionally for the active column. When an operator clicks a different column row while a sub-editor's modal is open, the sub-editor stays mounted but the active-column id atom updates; the form state was initialised from the previous column's data. Depending on which sub-editor is open and how the form-state closure was captured at mount time, a save click on the open modal **may** submit the previous column's values against the new column's id.

This hazard is currently **not verified by a runtime probe** — the failure shape is inferred from the composer's source structure. Saves on the affected sub-editors are gated by their permissions and the activity feed captures the after-state, so a fast-switching mistake would be auditable. Until a probe confirms or rules out the hazard, **always close the open sub-editor before clicking a different column**.

The upstream fix is straightforward (a confirm-on-close + form-reset on column-id change); the doc-side caveat persists until the fix lands.
{% endhint %}

## Where to next

* [Data entity detail page](/features/data-discovery/entity-detail-page) — the parent container for the Structure tab and the Overview tab; covers the per-class panel matrix that decides which tabs appear.
* [Entity description](/features/data-discovery/entity-description) — the entity-level counterpart to the column-level description sub-editor; shares the Markdown renderer and the load-bearing no-write-time-sanitisation caveat across six surfaces (this page is one of the six).
* [Custom metadata](/features/data-discovery/custom-metadata) — sibling per-entity Overview surface for typed key/value annotations; same authoring philosophy, different cardinality.
* [Manual Object Tagging](/features/data-discovery/tagging) — the read-side canonical home for tags, including the operator-caveat list for the global vocabulary the column-level Tags sub-editor writes into.
* [Business Glossary](/features/data-glossary/business-glossary) — the canonical home for terms; the column-level Terms sub-editor is one of three places terms can be linked (alongside the entity-level Terms panel and the term-mention `[[Namespace:Term]]` auto-link in any Markdown description).
* [Business names](/features/data-discovery/business-names) — the canonical home for business-name semantics; the column-level Business-name sub-editor shares the same vocabulary.
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the canonical home for the six `DATASET_FIELD_*` permissions and the wiring-bug flag on `DATASET_FIELD_ADD_TERM`.


# Manual Object Tagging

Manual Object Tagging — apply tags to data entities and columns; the read-side counterpart to Management → Tags.

Tags are the platform's lightweight labelling mechanism — apply them to tables, datasets, columns, and quality tests to drive faceted search, organise the catalog by domain or stage, and signal special handling (`PII`, `Important`, `Deprecated`).

This page is the **read-side canonical home** for tagging — how operators apply, browse, and filter by tags. The operator-mutating side (curate the tag vocabulary, set the Important flag, manage namespace-scoped tags) lives at [Management → Tags](/features/management).

## What tags are

A tag is an operator-curated label that can be attached to any data entity or to any individual column. Tags drive:

* **Discovery.** The Tag facet on [Search and Filtering](/features/data-discovery/search) is one of the seven catalog filters; selecting one or more tags narrows the search to entities carrying any of them.
* **Organisation.** Tags are how operators encode lightweight, cross-cutting groupings that do not justify their own [Data Entity Group](/features/data-discovery/groups-domains).
* **Catalog Overview surfacing.** The most-used tags surface as the **Top tags** chip strip on the Catalog Overview home page — one-click filter into the catalog.
* **Important-flag visibility.** A tag flagged as **Important** in [Management → Tags](/features/management) is rendered visually distinct on entity pages and result rows, surfacing high-priority labels (`PII`, `Restricted`, `Deprecated`) without requiring operators to scan every tag chip.

## Applying tags

Apply tags both to data assets as a whole and to individual columns of datasets.

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-d6e3914cd56171e90b3ee11fefccc578e9781c04%2Ftagging.gif?alt=media)

The same UI flow applies at both granularities — open the entity (or column) detail surface, click the tag-management control, and pick from the existing tag vocabulary or create a new tag inline.

The platform exposes three `TAG_*` RBAC permissions:

| Permission   | Action                                      |
| ------------ | ------------------------------------------- |
| `TAG_CREATE` | Create a new tag in the catalog vocabulary. |
| `TAG_UPDATE` | Edit a tag's name or its Important flag.    |
| `TAG_DELETE` | Remove a tag from the catalog vocabulary.   |

Plus the cross-cutting `TAG_ASSIGNMENT_UPDATED` activity-event marker emitted whenever tag assignments on an entity change. This is **not** an RBAC permission — it is an entry on the `ActivityEventType` enum, surfaced on the [Activity Feed](/features/active-platform-features/activity-feed) for the affected entity rather than gating who can mutate tags.

For the platform-wide permission catalog and how to compose roles around these permissions, see [Permissions](/configuration-and-deployment/enable-security/authorization/permissions).

## Tag-driven discovery

Once tags are applied, three discovery paths rely on them:

* [**Search → Tag facet**](/features/data-discovery/search) — multi-select filter; results match entities carrying any of the selected tags.
* **Catalog Overview → Top tags** — one-click chip strip filtering into the catalog by the most-used tags across the deployment, rendered on the home page.
* **Tag-based per-entity badges** — tags appear on entity detail pages and in search result rows; Important-flagged tags render visually distinct.

## Operator workflow

The full lifecycle of a tag splits across two surfaces by design:

1. **Author the vocabulary** — go to [Management → Tags](/features/management) to create the canonical tag list, set the Important flag where appropriate, and govern the vocabulary across teams.
2. **Apply tags** — on entity detail pages, attach tags from the curated vocabulary to specific entities and columns.
3. **Narrow searches** — use the Tag facet on the Catalog page to find tagged entities.

Tags appear in two places, each for a different user action. This page covers **applying tags to entities and finding entities by tag**. The [Management → Tags](/features/management) page is where operators **create and edit the tag vocabulary itself** — renaming, deleting, marking tags as `Important` for higher list ordering. Apply and find by tags here; manage the catalog of tags there.

## Known limitations and operator caveats

A few behaviours of the tagging surface are non-obvious from the UI alone. Each item below states what an operator might assume, what actually happens, and what to do today.

{% hint style="info" %}
**Fixed in 0.28.0 — "Top tags" and the Tag-facet seed list now rank by true popularity.** Releases up to 0.27.x truncated the tag directory to the requested page size **before** computing per-tag usage (the window ordered by `tag.id`), so once the directory exceeded the page size the strip showed the oldest tags re-ranked among themselves and younger, more-used tags never appeared (the empirical case: 35 tags, `size=30` — the 5 youngest absent regardless of usage). As of 0.28.0 the platform aggregates usage over the full directory first, then orders by usage count with tag id as a deterministic tiebreak, then paginates — the endpoint's "sorted by popularity" promise holds past one page and page boundaries are stable. No operator action needed; the pre-0.28.0 workaround (querying tag-to-entity relations directly for governance reviews) is no longer necessary.
{% endhint %}

{% hint style="warning" %}
**Five paths mint new tags into the global tag directory — not only `TAG_CREATE`.** An operator restricting `TAG_CREATE` to "vocabulary stewards" might assume that closes the directory to free-form additions. It does not. Every one of the following surfaces silently creates a new tag row for any name that does not already exist in the catalog:

The four `*_TAGS_UPDATE` permissions and the collector ingestion path all call the platform's shared `getOrCreateTagsByName` helper, which creates rows for any novel names before attaching them to the target entity. Any user holding per-entity / per-term / per-column tag-update on a single entity (or any collector ingestion) can therefore enlarge the global tag vocabulary visible to every user via `GET /api/tags`, the Top-Tags strip, and the Tag-facet seed list.

**Mitigation today:** if vocabulary governance matters in your deployment, withhold the `*_TAGS_UPDATE` permissions from rank-and-file users; do not rely on `TAG_CREATE` alone. The collector ingestion path is not gated by RBAC and cannot be locked down through permissions — restrict it via the upstream collector configuration or by reviewing ingested tags periodically.
{% endhint %}

| Surface                                                      | Permission gating the surface           | Effect on the tag directory                                                              |
| ------------------------------------------------------------ | --------------------------------------- | ---------------------------------------------------------------------------------------- |
| `POST /api/tags`                                             | `TAG_CREATE`                            | The documented path.                                                                     |
| `PUT /api/dataentities/{id}/tags`                            | `DATA_ENTITY_TAGS_UPDATE`               | A novel tag name on an entity mints a new tag in the directory.                          |
| `PUT /api/terms/{id}/tags`                                   | `TERM_TAGS_UPDATE`                      | A novel tag name on a term mints a new tag in the directory.                             |
| `PUT /api/datasetfields/{id}/tags`                           | `DATASET_FIELD_TAGS_UPDATE`             | A novel tag name on a column mints a new tag in the directory.                           |
| Collector ingestion (`ExternalTagIngestionRequestProcessor`) | Collector token (no per-tag permission) | An ingested entity carrying tag names that do not yet exist mints them in the directory. |

{% hint style="info" %}
**Tag names are case-sensitive — `finance` and `Finance` are two separate tags.** The platform stores tag names verbatim. Two tags with names that differ only in capitalisation are distinct rows; entities tagged with one are not surfaced by a Tag-facet filter on the other. When seeding the catalog vocabulary on Management → Tags, settle a casing convention up front (uniform lowercase, Title-case, or all-uppercase) and audit `GET /api/tags` periodically for accidental near-duplicates — particularly after a collector ingestion run, which often emits framework-specific casing different from the operator-curated style.
{% endhint %}

{% hint style="warning" %}
**Tag names are stored verbatim — there is no server-side trim, length cap, or character-set restriction on any write path.** None of the tag write paths normalises the incoming name: the create form's OpenAPI schema (`TagFormData.name`) is a bare string with no `maxLength` or `pattern`, and the shared service helper writes the raw name straight to the directory row. Two consequences beyond the casing caveat above:

* **Leading / trailing whitespace mints a distinct row.** Because matching is exact-string, `' tag '` (with surrounding spaces) and `'tag'` are two separate tags — the same trap as `finance` vs `Finance`, but harder to spot.
* **The global tag directory is a pollution / DoS surface.** Arbitrarily long or arbitrary-character names are accepted, and an over-long name or a flood of near-identical whitespace variants lands in `GET /api/tags`, the Catalog **Top tags** strip, and the Search Tag-facet seed list — surfaces every user sees, with no cap to bound them.

**Mitigation today:** settle a naming + casing + no-surrounding-whitespace convention up front, and audit `GET /api/tags` periodically for whitespace / over-long near-duplicates (especially after a collector ingestion run). The upstream platform fix is a server-side trim + length cap + a database `CHECK` constraint; a separate, sibling input-validation gap on the dataset-statistics ingestion endpoint is tracked independently.
{% endhint %}

{% hint style="warning" %}
**The audit trail for tag changes is non-uniform across the three tag-assign endpoints.** A nominally-symmetric set of three tag-assign actions emits three different things to the [Activity Feed](/features/active-platform-features/activity-feed):

Entity and dataset-field tag changes are both fully audited — each event carries the before-and-after tag lists, under the two different event types above. The gap is the term path: term tag changes are not in the Activity Feed at all — they are observable only by polling the term's current tag list and diffing externally. Compliance / audit workflows depending on tag-change history must instrument the term path separately until the platform-side fix lands.
{% endhint %}

| Action                                                                    | Audit-feed event                                                                                      |
| ------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------- |
| Tagging a **data entity** (`PUT /api/dataentities/{id}/tags`)             | Emits a `TAG_ASSIGNMENT_UPDATED` event scoped to the entity, capturing the before-and-after tag list. |
| Tagging a **dataset field** / column (`PUT /api/datasetfields/{id}/tags`) | Emits a `DATASET_FIELD_TAGS_UPDATED` event capturing the before-and-after tag list.                   |
| Tagging a **term** (`PUT /api/terms/{id}/tags`)                           | Emits **no** activity event today.                                                                    |

## Where to next

* [Data entity detail page](/features/data-discovery/entity-detail-page) — the per-entity surface where the sidebar Tags panel lives and Important-flagged tags render visually distinct on entity rows.
* [Search and Filtering](/features/data-discovery/search) — where the Tag facet narrows the catalog.
* [Data Entity Groups & Domains](/features/data-discovery/groups-domains) — the heavier-weight grouping mechanism for related entities (datasets, transformers, quality tests).
* [Management](/features/management) — the operator-mutating side: tag vocabulary curation, Important flag, namespace scoping.
* [Activity Feed](/features/active-platform-features/activity-feed) — the audit trail for `TAG_ASSIGNMENT_UPDATED` + `DATASET_FIELD_TAGS_UPDATED` events (read the audit-asymmetry caveat above before relying on it).
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the platform-wide permission catalog, including the three `TAG_*` rows plus the four `*_TAGS_UPDATE` side-channel rows.


# Data Entity Groups & Domains

Data Entity Groups + the Domain framing — logical containers for related entities, how the Domain flag surfaces them on the Catalog Overview, and the relationship to ML experiments.

A **Data Entity Group (DEG)** is the platform's logical-grouping primitive — a catalog-level container that gathers related data entities (datasets, transformers, quality tests, consumers) under one umbrella with their own metadata, owners, tags, and terms. A **Domain** is a particular use of a DEG: a DEG flagged as a domain surfaces in the Catalog Overview home page's Domains section as a top-level discovery surface.

This page covers both framings — DEGs as the underlying primitive, and Domains as the operator-flag use of them.

## What a DEG is

Create groups to gather similar entities (datasets, transformers, quality tests, etc.). Each group can be enriched with specific metadata, owners, and [terms](/features/data-glossary/business-glossary).

**Example.** An organisation has ingested metadata related to its finances into the ODD Platform. All the entities are united into the Finance **Namespace** by default. To categorise entities, one creates Revenue and Payrolls DEGs.

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-0166dfde96939e547b8aadf5a155cee1c9a5b5f8%2Fgroups.gif?alt=media)

A DEG is itself a Data Entity (of type `DATA_ENTITY_GROUP`) — it has a detail page, an ODDRN, and participates in [lineage](/features/data-lineage/data-objects) (Group lineage returns the union of the group's children's lineage).

## The Domain framing

Flagging a DEG as a **domain** unlocks one extra surface: the Catalog Overview page renders a **Domains** section listing all domain-flagged DEGs as quick-jump tiles. This makes domain-flagged DEGs the platform's first-class discovery axis on the home page.

Operationally:

1. Create or open a DEG.
2. Use the DEG's edit surface to flag it as a domain.
3. The DEG now appears on the Catalog Overview's Domains section (which is conditional — the section appears only when at least one domain-flagged DEG exists).

The Domains section is also reachable through the [Search](/features/data-discovery/search) Groups facet, where domain DEGs participate alongside non-domain DEGs.

## DEG metadata

A DEG carries the same metadata model as any other Data Entity — owners, tags, terms, descriptions, statuses — at the group level. The convention is:

* **Owners** — set on the DEG to mark domain-stewardship at the group level instead of duplicating per-child.
* **Tags** — applied at the DEG level surface the group on Tag-faceted searches.
* **Terms** — link [glossary terms](/features/data-glossary/business-glossary) to the DEG to capture meaning.
* **Description** — narrative authoring describing what the group represents.

Children of the DEG keep their own metadata; the DEG-level metadata supplements it rather than replacing it.

## Relationship to ML Experiments

In ODD, an **ML experiment** is a Data Entity Group of class `ML_EXPERIMENT` that collects the entities produced by a training run — input datasets, feature tables, training jobs, model instances, and resulting model artifacts — into one logical container. Lineage, ownership, tags, and alerts follow through at the experiment level instead of being scattered across each child entity.

ML experiments are DEGs of a particular shape — the same primitive, used for a specific workflow.

{% hint style="info" %}
ML experiments in ODD are a **catalog view** over the assets that participated in the run. The platform does not track metrics, compare runs, or select a "best" model — it has no experiment-tracking UI or API of its own. For tracking, keep using MLflow, Weights & Biases, Comet, or your tool of choice, and push the resulting entities (datasets, models, runs) into ODD through a push adapter or the [ODD Specification](/introduction/main-concepts#odd-specification) so the experiment and its lineage are browsable alongside the rest of your data platform.
{% endhint %}

Each experiment's training-run inputs and outputs participate in the catalog-wide [lineage graph](/features/data-lineage/data-objects) — an operator opening an ML experiment's Lineage tab sees its dataset / model / run-level edges alongside the rest of the data platform.

## Managing DEG Membership

Membership of a manually-created DEG is mutated through two `Data Entity` controller endpoints; the surface is bound to the **child entity**, not the parent group.

| Method   | Path                                                              | Permission                      |
| -------- | ----------------------------------------------------------------- | ------------------------------- |
| `POST`   | `/api/dataentities/{data_entity_id}/data_entity_group`            | `DATA_ENTITY_ADD_TO_GROUP`      |
| `DELETE` | `/api/dataentities/{data_entity_id}/data_entity_group/{group_id}` | `DATA_ENTITY_DELETE_FROM_GROUP` |

Both permissions are scoped against the **child** `data_entity_id` in the URL — the platform's authorisation rules do **not** consult the parent DEG. A caller holding `DATA_ENTITY_ADD_TO_GROUP` against entity X can place X into any manually-created DEG in the catalog, regardless of who owns that DEG.

{% hint style="danger" %}
**DEG membership is write-collaborative — there is no per-DEG authorisation today.** The two permissions above are bound to the child entity in the URL; the parent group id is not consulted by the authorisation layer. In a multi-team deployment that uses DEGs (or the Domain flag) to model organisational boundaries (`Finance Domain`, `Marketing Domain`, `Engineering Reference`), any caller with `DATA_ENTITY_ADD_TO_GROUP` against an entity they own can place that entity into another team's DEG — including domain-flagged DEGs visible on the Catalog Overview home page. There is no DEG-side gate, no per-DEG owner check, no notification to the DEG's stewards.

**Operator mitigation today:** treat DEG membership as **collaborative by design** rather than as a private-namespace-style isolation. Use a naming convention (`finance-internal-…`) and operator policy (a wiki page, a team-charter section) rather than relying on the platform's RBAC to enforce DEG-membership ownership. The upstream platform fix tracks a per-DEG permission scope; until then, the platform's contract is "anyone with `DATA_ENTITY_ADD_TO_GROUP` on a child can place it into any DEG."
{% endhint %}

{% hint style="warning" %}
**DEG-membership changes emit no Activity Feed event today — auditors cannot trace "who added entity X to DEG Y."** Both `addDataEntityToDEG` and `deleteDataEntityFromDEG` are transactional but **not annotated with `@ActivityLog`**. The Activity Feed event type `DATA_ENTITY_RELATION_UPDATED` exists in the platform's enum but is not emitted by any code path today — it is a **dead value** that the wider event-type enumeration mentions but no event ever triggers (see [Activity Feed → Scope](/features/active-platform-features/activity-feed) for the structural framing). Per-entity Activity tabs and the global Activity page show no record of membership changes.

**Operator mitigation today:** if you need an audit trail of DEG membership, instrument it externally — PostgreSQL `pgaudit` on the membership tables (`group_entity_relations`-shaped writes), or an API-gateway log on the two endpoints above. The platform-side activity-event ship is on the roadmap but not yet shipped.
{% endhint %}

{% hint style="warning" %}
**Add and Delete are asymmetric on idempotence — reconciliation scripts must branch.** Calling `POST` on an entity already in the target DEG raises **HTTP 400** with the body `Data entity is already in this DEG`. Calling `DELETE` on an entity that is not in the target DEG silently returns **HTTP 204 No Content** — the no-op success path. A reconciliation script that idempotently asserts "entity X is in DEG Y" cannot use the `POST` endpoint blindly (it will see 400s on every re-run); the safe pattern is a `GET` preflight on the entity's current group membership followed by `POST` only when missing. The `DELETE` side is naturally idempotent and does not need the preflight.

Combined with the forensic silence above, the caller cannot tell from HTTP response or activity feed whether anything actually changed on a `DELETE` call — both the no-op and the genuine removal return the same `204`.
{% endhint %}

A few smaller behaviours worth knowing before scripting DEG membership:

* **The optional `data_entity_group_id` parameter is not validated.** Missing or malformed values produce the generic `id null` error message rather than a typed `BadRequest`. Direct API callers should defensively validate the parameter before submitting.
* **Empty DEGs persist after the last member is removed.** Deleting the only member of a DEG leaves an empty group entity in the catalog — there is no automatic cleanup. Operators retiring a DEG must explicitly delete it through the DEG's own entity-detail surface after emptying its membership.
* **Under `auth.type=DISABLED`, both endpoints are reachable anonymously.** The membership endpoints inherit the platform's DISABLED-mode no-auth posture (see [DISABLED authentication](/configuration-and-deployment/enable-security/authentication/disabled-authentication)). Don't run DISABLED in production if DEG membership matters for organisational boundaries.
* **The 400 response on `POST` conflates three failure modes.** "Entity already in DEG", "target is not a manually-created DEG", and "invalid request body shape" all produce the same generic 400 with the same human-readable message. Operators debugging a failing `POST` should check the entity's current membership first (most common cause), then the target's `type` (must be a manually-created DEG, not an ingested one), then the request body shape.

## Group lineage

The dedicated [Group lineage](/features/data-lineage/data-objects#group-lineage) endpoint returns the lineage graph for the DEG's *children*, not the DEG itself. This is what an operator usually wants when reasoning about a domain or pipeline group — *"what does the Finance domain depend on, and what depends on it?"* is a question about the union of the children's edges.

## Where to next

* [Data entity detail page](/features/data-discovery/entity-detail-page) — the per-entity surface where the sidebar Groups panel lives, plus the visible-window truncation caveat on Groups membership.
* [Search and Filtering → Groups facet](/features/data-discovery/search) — narrow the catalog to entities that are members of selected DEGs.
* [Data Lineage → Data Objects → Group lineage](/features/data-lineage/data-objects#group-lineage) — the dedicated endpoint that returns DEG-children lineage.
* [Manual Object Tagging](/features/data-discovery/tagging) — the lighter-weight labelling counterpart for cross-cutting groupings that do not justify a DEG.
* [Main Concepts → Terms & Aliases — Data Entity Group](/introduction/main-concepts#terms-aliases) — the canonical-term reference.


# Business names

Business names for data entities and dataset fields — operator-assigned alternative names that surface alongside the original technical names everywhere the entity is rendered.

Datasets and dataset fields ingested from a source system carry their **technical names** (`fct_orders_v2`, `cust_id_pk`, `txn_dt`) — names chosen by whoever built the source schema, often unfit for the cross-team operator and analyst audience that consumes the catalog. ODD lets operators assign **business names** alongside the technical name: an alternative human-readable label that surfaces everywhere the entity is shown, while the original technical name persists below as a reference wherever the entity carries one.

The technical name stays as-is in lineage edges, ODDRNs, and the underlying source — the business name is purely a presentation-layer alias on the catalog surface.

## Setting a business name on a data entity

**Step 1.** On any data entity's detail page, click the **Add Business Name** button.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-2ad43b42d977bc0fb7d1ca4c7b0cfa9559953592%2Fmedium-0-E2MncXGF9RfmaVRa.png?alt=media" alt="" height="357" width="700"><figcaption></figcaption></figure>

**Step 2.** Enter the preferred name in the **Business Name** field and confirm.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-069e9f77779034cf855da7040a1b0b91b073e059%2Fmedium-0-Wtz-vOWK1oq2c4HZ.png?alt=media" alt="" height="425" width="700"><figcaption></figcaption></figure>

**Step 3.** The newly-assigned business name renders prominently as the entity's display name. When the entity also carries a source-ingested technical name, that original name persists below the new name as an inline reference, so anyone looking at the entity can see both. A manually-created entity has no separate technical name, so it shows only the business name with no `Original` line beneath it.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-980d603558c64fd0b0adaf3809e265a3f31b3cc6%2Fmedium-0-3VZ_ANHKomQdyVDb.png?alt=media" alt="" height="421" width="700"><figcaption></figcaption></figure>

{% hint style="info" %}
**The Add / Edit business-name button is hidden on entities whose status is `DELETED`.** When an entity is in the `DELETED` status the entity-level business-name affordance disappears entirely — there is no disabled-button state and no banner explaining why it is gone. An operator who expects to rename a deleted entity simply sees no button. Restore the entity to a non-deleted status to regain the affordance.
{% endhint %}

## Setting a business name on a dataset field (column)

The same workflow applies at the column level. Open the dataset's **Structure** tab, find the column to rename, and follow the same Add Business Name flow:

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-be88b90c95ba888e44949c4cb9d3741aa6f74deb%2Fmedium-0-P5L1yCszYXX_uMfG.png?alt=media" alt="" height="420" width="700"><figcaption></figcaption></figure>

The dataset's Structure tab renders the business name as the primary column label and the technical name as a secondary line — same pattern as the entity-level rename.

## Where business names appear

Once set, the business name is the primary display label everywhere the entity (or the field) is rendered:

* On the entity's own detail page (Overview, Structure, Lineage, Test reports, Alerts, Query Examples, Activity, Discussions tabs).
* In [Search](/features/data-discovery/search) result rows and the per-entity tile on the [Catalog Overview](/features/data-discovery/catalog-overview).
* In the [Directory](/features/data-discovery/directory) drill-down (level-4 entity list).
* In lineage graphs (per-node label).
* In any catalog surface that renders the entity name.

The technical name is preserved underneath for any entity that carries one (a manually-created entity has no separate technical name to show) — operators looking for an entity by either name can find it; analysts reading the catalog see the friendlier label.

## RBAC

Setting a business name on a data entity is gated by `DATA_ENTITY_INTERNAL_NAME_UPDATE` and records a `BUSINESS_NAME_UPDATED` event on the [Activity Feed](/features/active-platform-features/activity-feed). Setting a business name on a dataset field (a column) is gated by `DATASET_FIELD_INTERNAL_NAME_UPDATE` and records a **`DATASET_FIELD_INTERNAL_NAME_UPDATED`** event — a different event type. An operator filtering the Activity Feed by `BUSINESS_NAME_UPDATED` alone sees entity renames but silently misses every column rename; filter on both event types to audit all business-name changes.

For the full permission list, see [Permissions](/configuration-and-deployment/enable-security/authorization/permissions).

## Where to next

* [Data entity detail page](/features/data-discovery/entity-detail-page) — the per-entity surface where the business-name affordance lives in the detail-page header.
* [Activity Feed](/features/active-platform-features/activity-feed) — the audit trail of business-name changes: `BUSINESS_NAME_UPDATED` (entity) and `DATASET_FIELD_INTERNAL_NAME_UPDATED` (column).
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — `DATA_ENTITY_INTERNAL_NAME_UPDATE` + `DATASET_FIELD_INTERNAL_NAME_UPDATE`.
* [Search and Filtering](/features/data-discovery/search) — where renamed entities surface (search matches against both the technical name and the business name).
* [Data Discovery overview](/features/data-discovery) — the bucket landing this page sits under.


# Data Entity Statuses

Data Entity Statuses — UNASSIGNED / DRAFT / STABLE / DEPRECATED / DELETED lifecycle on every catalogued entity, plus the soft-delete TTL configured by the platform's housekeeping job.

Every catalogued entity carries a **status** that signals where it is in its lifecycle — newly ingested, in active use, deprecated for a planned removal, or soft-deleted pending permanent purge. The status is operator-set, surfaces on the Catalog page as a [Search facet](/features/data-discovery/search), and drives the [Activity Feed](/features/active-platform-features/activity-feed)'s `DATA_ENTITY_STATUS_UPDATED` event.

## The five statuses

| Status           | Meaning                                                                                                                                                                                               | Set by                                                                                         |
| ---------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------- |
| **`UNASSIGNED`** | The default. When metadata collectors ingest data entities into the platform's database, every new entity lands as `UNASSIGNED` until an operator changes it.                                         | Platform default; can be operator-overridden via the entity detail page.                       |
| **`DRAFT`**      | The data entity is a draft / test entity in the data source — not yet ready for downstream consumption. The UI lets operators set a time period after which the status auto-transitions to `DELETED`. | Operator.                                                                                      |
| **`STABLE`**     | The data entity is stable and fully operational — safe for downstream pipelines and BI reports.                                                                                                       | Operator.                                                                                      |
| **`DEPRECATED`** | A warning marker — the entity is deprecated for planned removal. The UI lets operators set a time period after which the status auto-transitions to `DELETED`.                                        | Operator.                                                                                      |
| **`DELETED`**    | Soft-deleted. The entity is hidden from the [Management → Datasources](/features/management) view by default and only reachable through filter-with-deleted-items.                                    | Operator (manual) or auto-transition from `DRAFT` / `DEPRECATED` after the TTL window expires. |

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-6c1fa7206c02e550ea28ad3acecef391766c77fb%2Fmedium-0-IbK2C-ipZVHhOpRy.png?alt=media" alt=""><figcaption><p>Default status on newly-ingested entities</p></figcaption></figure>

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-02881207cdad75e37c41e8b601769ecb67cb7a41%2Fmedium-0-_n5FgaUlriOPKtS4.png?alt=media" alt=""><figcaption><p>Operator changes the status from the entity detail page</p></figcaption></figure>

## The soft-delete TTL

`DELETED` is **soft delete**. The platform's housekeeping job permanently deletes a `DELETED` entity (and every cascading row attached to it — metadata values, ownerships, lineage, tags, terms, alerts, messages, metrics, **attachment files including objects in S3 / MinIO storage**, task runs, group relations, and dataset structure / enum values for datasets) only after the entity's status-update timestamp is older than `housekeeping.ttl.data_entity_delete_days`. The default window is **30 days**.

During the soft-delete window the operator can flip the status back (`DELETED` → `STABLE` or any non-deleted status) and the entity reappears in the catalog with its history intact. After the TTL expires the next housekeeping run hard-deletes the row; once that happens, recovery requires re-ingest from the source.

To change the retention window, see [Housekeeping Settings Configuration → `housekeeping.ttl.data_entity_delete_days`](/configuration-and-deployment/odd-platform#housekeeping-settings-configuration). Raise the value before any planned bulk deprecation if the audit trail matters for compliance.

{% hint style="danger" %}
**The 30-day purge is permanent and cascades to object storage — `DELETED` is not long-term parking.** On a default install (`housekeeping.enabled: true`, `housekeeping.ttl.data_entity_delete_days: 30`), once a `DELETED` entity's status-update timestamp is older than the configured window, the next housekeeping run **hard-deletes** it: the `data_entity` row, its cascading rows across the child tables (lineage, metadata, ownerships, tags, terms, alerts, messages, metrics, task runs, group relations, and dataset structure / enum values), **and its attachment files in object storage — including objects in S3 / MinIO**. There is **no restore path** once this runs; recovering the entity means re-ingesting it from its source.

Do **not** treat `DELETED` as an archive or a recycle bin. The restore-by-flipping-status escape hatch works **only within** the retention window — after the window elapses the entity and its attachments are gone. To retire entities but keep them recoverable for longer, raise `housekeeping.ttl.data_entity_delete_days` (or disable the housekeeping job) **before** parking anything in `DELETED`. See [Housekeeping Settings Configuration](/configuration-and-deployment/odd-platform#housekeeping-settings-configuration) for the key and the partial-override risk that can shrink the window to zero.
{% endhint %}

{% hint style="info" %}
**Known defect — the `status_updated_at` timestamp is not refreshed on non-`DELETED` status transitions.** A guard in the platform's status mapper (`DataEntityMapperImpl.applyStatus`) tests the new status id against a value it has just overwritten with that same id, so the branch that re-stamps `status_updated_at` never runs. The timestamp is therefore left unchanged when an entity moves between `DRAFT` / `STABLE` / `DEPRECATED` or is restored from `DELETED`. This is cosmetic and does **not** affect the soft-delete retention clock above: the transition **to** `DELETED` runs through a separate soft-delete code path that stamps `status_updated_at` correctly, so the 30-day purge always measures retention from the actual deletion time.
{% endhint %}

{% hint style="warning" %}
**Known limitation — the scheduled DRAFT / DEPRECATED → DELETED auto-flip has no per-tick batch cap.** When an operator schedules a future status switch (the `auto-transition to DELETED after N days` affordance on `DRAFT` and `DEPRECATED`), the platform records `status_switch_time` on the entity and a background job picks up every entity whose `status_switch_time` is in the past and flips it. The job fires every **10 minutes** under a **9-minute distributed lock** (ShedLock), and the underlying query selecting candidate entities has **no `LIMIT`** — every overdue entity is processed in a single transaction.

A bulk operation that schedules (say) 5,000 entities for a near-future flip triggers one transaction processing all 5,000 pojos plus their cascade fan-out. If the transaction runs longer than the 9-minute lock window, the lock releases mid-flight, the next tick acquires its own lock, and the effective cadence drifts from "every 10 minutes" to "as fast as one large transaction can finish." There is no per-batch metric or operator-side dial to throttle it.

When scripting bulk `DRAFT` / `DEPRECATED` assignments with auto-transition, stagger `status_switch_time` values across multiple windows (e.g. spread 5,000 entities across 50 ten-minute windows of 100 each) to avoid the burst. A platform-side per-tick `LIMIT` is on the roadmap.
{% endhint %}

## Status changes propagate to data sources

If the status of a data entity **and its parent data source** are both set to `DELETED` and an operator then flips the entity status back to a visible state, the data source itself reverts to its original (non-deleted) condition. The platform mirrors entity-level status changes back up the data-source row when the two are in lockstep.

## DELETED-state read-only surface

When an entity's status flips to `DELETED`, the platform makes it intentionally read-only in the UI. Several edit affordances disappear from the detail page in the same render — silently, without an info banner — until the status is flipped back to a non-deleted state.

The affordances hidden in `DELETED` state:

| Affordance                                                | Location                                     |
| --------------------------------------------------------- | -------------------------------------------- |
| **Add / Edit business name**                              | Detail-page header, next to the entity name. |
| **Edit group** (manually-created Data Entity Groups only) | Detail-page header, right-hand action strip. |
| **Edit tags**                                             | Overview tab → Tags sidebar panel.           |
| **Add to group**                                          | Overview tab → Groups sidebar panel.         |

The entity name, the class / type badges, the [status](/features/data-discovery/statuses) badge, the [Share to Slack](/features/active-platform-features/data-collaboration) button (when [Data Collaboration](/features/active-platform-features/data-collaboration) is enabled), the read-only data on every panel, and every tab below the header all continue to render normally.

{% hint style="info" %}
**To edit a `DELETED` entity, restore it first.** Soft-deleted entities are intentionally read-only — the platform hides the edit affordances rather than letting an operator modify a record that is queued for permanent deletion. Flip the status back to `STABLE`, `DRAFT`, or `DEPRECATED` from the status badge (the badge itself is always interactive for users with the `DATA_ENTITY_STATUS_UPDATE` permission, even in `DELETED` state); the hidden affordances reappear in the next render.
{% endhint %}

The same read-only treatment applies when the soft-delete TTL has not yet expired — see [The soft-delete TTL](#the-soft-delete-ttl) above. Once the TTL elapses and the housekeeping job hard-deletes the row, the detail page itself returns a 404; restoring is only possible during the soft-delete window.

## Detail-header authoring caveats

A few smaller behaviours on the detail-page header that are non-obvious on first encounter:

* **The business-name button toggles its label between "Add business name" and "Edit".** Both labels open the same dialog. If the entity has no `internalName` set, the button reads `Add business name`; once one is set, it reads `Edit`. Train teammates to look for either label rather than only `Add business name`. The Overview tab's Tags row follows the same pattern (`Add tags` vs `Edit tags`).
* **The status badge renders identically for users without `DATA_ENTITY_STATUS_UPDATE` — but clicking it does nothing.** The badge has no lock icon, no `cursor: not-allowed`, and no "you can't change this" tooltip; non-permission holders see the same chip everyone else does and discover they can't interact with it by clicking. If your deployment uses strict RBAC, grant `DATA_ENTITY_STATUS_UPDATE` explicitly to the roles that should change status — see [Permissions](/configuration-and-deployment/enable-security/authorization/permissions).
* **The "Share" button is silently absent unless Data Collaboration is enabled.** The Slack share affordance is gated by the `DATA_COLLABORATION` feature toggle (default off). When the toggle is off the button is unmounted entirely — no "feature disabled" placeholder, no install hint. After enabling [Data Collaboration](/features/active-platform-features/data-collaboration), the button appears on every entity detail page in the next page load.

## Group statuses

Status assignments apply to entity **groups** as well as individual entities. When an operator changes a status on a [Data Entity Group](/features/data-discovery/groups-domains), the UI offers the option to apply the change to the group as a whole or to cascade it to every member entity. Use the group-level status when you want to deprecate or retire an entire pipeline; use member-level when only specific members are affected.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-be088afe5c7bd425cef7ed5939303ee1e35b5fd4%2Fmedium-0-YFTgiPz-tFfMASV3.png?alt=media" alt=""><figcaption><p>Group-level status assignment</p></figcaption></figure>

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-3890676f4b4507608b5a59a41c3d36f1c5c93dbf%2Fmedium-0-MtofADdnN-bWPrPt.png?alt=media" alt=""><figcaption><p>Apply-to-group vs apply-to-members confirmation</p></figcaption></figure>

## Where the status surfaces

* **Catalog page filter** — Statuses is one of the seven [Search facets](/features/data-discovery/search). Selecting one or more statuses narrows the result set to entities matching any of them.

  <figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-703c510be30507d2658168aa49dfcd622898fa28%2Fmedium-0-nwXHceHpvaJdOQhU.png?alt=media" alt=""><figcaption><p>Statuses facet on the Catalog page</p></figcaption></figure>
* [**Activity Feed**](/features/active-platform-features/activity-feed) — every status change emits a `DATA_ENTITY_STATUS_UPDATED` event. The feed is the audit trail for who set what status and when.

  <figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-f38494892f925734174cb3f0ac835fa14fff1e5b%2Fmedium-0-PayxOrpY7AfMGLBj.png?alt=media" alt=""><figcaption><p>Status-update event on the Activity feed</p></figcaption></figure>
* **Entity detail page** — the current status is shown next to the entity name, with edit affordance gated by the `DATA_ENTITY_STATUS_UPDATE` permission (see [Permissions](/configuration-and-deployment/enable-security/authorization/permissions)).

## RBAC

Operators need the `DATA_ENTITY_STATUS_UPDATE` permission to change a data entity's status. The permission is part of the Data entity permissions group; see [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) for the full list and how to compose roles around it.

## Where to next

* [Search and Filtering](/features/data-discovery/search) — the Statuses facet that surfaces these on the Catalog page.
* [Activity Feed](/features/active-platform-features/activity-feed) — the audit trail of every status change (`DATA_ENTITY_STATUS_UPDATED`).
* [Data Entity Groups & Domains](/features/data-discovery/groups-domains) — the group-vs-member status apply-to choice.
* [Data entity detail page](/features/data-discovery/entity-detail-page) — the composition of the detail page that hosts every header affordance documented above.
* [Housekeeping Settings Configuration](/configuration-and-deployment/odd-platform#housekeeping-settings-configuration) — the soft-delete TTL operator-side reference.
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the `DATA_ENTITY_STATUS_UPDATE` permission.
* [Data Discovery overview](/features/data-discovery) — the bucket landing this page sits under.


# Data Entity Attachments

Files (images, PDFs, CSVs, TXT) and remote-URL links attached to data entities for additional context. Storage backend is operator-configurable; the LOCAL default is ephemeral.

Operators and users can attach **files and links** to any data entity to carry additional context — runbook PDFs, sample CSVs, dashboard screenshots, links to internal wikis, ticketing references. Attachments live alongside the entity's metadata and persist across re-ingests, behaving similarly to attachments on a Jira ticket.

{% hint style="danger" %}
**The default `LOCAL` storage mode is ephemeral.** Files are written to a local container path that is wiped on any container or pod restart — routine deployment, node drain, crash, Kubernetes eviction. Use `REMOTE` (S3 / MinIO) storage for any deployment where users will actually upload attachments. See the [Attachment Storage Configuration](/configuration-and-deployment/odd-platform#attachment-storage-configuration) operator reference for the storage caveats and the `us-east-1` constraint on AWS S3.

**In-flight chunk staging is always node-local — even under REMOTE persistence.** The 3-step chunked-upload protocol (initiate → upload-part(s) → complete) writes every part to `/tmp/odd/chunks/{upload_id}` on the platform API container. The path is hard-coded and ignores the `attachment.storage` setting; only at COMPLETE time does the REMOTE path stream the assembled file to S3. An operator running REMOTE persistence on a Kubernetes deployment with `spec.volumes` excluding `/tmp`, or any container restart between initiate and complete, loses all in-flight upload state — partial chunks become orphan files that the housekeeping job does not clean. Multi-hour large-file uploads (the chunked protocol's intended use case) can lose partial state on container churn even when persistent storage is otherwise configured.

**Mitigation today.** For deployments expecting multi-hour large-file uploads, mount a persistent volume at `/tmp/odd/chunks` on the platform API container so chunked uploads survive routine container churn. For deployments that tolerate upload-restart on container restart, no action is required — but operators should know the failure mode so they can recognise "lost partial upload" as a deployment-state symptom rather than an attachment-subsystem bug.
{% endhint %}

{% hint style="danger" %}
**Attachment mutation endpoints discard the URL's data-entity id after the auth gate — operators with `DATA_ENTITY_ATTACHMENT_MANAGE` on entity A can mutate any other entity's attachments by file id.** The URL pattern is `/api/dataentities/{data_entity_id}/attachments/files/{file_id}`. The platform's authorization layer evaluates the gate against `data_entity_id` (entity A — granted), but the controller method operates only on `file_id`. A user with `DATA_ENTITY_ATTACHMENT_MANAGE` on entity A constructs a `PUT` against `/api/dataentities/{A_id}/attachments/files/{B_file_id}` — the auth gate passes and the mutation acts on entity B's file. The READ endpoints have no `SecurityRule` entry at all, so any authenticated user lists any data entity's attachments by id today. Combined, **per-entity ownership boundaries are silently bypassed for attachments in multi-tenant deployments**.

**Mitigation today.** Treat attachment authorization as a network-perimeter concern in multi-tenant deployments — apply a reverse-proxy filter that asserts the URL's `data_entity_id` matches the file's owning entity before forwarding the request to the platform. The upstream platform-side fix is a one-commit guard at the controller layer (assert `file.dataEntityId == pathDataEntityId` before mutating); the doc-side caveat persists until that lands.
{% endhint %}

## Attaching a file

**Step 1.** Open the **Overview tab** of any data entity and click the **Add attachment** icon:

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-17d08bf97babfa28ff03f40558c1ddf885099d98%2Fmedium-0-YuyFT-yZ-2k97Rdn.png?alt=media" alt="" height="508" width="700"><figcaption></figcaption></figure>

**Step 2.** Drag-and-drop the file into the attachment window, or browse to select:

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-976108c302deb09d8d8c0072bfdb3a39cc83c24f%2Fmedium-0-9s8OsALVV4jxuLvU.png?alt=media" alt="" height="524" width="700"><figcaption></figcaption></figure>

There is no restriction on file type — images, CSVs, PDFs, TXT files, and any other format are accepted. The single restriction is **file size**, which is capped at `attachment.max-file-size` megabytes (default `20`). Files larger than the cap are rejected by the upload API.

If the file exceeds the size cap or the operator prefers to reference an external location, attach a **link** instead (next section).

## Attaching a link

**Step 3.** To attach a link to a remotely-stored file or other web resource, insert an `http`/`https` URL and provide a customised display name. As of 0.28.0 a link attachment must use the `http` or `https` scheme — other schemes (`mailto:`, `ftp:`, `data:`, …) are rejected. Multiple links can be added in one go via the **+ Add link** icon:

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-10ca6ffeef64550777a48b4a8dc86fd8bf9eb5f0%2Fmedium-0--mBtQVX0bGGJzRNV.png?alt=media" alt="" height="517" width="700"><figcaption></figcaption></figure>

Once saved, the file and the link both appear on the entity's Attachments list:

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-7a4ec03c75dcdf70d1912dc3fefd78333e618f9c%2Fmedium-0-67mYc30rYm9jYWRQ.png?alt=media" alt="" height="464" width="700"><figcaption></figcaption></figure>

A single data entity can carry **multiple files and multiple links** — the platform does not cap the count.

## Editing and deleting attachments

Editing and deleting attachments — files and links alike — is performed by clicking the per-attachment icons next to each row:

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-2a41996abe811b8cd60581473a539f970e691bb2%2Fmedium-0-uJVx9_ko7-tQcLgL.png?alt=media" alt="" height="183" width="700"><figcaption></figcaption></figure>

## Storage backend (operator-configurable)

The platform supports two storage backends for the file (not the link) attachments:

* **`LOCAL`** *(default)* — files written to a local filesystem path inside the platform container. Suitable only for single-host evaluations and local development; **ephemeral on container restart**.
* **`REMOTE`** — S3-compatible object storage (AWS S3, MinIO, etc.). Required for production deployments. Configured via `attachment.storage`, `attachment.remote.url`, `attachment.remote.access-key`, `attachment.remote.secret-key`, `attachment.remote.bucket`.

The full operator-side reference (every key, the `us-east-1` AWS S3 constraint, the in-memory-buffer ceiling on `spring.codec.max-in-memory-size`) lives at [Configure ODD Platform → Attachment Storage Configuration](/configuration-and-deployment/odd-platform#attachment-storage-configuration). The hint at the top of this page is the operator-relevant summary; the configuration reference is authoritative.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-2a7d03b8207eaf2da80b825207a889cd93dbed02%2Fmedium-0-NBJwpG1FNNNn-w_h.png?alt=media" alt="" height="247" width="700"><figcaption></figcaption></figure>

## RBAC

Adding, deleting, and managing attachments on a data entity is gated by the `DATA_ENTITY_ATTACHMENT_MANAGE` permission. See [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) for the full list and how to compose roles around it.

## Where to next

* [Data entity detail page](/features/data-discovery/entity-detail-page) — the per-entity surface where the Attachments panel lives on the Overview tab.
* [Configure ODD Platform → Attachment Storage Configuration](/configuration-and-deployment/odd-platform#attachment-storage-configuration) — the operator reference for the storage backend, including the LOCAL-is-ephemeral warning and the REMOTE caveats.
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the `DATA_ENTITY_ATTACHMENT_MANAGE` permission and other data-entity permissions.
* [Data Discovery overview](/features/data-discovery) — the bucket landing this page sits under.


# Vector Store metadata

Vector Store cataloguing — datasets containing vector-typed columns recognised as a first-class dataset type, with per-column metadata reflecting the vector data type.

ODD recognises **vector-typed datasets** as a first-class entity in the catalog — a dedicated dataset type plus a dedicated column data type — so vector tables (Postgres `pgvector`, dedicated vector databases) sit alongside relational tables in search, lineage, and ownership without bespoke handling.

The platform ships two complementary additions for vector data:

## Dataset type — `Vector Store`

The platform exposes a dedicated dataset type literal — `Vector Store` — that an adapter can emit when the source is a vector-oriented store. Vector Stores show up on Catalog search facets, the [Directory](/features/data-discovery/directory), and entity lists, carrying a **`Vector store` type label** and a dedicated value on the **Type** filter facet.

A Vector Store does **not** carry a distinct entity badge. The coloured class badge on a catalog row is keyed by the entity *class*, and `Vector Store` is a *type* within the `Dataset` class — so it shows the same `Dataset` badge as a relational table. The way to tell a Vector Store apart is the type label on the entity and the **Type** facet on [Search](/features/data-discovery/search), not the badge colour or icon.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-f5d9dfbc1f52fe0d249a5fc2e232ef758a20b653%2Fmedium-0-T1-NDc4pI0YsKpit.png?alt=media" alt=""><figcaption><p>A Vector Store recognised in the ODD catalog</p></figcaption></figure>

The classification is a strong signal for operators: a Vector Store row in the catalog is the same primitive as a relational dataset (it has fields, owners, tags, lineage edges) but the workload it serves is different (similarity search, retrieval-augmented generation, embeddings storage), and surfacing the type makes it explicit.

## Column data type — `Vector`

Each column on a dataset carries a data type. The platform's data-type taxonomy includes `Vector` as a recognised primitive — adapters that ingest a column declared as a vector type (e.g., `pgvector`'s `vector(N)` column type) emit it as `Vector` rather than as a generic Array or Unknown type. The Structure tab renders `Vector` columns explicitly, and downstream surfaces (lineage, schema diff, search filtering by data type) recognise them.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-25bd8dbf986d62faab03f6fab3abedd09e2e9af6%2Fmedium-0-MrWlPWPRG6kN0oWI.png?alt=media" alt=""><figcaption><p>A Vector-typed column on a dataset's Structure tab</p></figcaption></figure>

## Specification source

Both additions — the `Vector Store` dataset type and the `Vector` column data type — are defined in the [opendatadiscovery-specification](https://github.com/opendatadiscovery/opendatadiscovery-specification/blob/main/specification/entities.yaml) repo's `entities.yaml`. Adapters speak the specification and emit either type when applicable; the platform ingests whatever the adapter declares.

## Adapter coverage

The first adapter to surface vector cataloguing was the **PostgreSQL adapter** in [`odd-collector`](/integrations/integrations/odd-collector). When the adapter encounters a PostgreSQL table containing at least one column with a `vector` data type (`pgvector` extension), it classifies the table as `Vector Store` during ingestion.

Other adapters that ingest vector-storing systems can emit the same dataset type by following the specification. Coverage grows as more adapters add vector recognition; consult per-adapter pages under [Integrations](/integrations/integrations) for the latest matrix.

## Where to next

* [Search and Filtering](/features/data-discovery/search) — Vector Stores surface on the Type facet (multi-select on the entity-class tab strip).
* [Data Objects Lineage](/features/data-lineage/data-objects) — Vector Stores participate in lineage like any other dataset class.
* [`odd-collector`](/integrations/integrations/odd-collector) — the canonical pull collector with the PostgreSQL `pgvector` recognition built in.
* [opendatadiscovery-specification](https://github.com/opendatadiscovery/opendatadiscovery-specification/blob/main/specification/entities.yaml) — the specification source for the `Vector Store` dataset type and the `Vector` column data type.
* [Data Discovery overview](/features/data-discovery) — the bucket landing this page sits under.


# Dataset schema diff

Dataset schema diff — visual side-by-side comparison of dataset schema revisions, with per-revision history and automatic alert raising for backwards-incompatible schema changes.

When metadata is re-ingested for a dataset, the platform compares the new revision to the previous one and surfaces every change — added columns, removed columns, renamed columns, type changes — on the dataset's **Structure** page. Operators get a visual diff for every revision, and the platform raises a [Backwards-incompatible schema change](/features/active-platform-features/alerting#backwards-incompatible-schema-change-what-triggers-it) alert whenever a removal or type change breaks downstream consumers.

This page covers the user-facing diff surface. The underlying alert mechanism — what triggers it, how it lifecycles, the per-entity halt configuration — lives on the [Alerting](/features/active-platform-features/alerting) page.

## Where to find it

Open any dataset (`Table`, `File`, `View`, `Vector Store`, ...) and navigate to the **Structure** tab on the entity's detail page.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-4b86e2f4271e554632eba2f9d1fc00497a221548%2Fmedium-1-I8vubQXKh8oJYEsugbvxLQ.png?alt=media" alt=""><figcaption><p>Dataset structure in the ODD UI</p></figcaption></figure>

The Structure tab carries:

* **Fields** — every column the dataset exposes.
* **Data types** per field.
* **Statistics** per field (when ingested by an adapter that emits them — see [Test Results Import](/features/data-quality/test-results-import) for the per-adapter coverage).

## Revision history

Every re-ingest of a dataset that **changes the structure** creates a new **revision**. Adding a column, deleting a column, renaming a column, or changing a column's data type all bump the revision counter. Same-structure re-ingests do not create a new revision (the platform compares structure by `(field_oddrn, type)` to decide).

The revision history is browsable per dataset: pick any two revisions to see exactly what changed between them.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-fa34a270232d63beb7af051c4b739ad838f5b810%2Fmedium-0-2ErN3MW8ItLpPVsJ.png?alt=media" alt=""><figcaption><p>Dataset revisions in the ODD UI</p></figcaption></figure>

Two illustrative diffs the platform surfaces:

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-a5e483b2bbfda470ff59d69e4931ce2cc1d35a5b%2Fmedium-0-BuZNkYkLCVTsBDkR.png?alt=media" alt=""><figcaption><p>Column was added</p></figcaption></figure>

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-6dc682368524985b88339289097416ae413de5c0%2Fmedium-0-OdFT_yoJ9I5vgV5p.png?alt=media" alt=""><figcaption><p>Column was removed</p></figcaption></figure>

The diff also captures **data-type changes** and **column renames** (both are detected as a type change or an ODDRN change between revisions, respectively).

## Backwards-incompatible alerts

When the comparison surfaces a **removal** of a previously-present column, or a **type change** on an existing column, the platform additionally raises a [Backwards-incompatible schema change](/features/active-platform-features/alerting#backwards-incompatible-schema-change-what-triggers-it) alert against the dataset. The alert lands on the entity's Alerts tab and the platform-wide [Alerts](/features/active-platform-features/alerting) section, and is **not** auto-resolved — an operator must work it by hand.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-ca717aedd08d89ecd5796cb831c74ce385e2c301%2Fmedium-0-AfQmbv7MMBtWVceX.png?alt=media" alt=""><figcaption><p>Schema-change alerts in the ODD UI</p></figcaption></figure>

This separation is intentional:

* **The diff** is a discovery surface — every operator looking at the dataset sees what changed across revisions.
* **The alert** is the action surface — the platform proactively flags the case where the change breaks a downstream consumer.

For the full alert rule (what counts as backwards-incompatible per entity class — Datasets, Transformers, Consumers — and the first-ingest-no-alert exception), see [Alerting → Backwards-incompatible schema change](/features/active-platform-features/alerting#backwards-incompatible-schema-change-what-triggers-it).

## Known limitations and operator caveats

The dataset-version read and diff endpoints behind this page carry a few behaviours that are non-obvious from the UI alone. Each item below states what an operator might assume, what the platform actually does, and what to do today.

{% hint style="danger" %}
**Dataset-version reads (including the diff endpoint) are not scoped to their dataset — any authenticated caller who can guess a `version_id` reads any dataset's schema.** The `GET /api/datasets/{data_entity_id}/structure/{version_id}` endpoint, the diff endpoint at `/api/datasets/{data_entity_id}/structure/diff`, and the "latest version" read all consume the path component `{data_entity_id}` in the controller signature, but the underlying repository query filters **only** on `dataset_version.id` — no `data_entity_id` predicate is added. Calling `GET /api/datasets/9999/structure/{any-real-version-id}` returns the schema that owns that `version_id`, regardless of which dataset id you put in the path.

The UI surface amplifies the leak. The catalog's compare viewer (`/dataentities/{id}/structure/compare?firstVersionId=…&secondVersionId=…`) reads the two `version_id`s straight from the URL query string and passes them into the diff fetch **without** checking they belong to the dataset whose detail page is open. A pasted URL whose `version_id`s come from a different dataset returns 200 with a structurally-valid but semantically-nonsense diff; the compare panel renders it the same as a legitimate diff.

**Operator-visible consequences.**

* In a multi-tenant deployment, any authenticated user enumerating `version_id` integers reads every dataset's full schema — column names, types, descriptions, tags, terms, attached lookup tables, enum values — independent of dataset-level RBAC.
* Under `auth.type=DISABLED`, the same reads are reachable anonymously.
* The compare viewer is a *trusted* audit surface — operators use it to reason about "what changed between V1 and V2." A forged URL (shared in chat, in a bookmark, in another document) can display a deliberately misleading diff that looks identical to a real one. There is no "this isn't your dataset" warning.

**Mitigations until the platform-side fix lands.** Treat any view of the structure / diff page as catalog-read-collaborative — every authenticated user can effectively read every dataset's structure, regardless of dataset RBAC. If your deployment requires per-dataset isolation, enforce it at the network perimeter (reverse-proxy rules on the `/api/datasets/*/structure*` paths) rather than relying on platform RBAC. The upstream fix tightens the repository predicate to also filter on `data_entity_id`, adds a typed `NotFoundException` when the version-id does not belong to the dataset, and adds a client-side check in the compare viewer.
{% endhint %}

{% hint style="warning" %}
**The diff endpoint returns 500 for missing-version-id and 400 for identical-version-id — operators cannot distinguish "wrong input" from "platform broken."** When one or both version-ids in `GET /api/datasets/{id}/structure/diff?first_version_id=A&second_version_id=B` do not exist (typo, deleted version, cross-dataset id), the service raises a bare `RuntimeException("Query returned %s rows for diff request")` that the controller-advice maps to **HTTP 500**. When the two version-ids are identical, the service raises a typed `BadUserRequestException` that maps to **HTTP 400**. The compare-viewer UI catches both into the same generic error page; the operator sees the same "something went wrong" regardless of whether they mistyped a version-id or whether the platform is actually broken.

This breaks the common debugging path: an SRE seeing a 500 on the diff endpoint starts looking at platform health (logs, JVM heap, database) when the actual cause was a wrong `version_id` in the URL. The upstream fix replaces the bare `RuntimeException` with a typed `NotFoundException` so the controller-advice maps "missing version-id" to HTTP 404; once that ships, the compare UI can differentiate 4xx (user input) from 5xx (platform error) and present a meaningful message.

Until the fix lands, treat any 500 from the structure / diff endpoints as **probably a wrong version-id** before treating it as a platform incident — verify both ids exist on the dataset (the revision history dropdown on the Structure tab is authoritative) before opening a ticket.
{% endhint %}

{% hint style="info" %}
**"Latest version" means the highest `version` integer, not the most recently created.** `GET /api/datasets/{id}/structure` (no `version_id`) returns the structure of the dataset version with the highest `version` column value — computed by the repository as `max(DATASET_VERSION.VERSION)`. The `CREATED_AT` timestamp is **not** considered. Under normal ingestion (where the version integer increases monotonically with each re-ingest) the two are equivalent. They diverge in two scenarios:

* **Operator-driven re-ingest of an older version** (collector replay of historical metadata, manual SQL fix-up). The replay carries the older `version` value but a newer `created_at`; "latest" by version returns the just-replayed row's structure.
* **Out-of-order or manually-edited version numbers** in the database (rare; usually only from migrations or recovery).

If you observed a recent re-ingest and the "latest" structure looks unexpected, query an explicit `version_id` from the revision history rather than relying on the no-version-id read.
{% endhint %}

{% hint style="info" %}
**Renaming one parent field in a nested struct shows every descendant field as removed-and-re-added.** On datasets with nested structures (a struct/record column whose sub-fields are themselves diffable), a field's identity includes its parent's ODDRN. When you rename a parent field, every field hierarchically beneath it gets a new ODDRN too — so the diff treats each descendant as a different field, emitting it once as **removed** (under the old name) and once as **added** (under the new name). A single rename near the top of a deep struct therefore renders as a large "everything changed" diff, even though only one name actually changed.

This is expected behaviour, not a diff bug: if you renamed a parent struct field, read the wall of removed/added descendant rows as the consequence of that one rename rather than as independent column changes.
{% endhint %}

## Activity-feed surfacing

Schema changes also surface as events on the [Activity Feed](/features/active-platform-features/activity-feed) — an operator walking the feed sees every metadata change across the catalog including schema edits, alongside ownership / tag / term / status changes.

## Where to next

* [Alerting → Backwards-incompatible schema change](/features/active-platform-features/alerting#backwards-incompatible-schema-change-what-triggers-it) — the alert rule, lifecycle, and operator workflow.
* [Activity Feed](/features/active-platform-features/activity-feed) — the audit trail of every schema (and other metadata) change.
* [Test Results Import](/features/data-quality/test-results-import) — per-adapter coverage of field statistics surfaced on the Structure tab.
* [Data Discovery overview](/features/data-discovery) — the bucket landing this page sits under.


# Metadata stale

Per-entity orange icon shown when an entity has not been re-ingested for longer than \`odd.data-entity-stale-period\` (default 7 days) — signals possible collector or source-side issues.

ODD's catalog reflects the most recently ingested view of every source system. If a collector pauses, fails, or its source goes offline, the metadata for affected entities **goes stale** — the catalog row continues to render, but its ground-truth-on-the-source state is no longer guaranteed. The platform surfaces this with a per-entity **stale indicator** so users can distinguish "actively-maintained metadata" from "metadata of uncertain freshness".

## How the indicator surfaces

Stale entities are marked with an orange clock icon next to the entity name. Hovering the icon reveals the **last refresh timestamp** — the moment the platform last received an ingest for this entity.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-7def4bfd104b600bc5088a190cbe4caf2cffb5e6%2Fmedium-0-IqrIKHTogplOUrLJ.png?alt=media" alt="" height="390" width="700"><figcaption><p>Stale icon and last-refresh tooltip on a catalog entity</p></figcaption></figure>

The same indicator surfaces on:

* The [Catalog Overview](/features/data-discovery/catalog-overview) → Recommended panel tiles.
* [Search](/features/data-discovery/search) result rows.
* The [Directory](/features/data-discovery/directory)'s level-4 entity list.
* The entity's own detail page.

Wherever the entity name appears in the catalog, the stale icon appears next to it once the staleness window elapses.

## The freshness window

The platform considers an entity stale when its last successful ingestion is older than `odd.data-entity-stale-period` (integer; days; **default `7`**).

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-468b855907ff5c339b0bc056ebeef3650782a302%2Fmedium-0-hhj-g7GQg19U9bFb.png?alt=media" alt="" height="209" width="700"><figcaption><p>Default stale period in the platform configuration</p></figcaption></figure>

Operators running collectors on cadences longer than the stale window should raise the value to match — otherwise every entity from a slow-cadence collector flips to stale between scheduled runs even though the collector is healthy. The reference for tuning the value lives at [Configure ODD Platform → Detecting stale metadata](/configuration-and-deployment/odd-platform#detecting-stale-metadata).

## What the indicator does (and doesn't) signal

The stale icon means **"the catalog has not received an ingest for this entity within the configured window"**. It does not by itself diagnose **why**. Common causes:

* The collector is paused or stopped.
* The collector is running but the adapter is failing on this source.
* The source itself is unreachable (network, credentials, deletion).
* The collector's cadence is longer than the stale window (raise the window, or shorten the cadence).
* A specific entity was excluded by an [ingestion filter](/integrations/integrations) and is no longer reported even though peers are.

A stale icon is a discovery-time prompt — *"check whether this is still trustworthy"* — not a runtime alert. For platform-detected runtime issues (failed jobs, failed quality tests, schema-incompatible changes), see [Alerting](/features/active-platform-features/alerting).

## Known limitations and operator caveats

The stale-detection predicate is a single backend check (`last_ingested_at + odd.data-entity-stale-period < now()`) rendered through a single UI widget that returns `null` when an entity is fresh. Five operator-visible behaviours follow from that shape — each one needs to be on every operator's checklist before relying on staleness as a collector-health signal.

{% hint style="danger" %}
**Silent-default footgun: verify `odd.data-entity-stale-period` is present in your deployment overlay.**

The shipped `application.yml` sets the key to `7` days, but the value is bound with no startup validation. If your Helm values, Docker `environment:` block, Kubernetes ConfigMap, or any other overlay tool **removes or empties the line**, the platform resolves the value to `null`. The predicate then returns `false` for every entity in the catalog — no stale icons anywhere, no startup log, no admin warning, no diagnostic banner. The platform looks healthy; collectors could be hours, days, or weeks behind and no signal surfaces.

Treat `odd.data-entity-stale-period` as a **required** configuration key, not an overridable default. After every deployment change touching the platform config, confirm the resolved value in your environment (for example: hit any entity detail page and check whether stale entities elsewhere still render their icons; or read the rendered value off your overlay artefact). The doc-side caveat is the only signal until an explicit startup validator lands.
{% endhint %}

### "No stale icon" does not mean "freshly ingested"

The predicate's first condition is `last_ingested_at IS NOT NULL`. An entity that has never been ingested — manually created in the UI, pending its first collector pull, or skipped by the collector on its first run — has a NULL `last_ingested_at` and therefore reports `is_stale: false`. The UI shows the same absence of icon for "ingested twenty minutes ago" and "never ingested at all"; you cannot distinguish the two from the catalog page alone.

When building dashboards or SLA reports on top of staleness, do not treat absence-of-stale as evidence of recency. Enumerate never-ingested entities separately (e.g. `WHERE last_ingested_at IS NULL` in PostgreSQL) and treat that set as its own freshness category.

### A globally-dead signal is visually indistinguishable from a fully-healthy platform

The stale widget renders the orange icon only when `is_stale=true`; in every other case it renders nothing — no DOM, no whitespace. Combined with the silent-default footgun above, a deployment that has accidentally unset the stale period shows zero stale icons across every list, detail page, and lineage view — looking exactly like a deployment where every collector is hitting its cadence perfectly.

Monitor the count of stale entities outside the UI (`SELECT COUNT(*) FROM data_entity WHERE last_ingested_at + interval '7 days' < now()` or similar against your actual configured period). A flat-line at zero where you previously saw a non-zero baseline is the operator-visible signature of a silent-disable; an unexpected non-zero is a real-time collector incident.

### One global cadence — no per-data-source or per-namespace override

`odd.data-entity-stale-period` is a single deployment-wide integer. There is no per-data-source `stale_period_days` column, no per-namespace override, no per-class default. A deployment that mixes high-cadence sources (a streaming Kafka topic ingested hourly) with low-cadence ones (weekly dbt model snapshots) faces an impossible single-value choice — a 7-day window flags the streaming topic every pause it takes; a 1-hour window flags the weekly dbt models as permanently stale.

The supported posture today is the single global cadence. When you have heterogeneous sources, the recommended compromise is to set the threshold to the **most conservative source's window** (so high-cadence sources flip stale promptly while low-cadence sources keep flipping back and forth) or to accept the flag-noise from the slow sources. Both have trade-offs; neither is a workaround for the missing per-source knob.

### Multi-replica deployments can render the stale icon inconsistently due to clock skew

The stale-detection predicate compares `last_ingested_at + odd.data-entity-stale-period` against `now()` evaluated on the **rendering replica**. Each ODD Platform replica calls its own JVM clock; if the platform runs on multiple pods / nodes whose system times are not strictly NTP-synchronised, two replicas evaluating the same entity at the same wall-clock moment can land on opposite sides of the cutoff. The result is a visual flicker on the catalog UI — an operator refreshing the page on a load-balanced deployment may see the orange icon appear, disappear, and reappear within seconds as their requests round-robin across replicas at the boundary.

This is a low-impact edge case (most production deployments run with sub-second NTP skew, well inside the 7-day default cutoff, so flicker is rarely visible). It becomes operator-observable when the deployment has either set an unusually short `odd.data-entity-stale-period` (hours rather than days) or runs on infrastructure where clock skew is measured in seconds rather than milliseconds. If you see the flicker, audit the replicas' clocks — `kubectl exec` into each pod and compare `date` output, or check your container runtime's clock-sync policy.

### `last_ingested_at` is trust-on-write — the freshness signal is forgeable

The predicate operates on whatever value sits in `last_ingested_at` at read time, without checking whether the writer is the legitimate collector for that source. Any actor with ingestion-write capability against a data source — a collector token, a server-to-server API key, a push-adapter credential — can emit an event with a current timestamp for any entity in that source and the entity will report `is_stale: false`.

This is the read-collaborative posture's write-side mirror: the catalog trusts ingestion writes by design, and the stale signal inherits that trust. For collector-health monitoring, treat the staleness signal as a **freshness lower bound, not an authenticity proof** — combine it with collector-side cron monitoring or job-run alerts so you have an independent signal of whether the source actually produced new data, not just whether something wrote a new timestamp.

## Where to next

* [Configure ODD Platform → Detecting stale metadata](/configuration-and-deployment/odd-platform#detecting-stale-metadata) — the operator-side reference for `odd.data-entity-stale-period`.
* [Catalog Overview page → Recommended panel](/features/data-discovery/catalog-overview#recommended) — where stale tiles surface explicitly with the orange icon.
* [Data entity detail page](/features/data-discovery/entity-detail-page) — the per-entity surface where the stale icon and the relative-time tooltip appear in the header.
* [Alerting](/features/active-platform-features/alerting) — the platform's runtime alert surface for failures (distinct from staleness, which is a freshness signal).
* [Data Discovery overview](/features/data-discovery) — the bucket landing this page sits under.


# Data Modelling

Top-level UI section for data-modelling artefacts — Query Examples and Relationships / ERDs.

The **Data Modelling** section of ODD Platform is the home for operator-curated artefacts that describe how data is *intended* to be used: canonical query examples and the entity-to-entity relationships that collectors extract or that operators define explicitly. The section is intentionally narrow — two child surfaces today — but the role is durable: anything that documents the *contract* of a dataset (how it's queried, how it's connected) belongs here rather than in the per-entity catalog page.

Open it from the top-level navigation **Data Modelling**. The route opens on **Query Examples** by default; a vertical-tabs sidebar switches between Query Examples and Relationships in one click.

## Subsections

* [**Query Examples**](/features/data-modelling/query-examples) — operator-curated SQL / KQL / Spark snippets attached to data entities and terms. Surfaces "how the team uses this dataset" as a first-class catalog object instead of leaving it buried in a wiki, with a dedicated faceted search and term-linking workflow.
* [**Relationships**](/features/data-modelling/relationships) — entity-to-entity links rendered as ERD diagrams. Covers two relationship classes: `ENTITY_RELATIONSHIP` (foreign-key-style ERD edges between table-class entities) and `GRAPH_RELATIONSHIP` (free-form graph edges, e.g. between Neo4j nodes).

## UI entry points

| Path                                  | What                                                                                                                                                                                              |
| ------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `/data-modelling`                     | Redirects to `/data-modelling/query-examples`.                                                                                                                                                    |
| `/data-modelling/query-examples`      | Query Examples list + creation surface. Read-open to any authenticated user; `QUERY_EXAMPLE_CREATE` gates only the **Add** button, not the list view.                                             |
| `/data-modelling/query-examples/{id}` | Query Example details / edit. Read-open to any authenticated user; `QUERY_EXAMPLE_UPDATE` / `QUERY_EXAMPLE_DELETE` gate only the per-example **edit** / **delete** actions, not the details view. |
| `/data-modelling/relationships`       | Relationships list — ERD and graph relationships discovered across all data sources.                                                                                                              |

## Why this is a separate pillar

For how Data Modelling relates to the other governance pillars (Data Discovery, Master Data Management, Data Lineage, Data Glossary, Data Quality), see [Main Concepts → Data Governance map → Pillar differentiation](/introduction/main-concepts#pillar-differentiation) — the canonical home for the six-pillar framing. Data Modelling is its own pillar because it captures the *contract* of a dataset (how it's queried, how it's connected) — the dataset itself comes from outside; this pillar records the intent and structure layered on top.

## Where to next

* If you're documenting how a dataset is *queried*, start with [Query Examples](/features/data-modelling/query-examples).
* If you're discovering how datasets are *connected* (foreign keys, cross-schema joins, graph references), start with [Relationships](/features/data-modelling/relationships).
* For the broader catalog vocabulary (Data Entity, Plugin, Push adapter, …), see [Main Concepts](/introduction/main-concepts).


# Query Examples

Operator-curated SQL / KQL / Spark snippets attached to data entities and terms — the canonical "how to use this dataset" surface.

**Query Examples** are operator-curated query snippets — typically SQL, but anything that reads as a "how the team uses this dataset" example — attached to one or more data entities and optionally linked to glossary terms. They turn the catalog from "what we have" into "what we have *and* how to use it", without forcing readers to dig into a wiki or ping the team that owns the data.

Query Examples is the first sub-surface of the [Data Modelling](/features/data-modelling) section.

## What you can do

* **Author and edit** snippets with a name, description, and the query body. The description doubles as a "prompt"-style explanation of intent.
* **Link a snippet to one or more data entities** (tables, views, files) so it shows up on the entity's detail page as one of the canonical examples.
* **Link a snippet to glossary terms** so terminology + canonical usage stay close to each other.
* **Search the catalog of snippets** with a dedicated faceted search that supports filters, the same shape as the main catalog search.
* **Get search suggestions** as you type — the top five matching snippet titles for a query string.

## UI walkthrough

Open **Data Modelling → Query Examples** from the top-level navigation (`/data-modelling/query-examples`). The list view shows every snippet the user is allowed to read, with a search box and an "Add query example" button. The button is gated by the `QUERY_EXAMPLE_CREATE` permission — users without it see the list but no create entry-point.

![Query Examples list page — each row carries the snippet's number, definition, query body preview, linked data entities (ORDERS, CUSTOMER, LINEITEM), and any linked glossary terms (2NF). The left-rail switches between Query Examples and Relationships, the two Data Modelling sub-surfaces.](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-55059de8a6923dc190b207bf25089da0e825ff40%2Fquery-examples.png?alt=media)

* **List page** (`/data-modelling/query-examples`) — all snippets, with search, total count, and the create button.
* **Details / edit page** (`/data-modelling/query-examples/{id}`) — the snippet's full body, its description, and the linked data entities and terms. Edit and delete actions are gated by `QUERY_EXAMPLE_UPDATE` and `QUERY_EXAMPLE_DELETE` respectively.
* **On a dataset's detail page** — Query Examples linked to that dataset surface in the dataset's "Query Examples" tab; operators with `QUERY_EXAMPLE_DATASET_CREATE` can attach existing snippets, and `QUERY_EXAMPLE_DATASET_DELETE` users can detach.
* **On a term's detail page** — same pattern, gated by `QUERY_EXAMPLE_TERM_CREATE` and `QUERY_EXAMPLE_TERM_DELETE`.

## Permissions (RBAC)

Seven permissions on the Query Example surface, all configurable on roles via the standard authorization model (see [Authorization → Roles](/configuration-and-deployment/enable-security/authorization/roles)):

| Permission                     | What it gates                                                           |
| ------------------------------ | ----------------------------------------------------------------------- |
| `QUERY_EXAMPLE_CREATE`         | Create a new snippet (the "Add query example" button on the list page). |
| `QUERY_EXAMPLE_UPDATE`         | Edit an existing snippet.                                               |
| `QUERY_EXAMPLE_DELETE`         | Delete an existing snippet.                                             |
| `QUERY_EXAMPLE_DATASET_CREATE` | Attach a snippet to a dataset (entity ↔ snippet link).                  |
| `QUERY_EXAMPLE_DATASET_DELETE` | Detach a snippet from a dataset.                                        |
| `QUERY_EXAMPLE_TERM_CREATE`    | Attach a snippet to a glossary term (term ↔ snippet link).              |
| `QUERY_EXAMPLE_TERM_DELETE`    | Detach a snippet from a glossary term.                                  |

## API surface

The full HTTP API for Query Examples is documented at [API Reference → Query Examples](/developer-guides/api-reference/query-examples) — 16 endpoints across three groups (CRUD, faceted search, per-entity/per-term lookup and linking), exposed by `QueryExampleController` and the Data Entity / Term controllers, with the seven `QUERY_EXAMPLE_*` permissions called out alongside the gated endpoints. To call them outside the in-app UI, authenticate with a [server-to-server (S2S) API key](/configuration-and-deployment/enable-security/authentication/s2s).

## Term-linking workflow

Glossary terms and Query Examples reinforce each other: a term defines what a concept *is* (e.g., "active customer"); a query example shows how to *compute it* against your real datasets. The platform supports both directions:

1. From a term's detail page, attach an existing Query Example. The term gains a "Query Examples" cluster surfacing the snippet alongside the linked datasets.
2. From a snippet's detail page, link the snippet to one or more terms. The snippet gains a "Terms" cluster.
3. The dedicated Query Example faceted search exposes a Terms facet — narrow snippets to ones that target a specific glossary term.

This closes the catalog loop: a reader landing on the term finds the canonical snippet; a reader landing on the snippet finds the term it implements.

## Query Example Details Page

Opening any Query Example from the list (`/data-modelling/query-examples/{id}`) lands on a three-tab details page. The active tab is driven by a `?tab=` URL query parameter:

| Tab                 | URL state                                 | What it shows                                                                                                                                                                         |
| ------------------- | ----------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Overview**        | `?tab=overview` (or no `?tab=` — default) | The snippet's `definition` (prompt-style description) and the `query` body, both rendered through the platform's Markdown renderer.                                                   |
| **Linked Entities** | `?tab=linked-entities`                    | The data entities this snippet is attached to (tables, views, files). Read-only — unlinking requires opening the linked entity's own detail page and removing the snippet from there. |
| **Linked Terms**    | `?tab=linked-terms`                       | The glossary terms this snippet is linked to. Read-only with the same workflow note.                                                                                                  |

The tab strip carries small counter "hint badges" next to each tab name showing how many entries it contains.

{% hint style="warning" %}
**Arbitrary `?tab=` values render an empty body.** The page accepts the URL parameter verbatim — it does not validate that the value is one of the three known tokens above. A typo (`?tab=overiew`, `?tab=linked_entities` with underscore) or a future-renamed token lands the user on the page with **no active tab and a blank content area** — no error message, no "tab not found" placeholder. If you are deep-linking from another system, validate the token on your side before generating the URL.
{% endhint %}

{% hint style="info" %}
**The "Linked Terms" hint badge can understate when a snippet has many terms.** The Linked Entities badge reads the total from server-side pagination (it is correct across all pages). The Linked Terms badge reads `items.length` on the loaded slice (it understates if the term collection is large enough to paginate). The tab body itself shows all loaded terms; only the badge digit may differ from the total.
{% endhint %}

The details page does not carry a breadcrumb back to the list — use the **Data Modelling → Query Examples** left-rail tab to return to the listing, or the browser Back button.

## Known operator caveats

The Query Examples surface carries several behaviours that are non-obvious from the UI and the permission table alone. Each item below states what an operator might assume, what the platform actually does, and what to do today.

{% hint style="warning" %}
**The seven `QUERY_EXAMPLE_*` permissions are wired across three different controllers.** Configuring "Query Example access" in a single Policy is not enough — the gating endpoints live on three different surfaces:

When granting Query Example capability to a role, audit Policies on all three controllers. Restricting `QUERY_EXAMPLE_*` in one Policy scope (e.g., only the Query Example controller) leaves four of the seven permissions un-enforced on that role — operators can still attach / detach snippets from datasets or terms.
{% endhint %}

| Permissions                                    | Controller surface       | Endpoints                                                        |
| ---------------------------------------------- | ------------------------ | ---------------------------------------------------------------- |
| `QUERY_EXAMPLE_CREATE` / `_UPDATE` / `_DELETE` | Query Example controller | `POST/PUT/DELETE /api/queryexample/...`                          |
| `QUERY_EXAMPLE_DATASET_CREATE` / `_DELETE`     | Data Entity controller   | `POST/DELETE /api/dataentities/{id}/queryexample[/{example_id}]` |
| `QUERY_EXAMPLE_TERM_CREATE` / `_DELETE`        | Term controller          | `POST/DELETE /api/terms/{id}/queryexample[/{example_id}]`        |

{% hint style="warning" %}
**All read, search, and listing endpoints for Query Examples are open to every authenticated user — only the seven mutation permissions are RBAC-gated.** The mutation operations (CREATE / UPDATE / DELETE on snippets, dataset-link CREATE / DELETE, term-link CREATE / DELETE) check the permission table above. The listing surface (`GET /api/queryexample`), the per-snippet read (`GET /api/queryexample/{id}`), the faceted search endpoints, and the per-entity / per-term lookup endpoints all fall through to the platform's catch-all "any authenticated user" rule.

**Operator-visible consequence.** Every authenticated user reads every Query Example in the platform — title, description, query body, linked entities, linked terms — regardless of dataset RBAC, namespace scoping, or `exclude_from_search`. Under `auth.type=DISABLED`, the same reads are anonymous. Multi-team deployments expecting per-team query-example visibility cannot enforce it through the RBAC layer today. Treat Query Example content as catalog-read-collaborative; sensitive SQL bodies (production credentials, restricted column references, internal table aliases) should not be authored here, or should be enforced at the network perimeter via reverse-proxy rules.
{% endhint %}

{% hint style="info" %}
**The Query Example Markdown render is HTML-sanitised as of 0.28.0.** The `definition` (prompt-style description) and `query` (SQL body) fields are stored verbatim and rendered through the platform's shared Markdown renderer on the details page. Releases up to 0.27.x ran that renderer without an HTML-sanitisation pass, so HTML embedded in either field rendered for every viewer; **0.28.0 adds render-time sanitisation** to the shared Markdown renderer, so `<script>`, `javascript:` hrefs, and other raw-HTML payloads in a Query Example body are stripped when the snippet is displayed.

**Still review what you store.** Sanitisation is a render-time defence, not an input filter: the raw field value is stored verbatim and is readable by every authenticated user through the open read endpoints above. Restrict `QUERY_EXAMPLE_CREATE` and `QUERY_EXAMPLE_UPDATE` to operators reviewing the source of every value they paste in, and avoid bulk-importing Query Examples from untrusted external systems.
{% endhint %}

{% hint style="warning" %}
**The create / edit dialog has no client-side validation and no draft persistence.** The Query Example form validates only that the `definition` and `query` fields are non-empty — there is no length cap and no content preview. Values are stored verbatim; rendered Markdown is HTML-sanitised at display time as of 0.28.0 (see the note above).

The dialog also has **no dirty-form warning and no autosave**: closing the dialog through Escape, an outside-click, or browser back drops the entire in-progress body silently. For a SQL snippet of moderate size this is a real loss — minutes-to-hours of work disappear without recovery. Workaround: copy the SQL body to the clipboard before closing the dialog; treat the dialog as ephemeral until the upstream `handleNavigationWarning` hook ships.
{% endhint %}

{% hint style="info" %}
**The `definition` field is a plain text input at authoring time but renders through the Markdown renderer on the details page.** An author typing `**bold**` or `## Heading` into the definition field sees plain text in the form preview but rendered Markdown on the details page. Review the rendered details page after the first save to catch formatting surprises (rendered Markdown is HTML-sanitised as of 0.28.0 — see the render-sanitisation note above).
{% endhint %}

{% hint style="warning" %}
**Query Example mutations are not recorded on the Activity Feed.** Creating, updating, deleting, or linking / unlinking a Query Example produces no entry on the global Activity Feed and no entry on the per-entity Activity tab. There is no platform-side audit trail for Query Example changes today — auditor queries of "who edited which snippet when" cannot be answered from platform logs. The wider audit-scope picture and the compensating controls operators can apply are documented on the [Audit trail scope](/configuration-and-deployment/enable-security/audit-trail-scope) page; until the platform-side activity-event ships, instrument Query Example changes externally (PostgreSQL `pgaudit` on the `query_example` and `query_example_*` tables, or an API-gateway-level audit hook).
{% endhint %}

## Where to next

* [Data Modelling overview](/features/data-modelling) — parent section; pairs Query Examples with Relationships.
* [Relationships](/features/data-modelling/relationships) — the other Data Modelling sub-surface.
* [Authorization → Roles](/configuration-and-deployment/enable-security/authorization/roles) — wire the seven `QUERY_EXAMPLE_*` permissions onto your roles.
* [Audit trail scope](/configuration-and-deployment/enable-security/audit-trail-scope) — the cross-platform list of surfaces that emit Activity-Feed events versus those that do not.
* [API reference](/developer-guides/api-reference) — the full Ingress / management API.


# Relationships

Entity-to-entity relationships in the catalog — ERD edges from foreign keys and graph edges between graph-store nodes.

ODD Platform tracks entity-to-entity relationships as first-class catalog objects. They show up two ways: as **ERD diagrams** between table-class entities (foreign-key-style edges) and as **graph relationships** between graph-store entities (Neo4j-style edges). Both are surfaced under [Data Modelling](/features/data-modelling) → Relationships in the UI and through the `/api/relationships` API.

## The two relationship classes

The platform's internal model defines a `DATA_RELATIONSHIP(9)` data-entity class that contains two types:

| Internal type             | API filter value | What it represents                                                                                                                                                                                           |
| ------------------------- | ---------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `ENTITY_RELATIONSHIP(25)` | `ERD`            | Foreign-key-style edges between two table-class entities. Cross-schema references are supported. The collector that catalogs the source emits one `ENTITY_RELATIONSHIP` per detected foreign-key constraint. |
| `GRAPH_RELATIONSHIP(26)`  | `GRAPH`          | Free-form graph edges between graph-store entities (e.g., relationships between nodes in a Neo4j database). Distinct from ERD because the cardinality model is graph-native, not relational.                 |

A relationship is a regular catalog entity — it has an ODDRN, an owner, a namespace inherited from its source / target, and shows up in search alongside datasets. The dedicated UI surface and `/api/relationships` API are for **list and detail navigation** of just the relationship-class entities.

## ERD cardinality model (ENTITY\_RELATIONSHIP)

ERD relationships carry the source-and-target table pair plus a cardinality classifier. Four classifiers are defined upstream:

* `ONE_TO_EXACTLY_ONE` — one source row maps to exactly one target row.
* `ONE_TO_ZERO_OR_ONE` — one source row maps to zero or one target row.
* `ONE_TO_ONE_OR_MORE` — one source row maps to one or more target rows.
* `ONE_TO_ZERO_ONE_OR_MORE` — one source row maps to zero, one, or many target rows.

These mirror the cardinality vocabulary defined in the `odd-collectors` monorepo's [Relationships section](https://github.com/opendatadiscovery/odd-collectors#relationships).

## UI walkthrough

Open **Data Modelling → Relationships** from the top-level navigation (`/data-modelling/relationships`). The list page shows every visible relationship across all data sources — as of 0.28.0 it applies the catalog's default visibility rules, so soft-deleted, hollow, and excluded-from-search relationship entities are filtered out (earlier releases listed them here even after every other catalog surface hid them). The page shows:

* **A table** with columns Name, Type (ERD or GRAPH), Namespace + Datasource, Source entity, Target entity.
* **A type tab strip** filtering by `ALL` / `ERD` / `GRAPH` (matches the API enum).
* **A search input** filtering by name across the visible set.
* **Infinite-scroll pagination** — page size is 30 by default.

Click a row to open the relationship's detail page; the platform routes to the `/api/relationships/erd/{id}` or `/api/relationships/graph/{id}` payload depending on the relationship type.

![Relationships list page — eight ENTITY\_RELATIONSHIP rows from a Snowflake sample-data source, each with its name, type (ENTITY RELATIONSHIP), namespace + datasource, source entity, and target entity. The All / ERD / Graph type-filter strip sits above the table; the right-rail switches between Query Examples and Relationships, the two Data Modelling sub-surfaces.](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-b725d83bfb72f24ef93c1503d58f31bea4144f1d%2Frelationships.png?alt=media)

The same data is also surfaced **per-entity** — every dataset's detail page has a **Relationships** tab (in the same tab strip as Overview / Structure / Lineage / Test reports / Alerts / Query examples / Activity / Discussions) that lists only the relationships in which the current entity participates as Parent or Child:

![Per-entity Relationships tab on the ORDERS table (DS / TABLE) — two relationships: (1) ORDERS\_references\_CUSTOMER with CUSTOMER as Parent and ORDERS as Child, cardinality ONE TO ZERO ONE OR MORE, Is Identifying False; (2) LINEITEM\_references\_ORDERS with ORDERS as Parent and LINEITEM as Child, cardinality ONE TO ZERO ONE OR MORE, Is Identifying True. Each row carries an inline ERD-style cardinality glyph (crow's-foot notation) between the Parent and Child columns.](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-98e270ead1ba13476ced3175a7e839b457e61fc7%2Fentity-relationships.png?alt=media)

The per-entity view is the operator-relevant perspective: when reading a table's documentation, you see only its incoming and outgoing relationships, not the whole catalog's. The Parent / Child columns and the cardinality glyph match the underlying `ENTITY_RELATIONSHIP` model and the same `/api/relationships/erd/{id}` payload surfaces both in this tab and on the global Data Modelling → Relationships list above. As of 0.28.0 this tab hides soft-deleted and hollow relationship entities, but — unlike the global list — it deliberately keeps `exclude_from_search`-flagged ones visible: that flag scopes discovery surfaces, and the dataset's own detail tab would be silently incomplete without its real relationships.

## API surface

The three endpoints exposed by `RelationshipController` are documented at [API Reference → Relationships](/developer-guides/api-reference/relationships) — `GET /api/relationships` (paginated list with optional `type=ERD|GRAPH|ALL` filter and free-text query) plus the two per-type detail endpoints. The same payloads also surface on the source and target dataset's detail pages under the dataset's relationships cluster.

## How relationships get into the catalog

Relationships are populated **by the ingesting collector** during the source-side metadata pull. The platform does not infer relationships from naming conventions or column-name similarity — only what the collector emits is surfaced.

Adapter coverage as of the time of writing (per the upstream [`odd-collectors` Relationships matrix](https://github.com/opendatadiscovery/odd-collectors#relationships)):

| Collector       | Adapter      | Relationship type           | How it's derived                                                                |
| --------------- | ------------ | --------------------------- | ------------------------------------------------------------------------------- |
| `odd-collector` | `postgresql` | `ENTITY_RELATIONSHIP` (ERD) | Foreign-key constraints in the database catalog. Cross-schema FKs are detected. |
| `odd-collector` | `snowflake`  | `ENTITY_RELATIONSHIP` (ERD) | Foreign-key constraints in the database catalog. Cross-schema FKs are detected. |

{% hint style="info" %}
**No other adapter currently emits relationships.** The `GRAPH_RELATIONSHIP` type is reserved in the platform model for graph-store sources (e.g., Neo4j edges), but no adapter in the published `odd-collectors` Relationships matrix currently surfaces graph relationships at the time of writing — operators using a Neo4j adapter today get nodes catalogued without their inter-node edges. This is an upstream collector-side gap; if your deployment relies on graph relationships, follow the upstream repo for adapter changes.
{% endhint %}

## Known operator caveats

Four behaviours of the Relationships surface are non-obvious from the UI alone — they are model contracts to know about, not defects. Two further code-side defects from earlier releases (the Target-column rendering and the unvalidated `?type=` parameter) were **fixed in 0.28.0**; the notes below describe them for operators on 0.27.x and earlier.

{% hint style="info" %}
**Fixed in 0.28.0 — the Target column previously showed the source entity.** On 0.27.x and earlier, the list-row renderer passed the source entity's data to both the Source and the Target cells, so every row displayed the same dataset twice and a discovery workflow of the form "find every relationship where `ORDERS` is the target" was impossible from this page. As of 0.28.0 the Target column renders the actual target entity. On affected releases, use the per-entity Relationships tab (which was never affected) for target-side questions.
{% endhint %}

{% hint style="warning" %}
**There is no RBAC gate on the Relationships endpoints — any authenticated caller can list every visible relationship in the catalog.** Neither `GET /api/relationships` nor the two per-type detail endpoints (`/api/relationships/erd/{id}` and `/api/relationships/graph/{id}`) are enumerated in the platform's authorization rules; the catch-all "any authenticated user" rule applies, and the query does not filter by owner or namespace. The catalog UI route mounts bare — contrast with `/data-modelling/query-examples`, which is wrapped in a permission-context provider. (Until 0.28.0 the listing also ignored the catalog's visibility flags — soft-deleted and excluded-from-search relationship entities stayed listed here after every other surface hid them; as of 0.28.0 the default visibility rules apply, so this caveat is now purely about access, not visibility.)

**Operator-visible consequence.** Every authenticated user reads every visible relationship in the catalog, across team boundaries. Under `auth.type=DISABLED`, the same listing is anonymous. Multi-team deployments expecting per-team isolation on relationships cannot enforce it through the platform's RBAC today.

**Mitigation today.** Treat the Relationships listing as catalog-read-collaborative — the same posture as the Owner / Namespace / Datasource directories. If your deployment requires per-team isolation on relationships specifically, enforce it at the network perimeter (reverse-proxy rules on `/api/relationships/*` plus the corresponding UI route).
{% endhint %}

{% hint style="warning" %}
**Clicking a row on the list opens the source entity's detail page — not a relationship-type-specific URL.** The row's Name link routes to `/dataentities/{id}` (the entity-detail-page route) on every click, regardless of relationship type. The two type-specific endpoints (`/api/relationships/erd/{id}` and `/api/relationships/graph/{id}`) are reached **from inside** the entity-detail page's relationship-card rendering, not from the row click on the list page. If you are scripting deep-links into "the relationship's detail view," use the per-entity Relationships tab on the source / target entity's page; there is no list-page row URL that lands on a type-specific relationship view today.
{% endhint %}

{% hint style="warning" %}
**The search input filters by relationship name only — not by source or target entity name.** Typing `orders` into the list-page search box matches relationships whose own `name` field contains the string `orders` (case-insensitive). It does **not** match relationships where the source or target entity is named `ORDERS`. The behaviour is consistent with how the platform models relationships as first-class entities, but the framing on the page above ("search input filtering by name across the visible set") does not call out the scope.

**To find every relationship that involves a specific dataset**, open that dataset's detail page → Relationships tab. That surface lists only the relationships in which the entity participates as Parent or Child, which is the question operators usually mean when they search.
{% endhint %}

{% hint style="info" %}
**Fixed in 0.28.0 — a mistyped `?type=` URL parameter previously rendered a dead, blank view.** On 0.27.x and earlier, the page sent the raw value to the backend, which rejected it with an opaque HTTP 400 from enum-binding; the tab strip showed no active tab and the list read "0 relationships overall" with no error message — indistinguishable from an empty catalog. As of 0.28.0 an unknown value (`?type=erd` lower-case, `?type=Erd` mixed-case, anything outside `ALL` / `ERD` / `GRAPH`) falls back to the `ALL` view with the All tab active. The accepted tokens are still exactly `ALL` / `ERD` / `GRAPH` (case-sensitive) — deep links using other spellings load the unfiltered list, not the intended tab.
{% endhint %}

{% hint style="info" %}
**The `relationship_id` path parameter on the API is the relationship's data-entity id, not the `relationships` table primary key.** The platform models a relationship as a regular catalog entity (entity-class id `9`, `DATA_RELATIONSHIP`). The API parameter named `relationship_id` is the corresponding `data_entity.id`; the underlying `relationships.id` row is internal and is not the value the API consumes.

The same trap exists **inside the API payload itself**: the details response exposes `erd_relationship.erd_relationship_id` and `graph_relationship.graph_relationship_id` — internal detail-record ids from two further tables. Feeding either back into `/api/relationships/{type}/{id}` returns a 404 (or, on a numeric coincidence with another relationship's data-entity id, the payload of an unrelated relationship). The only value that round-trips is the relationship's own `id` field from the list or details payload; the UI always uses it and is unaffected. As of 0.28.0 the OpenAPI spec states this on the `relationship_id` parameter and on both `*_relationship_id` fields.
{% endhint %}

## Where to next

* [Data Modelling overview](/features/data-modelling) — parent section; pairs Relationships with Query Examples.
* [Query Examples](/features/data-modelling/query-examples) — the other Data Modelling sub-surface.
* [Integrations → odd-collector](/integrations/integrations/odd-collector) — the generic collector that hosts the PostgreSQL and Snowflake adapters surfacing ERD relationships today; the per-adapter feature matrix on that page calls out ERD support explicitly.
* [Main Concepts](/introduction/main-concepts) — for the broader catalog vocabulary that names these entities.


# Master Data Management

Master Data Management aspect of Data Governance — operator-curated reference data managed inside the platform.

The **Master Data Management** section of ODD Platform is the home for operator-curated reference data — the canonical lists, lookup values, and code tables that downstream pipelines and BI tools join against. The section is intentionally narrow today (one child surface — Lookup Tables), but the role is durable: anything that documents *authoritative reference data managed inside the platform itself* (rather than ingested from an external source) belongs here.

ODD covers Master Data Management partially today — what ships is **Reference Data Management** (operator-managed lookup / reference tables as first-class catalog entities). Full MDM semantics (golden records, survivorship rules, stewardship workflows) are not part of ODD; see the [Data Governance map](/introduction/main-concepts#data-governance-map) for the position of MDM in the overall pillar set.

Open it from the **Master Data** top-level toolbar tab.

## Subsections

* [**Lookup Tables**](/features/master-data-management/lookup-tables) — operator-curated reference tables managed inside the platform. Schema, data tab, RBAC (9 `LOOKUP_TABLE_*` permissions on three surfaces — table, definition, data), full `/api/referencedata/` API surface, and direct PostgreSQL access via `lookup_tables_schema`.

{% hint style="warning" %}
**The 9 `LOOKUP_TABLE_*` permissions are platform-wide, not per-table.** Unlike the per-entity-scoped Term and Data-Entity permissions, a Policy granting (for example) `LOOKUP_TABLE_UPDATE` lets the holder modify **any** Lookup Table in the catalog — there is no per-table or per-owner scoping on these permissions today. Grant them only to operators trusted across the entire reference-data surface. The full per-permission breakdown lives on the [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) page and the [Lookup Tables](/features/master-data-management/lookup-tables) feature page.
{% endhint %}

## Why this is a separate pillar

For how Master Data Management relates to the other governance pillars (Data Discovery, Data Modelling, Data Lineage, Data Glossary, Data Quality), see [Main Concepts → Data Governance map → Pillar differentiation](/introduction/main-concepts#pillar-differentiation) — the canonical home for the six-pillar framing. The closest neighbour is Data Modelling — both involve operator authoring inside the platform — but the difference is structural: Data Modelling artefacts attach to existing entities (a Query Example links to a dataset that a collector ingested); Master Data artefacts *are* entities (a Lookup Table is itself a Data Entity of type `LOOKUP_TABLE`).

## Where to next

* [Lookup Tables](/features/master-data-management/lookup-tables) — the only Master Data feature today; full reference.
* [Main Concepts → Data Governance map](/introduction/main-concepts#data-governance-map) — for the position of Master Data Management among the other governance pillars (Data Discovery, Data Lineage, Data Quality, Data Modelling, Data Glossary).
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — for the regenerated permission list (includes the 9 `LOOKUP_TABLE_*` rows).


# Lookup Tables

Operator-curated reference tables managed inside the ODD Platform — schema, data, RBAC, and API surface.

**Lookup Tables** are operator-curated reference tables that live inside the ODD Platform itself rather than in an external source system. The platform manages their lifecycle end-to-end: schema definition, row-level data entry, versioning of structure changes, RBAC, and read access via the platform's API. Each lookup table is exposed in the catalog as a standard Data Entity (entity type `LOOKUP_TABLE`, ID `24`), so existing search, tagging, descriptions, and term-linking flows apply uniformly.

In the platform UI, lookup tables live under the top-level **Master Data** tab → **Lookup Tables**. The same page name appears throughout the API and code as "Lookup Table"; "Master Data" is the toolbar tab label, "Lookup Table" is the per-row noun.

![Master Data → Lookup Tables list page — every lookup table the user can read, with name, description, and namespace columns plus search and the + Add new entry-point gated by the LOOKUP\_TABLE\_CREATE permission.](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-c612dc15e543fc60d6992515936f7e67260bef69%2Flookup-tables.png?alt=media)

## Creating a Lookup Table

The creation of Lookup Tables involves adding a new table through the **`+Add new`** button in the right upper corner of the Master Data section. On a physical level, this implies that an actual table will be generated by ODD using the specified [configuration](/configuration-and-deployment/odd-platform) connection. These tables are entirely managed by the ODD Platform.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-8d41674ad7ec6221c5afef2b9f13206f6add8478%2Fmedium-0-FIZPRcSVE9FYJT90.png?alt=media" alt="" height="383" width="700"><figcaption><p>Adding a new table</p></figcaption></figure>

When a Lookup Table is created a Data Entity of type "lookup table" is generated.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-0b612502a90830360504033f7f00b41318b4159b%2Fmedium-0-URL-MNBGb-9bVEIp.png?alt=media" alt="" height="162" width="700"><figcaption><p>Lookup Table is created</p></figcaption></figure>

The Table name entered during creation is assigned to it as a Business Name. Simultaneously, an Original Name is provided, prefixed with the ID of Namespace. This prefix is added to distinguish tables with potentially identical names and it ensures that the tables adhere to a format acceptable for PostgreSQL.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-efe5ddc7fb6ccb89837479c1cd342bb061007440%2Fmedium-0-okyWl4Qx-jzS804g.png?alt=media" alt="" height="411" width="700"><figcaption><p>The Business and the Original names of Lookup Table</p></figcaption></figure>

The Original Name of Lookup Table functions as a table identifier within PostgreSQL, allowing it to be identified by the users. This information is useful when tasks such as uploading the table elsewhere or establishing a direct connection to the table data are required. **Renaming the table after creation issues `ALTER TABLE … RENAME TO` against the underlying PostgreSQL table** — downstream BI / ETL pipelines that hardcoded the old name break immediately. See the [rename-break caveat](#known-operator-caveats) below before renaming a table that any downstream consumer depends on.

## Lookup Table structure

The creation of the Lookup Table structure starts with column creation on a Structure Tab. Column creation starts with **`+Add column`** button and requires the specification of Column Name.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-d88e6e5480f90619d4b3e92cc4411bada027d86b%2Fmedium-0-yKIhT5moRtreO6OC.png?alt=media" alt="" height="413" width="700"><figcaption><p>Column creation</p></figcaption></figure>

In contrast to the Table Name, which can assume any format, the right selection of name at this stage is crucial and adhering to a specific format is considered essential.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-d52a91503d5857a4187ac8cfc78ea9aa6d0839c0%2Fmedium-0-LD1lrr0ujQMfLg3P.png?alt=media" alt="" height="442" width="700"><figcaption><p>Specific format for Column Name is required</p></figcaption></figure>

Further, the creation of Descriptions occurs at this point. Essentially, the columns that will be generated within the current table are the focus of these descriptions. The final step in creating a column involves selecting a Data Type. Currently, a limited list of PostgreSQL data types is supported for columns (see [Supported field types](#supported-field-types) below). Once the Column Name, Description and Data Type are provided, the column is created by clicking on the **`Add column`** button.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-3e3a04ebeac81d2f566af06d2d1df85a8e1e0899%2Fmedium-0-R42dOZFhGp5xkonh.png?alt=media" alt="" height="344" width="700"><figcaption><p>Lookup Table Structure</p></figcaption></figure>

It is possible to further edit, i.e. to rename column or edit the description for that column, or delete columns:

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-b8a46343ddf6be403b66801ccb17c31f0aa14d52%2Fmedium-1-jDVCVX1zuMHQlQWqexIPrw.png.png?alt=media" alt="" height="403" width="700"><figcaption><p>Deleting a Column</p></figcaption></figure>

Once a column is created and its corresponding data type is already selected, the alteration of that data type becomes impossible.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-530302b2831abae137f0338062486c18649e6c2b%2Fmedium-1-Q_X_r-DeljWcIgL8ZHm97A.png.png?alt=media" alt="" height="400" width="700"><figcaption><p>Editing a Column</p></figcaption></figure>

If there is a need to change the data type for a column, a secure approach involves the:

1. creation of a new column with the desired data type,
2. transfer of the old column data to the new column, and
3. deletion of the old column.

This method ensures a ***secure approach to any data migration***.

Each time the table structure is modified, a new revision of structure is generated, allowing table version differences to be tracked.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-2f9a0a6ba1d631ea0230148792d4fcd2228f119b%2Fmedium-1-2pqmNA1F0hOV2X4RifsRSw.png.png?alt=media" alt="" height="332" width="700"><figcaption><p>Revisions</p></figcaption></figure>

### Supported field types

A column's data type is selected once at column creation and cannot be changed afterwards (use the migration pattern above). The platform exposes the following nine field-type options via the `LookupTableFieldType` enum. They map to **eight** distinct PostgreSQL types — `SERIAL` is not a separate type but an auto-increment `INTEGER`, so it shares the underlying `integer` type with the plain `INTEGER` option:

| Field type | PostgreSQL mapping | Typical use                                                                                                                                 |
| ---------- | ------------------ | ------------------------------------------------------------------------------------------------------------------------------------------- |
| `VARCHAR`  | `varchar`          | Variable-length text.                                                                                                                       |
| `INTEGER`  | `integer`          | 4-byte signed integer.                                                                                                                      |
| `SERIAL`   | `serial`           | Auto-incrementing integer (typical for synthetic keys); the primary-key `id` column is generated automatically and cannot be redefined.     |
| `DECIMAL`  | `numeric`          | Arbitrary-precision decimal.                                                                                                                |
| `BOOLEAN`  | `boolean`          | True/false.                                                                                                                                 |
| `DATE`     | `date`             | Calendar date (no time component).                                                                                                          |
| `TIME`     | `timestamp`        | A full date+time instant, **not** a time-of-day. Supply values as `yyyy-mm-dd hh:mm:ss`; a bare time-of-day value is rejected with a `400`. |
| `JSON`     | `json`             | JSON document.                                                                                                                              |
| `UUID`     | `uuid`             | 128-bit identifier.                                                                                                                         |

Per-column validation is also configurable: each field carries `is_nullable` (default `true`), `is_unique` (default `false`), and an optional `default_value` string.

## Adding and managing data

Within ODD Platform an exclusive Data tab is made available for Lookup Tables. It displays a table with headers that mirror the structure of Lookup Table, which is created in the Structure tab. When a column is added in the Structure tab, its appearance in the Data tab is immediate.

Data values can be inputted into the table columns by clicking on **`[+]`** button within the Data tab.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-5991194627e13ae00f00add65df7c23476e26c02%2Fmedium-0-mrxWiNOtENV7fsrK.png?alt=media" alt="" height="175" width="700"><figcaption><p>Lookup Table Headers</p></figcaption></figure>

This table has a flexible structure, allowing addition of multiple diverse columns.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-b7a7741dbcd8acdd8119d97392192f96db37db68%2Fmedium-0--8XYwx6J9WQP_3YA.png?alt=media" alt="" height="232" width="700"><figcaption><p>Filling in the columns with data</p></figcaption></figure>

Even after filling in the columns with data, the table structure remains customizable, i.e. it is still possible to edit, add or delete its columns. The filled in data is also subject to be edited or deleted.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-e07e9a50a5ee425da170acca712dc5befcaedf44%2Fmedium-0-vReV3H79TXpqSJ7P.png?alt=media" alt="" height="255" width="700"><figcaption><p>Lookup Table Data is subject to be edited or deleted</p></figcaption></figure>

The information entered into the table resides in a separate schema within the database (`lookup_tables_schema` — see [Direct database access](#direct-database-access) below).

## Lookup Table vs regular Data Entity

The Lookup Table is essentially the same as regular Data Entity in ODD. The key difference lies in the fact that for a standard data entity there is no direct ability to modify its structure while for a lookup table the interaction with the structure becomes possible.

All the actions possible with the structure in any other data entity, such as adding Descriptions, Tags, Terms and Business Names can be performed both with Lookup Table itself and its columns also.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-110cb9ed2b46acd9043850780636f60891e6f0b7%2Fmedium-0-h2rguFN5wofjfp02.png?alt=media" alt="" height="352" width="700"><figcaption><p>Adding Descriptions, Tags, Terms and Business Names to Lookup Table itself and to its columns</p></figcaption></figure>

Also, the ID column, marked as the Primary Key, is automatically generated and cannot be modified. While the Primary key is currently unchangeable, there are plans for future developments that will enhance user experience by allowing interaction with it.

## Accessing Lookup Table data

Access to the data in the Lookup table is available by the distinct schema within PostgreSQL, and it can also be accessed via an API.

* **Access via an API** is currently considered not the most user friendly or recommended method, because with this access for example only column IDs are accessible and not their corresponding names. Nevertheless, assistance from our team is available to users in configuring access, ensuring that additional data can also be made available through the API in such cases. The full surface is documented at [API Reference → Reference Data](/developer-guides/api-reference/reference-data).
* **Direct database access** is the recommended path for downstream consumers (BI tools, ETL jobs, ad-hoc queries) that need the human-readable column names.

### Direct database access

For all of its features ODD Platform uses PostgreSQL database and PostgreSQL database only. Database connection defining block would look like this:

{% code title="YAML" overflow="wrap" %}

```yaml
spring.custom-datasource.url
#unset by default (@Value("${spring.custom-datasource.url:}")); falls back to
#spring.datasource.url, which itself defaults to jdbc:postgresql://127.0.0.1:5432/odd-platform
spring.custom-datasource.username
#unset by default; falls back to spring.datasource.username (default: odd-platform)
spring.custom-datasource.password
#unset by default; falls back to spring.datasource.password (default: odd-platform-password)
```

{% endcode %}

Within PostgreSQL, ODD Platform database comprises two primary schemas:

* **public** — this schema contains the essential resources of the ODD itself;
* **lookup\_tables\_schema** — this schema contains all the lookup tables created by the user.\
  Users can interact with these tables just like any other regular tables within the database.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-059de75aec2557c2fa63e9e5692b92963d181ce9%2Fmedium-1-bVtyoKbgeY83s0ixUADBrg.png.png?alt=media" alt="" height="155" width="700"><figcaption><p>ODD Platform database two primary schemas</p></figcaption></figure>

Placing them in a separate schema is a matter of convenience, aimed to simplify the management of these tables particularly during migration like activities. This approach ensures a clear separation between user tables and service tables, allowing for independent handling and manipulation.

## RBAC permissions

Lookup Table actions are gated by 9 permissions on three surfaces — table, definition (the column schema), and data (the rows). Assign these via the platform's [Policies](/configuration-and-deployment/enable-security/authorization/policies) and [Roles](/configuration-and-deployment/enable-security/authorization/roles) flow. The full permission list is regenerated from the OpenAPI spec under [Permissions](/configuration-and-deployment/enable-security/authorization/permissions); the rows specific to Lookup Tables:

| Permission                       | Surface              | What it gates                                                                                                     |
| -------------------------------- | -------------------- | ----------------------------------------------------------------------------------------------------------------- |
| `LOOKUP_TABLE_CREATE`            | Table                | Creating a new lookup table (the `+Add new` flow).                                                                |
| `LOOKUP_TABLE_UPDATE`            | Table                | Renaming a lookup table or editing its description.                                                               |
| `LOOKUP_TABLE_DELETE`            | Table                | Deleting a lookup table.                                                                                          |
| `LOOKUP_TABLE_DEFINITION_CREATE` | Definition (columns) | Adding a column to an existing table's structure.                                                                 |
| `LOOKUP_TABLE_DEFINITION_UPDATE` | Definition (columns) | Editing column metadata (rename, description, validation flags). The data type itself cannot be changed once set. |
| `LOOKUP_TABLE_DEFINITION_DELETE` | Definition (columns) | Deleting a column from the structure.                                                                             |
| `LOOKUP_TABLE_DATA_CREATE`       | Data (rows)          | Inserting a new row.                                                                                              |
| `LOOKUP_TABLE_DATA_UPDATE`       | Data (rows)          | Editing an existing row's cell values.                                                                            |
| `LOOKUP_TABLE_DATA_DELETE`       | Data (rows)          | Deleting a row.                                                                                                   |

**These nine permissions gate writes only, and they are global.** There is no read permission for Lookup Tables: every read and search endpoint (`GET` table / columns / rows, and search) requires only that the caller is authenticated, so any authenticated user can read every lookup table's structure and data regardless of who created it. The write permissions above are also global rather than per-table or per-owner — a holder of `LOOKUP_TABLE_DEFINITION_UPDATE` (or any other `LOOKUP_TABLE_*` permission) can act on **any** lookup table, not only ones they created. Multi-team deployments that need per-team isolation of lookup-table reads or writes must enforce it outside the platform's RBAC (network perimeter / ingress rules).

The split lets operators grant edit-the-data without grant-edit-the-schema (a typical pattern for steward-curated reference lists), or grant create-the-table without grant-fill-the-data.

## Known operator caveats

Six behaviours of the Lookup Tables surface are non-obvious from the UI alone. Each item below states what an operator might assume, what the platform actually does, and what to do today.

{% hint style="danger" %}
**`LOOKUP_TABLE_*` permissions are global — there is no per-table RBAC today.** All nine permissions in the table above are gated against the **table-class** as a whole, not against a specific lookup-table id. The platform's authorization rules apply a no-context resolver to every `/api/referencedata/table/*` endpoint — the table id in the URL is not passed to a per-table permission-scope extractor. Contrast with `DATA_ENTITY_*` and `TERM_*` permissions, which **do** use per-resource resolvers (a `DATA_ENTITY_TAGS_UPDATE` Policy can target one entity; a `TERM_UPDATE` Policy can target one term).

**Operator-visible consequence.** A Policy granting `LOOKUP_TABLE_UPDATE` (or any other `LOOKUP_TABLE_*`) to a role permits modifying / deleting **every** lookup table in the platform — regardless of how the Policy's Conditions are scoped. A user with `LOOKUP_TABLE_UPDATE` granted "for the Finance team's tables" can edit the Marketing team's tables and the Engineering team's tables identically. The Policy Conditions UI accepts per-table scoping; the runtime ignores it for this permission class.

**Mitigation today:** do not grant any `LOOKUP_TABLE_*` permission to roles that should be restricted to a subset of tables. Treat the nine permissions as a single "global lookup-table steward" cluster and assign them to a small set of trusted operators. Per-table RBAC is on the upstream roadmap; until it ships, the Policy-Condition UI's per-table affordance does not narrow these permissions.
{% endhint %}

{% hint style="info" %}
**Deleting a Lookup Table removes both halves — use the Master Data UI.** A Lookup Table is two linked objects: the platform-side registry row (in `public.lookup_tables`) and the backing PostgreSQL table (in `lookup_tables_schema`). Deleting it through the Master Data UI — or `DELETE /api/referencedata/table/{lookup_table_id}` — cleans up both: it drops the backing schema-side table and its sequences, then removes the registry row. There is no whole-entity catalog delete for a Lookup Table's parent (the `/api/dataentities/{data_entity_id}` path is read-only, and the entity detail page exposes no Delete action), so the catalog side cannot leave the backing table orphaned.
{% endhint %}

{% hint style="danger" %}
**Renaming a Lookup Table silently breaks every downstream BI / ETL pipeline that hardcoded the old name.** The page above documents the Original Name as the PostgreSQL table identifier — the "SQL-joinable schema-direct-access" contract on which BI / ETL integrations rely. Renaming the table through the platform UI (or the `PUT /api/referencedata/table/{id}` endpoint) issues `ALTER TABLE … RENAME TO` against the underlying PostgreSQL table; from the very next millisecond, queries against the old name return `relation "<old>" does not exist`. The platform does **not** create a PostgreSQL VIEW alias under the old name, does **not** issue a "rename-blocker" warning at the UI, and does **not** surface a list of downstream consumers before applying the change.

**Operator workflow.** Treat Lookup Table renames as a coordinated migration window: enumerate the downstream SQL references (BI dashboards, ETL DAGs, ad-hoc queries cached in tools like Hex / Metabase / dbt), rewrite each to the new name in lock-step with the rename, and avoid renaming Lookup Tables that are referenced by integrations you do not own. The same class of silent-default risk that previously affected attachment storage and the soft-delete TTL applies here — a default-shaped action with cascading-failure consequences.
{% endhint %}

{% hint style="warning" %}
**Lookup Table values, column names, and the table name itself are stored and rendered without escaping — treat the surface as trusted-input.** The platform's lookup-table value-validator returns input values verbatim and stores them unchanged. The same path is used for the table's display name, the column names entered on the Structure tab, and every per-row cell value entered on the Data tab. Rendering surfaces in the catalog UI display the stored text as HTML; pasting content from untrusted sources (an external spreadsheet, a webhook payload, a user-submitted form) can store an active payload that fires when another operator opens the table.

**Mitigation today.** Restrict Lookup Table editing to operators reviewing the source of every value they paste in — the same posture you would apply to any "free-text into the database" surface. Avoid bulk-importing values from external systems without a sanitisation pre-pass. If your deployment ingests Lookup Table content from external pipelines, gate that ingestion behind a sanitiser at the integration layer.
{% endhint %}

{% hint style="info" %}
**Where a Lookup Table's description appears.** The Description you enter when creating or editing a Lookup Table is shown on the table's catalog entity overview as the entity's **external (source) description**. A lookup table is treated as a source the platform auto-ingests into the catalog, so its description is the *source-provided* one; editing the Lookup Table's description updates what the overview shows.

The catalog entity also keeps its **own internal description**, edited directly on the overview via **About → Add info / Edit info** — the same flow as any other Data Entity, including `[[term]]` live links. The two are independent: the Lookup Table form drives the external (source) description, while the About editor drives the internal (catalog-curated) one. A future release may consolidate these into a single description.
{% endhint %}

## API reference

The full HTTP API for Lookup Tables is documented at [API Reference → Reference Data](/developer-guides/api-reference/reference-data) — 16 endpoints across four groups (Table CRUD, Column CRUD, Row CRUD, Search) under `/api/referencedata/`, plus the `LookupTableFieldType` mapping notes and the per-endpoint `LOOKUP_TABLE_*` RBAC gating that ties back to the [permissions table above](#rbac-permissions).

## Where to next

* [Master Data Management](/features/master-data-management) — the parent pillar landing; positions Lookup Tables within the broader MDM / Reference-Data Management surface and the Data Governance map.
* [Data Modelling](/features/data-modelling) — the sibling pillar for query examples and entity relationships.
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the canonical, regenerated-from-spec permission list (includes the 9 Lookup Tables rows above).
* [Configure ODD Platform](/configuration-and-deployment/odd-platform) — the Spring datasource keys (`spring.custom-datasource.*`) the platform uses for both its own metadata and the `lookup_tables_schema`.


# Data Quality

Catalog-side data-quality signals — test results from Great Expectations / dbt / odd-collector-profiler / custom frameworks, the cross-catalog Quality Dashboard, and dataset SLA statuses.

The **Data Quality** section of ODD Platform is the home for the catalog's correctness signals — test results pushed in from quality frameworks, the cross-catalog quality dashboard, and the operator-set dataset SLA statuses that downstream BI reports consume.

ODD covers Data Quality fully *as an aggregator*. Quality checks are not performed inside ODD Platform — the platform integrates with leading tools in the field and surfaces their results in one operator-friendly view. See the [Data Governance map](/introduction/main-concepts#data-governance-map) for the position of Data Quality among the other governance pillars.

Open it from the top-level navigation **Data Quality** tab (the catalog-wide dashboard) or from any data entity's **Test reports** tab (per-entity test results and SLA status).

## Subsections

* [**Test Results Import**](/features/data-quality/test-results-import) — how test results land in the catalog: push-client integrations with [Great Expectations](/integrations/integrations/odd-great-expectations) and [dbt](/integrations/integrations/odd-dbt), statistical profiles via [`odd-collector-profiler`](/integrations/integrations/odd-collector-profiler), and a custom-framework escape hatch via `POST /ingestion/entities`.
* [**Quality Dashboard**](/features/data-quality/dashboard) — the catalog-wide quality view at `/data-quality` — three breakdown rings (Table Health / Test Results / Monitored Tables), six anomaly-class metrics, and the per-side filter sets (tables vs tests).
* [**Dataset Quality Statuses (SLA)**](/features/data-quality/sla-statuses) — Minor / Major / Critical statuses on test results, the dataset-level aggregate SLA colour, and two endpoints for BI import: `/api/datasets/{data_entity_id}/sla_report` (the JSON report) and `/api/datasets/{data_entity_id}/sla` (a pre-rendered PNG badge).
* [**Test Run History**](/features/data-quality/test-run-history) — the per-test runs timeline (`/dataentities/{id}/history`) — every individual run, the `status_reason` diagnostic each upstream framework writes, status filter, infinite-scroll pagination, and the cross-owner read posture on `status_reason` text.

## Why this is a separate pillar

For how Data Quality relates to the other governance pillars (Data Discovery, Data Modelling, Master Data Management, Data Lineage, Data Glossary), see [Main Concepts → Data Governance map → Pillar differentiation](/introduction/main-concepts#pillar-differentiation) — the canonical home for the six-pillar framing. Quality is its own pillar because the correctness signal cuts across every catalogued dataset; this landing consolidates the three ways an operator interacts with it (ingest test results, view the catalog-wide dashboard, curate per-dataset SLA statuses for BI consumption).

## Where to next

* If you are connecting a quality framework into the platform → [Test Results Import](/features/data-quality/test-results-import).
* If you are auditing the catalog's overall quality posture → [Quality Dashboard](/features/data-quality/dashboard).
* If you are exposing dataset-level quality to BI reports → [Dataset Quality Statuses (SLA)](/features/data-quality/sla-statuses).
* For the data-quality-engineer use case end-to-end → [Visibility for Data Quality Engineer](/use-cases/use-cases/dq-visibility).
* For DQ-test-failed alerts and where they surface → [Alerting](/features/active-platform-features/alerting).
* For the broader catalog vocabulary → [Main Concepts](/introduction/main-concepts).


# Test Results Import

How DQ test results land in ODD — push-client integrations with Great Expectations and dbt, statistical profiles via odd-collector-profiler, and the custom-framework ingestion endpoint.

Monitor test suite results in ODD Platform without thinking about masking or removing sensitive data — your datasets do not migrate to your ODD Platform installation, the platform gathers test results only.

The platform ingests test results from four canonical paths today, plus a custom-framework escape hatch.

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-7feedef4fce3e6ba3603c34f71c114a095276cee%2Fdqtest.gif?alt=media)

## Great Expectations

Push-client integration via [`odd-great-expectations`](/integrations/integrations/odd-great-expectations). Add the action to your Great Expectations checkpoint configuration; on each validation run the action emits the validation results into ODD's Ingestion API. Test outcomes surface on the dataset's detail page **Test reports** tab and aggregate into the [Quality Dashboard](/features/data-quality/dashboard).

## dbt tests

Push-client integration via [`odd-dbt`](/integrations/integrations/odd-dbt). Run `dbt test` (or your normal `dbt build`); the adapter emits the test outcomes into ODD's Ingestion API. The same surface conventions as Great Expectations — per-dataset Test reports tab + dashboard aggregation.

## Statistical profiles via `odd-collector-profiler`

Pull-strategy collector that uses Capital One's [DataProfiler](https://github.com/capitalone/DataProfiler) under the hood. See [`odd-collector-profiler`](/integrations/integrations/odd-collector-profiler) for the adapter's per-source coverage. Profile results contribute to the platform's quality signal alongside framework-driven test outcomes — the dashboard renders them as part of the same anomaly-class breakdown.

## Custom frameworks

For frameworks not covered by an existing adapter, push results directly through the platform's [Ingestion API](/introduction/main-concepts#odd-specification) — the same contract every other producer uses. Author a small client that maps your framework's outcomes onto ODD's `DataEntityList` schema with the `DataQualityTest` and `DataQualityTestRun` entity types, and POST that payload to **`POST /ingestion/entities`**.

Do **not** send test results to `POST /ingestion/entities/datasets/stats` — that endpoint accepts a `DatasetStatisticsList` (per-column statistical profiles, the path the [`odd-collector-profiler`](/integrations/integrations/odd-collector-profiler) uses), not a `DataEntityList`. A `DataEntityList` posted there does not land as test results. See the specification's [Ingestion API documentation](https://github.com/opendatadiscovery/opendatadiscovery-specification/blob/main/specification/specification.md) for the wire contract.

## Where to next

* [Quality Dashboard](/features/data-quality/dashboard) — where ingested test results aggregate into the cross-catalog quality view.
* [Dataset Quality Statuses (SLA)](/features/data-quality/sla-statuses) — operator-set Minor / Major / Critical severities on test results, plus the BI-report SLA endpoint.
* [Visibility for Data Quality Engineer](/use-cases/use-cases/dq-visibility) — the end-to-end DQ-engineer workflow.
* [Alerting](/features/active-platform-features/alerting) — where DQ-test-failed alerts surface and how they route to operators.
* [`odd-great-expectations`](/integrations/integrations/odd-great-expectations), [`odd-dbt`](/integrations/integrations/odd-dbt), [`odd-collector-profiler`](/integrations/integrations/odd-collector-profiler) — the per-integration setup pages.


# Quality Dashboard

The catalog-wide Data Quality Dashboard at /data-quality — three breakdown rings, six anomaly-class metrics, and the per-side filter sets for tables and tests.

The **Data Quality Dashboard** at `/data-quality` is the catalog's cross-entity quality view. It builds on top of the test results imported through the [Test Results Import](/features/data-quality/test-results-import) paths — Great Expectations, dbt, `odd-collector-profiler`, and custom frameworks — and renders them as one operator-friendly summary.

Quality checks are not performed inside ODD Platform — the dashboard surfaces results from the integrated tools.

{% hint style="info" %}
**The dashboard is visible to every signed-in user.** The `/data-quality` route carries no per-permission gate, and the aggregate it reads requires only that the caller be authenticated — there is no dedicated data-quality permission. Every signed-in user therefore sees the catalog-wide health of every dataset; under [`auth.type=DISABLED`](/configuration-and-deployment/enable-security/authentication/disabled-authentication) the dashboard is open to anyone who can reach the platform. The filters narrow what *you* are looking at; they do not restrict what a given user is *allowed* to see. If the mix of failing datasets is itself sensitive in your deployment, put the platform behind a network perimeter rather than relying on a dashboard-level permission that does not exist.
{% endhint %}

![Data Quality dashboard — three pie charts at the top (Table Health 88 tables broken into Healthy / Warning / Error slices; Test Results Breakdown 335 tests broken by latest-run status; Monitored Tables 98 split into monitored / unmonitored) and a per-test-category matrix on the right showing per-anomaly-class counts. The left rail carries two filter sets — one for tables, one for tests.](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-3b08a272284b885c3cc70eb1cabae9fa7d4aa629%2Fdata-quality.png?alt=media)

## Three breakdown rings

The dashboard's hero row is three pie charts, each computed across the catalog at the time the page is loaded:

* **Table Health** — the count of tables broken down by their aggregate health status, rated by a **priority cascade**: the highest-severity latest-run status on any of a table's tests decides the table's slice. The UI labels four slices — a table is **Error** when at least one latest run is **failed**; **Warning** when at least one is **broken** (and none failed); **Unknown** when at least one is **unknown** (and none failed or broken); and **Healthy** when none of those apply — i.e. its tests' latest runs are only *success*, *skipped*, *aborted*, or *running* (a currently-running test does **not** degrade a table's health). Searching the dashboard for a "broken tables" count will not find that label — *broken* latest runs roll up into the **Warning** slice and *failed* into **Error**.
* **Test Results Breakdown** — the count of **tests by their latest run's status**, across the same status set as the per-test [Test Run History](/features/data-quality/test-run-history) filter (**Success**, **Failed**, **Skipped**, **Broken**, **Aborted**, **Running**, **Unknown**). A test's *latest* run includes an **in-flight** one: a test that is currently running counts under **Running** (the in-flight run becomes its latest run, then is replaced by the terminal status once it finishes). See the disclosure below — this is **not** a count of individual runs.
* **Monitored Tables** — the count of tables broken down by whether they are monitored (have at least one DQ test) or unmonitored.

The "Monitored vs Unmonitored" framing applies specifically to **Table-type datasets** — the catalog's primary tabular entities.

{% hint style="warning" %}
**Test Results Breakdown counts tests, not runs.** The "Test Results Breakdown" ring (and every per-category total on the right-side matrix) aggregates **distinct tests, each represented by its latest run only**. A test that has failed 100 times in a row contributes a single entry to the "failed" count — the dashboard shows **1 failed**, not **100 failed**. The underlying table (`data_entity_task_last_run`) carries one row per test, keyed by the test's identifier, holding only the most recent run's status.

This matters most for **compliance and audit** reading. "How many test failures last week" answered from this dashboard returns "how many tests are currently failing on their latest run" — a smaller and structurally different number. For the per-run history of any individual test (every run, all states), open the test's [Test Run History](/features/data-quality/test-run-history) page from the test's detail surface.
{% endhint %}

## Six anomaly-class metrics

The right-side matrix shows the breakdown of failures across the six anomaly classes the platform recognises. The cards are ordered **alphabetically by category name** — not by failure count, severity, or test volume. An operator opening the dashboard to find "which category is failing worst" must scan all panels; the panel order conveys nothing about quality. Each metric represents a dimension of data quality:

* **Assertion Tests** — validations or checks put in place to ensure that specific conditions or assertions about the data are met.
* **Column Values Anomalies** — irregularities or unexpected values in the data that deviate from a predefined set of acceptable or standard values.
* **Freshness Anomalies** — staleness signals — checking whether the data is up-to-date and falls within the acceptable time frame.
* **Schema Changes** — modifications in the structure or organization of the data, with a focus on monitoring whether the data schema remains consistent over time.
* **Unknown Category** — data placed into a category that was not foreseen or specified in the established data model or schema.
* **Volume Anomalies** — unexpected changes in the quantity or volume of data.

Each per-category total at the top of the card uses the same latest-run-only semantic as the headline Test Results Breakdown ring — see the disclosure above.

For each of these metrics the dashboard assigns statuses to the checks, distinguished by colors for better visualization:

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-69680bacd3b0253b48cc13f3a3da74a01821764c%2Fmedium-1-RUuCb6M9dZ87nfbtAgDT9Q.png.png?alt=media" alt="" height="74" width="700"><figcaption><p>Checks Statuses distinguished by colors</p></figcaption></figure>

## Monitored vs unmonitored portions

Beyond the per-anomaly breakdown, the dashboard reports what portion of data was monitored and what portion was skipped:

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-795ec8caf5138fccb83d6c98cb86fafc897b91ab%2Fmedium-1-mj70MWKM4Nb9VK43glP3tA.png.png?alt=media" alt="" height="496" width="413"><figcaption><p>Monitored / unmonitored tables portions</p></figcaption></figure>

This applies specifically to Table-type datasets — the catalog's primary tabular entities.

## Filtering

Filter the dashboard by five dimensions: **Namespace**, **Datasource**, **Owner**, **Owner title**, and **Tag**. The filters apply on **two separate sides**:

{% hint style="warning" %}
**The "Owner title" filter is the ownership role, not the dataset name.** The **Owner title** filter matches the [ownership title](/configuration-and-deployment/enable-security/authorization/owners) — the role attached to an owner of an entity, such as `Steward`, `Subject Matter Expert`, or `On-call` — **not** the name of a dataset. Selecting `Owner title = Steward` narrows the rings to entities that have an owner holding the `Steward` role, which is a wider and different slice than "datasets called X." There is no filter for the dataset name on this dashboard; use [Search](/features/data-discovery/search) when you need to find a named entity.

**Owner and Owner title combine into a single owner match.** When you select **both** an **Owner** and an **Owner title**, the dashboard matches only entities where **that owner holds that title** on the entity (the two conditions are intersected on the same ownership row), not entities that have that owner *and*, separately, someone with that title. A combination no single owner satisfies returns an empty ring.

**"Namespace" includes the datasource's namespace.** The **Namespace** filter matches an entity when **either** the entity's own namespace **or** the namespace of its datasource is the one you selected. An entity inherits its datasource's namespace for this filter even if the entity itself was ingested into a different namespace, so the ring counts can be larger than a "entities whose namespace is X" query run elsewhere would return.
{% endhint %}

* **Tables-side filters** — narrow the Table Health and Monitored Tables rings to the selected slice of tables.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-e3464068a7d46f659c6fb1ac14083a55537cd5f2%2Fmedium-1-E08rxeOS82YXQf3bg0B1Gg.png.png?alt=media" alt="" height="374" width="700"><figcaption><p>Filters for tables</p></figcaption></figure>

* **Tests-side filters** — narrow the Test Results Breakdown ring to tests with the selected attributes.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-2cfb8f956674224a2784b5c807ac754a982bbcbb%2Fmedium-1--w027JpdmXoJci9NsO6imw.png.png?alt=media" alt="" height="385" width="700"><figcaption><p>Filters for tests</p></figcaption></figure>

The two filter sets are independent — you can hold the tables-side filter at one slice and the tests-side at another, which is useful when reasoning about test coverage across a slice of tables.

ODD users can narrow down test results for datasets by multiple attributes simultaneously.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-dd2cdb804cceed12dce5a11add5283b03c6df7cb%2Fmedium-1-IJO4MrByO-Nww0AEeUbuuQ.png.png?alt=media" alt="" height="460" width="700"><figcaption><p>Filtering by multiple attributes simultaneously</p></figcaption></figure>

{% hint style="info" %}
**`AND`-only conjunction.** For simplicity the platform implements only one logical conjunction across filter dimensions — `AND`. The results displayed after filtering are the outcome of all selected filters intersected together.
{% endhint %}

{% hint style="warning" %}
**Filter selections are page-session state — they survive only if the URL survives.** The dashboard's filter state lives **per page mount**: selecting filters writes them to the URL query string in real time (a `replace` URL update, so the browser history isn't polluted), and re-opening the page re-reads the filters from that URL. The persistence is therefore tied to the URL, not to your session.

In practice:

* **Browser back** — preserves the URL → filters reconstruct correctly. Pick filters, drill into an entity, hit back, the filter row is the same.
* **Bookmarked or shared URL** — a `/data-quality?...` URL with filter parameters is a portable snapshot. Open it from a bookmark or paste it to a teammate; they land on the same filter set.
* **Clicking "Data Quality" in the top navigation** — that link points at bare `/data-quality` with no query string, so the page reopens with **all filters empty**. The most common surprise: you set up filters, navigate away through the top nav, click "Data Quality" again, and your selection is gone.
* **Re-opening the dashboard from another part of the catalog** — same as the top-nav case: unless you arrive via a URL that carries the filter parameters, the filter row starts empty.

The pattern (filter / cursor state resets when you leave the page through anything that doesn't preserve the URL) applies to a few other catalog surfaces — Owner Associations in Management, the DEG (Data Entity Group) lineage canvas, and the Dataset Structure compare view — but the Data Quality Dashboard is where most operators meet it first. To pin a working view, copy the URL from the address bar and bookmark or share it.
{% endhint %}

## Where to next

* [Test Results Import](/features/data-quality/test-results-import) — how the test results that populate the dashboard land in the catalog.
* [Dataset Quality Statuses (SLA)](/features/data-quality/sla-statuses) — operator-set severities on test results that feed the dataset-level SLA.
* [Alerting](/features/active-platform-features/alerting) — DQ-test-failed alerts feeding through the alert lifecycle.
* [Visibility for Data Quality Engineer](/use-cases/use-cases/dq-visibility) — the dashboard in the context of the DQ-engineer end-to-end workflow.


# Dataset Quality Statuses (SLA)

Operator-set Minor / Major / Critical severities on dataset test results, the dataset-level aggregate SLA colour, and the /sla (PNG) and /sla\_report (JSON) endpoints for BI import.

Mark the importance of each test on a dataset using **Minor**, **Major**, and **Critical** severities. The platform aggregates those severities together with the test pass / fail counts into a single dataset-level **SLA colour** (Green / Yellow / Red) that downstream BI reports can import directly.

## Setting severities

Severities are operator-set — the platform does not infer them.

1. Open the dataset's main page and select the **Test reports** tab.
2. Click on a job (a test result row) and, in the right-side panel, choose a severity — Minor, Major, or Critical — then confirm the change in the dialog that appears. The severity is only saved once you confirm; the panel always shows the test's stored severity until then.

Severities apply per-test, not per-dataset; one dataset can carry tests at all three severities. Each test's severity together with whether the latest run passed feeds the dataset's aggregate SLA colour.

## Importing SLA into BI reports

Each dataset exposes its current aggregate SLA through **two endpoints** — one returns a pre-rendered PNG badge, the other returns the structured JSON report. Use whichever fits your BI tool's integration model.

| Endpoint                                        | `Content-Type`     | Use for                                                                                                                                                                                                                                                                                      |
| ----------------------------------------------- | ------------------ | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `GET /api/datasets/{data_entity_id}/sla`        | `image/png`        | A pre-rendered PNG badge (1–2 KB). Suitable for BI tools that can embed an image URL directly (Confluence macros, Notion image embeds, Excel `IMAGE()` formula, Looker / Tableau image tiles).                                                                                               |
| `GET /api/datasets/{data_entity_id}/sla_report` | `application/json` | The structured `DataSetSLAReport` — current SLA colour (`GREEN` / `YELLOW` / `RED`), severity-weights breakdown, and a `sla_ref` self-link. Use this when your BI tool parses JSON (BI dashboards that compute their own visualisation, custom report pipelines, internal-tools dashboards). |

In both cases `{data_entity_id}` is the numeric ID of the dataset's data entity — the same ID that appears in the dataset's catalog URL.

**Choosing between the two:** if your destination renders an image natively, the `/sla` PNG is one HTTP call and zero parsing. If your destination needs the underlying numbers (per-severity counts, severity-weights breakdown), the `/sla_report` JSON is the only path — the PNG does not carry the structured data.

## How the SLA colour is computed

The SLA colour is **not** a direct severity-to-colour mapping — it is computed across the dataset's tests by `SLACalculator` based on which severities have failing tests:

* **Red** — at least one Critical test is failing, OR all Major-severity tests are failing, OR a particular all-but-one-Major-failing-and-all-Minors-failing pattern.
* **Yellow** — some Major tests failing (but not all), OR all Minor tests failing, OR no tests at any severity defined yet (the platform errs cautious when nothing is defined).
* **Green** — none of the above; passing tests dominate at every severity.

So changing a single test's severity from Major to Critical can flip the dataset from Yellow to Red without any test pass / fail status changing. Use severities to encode "how loud should this dataset's failure be" rather than as a labelling exercise.

## Known operator caveats

{% hint style="warning" %}
**Tests without an operator-set severity contribute to the SLA aggregate as Major.** The platform's mapper returns `MAJOR` as the default severity for any test row that has no explicit entry in the severity table. An operator who never opens the Test reports tab to set severities, or one who relies on the page's "severities are operator-set — the platform does not infer them" framing literally, still has every test contributing to the SLA — at `MAJOR` weight. A dataset with 100 unset-severity tests and 1 Critical-failing test renders **Red**, not because of the one Critical test alone but because the 100 default-Major tests count against the SLA aggregate. To exclude tests from the SLA aggregate, mark them `Minor` (or wait for the upstream `severity_source` discriminator that would separate operator-set values from defaults).
{% endhint %}

{% hint style="warning" %}
**The four DQ read endpoints behind this page are reachable to any authenticated user — there is no per-owner gate.** `GET /api/datasets/{data_entity_id}/dataqatests`, `GET /api/datasets/{data_entity_id}/test_report`, `GET /api/datasets/{data_entity_id}/sla`, and `GET /api/datasets/{data_entity_id}/sla_report` are not enumerated in the platform's authorization rules; the catch-all "any authenticated user" rule covers them. Authenticated callers under `LOGIN_FORM` / `OAUTH2` / `LDAP` read every dataset's DQ tests and SLA regardless of dataset ownership. Multi-team deployments that require per-team DQ-result isolation must enforce it at the network perimeter (reverse proxy rules, ingress filtering) or rely on the existing `DATASET_TEST_RUN_SET_SEVERITY` permission to gate writes only — the read side is not configurable in the platform's RBAC today.
{% endhint %}

{% hint style="warning" %}
**Severity changes are not logged in the Activity Feed today.** Changing a test's severity through the Test reports tab or the API gates on the `DATASET_TEST_RUN_SET_SEVERITY` permission but does **not** emit an Activity Feed event, does not stamp `last_modified_by` on the row, and does not version the prior severity. The SLA colour flip is observable downstream (in the platform UI and in BI tools embedding the colour through the endpoints above), but the platform-side signal of *who* triggered it is unavailable without direct database inspection. Compliance and audit workflows depending on SLA-colour history must instrument severity changes externally until the upstream activity-event emission ships. The wider audit-scope picture and the compensating controls operators can apply are documented on the [Audit trail scope](/configuration-and-deployment/enable-security/audit-trail-scope) page.
{% endhint %}

## Where to next

* [Test Results Import](/features/data-quality/test-results-import) — how the test results that the SLA aggregates land in the catalog.
* [Quality Dashboard](/features/data-quality/dashboard) — the catalog-wide quality view that surfaces test outcomes alongside the per-dataset SLA.
* [Alerting](/features/active-platform-features/alerting) — DQ-test-failed alerts (which fire on the test-result event the SLA also consumes).
* [Visibility for Data Quality Engineer](/use-cases/use-cases/dq-visibility) — the DQ-engineer use case end-to-end.


# Test Run History

Per-test history of every individual run — every status, every duration, every status-reason diagnostic. The drill-in counterpart to the Quality Dashboard's tests-by-latest-status summary.

The Test Run History surface lists **every individual run** of a single Data Quality test — the full timeline of pass / fail / skip / abort / broken outcomes, the upstream framework's `status_reason` diagnostic text on each run, and the per-run start time, end time, and duration. It is the drill-in for any test where the catalog-wide [Quality Dashboard](/features/data-quality/dashboard)'s tests-by-latest-status summary is not enough — the dashboard tells you a test is currently failing; this surface tells you *how many times in a row*, *when each failure happened*, and *what the upstream framework reported as the reason*.

## Where to find it

Two places surface per-run history:

* **`/dataentities/{id}/history` — full history with infinite scroll.** Open a Quality Test entity's detail page and navigate to the **History** tab. The list shows every run, paginated **100 at a time**, ordered most-recent-first. A status filter at the top of the table narrows the list to a single status (Show all statuses, Success, Failed, Skipped, Broken, Aborted, Running, Unknown).
* **The first 10 runs as a preview on `/test-report`.** A Quality Test's main report surface includes a recent-runs strip — the same endpoint, scoped to the first 10 runs. Use it as a quick "did this test just flip" glance; use the History tab for everything else.

The History tab is **hidden when the test entity's status is `DELETED`** — the route redirects to the entity's Overview. Restore the entity via the status badge to access its run history (see [Data entity statuses](/features/data-discovery/statuses)).

## The endpoint

Both UI surfaces consume the same endpoint:

```
GET /api/dataentities/{data_entity_id}/runs?page={page}&size={size}&status={status}
```

| Parameter        | Required | Notes                                                                                                                           |
| ---------------- | -------- | ------------------------------------------------------------------------------------------------------------------------------- |
| `data_entity_id` | yes      | The Quality Test's data-entity id (numeric). The same id that appears in the test's catalog URL.                                |
| `page`           | no       | 1-based page number. Defaults to the platform's standard pagination default if omitted.                                         |
| `size`           | no       | Page size. The UI passes `100` on `/history` and `10` on `/test-report`.                                                        |
| `status`         | no       | One of `SUCCESS` / `FAILED` / `SKIPPED` / `BROKEN` / `ABORTED` / `RUNNING` / `UNKNOWN`. Omit (or pass `null`) for all statuses. |

The response is a `DataEntityRunList` — a `PageInfo` (`total`, `hasNext`) plus an `items` array of `DataEntityRun` objects (each carrying `id`, `oddrn`, `startTime`, `endTime`, `status`, `statusReason`).

`status_reason` is a free-form string that the upstream DQ framework — Great Expectations, dbt, `odd-collector-profiler`, or any custom framework that pushes to the [Test Results Import](/features/data-quality/test-results-import) endpoint — populates. Common framework behaviour: Great Expectations writes a JSON summary of the failed expectation including a sample of failing rows; dbt writes the failing test's compiled SQL and the row count above the threshold; `odd-collector-profiler` writes the metric and the observed value. The platform does not enforce a schema on this field — it is rendered verbatim on the History tab as the "Status reason" column.

## Sort, pagination, status filter

The list is sorted with **in-flight (currently-running) runs first**, then completed runs **most-recent-first by end-time**. An in-flight run has no end time yet, so it sits at the top — the freshest activity — marked with a **`running`** status badge; multiple in-flight runs order by start time, newest first. The order is fully deterministic (a final tiebreaker on run id), so the server-side, infinite-scroll list never drops or repeats a row across page boundaries; the `/history` tab calls the next page when the user scrolls to the end of the visible rows.

The status dropdown above the list is independent of the search facets used on the Catalog page; it only narrows the runs on this test. Selecting a status fires a new request with the `status` query param.

## Known limitations and operator caveats

A few behaviours on this surface are non-obvious from the UI alone. Each item below states what an operator might assume, what the platform actually does, and what to do today.

{% hint style="warning" %}
**The endpoint is reachable to any authenticated user — there is no per-owner gate on read.** `GET /api/dataentities/{id}/runs` is not enumerated in the platform's authorization rules; the catch-all "any authenticated user" rule covers it. Authenticated callers under `LOGIN_FORM`, `OAUTH2`, or `LDAP` read every Quality Test's full run history regardless of dataset ownership; under `auth.type=DISABLED` the same reads are reachable anonymously.

**This matters for the `status_reason` field specifically.** The free-form diagnostic text upstream DQ frameworks emit on failure routinely contains team-confidential information:

* Great Expectations writes **samples of failing data values** into the failed-expectation summary (a row's PII column value, a customer id, a transaction amount).
* dbt writes the **failing test's compiled SQL**, which exposes column names, table names, and the test thresholds.
* Custom-framework pipelines often append free-form text — internal table aliases, environment identifiers, ticket numbers.

In a multi-tenant deployment, any signed-in user from one team reads every other team's per-run diagnostic text indefinitely (run history is retained at least as long as the underlying test entity exists). Operators planning for cross-team data-shape isolation should treat `status_reason` as a **catalog-read-collaborative** field — same posture as Owner / Namespace / Datasource directories — and either configure upstream DQ frameworks not to emit failing-row samples (the GE / dbt / profiler configuration knobs are framework-side; consult their docs), or enforce isolation at the network perimeter (reverse-proxy rules on `/api/dataentities/*/runs`). The platform's RBAC layer does not gate this read today.
{% endhint %}

{% hint style="info" %}
**In-flight (currently-running) runs appear at the top of the list, marked `running`, with an empty Duration.** A run that has started but not finished has the `RUNNING` status and no `end_time`. The platform sorts in-flight runs to the **top** — they are the freshest activity — and the History tab renders each with a **`running`** status badge, so the in-flight state is unambiguous. The Duration column (computed from `endTime - startTime`) stays empty until the run finishes; when it completes, the row gains an end time and a terminal status (Success / Failed / …) and re-sorts into the completed timeline by end-time.

Before 0.29.0 a `RUNNING` row instead made this endpoint return HTTP 500 — the page was unavailable exactly while a test was in flight — and in-flight rows looked "undated". Both are fixed in 0.29.0: `RUNNING` is a first-class status that the API serialises and the UI renders.
{% endhint %}

## Where to next

* [Quality Dashboard](/features/data-quality/dashboard) — the catalog-wide tests-by-latest-status summary that this page drills into.
* [Dataset Quality Statuses (SLA)](/features/data-quality/sla-statuses) — operator-set severities on test results that feed the dataset-level SLA colour; the History page is where you would investigate why a given test's latest run drove the SLA flip.
* [Test Results Import](/features/data-quality/test-results-import) — the push-client integrations (Great Expectations, dbt, `odd-collector-profiler`, custom frameworks) that produce the runs surfaced on this page.
* [Alerting](/features/active-platform-features/alerting) — DQ-test-failed alerts (the alert lifecycle that fires on the same run-completed event the History page reads from).
* [Activity Feed](/features/active-platform-features/activity-feed) — the audit trail of every test-result import that this History list reflects.


# Data Lineage

Top-level UI section for upstream / downstream lineage across the ODD entity model — both data-object lineage and microservices-tracing lineage.

The **Data Lineage** section of ODD Platform is the home for upstream and downstream traceability across the catalog. The role is durable: anything that documents *how entities are connected* — which dataset was read by which job, which job produced which model, which microservice traced which call — belongs here.

ODD covers Data Lineage fully and across two complementary surfaces — **data-object lineage** (catalog entities and the edges between them) and **microservices lineage** (OpenTelemetry-traced microservice calls rendered alongside the data graph). See the [Data Governance map](/introduction/main-concepts#data-governance-map) for the position of Data Lineage among the other governance pillars.

Open lineage from the **Lineage tab** on any data-entity detail page (per-entity view) or from the **Group lineage** entry point on a [Data Entity Group](/features/data-discovery/groups-domains) detail page. The microservices view is reached from any catalogued microservice entity ingested through [`odd-tracing-gateway`](/integrations/integrations/odd-tracing-gateway).

Both canvases expose a Compact / Full view-mode toggle — same label, two subsystem behaviours; the [data-objects sub-page](/features/data-lineage/data-objects#view-mode-toggle-compact--full) describes the asymmetry and the dense-graph caveat. The same sub-page also covers the **UI-vs-API depth contract** every direct-API caller should read before scripting lineage queries — the canvas's 1-20 depth dropdown is a UI presentation choice; the URL and the API accept any positive integer with no upper bound.

## Subsections

* [**Data Objects Lineage**](/features/data-lineage/data-objects) — per-entity upstream / downstream graphs across the full ODD entity model: datasets, transformers, transformer runs, quality tests + their runs, consumers, data inputs, data entity groups (including ML experiments), and entity relationships. Backed by the split per-entity endpoints `GET /api/dataentities/{data_entity_id}/lineage/upstream` and `GET /api/dataentities/{data_entity_id}/lineage/downstream`, plus the dedicated group-lineage endpoint `GET /api/dataentitygroups/{data_entity_group_id}/lineage`.
* [**Microservices Lineage**](/features/data-lineage/microservices) — microservice call lineage rendered alongside data-object lineage. Sourced from OpenTelemetry traces ingested via `odd-tracing-gateway` (the platform's only [standalone gateway](/introduction/main-concepts#the-architecture-chain) push adapter today).

## Why this is a separate pillar

For how Data Lineage relates to the other governance pillars (Data Discovery, Data Modelling, Master Data Management, Data Glossary, Data Quality), see [Main Concepts → Data Governance map → Pillar differentiation](/introduction/main-concepts#pillar-differentiation) — the canonical home for the six-pillar framing. Lineage is its own pillar because the connection graph cuts across every other pillar; a dataset has a structure, a meaning, a location, a quality signal, *and* a lineage, and the lineage itself is the cross-pillar record.

## My-objects triplet — composition + anchor architecture

Three lineage-adjacent endpoints answer the operator question *"what do I own, what flows into it, what flows out of it"* as a unified triplet:

| Endpoint                              | What it returns                                                                                 |
| ------------------------------------- | ----------------------------------------------------------------------------------------------- |
| `GET /api/dataentities/my`            | The entities the signed-in user owns (the **anchor set**).                                      |
| `GET /api/dataentities/my/upstream`   | The set of entities that the user's owned entities **depend on** but the user does **not** own. |
| `GET /api/dataentities/my/downstream` | The set of entities that **depend on** the user's owned entities but the user does **not** own. |

The two `*upstream` / `*downstream` endpoints are not "my owned entities + their upstream" — they are explicitly **the non-owned set adjacent to the user's owned entities** (lineage neighbours minus the anchor). The UI labels the surfaces accurately as *"Upstream dependents"* / *"Downstream dependents"* — the dependents on the user's stuff, not the user's stuff.

{% hint style="danger" %}
**The OpenAPI summary on the upstream / downstream operations describes the wrong shape.** The spec text for `getMyObjectsWithUpstream` and `getMyObjectsWithDownstream` currently reads *"Returns list of data entities owned by current user with upstream dependencies"* — implying the response is your owned set with extra context. The actual response is the **NON-owned set adjacent to your owned entities** (the lineage neighbours, with the owned anchor explicitly excluded).

Third-party API consumers compiling SDKs from `openapi.yaml` will get the wrong mental model. SDK code that treats the response as *"my entities"* will silently mis-attribute lineage neighbours to the caller. Until the spec is corrected, **follow the UI label semantic** (*"Upstream dependents"* / *"Downstream dependents"*) when integrating these endpoints — they are dependency graphs around the caller's owned set, not the caller's owned set itself.
{% endhint %}

### Anchor architecture and operator caveats

A handful of architectural details on the triplet matter when reasoning about exposure, performance, and debugging:

{% hint style="warning" %}
**Owner-scoping is enforced at exactly one site — the lineage projection downstream has no defence-in-depth.** The triplet's owner filter runs at the anchor-fetch step (the platform resolves the signed-in user to their bound Owner and looks up the entities that Owner owns). From that point onward the lineage CTE has **no ownership join** and the final projection (`listByOddrns`) is a pure `WHERE oddrn IN (...)` scan against the anchor set with no per-owner predicate. The base `/api/dataentities/my` endpoint **does** join the ownership table; the triplet's upstream / downstream endpoints do **not**.

Today's code is correct — the anchor set IS the operator's owned set, so the lineage walk around that set is genuinely the caller's neighbourhood. The architectural caveat is that **a regression at the anchor-fetch step has catastrophic blast radius**: a misordered web filter dropping the security context, a typo in the user-owner-mapping resolver, or a fallback that defaults to an unintended owner under `auth.type=DISABLED` would silently return a different owner's lineage neighbourhood. The repository tier does not catch the mistake — there is no JOIN-side check that says "the anchor must match the caller." Combined with the [cross-mode user-name collision](/configuration-and-deployment/enable-security/authentication/login-form) on `USER_OWNER_MAPPING.OIDC_USERNAME`, a multi-mode deployment with a name collision is one regression away from cross-owner lineage neighbourhood leak. Audit attention belongs at the anchor-fetch site (`fetchAssociatedOwner`) — it is the single load-bearing line.
{% endhint %}

{% hint style="warning" %}
**The endpoint fetches the full owned set before applying pagination — admin / CI-bot owners trigger O(anchor) DB cost on every call regardless of `size`.** The triplet builds the upstream / downstream query by first calling `listByOwner(ownerId)` (which returns **all** entities the owner owns, no pagination) and then constructing a CTE with `WHERE child_oddrn IN (oddrn1, oddrn2, ...)` over the full anchor set. Memory and database CPU scale with the **size of the owned set**, not with the requested page size. PostgreSQL's planner cost is non-linear above \~1000 IN-clause elements; the jOOQ query does not paginate the IN clause.

**Operator-visible consequence.** An admin owner who owns thousands of catalogued entities (a CI-bot account that gets default-owner-assigned on every ingestion, an admin who became the owner of everything during initial setup) triggers a heavy query on every `/my/upstream` or `/my/downstream` call — even when the UI requests `size=5`. The Recommended panel on the Catalog Overview home page fires these endpoints on every SPA mount, so the cost is per-user-pageload, not per-explicit-API-call. **Operationally bound the owned set** — avoid making admin accounts the owner of all entities; use a service-account pattern for ingestion-time auto-owner assignment; consider a small dedicated owner per team rather than a single platform-wide steward.
{% endhint %}

{% hint style="info" %}
**An empty response (`HTTP 200` with `[]`) on the triplet is indistinguishable across four root causes.** The triplet does not signal which condition produced the empty response:

* No `USER_OWNER_MAPPING` row for the caller — the platform cannot resolve an Owner; the anchor set is empty.
* A bound Owner exists but owns zero entities — the anchor set is genuinely empty.
* Owned entities exist but they have no upstream / downstream lineage edges — the neighbourhood is empty.
* No security context (anonymous call under `auth.type=DISABLED`) — the anchor-fetch resolves to no Owner.

All four return the same `200 OK` body. When troubleshooting an empty triplet response, cross-check `/api/identity/whoami` (auth state — distinguishes the no-security-context case) and `/api/dataentities/my` (owned set — distinguishes the empty-anchor cases from the empty-neighbourhood case) before concluding "no lineage exists."
{% endhint %}

## Read posture across the catalog

Lineage on every catalogued entity — datasets, transformers, consumers, microservices, Data Entity Groups — uses the platform's read-collaborative posture. Any authenticated user with read access to the catalog can request the upstream / downstream graph of any catalogued entity, regardless of which team owns the underlying object. The lineage repository does not apply an ownership-side filter on the read path; the group-lineage endpoint exposes the full child-set under its parent group; the microservices lineage surface exposes the full call graph between catalogued services.

This matters most for **multi-team deployments** that expect per-team isolation on lineage reads — they don't get it from the platform's RBAC today. The mitigations are platform-wide and live on the [Authorization](/configuration-and-deployment/enable-security/authorization) subtree: scope the catalog deployment per team, or restrict who has authenticated access to it. Microservice lineage is the highest-sensitivity surface in this class because operational call patterns are more topology-revealing than schema-lineage edges (see [Microservices Lineage → Access model](/features/data-lineage/microservices#access-model)).

## Where to next

* If you want to trace upstream / downstream from a specific catalogued entity → [Data Objects Lineage](/features/data-lineage/data-objects).
* If you ingest microservices through OpenTelemetry traces and want to see them alongside your data graph → [Microservices Lineage](/features/data-lineage/microservices).
* For the Lineage HTTP API (per-entity, group-level, and microservices) → [API Reference → Lineage](/developer-guides/api-reference/lineage).
* For the broader catalog vocabulary (Data Entity, ODDRN, Plugin, Push adapter) → [Main Concepts](/introduction/main-concepts).
* For where Data Lineage sits among the other governance pillars → [Main Concepts → Data Governance map](/introduction/main-concepts#data-governance-map).


# Data Objects Lineage

Per-entity upstream / downstream lineage across the full ODD entity model, plus the dedicated group-lineage endpoint for Data Entity Groups and ML experiments.

ODD Platform renders upstream and downstream lineage across the full ODD entity model — not just datasets. Every data-entity class participates: datasets and views, transformers (ETL jobs, ML training jobs, microservices), transformer runs, data quality tests and their runs, consumers (BI dashboards, ML model artifacts), data inputs (API calls), data entity groups (including ML experiments), and entity relationships. See the [ODD Data Model](https://github.com/opendatadiscovery/opendatadiscovery-specification/blob/main/specification/specification.md#data-model-specification) for the canonical class reference.

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-ee3eba175ee95eb7d6aa8384d48d5795c0757e8e%2Flineage.gif?alt=media)

## Where to find it in the UI

* **Lineage tab** on any data-entity detail page — opens the entity-centric graph with the entity at the centre and configurable upstream / downstream depth.
* **Group lineage** entry point on a [Data Entity Group](/features/data-discovery/groups-domains) detail page — opens the lineage of the group's *children*, not of the group itself (see below).

The graph supports pan, zoom, and on-click expansion of intermediate nodes; the per-entity depth and pre-expanded nodes are controlled by query parameters (next section).

## Query parameters

The per-entity lineage graph is parameterised by two optional query parameters — `lineage_depth` (the number of upstream / downstream hops to walk by default) and `expanded_entity_ids` (entities to expand inline rather than show as collapsed neighbour stubs). Types, defaults, and when to set each are documented at [API Reference → Lineage → Per-entity lineage](/developer-guides/api-reference/lineage).

{% hint style="info" %}
**Keep `expanded_entity_ids` lists short.** The platform places no upper bound on the number of ids you pass, but the ids go straight into a single database query as bound parameters. A very long list (low thousands and up) can exceed Postgres's bound-parameter limit for one statement and fail the request. The UI only ever expands the handful of groups a user has clicked, so this is a direct-API concern — expand in batches rather than passing thousands of ids at once.
{% endhint %}

## View-mode toggle (Compact / Full)

The lineage canvas exposes a Compact / Full view-mode toggle. The control is one label, but the two surfaces it appears on (Data Entity Group lineage and per-entity Hierarchy lineage) implement it differently:

* **On the Data Entity Group canvas** — flipping the toggle triggers a **layout re-run**. The graph briefly shows a loading spinner; nodes animate from their old positions to the new ones. The DEG-side layout engine recomputes from scratch.
* **On the per-entity Hierarchy canvas** — flipping the toggle is a **re-render only**, not a re-layout. The hierarchy renderer changes per-node size but keeps existing positions. The visible effect is an instant shape change, not an animation.

The same control, two observable behaviours — your mental model from one canvas does not transfer to the other.

{% hint style="warning" %}
**On a dense Hierarchy graph, switching modes can produce visual overlap.** Because the Hierarchy re-render keeps positions static while node size changes, dense graphs (many siblings at the same depth) can end up with nodes overlapping after the switch. Use Full mode for dense graphs, or expand sub-trees individually rather than toggling at the top level.
{% endhint %}

**Compact mode hides the DEG-Items button in the Hierarchy canvas.** When the per-entity canvas renders a [Data Entity Group](/features/data-discovery/groups-domains) node and the canvas is in Compact mode, the **DEG-Items** button (the entry point to drill into the group's members) is **hidden**. The drill-in affordance is silently lost; operators wanting to see a DEG node's members from the Hierarchy canvas must switch to **Full** mode (or use the per-entity Overview → Members surface). The trade-off is invisible until you try to click the affordance.

## Lineage depth — UI control vs API contract

The Hierarchy canvas's depth dropdown ranges from **1 to 20**. That dropdown is a UI-presentation choice — it is **not** the platform's contract.

* The UI always **sends `lineage_depth=1`** on the initial entity-lineage fetch and on the per-canvas "Load more" affordance, so this next point never bites a UI user. Direct API callers (curl / SDK / Swagger UI) may omit the parameter: the OpenAPI spec declares `default: 1`, so an omitted `lineage_depth` returns the same single-hop graph the UI requests by default. (Before `0.29.0` the per-entity endpoints had no default and an omitted value returned **HTTP 500** from a `NullPointerException`; that is fixed — #1758.)
* The URL query parameter `?d=` is parsed as a number and forwarded **unclamped**. Manually editing the URL to `?d=10000` (or pasting a URL from a colleague that already has `?d=50`) triggers a 10000-depth / 50-depth recursive walk against the platform's lineage CTE — the dropdown's 20-entry array is never consulted.
* The controller carries `@Min(1)` validation but **no `@Max`**; the service tier hands the integer through unchanged; the repository tier consumes it directly as the CTE termination predicate. Four layers, only one validates the lower bound; none validates the upper bound.

**Operator-visible consequence.** Two patterns produce arbitrarily-deep walks without the operator touching the dropdown:

1. **Click-through depth compounding.** Clicking a graph node title navigates to the new lineage view with `?d` set to **that node's distance from the current root**. Drill five hops into a graph, click a leaf, and the new view fetches lineage to depth = 5 around that leaf. Postgres CPU correlates with user clicks, not with the depth slider.
2. **URL-edited depth bypassing the cap.** If `?d=N` (N > 20) is present in the URL when the user clicks a node, the click-through propagation preserves `N` — the dropdown is never consulted on propagation. The dropdown's 20-entry array is a one-time guard at first-paint only.

What the operator-visible knob looks like and what the system actually accepts are not the same control. Tune Postgres for the platform expecting deep-walk traffic from casual canvas clicks, not only from manual depth-slider use.

{% hint style="warning" %}
**A deep walk is a memory- and CPU-amplification risk, not just a slow query.** The lineage walk is a recursive Postgres CTE whose **only** stop condition is the depth bound — there is **no cycle guard**. On cyclic or diamond-shaped graphs (the same node reachable by several paths) the recursion re-expands the same nodes at each level, inflating intermediate rows before the final de-duplication. The platform then loads the **entire** result graph into the application's memory at once before sending the response. A large `lineage_depth` against a branchy graph can therefore spike both Postgres CPU and platform heap well beyond what the row count of the final graph suggests. Keep `lineage_depth` as low as the task allows, and size both Postgres and the platform's JVM heap for the deepest walks your operators can trigger.
{% endhint %}

## Group lineage

The dedicated lineage endpoint for [Data Entity Groups](/features/data-discovery/groups-domains) (including [ML experiments](/features/data-discovery/groups-domains#relationship-to-ml-experiments) and other logical containers) returns the lineage graph for the group's *children* rather than for the group itself. Operationally: a Finance DEG containing fifteen datasets and three ETL jobs returns the lineage union across those eighteen child entities, which is what an operator usually wants when reasoning about a domain or pipeline. The endpoint is documented at [API Reference → Lineage → Group lineage](/developer-guides/api-reference/lineage).

The group-lineage endpoint's request contract is **narrower** than the per-entity endpoints' — it carries only the path parameter (no `lineage_depth`, no `expanded_entity_ids`).

{% hint style="info" %}
**The group view is filtered in two ways that can hide edges you expect to see.**

* **Nested groups are dropped.** Any lineage edge that touches a Data Entity Group *inside* this group is filtered out, and the nested groups themselves are removed from the result. A DEG that contains other DEGs returns those nested DEGs missing, with no signal in the response — support for nested groups in group lineage is not implemented yet.
* **Only edges fully inside the group survive.** An edge is kept only when **both** of its endpoints are members of the group. Edges that cross the group boundary — an upstream source that feeds a member but is not itself a member, or a downstream consumer outside the group — are dropped. The group view shows internal flow between members, not the group's external upstream sources or downstream consumers. To see what feeds or consumes a member across the boundary, open that member with the per-entity upstream / downstream endpoints.
  {% endhint %}

{% hint style="warning" %}
**A 404 from the group-lineage endpoint has three possible causes — you cannot tell them apart from the response.** `GET /api/dataentitygroups/{id}/lineage` returns the identical `404 Not Found` when (a) the id does not exist, (b) the group exists but has zero members, or (c) the id belongs to a data entity that is **not** a group at all. The sibling membership endpoint returns `200 OK` with an empty list on the zero-members condition instead, so a script polling both sees two different contracts for the same DEG. See the [API reference's Group lineage section](/developer-guides/api-reference/lineage) for the full 404-vs-200-empty asymmetry and the disambiguation steps.
{% endhint %}

## What participates

| Entity class                                         | Participates in lineage | Notes                                                                    |
| ---------------------------------------------------- | ----------------------- | ------------------------------------------------------------------------ |
| Dataset, View                                        | Yes                     | Native source-to-sink lineage edges from collectors / push adapters.     |
| Transformer (ETL job, ML training job, microservice) | Yes                     | Edges from input datasets to the transformer to output datasets.         |
| Transformer Run                                      | Yes                     | Run-level lineage for per-execution traceability.                        |
| Data Quality Test, Data Quality Test Run             | Yes                     | Test linkage to the dataset(s) under test.                               |
| Consumer (BI dashboard, ML model artifact, …)        | Yes                     | Downstream-only — consumers read but do not produce.                     |
| Data Input (API call, …)                             | Yes                     | Upstream-only — inputs feed the platform but are not produced inside it. |
| Data Entity Group, ML experiment                     | Yes (via Group lineage) | Group lineage returns the union over the group's children.               |
| Entity Relationship                                  | Yes                     | Surfaces foreign-key-style ERD edges as part of the graph.               |

The exact set of entity classes ingested into your platform depends on which collectors and push adapters are connected; see [Integrations](/integrations/integrations) for the per-source coverage.

## Access model

Lineage reads are **read-collaborative**: none of the three lineage endpoints (per-entity upstream, per-entity downstream, group lineage) applies an ownership filter, and none requires a specific permission beyond being signed in. Any authenticated user who knows — or guesses — a data-entity id or group id can read the full reachable lineage subgraph around it, regardless of which team owns the entities in that graph. Lineage edges expose cross-team pipeline structure, so treat the lineage surface as visible to every authenticated user of the catalog.

{% hint style="warning" %}
**Two access facts to plan around before exposing lineage to a multi-team or untrusted audience.**

* **No owner scoping.** There is no per-owner or per-team isolation on lineage reads. If team isolation matters, scope the deployment to a single team rather than relying on lineage to hide other teams' graphs.
* **`auth.type=DISABLED` makes lineage anonymous.** When the platform runs with authentication disabled, every endpoint — including all three lineage reads — is reachable by any unauthenticated client that can reach the network port. Do not run `DISABLED` on a network where untrusted clients can reach the platform. See [Authorization](/configuration-and-deployment/enable-security/authorization) for the platform-wide model.

The **group-lineage** endpoint has the widest reach: by walking group ids a caller can enumerate the cross-owner co-membership graph of the whole catalog. If lineage exposure is a concern, the group endpoint is the one to weigh most carefully.
{% endhint %}

## Where to next

* [Microservices Lineage](/features/data-lineage/microservices) — the OpenTelemetry-traced counterpart for microservice call graphs.
* [Data Entity Groups & Domains](/features/data-discovery/groups-domains) — what gets returned when you call Group lineage on a DEG.
* [API Reference → Lineage](/developer-guides/api-reference/lineage) — full HTTP surface (per-entity, group, microservices).
* [ODD Specification — Data Model](https://github.com/opendatadiscovery/opendatadiscovery-specification/blob/main/specification/specification.md#data-model-specification) — the canonical entity-class reference.
* [Main Concepts → Data Governance map](/introduction/main-concepts#data-governance-map) — Data Lineage's position among the governance pillars.


# Microservices Lineage

Microservice call lineage — OpenTelemetry traces ingested through odd-tracing-gateway and rendered alongside data-object lineage.

This feature traces the data provenance of microservice-based applications. ODD represents microservices as catalog objects and shows their call graph as a typical lineage diagram — the same UI surface as [Data Objects Lineage](/features/data-lineage/data-objects), with microservice nodes participating alongside datasets, transformers, and the rest of the entity model.

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-b0b7a45c790baed747274810561b9b7b505dae4c%2Fmicroservices_lineage.png?alt=media)

## How microservices land in the catalog

Microservice lineage is sourced from **OpenTelemetry traces**. The path is:

1. The microservice (instrumented with OpenTelemetry) emits trace spans to a telemetry collector — typically an OTel Collector or directly to a backend that speaks OTLP.
2. [`odd-tracing-gateway`](/integrations/integrations/odd-tracing-gateway) — the platform's only [standalone gateway](/introduction/main-concepts#the-architecture-chain) push adapter today — receives those traces, infers the microservice topology and the calls between services, and emits the corresponding ODD entities (microservice transformers + the call edges between them) into the platform's [Ingestion API](/introduction/main-concepts#odd-specification).
3. The platform stores the inferred entities in the catalog and renders their lineage in the same Lineage tab as data-object lineage.

Operator-mental-model: "push" — microservices push their traces and the gateway forwards. The Platform-side leg is a pull hidden behind the gateway's standalone deployment, which is why `odd-tracing-gateway` is classified as a [standalone-gateway push adapter](/introduction/main-concepts#the-architecture-chain) in the architecture chain.

## Where to find it in the UI

Microservices appear in the catalog as `MICROSERVICE`-class transformer entities. From any microservice detail page, the **Lineage tab** opens the same graph view used for data-object lineage — call edges between microservices flow alongside dataset / transformer / consumer edges where the platform has visibility into both surfaces.

## Access model

Microservice lineage uses the same read-collaborative posture as the rest of the catalog: any authenticated user with read access to the platform's data entities can request the upstream / downstream graph of any catalogued microservice, regardless of which team owns the underlying service. The platform's lineage repository does not perform an ownership-side filter on the read path. And when the platform runs with `auth.type=DISABLED`, "authenticated user" widens to **any unauthenticated client that can reach the network port** — the lineage read is then anonymous.

{% hint style="warning" %}
**Microservice lineage exposes operational topology that schema lineage does not.** A microservice's upstream / downstream graph reveals which services it calls and which services call it — the same kind of dependency-graph that an operator would otherwise need APM access to read. In a multi-team deployment, an SRE on one team can read another team's service-call patterns through this surface; competitor service-call cardinality, inter-team-service coupling, and service-interdependence patterns become visible to every authenticated catalog user — and to **anonymous** callers if the platform runs with `auth.type=DISABLED`, since that mode removes the sign-in requirement from every endpoint, this one included. This is the same read-collaborative posture as data-object lineage (see [Authorization](/configuration-and-deployment/enable-security/authorization) for the platform-wide model), but the operational sensitivity is higher on microservice lineage because service-call patterns are more topology-revealing than schema-lineage edges. Multi-team operators planning microservice-lineage exposure should plan accordingly — keep the catalog deployment scoped to a single team, restrict who has authenticated access to it, and never run `DISABLED` on a network reachable by untrusted clients.
{% endhint %}

## Supported payload fields

The lineage response DTO is **class-agnostic** — every node carries the same shape regardless of whether it is a dataset, transformer, consumer, or microservice. The fields that survive on every node:

* Identity (`id`, `oddrn`, `externalName`, `internalName`).
* Class / type discriminators (`entityClasses`, `dataEntityType`).
* The lineage edges to upstream and downstream neighbours.
* Owner / namespace / data-source attribution.

Microservice-specific OpenTelemetry trace fields — `operation_name`, `span_kind`, `error_rate`, `p95_latency`, `callsPerMinute`, per-call cardinality, service-call cardinality — are **silently dropped** at the response-DTO mapper. The lineage endpoint returns the topology (which microservice calls which) but not the per-call metadata an APM consumer would expect. If you ingest those fields through a custom `odd-tracing-gateway` extension, they live in the platform's database but do not surface on the lineage API today.

**Mitigation today.** If your operator workflow needs the per-call metadata, query the upstream APM / tracing backend directly — the lineage API is the topology surface. The platform's lineage payload shape is generic across all entity classes; a microservice-specific payload extension is on the roadmap but not shipped.

## Where to next

* [Data Objects Lineage](/features/data-lineage/data-objects) — the catalog-side lineage surface that microservice nodes render alongside.
* [`odd-tracing-gateway`](/integrations/integrations/odd-tracing-gateway) — the standalone gateway that turns OpenTelemetry traces into ODD microservice entities.
* [Architecture](/introduction/architecture) — the platform-wide data-flow diagram, including the gateway's position in the producer-side topology.
* [Main Concepts → The architecture chain](/introduction/main-concepts#the-architecture-chain) — where standalone-gateway push adapters sit among the producer-side concepts.
* [API Reference → Lineage](/developer-guides/api-reference/lineage) — the same lineage HTTP surface used for both data-object and microservice lineage. Calling it directly? Always pass an explicit `lineage_depth` — omitting it returns HTTP 500, not a default-depth graph.


# Data Glossary

Top-level UI section for the in-app Business Glossary — term entities, term-to-term linking, term-to-data-entity descriptive associations, ownership, and RBAC.

The **Data Glossary** section of ODD Platform is the home for the in-app **Business Glossary** — operator-curated term entities that name and describe the concepts your data represents. The role is durable: anything that captures the *meaning* of an entity (what `Customer` means in your taxonomy, how `Order` relates to `Line Item`, who owns each definition) belongs here.

ODD covers Data Glossary fully through the Business Glossary feature. See the [Data Governance map](/introduction/main-concepts#data-governance-map) for the position of Data Glossary among the other governance pillars.

{% hint style="info" %}
**Not the Main Concepts page.** The [Main Concepts](/introduction/main-concepts) docs page captures the *project's* vocabulary — Data Entity, Plugin, Push adapter, ODDRN. The **Business Glossary** described here is the *catalog's* vocabulary — operator-authored term entities that live inside ODD Platform and link to the data they describe. Same word "glossary", different things.
{% endhint %}

Open it from the top-level navigation **Dictionary** tab (the in-app surface for browsing and curating terms). Term entities also surface inline on every data-entity detail page in the **Terms** section once descriptive associations are made.

## Subsections

* [**Business Glossary**](/features/data-glossary/business-glossary) — full reference for terms as catalog entities: the Dictionary tab UI, namespace-scoped terms, ownership and the seven `TERM_*` RBAC permissions, term-to-term linking (description-text mentions vs direct links), term-to-data-entity descriptive associations (the Wikipedia-About-style walkthrough), and the API surface.

## Why this is a separate pillar

For how Data Glossary relates to the other governance pillars (Data Discovery, Data Modelling, Master Data Management, Data Lineage, Data Quality), see [Main Concepts → Data Governance map → Pillar differentiation](/introduction/main-concepts#pillar-differentiation) — the canonical home for the six-pillar framing. Glossary is its own pillar because terms are a separate entity class with their own lifecycle (create / approve / link / retire), ownership model, RBAC, and search surface — first-class catalog citizens that data entities reference, not metadata attached to other entities.

## Where to next

* [Business Glossary](/features/data-glossary/business-glossary) — the dedicated reference covering terms, term-to-term linking, descriptive associations, ownership, and the API surface.
* [API Reference → Glossary](/developer-guides/api-reference/glossary) — the HTTP surface for term CRUD, term-to-term linkage, and term-to-entity assignment.
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the platform-wide permission catalog, including the `TERM_*` rows.
* [Main Concepts → Data Governance map](/introduction/main-concepts#data-governance-map) — Data Glossary's position among the governance pillars.


# Business Glossary

Full reference for the in-app Business Glossary — term entities, the Dictionary tab UI, namespace scoping, ownership and RBAC, term-to-term linking, and term-to-data-entity descriptive associations.

The **Business Glossary** is ODD Platform's operator-curated catalog of term entities — the concepts your data represents (`Customer`, `Order`, `Active User`), captured as first-class catalog entities with their own descriptions, owners, tags, and links to the data entities they explain.

This page is the canonical reference for the feature. For where it sits among the other governance pillars, see the [Data Glossary](/features/data-glossary) pillar landing.

## What terms are

A **term** in ODD Platform is a Data Entity of type `TERM`. Like every other data-entity class, a term has:

* A **name** (the canonical label — `Customer`, `Active User`, `Monthly Recurring Revenue`).
* A **namespace** — terms live within a Namespace and are scoped by it (see [Namespace-scoped terms](#namespace-scoped-terms) below).
* A **description** — the Wikipedia-About-style narrative authoring of what the term means.
* **Owners** — operators responsible for the term's definition and lifecycle.
* **Tags** — applied via the standard tagging surface; the term's `TERM_TAGS_UPDATE` permission gates this.
* **Links** to other terms (term-to-term) and to data entities (term-to-entity).

Give extra information about your data entities by creating terms that define these entities or processes related to them. You may see all terms connected to a data entity on its overview page. All created terms are gathered in the **Dictionary** tab.

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-75e7ab79d85dbdf7bb63bcff6a0eec13cf0d21fb%2Fterms.gif?alt=media)

## The Dictionary tab

The Dictionary tab is the catalog-wide entry point for browsing and curating terms. The tab is implemented as a **server-side faceted-search session** rather than a flat list — opening it for the first time creates a new search session and lands you on a results page with an empty results table until you either type a query, apply a facet filter, or use the platform's term-listing API directly. On a deployment with many terms this avoids paginating thousands of rows up-front, but it does mean a fresh visit shows zero rows even on a populated catalog.

From here you can:

* Type a query or apply a facet to populate the results table.
* Create a new term (gated by `TERM_CREATE`).
* Open a term's detail page to edit its description, manage owners, link to other terms, and review which data entities reference it.

A term's detail page shows the **Overview** (the About-style description), a **TERMS** section listing directly-linked terms, and a reverse-search panel showing every data entity and column that references this term in its description.

The search-session URL (the `/termsearch/{uuid}` path you see in the address bar after a query) is **session-shared** — sharing the URL with a colleague gives them the same session view, including any filters and pagination state, and lets them mutate the session by changing those filters. Treat the URL as a working-view share, not as a deep-link to fixed results.

## Namespace-scoped terms

Terms live within a Namespace and are scoped by it for **identity and authoring** purposes — `finance/Customer` is a distinct term from `marketing/Customer` if both teams want different definitions. The namespace is part of the inline-mention syntax used in description text (see [Term-to-entity associations](#term-to-entity-associations)).

Namespace is **not a read-time isolation boundary** on the term catalogue. Every authenticated user sees every term from every namespace in Dictionary search results, term-detail pages, and the `/api/terms` read endpoints — the namespace field is a payload classifier, not a query predicate, at the term-read layer. Multi-namespace deployments depending on per-namespace read isolation should treat this as a known limitation; the term metadata you author in one namespace is visible to operators authorised on the platform regardless of the namespace they belong to. See [Known operator caveats](#known-operator-caveats) below for the related security caveats around term-link side-channels.

For coordinating terms across teams, use [Namespaces in Management](/features/management) as the operator-mutating surface that creates and curates namespaces themselves.

## Ownership and privileges

A term carries **owners** — operators (linked to platform users via [User-owner association](/configuration-and-deployment/enable-security/authorization/user-owner-association)) responsible for the term's definition, edits, and lifecycle. The owner holds the authority to create, approve edits, and delete the associated term, contributing to the relevance of those descriptions.

The platform exposes seven `TERM_*` RBAC permissions:

| Permission              | Action                                                                                                                                                                                                                        |
| ----------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `TERM_CREATE`           | Create a new term in the Dictionary.                                                                                                                                                                                          |
| `TERM_UPDATE`           | Edit the term's name, description, or namespace. (Does **not** gate direct term-to-term links — those endpoints carry no permission; see [Known operator caveats → Security and RBAC bypasses](#security-and-rbac-bypasses).) |
| `TERM_DELETE`           | Delete a term from the Dictionary.                                                                                                                                                                                            |
| `TERM_OWNERSHIP_CREATE` | Assign an owner to a term.                                                                                                                                                                                                    |
| `TERM_OWNERSHIP_UPDATE` | Update an existing owner's role on a term.                                                                                                                                                                                    |
| `TERM_OWNERSHIP_DELETE` | Remove an owner from a term.                                                                                                                                                                                                  |
| `TERM_TAGS_UPDATE`      | Apply or remove tags on a term.                                                                                                                                                                                               |

Plus the cross-cutting `TERM_ASSIGNMENT_UPDATED` activity-event marker emitted whenever a term is linked to or unlinked from a data entity.

For the platform-wide permission catalog and how to compose roles around these permissions, see [Permissions](/configuration-and-deployment/enable-security/authorization/permissions).

## Term-to-term linking

ODD supports two distinct ways of relating terms in the catalog. Pick the one that fits the relationship you want to express.

**Description-text mentions.** Inline-mention a term inside a data entity's or column's description. The mention surfaces in that entity's **Terms** section once the description is saved. This is the right tool for narrative use — when the term is part of how you explain the entity. The required format and a full walkthrough live in [Term-to-entity associations](#term-to-entity-associations) below.

**Direct term-to-term links.** A term can also be linked directly to other terms — independent of any data entity description. From a term's detail page, the **Overview → TERMS** section exposes an **Add term** action that opens an autocomplete to pick the target term. The link is bi-directionally visible: it appears on both terms' pages and can be removed from either side. Each linked term carries an `isDescriptionLink` flag, so the UI can distinguish links created via inline description mentions from these direct links.

The UI surfaces the **Add term** action alongside the term edit controls, so it appears to follow `TERM_UPDATE` — but the underlying create/remove endpoints carry no RBAC permission and are open to any authenticated user. See [Known operator caveats → Security and RBAC bypasses](#security-and-rbac-bypasses) before relying on `TERM_UPDATE` to gate who can link terms.

The same term-to-term linking is exposed over the platform API — see [API Reference → Glossary → Term-side linkage](/developer-guides/api-reference/glossary).

**When to use which.** Reach for description-text mentions when the term naturally belongs in the narrative of an entity (*"This `orders` table records each `Customer Order`."*). Reach for direct term-to-term links when you are curating the glossary itself (*"`Customer` and `Client` mean the same thing in our taxonomy."*) and want the relationship to be visible from either term's page regardless of where it is mentioned.

## Term-to-entity associations

This is the descriptive-information walkthrough — how operators link business terms to specific data entities and columns to give them domain context.

**Adding business terms to the Dictionary.** Initially, it is necessary to add relevant business terms to the platform's Dictionary. These terms can be associated with specific data entities or columns.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-2bf95ad2a73ab0735b2ffb1622d82bb8305cdf00%2Fmedium-0-Ag1g1Z_0NFKcME2s.png?alt=media" alt=""><figcaption></figcaption></figure>

The Dictionary Terms section primarily serves to define and provide context for data entities. For instance, if a data asset relates to "Customer Analytics", the associated business term can signify its alignment with the customer analytics domain.

**Ownership and privileges.** An essential part of this feature is the capacity to designate an owner for a business term. This owner holds the authority to create, approve edits, and delete the associated entity, contributing to the relevance of those descriptions.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-7a89df9633436b6aa58408435864d9ca7cbc8519%2Fmedium-0-VsGFMUHIncPaz7TW.png?alt=media" alt=""><figcaption></figcaption></figure>

**An About feature inspired by Wikipedia.** The central concept behind the development of this feature draws inspiration from the user-friendly functionality found on Wikipedia — an **About** section.

As soon as the term is introduced into the dictionary, users can navigate to the **About** section and craft a concise term description using a rich formatting toolbar.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-d22a89bacb7dac02fc1bbb903d191b24fd36ff63%2Fmedium-0-Zg6k67QdeDbj8ADd.png?alt=media" alt=""><figcaption></figcaption></figure>

**Linking and describing terms.** The terms mentioned in description text can then be linked to the previously established business term, using the required format for linking. When users hover the cursor over an information icon, it triggers the highlighting effect, illuminating the text **format** that should be used to link the text to a specified term.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-7f46f16f47bdf21395ae0c311f60abfa983997cf%2Fmedium-0-QvhwncHrxu043zzB.png?alt=media" alt=""><figcaption></figcaption></figure>

**Updated Dictionary Terms section.** Once created and saved, the business term becomes accessible in the Dictionary Terms section. Successful creation of the link will be indicated by a notification in the bottom right corner of the screen.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-78d8c7d148c47af1aa5a4799644cd2a326fdc433%2Fmedium-0-Md8V4iTJohtWOhLP.png?alt=media" alt=""><figcaption></figcaption></figure>

Before linking terms, it is essential to have previously created them and established a corresponding Namespace in the Dictionary. Adhere to the specified formatting requirements and be mindful of spaces. If the term or Namespace is not defined in the Dictionary, a notification will appear around the About section.

**The identical feature for columns.** Users are able to associate terms not only with the dataset as a whole but also with the individual columns. To try it, the user may go to the **Structure** section, choose the desired **Column**, or proceed with the automatically selected one and provide a description in the same manner as described earlier.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-6089d1a6e0033aece1133030a89f7d6132514bdf%2Fmedium-0-EzL8uXsyOsga5dHh.png?alt=media" alt=""><figcaption></figcaption></figure>

After saving the description and associating it with the relevant term, the linked term will appear directly below in the Terms section.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-64e5f95c7fcbf3eb5594664eb124d7412dbe398e%2Fmedium-0-xAUNpg0N3W7YnSRj.png?alt=media" alt=""><figcaption></figcaption></figure>

This feature provides users with a convenient way to reach all the business terms available on the platform.

**Reverse search functionality.** It is important to note that connecting items to data entities enables a reverse search capability. Users can easily verify which entities and columns have previously been linked to a specific term.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-bf095ae10a2efe1dab901a79cb680a99112b7bcd%2Fmedium-0-3prwysGpf6T0pokg.png?alt=media" alt=""><figcaption></figcaption></figure>

If the user clicks on the term, a window containing the relevant information will be displayed.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-0bb06a08fc2afcd13661c484271078579815316c%2Fmedium-0-VtesnW1pYfPVHKfY.png?alt=media" alt=""><figcaption></figcaption></figure>

**Activity audit trail.** The history of numerous actions within the platform is accessible in the [Activity Feed](/features/active-platform-features/activity-feed), including the creation and linking of terms (the `TERM_ASSIGNMENT_UPDATED` event).

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-75f5606fec8d5d779ed90e8c43b2fd71690cc101%2Fmedium-0-CidDd5tUjI3clp7f.png?alt=media" alt=""><figcaption></figcaption></figure>

## Known operator caveats

The Business Glossary carries several platform-side defaults that surprise operators authoring deployment-time RBAC policies or compliance-grade audit procedures. Each item below names what an operator might assume, what the platform actually does, and what to do about it today. Caveats are grouped by category so operators auditing security posture can find the relevant items quickly.

### Security and RBAC bypasses

{% hint style="danger" %}
**Term-link and term-unlink operations are not currently gated by `DATA_ENTITY_ADD_TERM` / `DATA_ENTITY_DELETE_TERM`.** The platform's security-rule registry registers the gate against the path `/api/dataentities/{id}/term` (singular), but the actual endpoint exposed by the OpenAPI contract is `/api/dataentities/{id}/terms` (plural). The path-matcher never fires, and the requests fall through to the global "any authenticated user" rule. **Any authenticated user under `LOGIN_FORM`, `OAUTH2`, or `LDAP` can link or unlink any term to any data entity** regardless of the Policy grants the operator has authored for these two permissions. If separation-of-duties on term-to-entity linkage matters to your deployment, do not rely on `DATA_ENTITY_ADD_TERM` / `DATA_ENTITY_DELETE_TERM` until the platform-side path-rename fix lands.

Note that renaming the security-rule path alone would not fully close this gap: the service-layer methods that perform the link and unlink (`linkTermWithDataEntity`, `removeTermFromDataEntity`, `linkTermWithDatasetField`, `removeTermFromDatasetField`, `linkTermWithTerm`, `removeTermToLinkedTermRelation`) carry no permission check of their own — the only authorization is the controller-path rule. Treat term linkage as reachable by any authenticated user until both the path and a service-tier check are in place.
{% endhint %}

{% hint style="danger" %}
**Direct term-to-term links are not gated by `TERM_UPDATE` — or by any permission.** The **Add term** action on a term's **Overview → TERMS** panel calls `POST /api/terms/{term_id}/term` (and the matching `DELETE` to unlink). Unlike the term-edit endpoints, these two paths have no entry in the platform's security-rule registry at all, so they fall through to the global "any authenticated user" rule. **Any authenticated user can create or remove a direct term-to-term link regardless of whether you granted them `TERM_UPDATE`.** The UI placement next to the term-edit controls makes the action look `TERM_UPDATE`-gated, but it is not. Do not rely on `TERM_UPDATE` to control who can curate the term-to-term graph until the platform registers a permission for these paths.
{% endhint %}

{% hint style="warning" %}
**Editing an entity description with `[[namespace:term]]` mentions writes term-to-entity link rows without consulting `DATA_ENTITY_ADD_TERM`.** The auto-link side-channel materialises links as the description saves; the operator who edits the description does not need term-link permission to attach the term. Granting `DATA_ENTITY_DESCRIPTION_UPDATE` therefore implicitly grants term-link capability. Operators authoring separation-of-duties policies cannot use the two permissions as independent grants today.
{% endhint %}

{% hint style="warning" %}
**Creating a new term silently writes term-to-entity links for every pre-existing entity description that already mentioned the term by name.** The platform maintains two staging tables for `[[namespace:term]]` mentions that referenced a term that did not yet exist; the moment the term is created, the staging tables drain and the auto-links are written. These cross-time auto-links are recorded under the description author's historical context — not the term-creator's — and the only Activity Feed event surfaced is the `TERM_CREATED` of the new term. Compliance reconstructions of "who linked term X to entity Y at time T" cannot be answered from platform logs for entities linked through this drain. Operators authoring popular term names (`Customer`, `Order`, `PII`) should expect a significant burst of auto-links to materialise the moment the term is created.
{% endhint %}

{% hint style="warning" %}
**Typing a novel namespace name in the Term create / edit dialog creates a new namespace on submit — without consulting `NAMESPACE_CREATE`.** The dialog's namespace autocomplete accepts free-text input; on submit, the platform's namespace service auto-creates the namespace row on the requester's behalf. Operators granted `TERM_CREATE` but explicitly **not** `NAMESPACE_CREATE` (a separation-of-duties posture) can still mint namespaces this way. Track the namespace directory growth as part of your operator-hygiene cadence.
{% endhint %}

{% hint style="warning" %}
**Typing a novel tag name in the Term tags edit dialog creates a new tag on submit — without consulting `TAG_CREATE`.** Same shape as the namespace bypass above: operators with `TERM_TAGS_UPDATE` (but without `TAG_CREATE`) can mint tags through this dialog. The tag directory accretes silently. The `Management → Tags` surface remains the operator-curation tab, but it does not gate the side-channel creation path described here.
{% endhint %}

{% hint style="danger" %}
**The term-definition Markdown editor accepts raw HTML and inline JavaScript with no client-side sanitisation.** The Term create / edit dialog's definition field persists the Markdown body verbatim through the platform; the render side does not strip HTML / script payloads before mounting. Any operator with `TERM_UPDATE` permission can plant `<script>` payloads in the definition; the payload triggers for every authenticated user who subsequently views the Term overview. Treat the Term definition body as a **trusted-input surface** — do not paste content from untrusted authors. The same caveat applies to the `[[namespace:term]]` mention markers — the captured strings persist in the unhandled-mention staging tables verbatim and can carry payload through to the linked entity's render surface when the term is later created.
{% endhint %}

### Visibility and cross-tab UX

{% hint style="info" %}
**The Term Overview tab's TERMS mini-panel and the Linked Terms tab show the same data but offer different actions.** The Overview panel supports Add and Delete on each row; the Linked Terms tab supports search but not Add / Delete. To bulk-manage linked terms, use the Overview panel; to find a specific linked term in a large set, use the tab's search.
{% endhint %}

{% hint style="info" %}
**Auto-linked rows are visually distinct on the Term Overview panel but not on the Term Linked Entities tab.** On the Overview's TERMS panel, term-to-term rows created via inline description mentions show a distinguishing icon and hide the per-row delete button; on the Linked Entities reverse-lookup tab the auto-linked rows and the manually-created rows look identical. If a (term, entity) pair has **both** a manually-created link and an inline-description-mention link, the platform's read-time de-duplication prefers the auto-linked variant, which can hide the manually-created row from the UI entirely. Reconstructing "show me every term-to-entity link that was created manually, excluding the description-side-channel links" is not possible from the UI today.
{% endhint %}

### Correctness and UX defects

{% hint style="info" %}
**The Term create dialog's duplicate-name check loads the first 1000 terms client-side and compares against them.** Catalogs with 1001 or more terms can silently allow a duplicate name for the 1001-th term. The duplicate-name check also does **not** run in edit mode — renaming an existing term to collide with another in the same namespace produces no client-side warning. The backend uniqueness constraint catches the collision after submit but the client does not surface a friendly error today; see the silent-failure caveat below.
{% endhint %}

{% hint style="info" %}
**If the backend rejects the Term save (uniqueness violation, validation error, RBAC mismatch), the dialog stays open with the form filled in and no error message renders.** Operators cannot tell from the UI whether the save succeeded or failed. Workaround until the upstream fix lands: refresh the Terms list to confirm the save; if the term is absent, the save failed.
{% endhint %}

{% hint style="info" %}
**After creating a new term, the post-save cache invalidation runs against an undefined term ID — it invalidates nothing.** Lists that rely on the cached term set (notably the Terms list page itself) may not refresh until you reload manually. Workaround: refresh the Terms list explicitly after creating a new term.
{% endhint %}

### Performance characteristics

{% hint style="info" %}
**The Dictionary tab's facet rate-limit (1500 ms) does not function as intended.** Rapid facet clicks (five clicks in two seconds, for example) dispatch five separate backend requests instead of debouncing into one. The platform tolerates the burst, but operators tuning Postgres for high-cardinality facet sets should expect each facet click to incur its own request.
{% endhint %}

## API surface

The full Business Glossary HTTP API — term CRUD, term-to-term linkage, term-to-data-entity assignment, term-to-column assignment, and the corresponding Activity events — is documented at [API Reference → Glossary](/developer-guides/api-reference/glossary).

## Where to next

* [Manual Object Tagging](/features/data-discovery/tagging) — the taxonomy counterpart; tags are the *labelling* mechanism, terms are the *meaning* mechanism.
* [Search and Filtering](/features/data-discovery/search) — find data entities by the terms linked to them.
* [Query Examples](/features/data-modelling/query-examples) — query examples can be linked to terms via `QUERY_EXAMPLE_TERM_*` permissions.
* [API Reference → Glossary](/developer-guides/api-reference/glossary) — the HTTP surface.
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the platform-wide permission catalog, including all `TERM_*` rows.
* [Activity Feed](/features/active-platform-features/activity-feed) — where term creation and term-to-entity assignment events are recorded.


# Active platform features

Platform behaviours where ODD is itself an actor — alerts, notifications, activity, discussions, AI assistance, metrics ingestion. Six opt-in subsystems, each independently configured.

The **Active platform features** section is the home for ODD Platform's event-driven, opt-in behaviours — the features where the platform is itself an actor in the data lifecycle rather than a passive system of record. The role is durable: anything the platform **does** on the operator's behalf (detect a condition and raise an alert, deliver a notification through Slack or email, record a change to an entity, host a discussion thread, broker a question to an external AI service) belongs here.

ODD covers active platform features through six independently-configured subsystems. Each is opt-in — disabled out of the box, enabled per its own configuration surface — so deployments use whatever subset matches their workflow.

Open them either from the entity-level UI (the **Alerts**, **Activity**, and **Discussions** tabs that appear on data-entity pages once each subsystem is wired up), the global **Activity** page, or the platform's HTTP API. There is no single top-level navigation tab named "Active platform features"; the surface area is reached through the sub-features as they apply to the entities and workflows the operator is working in.

## Subsections

* [**Alerting**](/features/active-platform-features/alerting) — the platform watches each entity for failed jobs, failed data-quality tests, backwards-incompatible schema changes, and externally-injected distribution anomalies. The **Alerts** section in the navigation pane (with **All / My Objects / Dependents** tabs) lists **open** alerts only; resolved history is read on each entity's own Alerts tab. Auto-resolution and per-entity halt configuration shape the queue size; the lifecycle and cleanup rules are the operator-relevant detail.
* [**Notifications**](/features/active-platform-features/notifications) — alerts route out of the platform via Slack incoming-webhook, generic webhook, and SMTP email. The user-facing description (which channels exist, what the operator gets, how to disable) lives here; the operator-side configuration keys (`notifications.*`, the PostgreSQL replication prerequisite, the Gmail SMTP example, the AlertManager inbound webhook) live on the platform's [configuration reference](/configuration-and-deployment/odd-platform#enable-alert-notifications).
* [**Activity Feed**](/features/active-platform-features/activity-feed) — the platform records every metadata change as an event (entity lifecycle, ownership, tags, terms, dataset-field edits, data-entity-group changes, alerts) on a global **Activity** page and on each entity's **Activity** tab. The feed is the audit trail and the change-driven discovery surface.
* [**Data Collaboration**](/features/active-platform-features/data-collaboration) — operators start in-app discussion threads anchored to specific data entities, with replies tracked back into the platform from a Slack workspace. Bidirectional with Slack via OAuth + the [Events API](https://docs.slack.dev/apis/events-api/); distinct from the outgoing-only Slack alert webhook used by Notifications.
* [**GenAI assistant**](/features/active-platform-features/genai) — opt-in proxy from a single platform endpoint to an external AI service the operator deploys and operates separately. The platform itself does not embed an LLM; it forwards questions verbatim and returns whatever the service returns. API-only today.
* [**Metrics Ingestion**](/features/active-platform-features/metrics-ingestion) — push time-series metrics into the platform through `POST /ingestion/metrics` and surface them on each affected data entity's Metrics tab. Two storage backends (`INTERNAL_POSTGRES` default, `PROMETHEUS` for tenant-isolated multi-deployment setups); the unauthenticated `/ingestion/metrics` endpoint requires perimeter authentication for any non-trusted network.

## Why this is a separate pillar

The [Data Discovery](/features/data-discovery), [Data Modelling](/features/data-modelling), and [Master Data Management](/features/master-data-management) pillars are read-oriented — operators and users navigate the catalog to **find** existing entities, examine **structure** (queries, relationships), and consult **operator-curated reference data**. The platform is a system of record that surfaces what was ingested.

The [Management](/features/management) section is operator-mutating — every tab there changes how the platform itself is wired up: register a data source, issue a collector token, author a role, curate a tag, attach an owner.

Active platform features are different from both:

* They are **event-driven**: the platform reacts to ingest events (a failed job triggers an alert; a description edit emits an activity-feed event), to operator actions (a Discussions thread is started; a question is asked of the AI), or to external triggers (Prometheus AlertManager pushes a distribution anomaly through the inbound webhook).
* They produce **side effects**: alerts are stored, notifications go out over Slack / email / generic webhook, activity events are persisted, discussion messages are mirrored into Slack, AI questions are forwarded to an external service.
* They are **opt-in per subsystem**: each one is disabled by default and gated by its own `*.enabled` flag plus the configuration surface that supports it. A deployment can run with all six off and still serve the catalog — none is required.

{% hint style="warning" %}
**If you supply your own configuration, define `notifications.enabled` and `datacollaboration.enabled` explicitly — the platform reads these two flags with no built-in fallback and fails to start if either is missing.** The shipped `application.yml` sets both to `false`, so a default deployment is unaffected. But the platform resolves these two flags at startup with no default value baked in, so a custom or externalized configuration (a mounted `application.yml`, a Spring profile, or environment-variable overrides) that omits either key leaves the platform unable to resolve the flag and it **aborts startup** rather than defaulting the feature off. Always carry both keys forward into any configuration you author. The other subsystem flags (`genai.enabled`, `metrics.storage`) do not share this hazard.
{% endhint %}

That distinction shows up in the configuration footprint: every one of the six subsystems has a dedicated section under [Configure ODD Platform](/configuration-and-deployment/odd-platform) (Alert Notifications, Prometheus AlertManager Integration, Data Collaboration, GenAI Configuration, Enable Metrics, plus the platform-level activity-feed partition setting `odd.activity.partition-period`). The other pillars consume configuration but rarely own dedicated config sections — their feature pages link out to per-key references rather than carrying their own configuration footprint.

## Where to next

* For the catalog read-side counterparts — search, the directory, the Catalog Overview home page → see [Data Discovery](/features/data-discovery).
* For the operator-mutating UI surface — namespaces, datasources, owners, tags, roles, policies → see [Management](/features/management).
* For the operator-side configuration keys behind the six subsystems → see [Configure ODD Platform](/configuration-and-deployment/odd-platform).
* For the API surface behind the six subsystems → see [API Reference](/developer-guides/api-reference). Per-subsystem sub-pages: [Alerts](/developer-guides/api-reference/alerts), [Data Collaboration](/developer-guides/api-reference/data-collaboration), [GenAI](/developer-guides/api-reference/genai). The Activity Feed, Metrics Ingestion, and notifications dispatch APIs are documented inline on each active-platform-features sub-page where they apply.
* For the broader catalog vocabulary (Data Entity, ODDRN, Plugin, Push adapter) → see [Main Concepts](/introduction/main-concepts).


# Alerting

Per-entity alerts for failed jobs, failed DQ tests, backwards-incompatible schema changes, and injected distribution anomalies — tracked through an OPEN → RESOLVED lifecycle with per-entity halt.

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-32b806f7afa6693ce800787562a8e902d0cfd10f%2Falerting.gif?alt=media)

Whenever an issue arises with a catalogued entity — a failed job, a failed data quality test, a backwards-incompatible schema change, or an externally-injected distribution anomaly — the platform raises an **alert** visible in the navigation pane's `Alerts` section and on each affected entity's own Alerts tab.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-f4088127ea5f91469b6f9996d9abed416f89e9ef%2Fmedium-0-Nr1RcqQXtPAlwD3p.png?alt=media" alt="" height="320" width="700"><figcaption><p>Alerts section on the navigation pane</p></figcaption></figure>

Each alert carries the affected entity, the alert type, the triggering timestamp, status history, and a Resolve action; resolving an alert updates the same record in place.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-34aec31b22e51efe121369286afd0ea7948efbb7%2Fmedium-0-Y5NvDvimONHxPF7E.png?alt=media" alt="" height="260" width="700"><figcaption><p>Alert notification details</p></figcaption></figure>

Alerts are persisted the moment they are raised — a plain insert on the platform's own ingestion / evaluation pipeline — so the alert record exists independently of whether any outbound delivery channel (Slack, email, webhook) is configured.

## Alert types

The platform tracks four alert types:

* **Failed job** — a transformer entity's most recent run reported failure.
* **Failed data quality test** — a quality-test entity's most recent run reported failure.
* **Backwards incompatible schema change** — a producer dropped something a downstream consumer was relying on (see [Backwards-incompatible schema change](#backwards-incompatible-schema-change-what-triggers-it) for the detection rules).
* **Distribution anomaly** — anomalous distributions detected externally and pushed in via Prometheus AlertManager (see the inbound webhook description in [Notifications](/features/active-platform-features/notifications)).

Alerts originate from two sources: the platform's own ingestion / evaluation pipeline (for the first three types and any other internal triggers), and optionally from an external [Prometheus AlertManager](https://prometheus.io/docs/alerting/latest/alertmanager/) via the `POST /ingestion/alert/alertmanager` inbound webhook. AlertManager-routed alerts surface as **Distribution Anomaly** alerts using the `entity_oddrn` label to attribute them to the affected entity. The setup steps for the AlertManager integration live on [Notifications → Prometheus AlertManager inbound webhook](/features/active-platform-features/notifications#prometheus-alertmanager-inbound-webhook).

How an alert leaves the platform — Slack, email, generic webhook, plus the AlertManager-driven inbound path — is its own subsystem; see [Notifications](/features/active-platform-features/notifications).

### Inbound AlertManager webhook — operator caveats

The live page above already discloses that the `POST /ingestion/alert/alertmanager` endpoint is not authenticated (the platform's Spring Security configuration whitelists `/ingestion/**` for collectors, and the AlertManager path inherits that whitelist). Three additional operator-visible behaviours sit on top of that disclosure — each of them load-bearing for any deployment whose AlertManager is reachable from outside an operator-trusted network.

{% hint style="danger" %}
**Anyone with network reach to the webhook can inject a forged Distribution Anomaly on any catalogued entity.** The handler reads the `labels.entity_oddrn` from the request body and writes it to the new alert's `data_entity_oddrn` column with **no existence check, no ownership check, no permission check**. Combined with the unauthenticated endpoint, any caller — anonymous under `auth.type=DISABLED`, any authenticated user otherwise — can `POST` an `entity_oddrn` pointing at any other team's dataset and surface a false-positive Distribution Anomaly on that entity. The forged alert appears on the platform-wide **All** tab (cross-team readable today) and is indistinguishable from a real anomaly to the reviewer working the queue.

**Mitigation today:** place the platform behind a private network or an operator-controlled ingress that restricts who can reach `/ingestion/alert/alertmanager`. Until the upstream gate-or-shared-secret hardening ships, the webhook should be considered authoritative only from the trusted AlertManager instance; do not expose it on the public internet.
{% endhint %}

{% hint style="danger" %}
**The `generatorURL` from the AlertManager payload is embedded verbatim into the alert description — a stored-XSS / open-redirect surface.** The handler builds the alert's description by string-formatting the parsed generator URL into the body (`"Distribution Anomaly. URL: %s"`). The URL parser does not block `javascript:` or `data:` schemes, and the alert description is rendered as HTML on the UI's Alerts surface. Combined with the unauthenticated endpoint above, any caller can plant a `javascript:` URL (or an attacker-controlled redirect target) that fires when another operator opens the alert.

**Mitigation today:** the same network-layer restriction as above. The upstream fix is a scheme allow-list on the inbound URL plus UI-side sanitisation.
{% endhint %}

{% hint style="warning" %}
**Prometheus retries duplicate alerts in the UI — the webhook handler has no idempotency key.** The platform writes each inbound `ExternalAlert` as a new `INSERT` with no `ON CONFLICT` clause. Prometheus's default retry policy re-sends webhook payloads on any transient network blip; each retry creates a fresh alert row visible alongside the original. The in-platform alert path (failed-job, failed-DQ, schema-change) deduplicates at the application layer, but the AlertManager path bypasses that layer.

**Mitigation today:** if duplicate visibility is unacceptable, tune Prometheus AlertManager's `send_resolved: false` and lengthen `repeat_interval` so retries reach the platform less often. The upstream fix is an idempotency key on the inbound payload (or `ON CONFLICT DO NOTHING` on the platform-side insert).
{% endhint %}

## Alert views — All, My Objects, Downstream, Upstream

The `Alerts` section in the navigation pane is an Activity-style view: a left **filter panel** plus a results pane with four tabs that scope the alert list to different slices of the platform. Pick the tab that matches how you're working the queue — on large deployments the default `All` view can run into the hundreds of open alerts, and the `My Objects` / `Downstream` / `Upstream` tabs let individual owners cut the list down to what they're responsible for.

| Tab            | Scope                                                                                                     | When to use                                                                                                                                                       |
| -------------- | --------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **All**        | Every alert across the whole platform (matching the active filters).                                      | Platform-wide triage; stewards and admins watching the full alert surface.                                                                                        |
| **My Objects** | Alerts raised on data entities where the signed-in user is a registered owner.                            | Per-owner view — "what fires on the things I own". Requires user ↔ owner association.                                                                             |
| **Downstream** | Alerts raised on data entities that are **downstream** of entities the signed-in user owns (via lineage). | Impact view — "what's breaking in systems that consume my data". Surfaces ripple effects before the downstream team pings you. Requires user ↔ owner association. |
| **Upstream**   | Alerts raised on data entities that are **upstream** of entities the signed-in user owns (via lineage).   | Root-cause view — "what's failing in the systems my data depends on". Requires user ↔ owner association.                                                          |

The old single **Dependents** tab — which showed downstream alerts only — is now split into the two explicit lineage directions, **Downstream** and **Upstream**.

The tabs are **query-parameter driven** (`?type=ALL|MY_OBJECTS|DOWNSTREAM|UPSTREAM`), not separate routes; switching tabs changes the `type` parameter on the same `/alerts` page. The badge counts next to each tab react to the active filters but **not** to the selected tab, so you can see how many alerts each view holds under the current filter set before switching to it.

### Filter panel

The left panel filters every tab on the global Alerts page. The filters apply to the list **and** to the per-tab badge counts:

| Filter         | What it scopes to                                                                                                                                                           |
| -------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Period**     | Alerts whose triggering event falls in the chosen date-time range. Left unset by default, so the unfiltered view is "all alerts" rather than "alerts in the last *N* days". |
| **Datasource** | Alerts on entities belonging to the chosen datasource.                                                                                                                      |
| **Namespace**  | Alerts on entities in the chosen namespace.                                                                                                                                 |
| **Tag**        | Alerts on entities carrying the chosen tag(s).                                                                                                                              |
| **Owner**      | Alerts on entities owned by the chosen owner(s).                                                                                                                            |
| **Status**     | Alerts in the chosen lifecycle status — `OPEN`, `RESOLVED`, or `RESOLVED_AUTOMATICALLY`.                                                                                    |

{% hint style="info" %}
**The global views default to `OPEN`, and resolved alerts are reachable via the Status filter.** Out of the box the Status filter is set to **Open**, so every global tab opens on the active work queue. To read resolved history platform-wide, change **Status** to `RESOLVED` or `RESOLVED_AUTOMATICALLY` (or clear it to see every status) — the resolved alerts are returned on the same global tabs, no longer only through the per-entity view. (In the previous release the global tabs were hardwired to `OPEN` and resolved history was reachable only per-entity; the Status filter removes that restriction.)
{% endhint %}

![Alerts → All view on a populated deployment — 230 open alerts, each row carrying the affected entity name (dq\_test\_for\_\*), the entity-class chip (QT for Quality Test), the failure category ("Failed DQ test"), the timestamp + Show history link, and per-row Open / Resolve actions. The tab strip scopes the list to All / My Objects / Downstream / Upstream; the left panel carries the Period / Datasource / Namespace / Tag / Owner / Status filters.](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-a753047800dbf3c2bf4371375531732e33b0b6c7%2Falerts.png?alt=media)

The endpoints behind the four tabs (`getAlertsList`) and the badge-counter call (`getAlertCounts`) are documented at [API Reference → Alerts → Global alert listings](/developer-guides/api-reference/alerts).

{% hint style="info" %}
The `My Objects`, `Downstream`, and `Upstream` tabs are hidden unless the signed-in user is linked to an [Owner](/configuration-and-deployment/enable-security/authorization/user-owner-association) — without the association, the platform cannot evaluate "mine", "downstream of mine", or "upstream of mine". An operator who sees only the `All` tab almost always has a missing user-owner link. This is a different `My Objects` from the **Recommended → My Objects** wizard on the main page — the wizard surfaces recently-ingested owned entities; this tab filters alerts.
{% endhint %}

## Alert lifecycle: statuses, resolution, cleanup

Every alert moves through three statuses:

| Status                       | What it means                                                                                                                                                           | Who sets it                                                           |
| ---------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------- |
| **`OPEN`**                   | The alert is active. It shows on the entity's Alerts tab and, in the default (Open) global view, counts toward the **All / My Objects / Downstream / Upstream** badges. | The platform, when the alert is created.                              |
| **`RESOLVED`**               | An operator marked the alert resolved by hand — typically after fixing the underlying issue or judging it a false positive.                                             | An operator, via the `Resolve` action on the alert.                   |
| **`RESOLVED_AUTOMATICALLY`** | The platform itself resolved the alert because the condition that fired it has cleared (see below). No operator acted.                                                  | The platform, on the next ingest that observes the cleared condition. |

The two resolved statuses behave the same way — both clear the alert from open counts and stop notifications, and both drop the alert out of the **default (Open)** global view across the **All / My Objects / Downstream / Upstream** tabs. They are not gone, though: set the global **Status** filter to `RESOLVED` or `RESOLVED_AUTOMATICALLY` (or open the entity's own Alerts tab) to bring them back. The distinction between the two resolved statuses is preserved on the alert record and in the [Activity Feed](/features/active-platform-features/activity-feed), so you can tell whether an alert was worked on or simply cleared itself. Auto-resolution events are recorded as system events on the feed; manual resolutions carry the operator's identity.

### Auto-resolution triggers

Auto-resolution applies to **`Failed job`** and **`Failed data quality test`** alerts only. The other two alert types — `Backwards incompatible schema change` and `Distribution anomaly` — never auto-resolve and stay `OPEN` until an operator resolves them by hand.

The trigger is the next ingest that reports a **successful** run for the same task on the same entity:

* If a job that previously failed succeeds on its next run, the open `Failed job` alert for that entity flips to `RESOLVED_AUTOMATICALLY`.
* If a data-quality test that previously failed passes on its next run, the open `Failed data quality test` alert for that test flips to `RESOLVED_AUTOMATICALLY`.

A subsequent failure opens a **new** alert; auto-resolved alerts are not reopened.

{% hint style="info" %}
**Manual reopen has a guard.** An operator can reopen a `RESOLVED` or `RESOLVED_AUTOMATICALLY` alert by sending its status back to `OPEN` (`PUT /api/alerts/{alert_id}/status`) — but only if there is **no other open alert of the same type** on the same data entity. The platform refuses the reopen with `Cannot reopen alert since the system already has an open alert of the same type`. Resolve or work the newer alert first, or leave the old one closed.
{% endhint %}

### Auto-cleanup of resolved alerts

Resolved alerts do not accumulate forever. The platform's housekeeping job **permanently deletes** resolved alerts — **both** manually resolved (`RESOLVED`) and auto-resolved (`RESOLVED_AUTOMATICALLY`) — whose status-update timestamp is older than `housekeeping.ttl.resolved_alerts_days` (default `30` days). The chunk records attached to each alert are deleted along with it — this is a hard delete, not a soft one, so once the window passes the alert is gone from the database. The two resolution kinds are treated **symmetrically**: a freshly resolved alert (manual or automatic) lives its full retention window before it becomes eligible for deletion.

To change the retention window, see [Housekeeping Settings Configuration](/configuration-and-deployment/odd-platform#housekeeping-settings-configuration). Raise the value before resolved alerts age out if you need a longer audit trail; once deleted, alerts cannot be recovered.

{% hint style="info" %}
**Both manual and automatic resolutions respect `resolved_alerts_days`.** The cleanup predicate is `(status = RESOLVED OR status = RESOLVED_AUTOMATICALLY) AND status_updated_at <= cutoff`, so an alert is purged only after it has been resolved for longer than the window — there is no asymmetry between the two resolved states. (An earlier revision of this page described a manual-resolution retention bug from reading the job's jOOQ predicate as raw SQL precedence; that is not how the platform behaves — verified against the running job. The one real footgun is leaving `resolved_alerts_days` **unset** under a partial `housekeeping.ttl` override: an unset value binds to `0`, which deletes resolved alerts immediately — always set it explicitly, as the shipped default does.)
{% endhint %}

#### Reading the per-entity alert history — endpoint notes

The per-entity Alerts tab reads through `GET /api/dataentities/{data_entity_id}/alerts/list` (Period + Status filterable), and `GET /api/dataentities/{data_entity_id}/alerts/list?size=…` is also the path operators script when exporting an entity's alert history for a compliance archive or a postmortem. That read path has three properties that materially affect how operators must use it:

* **Pagination defaults silently truncate.** The endpoint accepts `page` and `size` query parameters but has no `@Min` / `@Max` validation and no `minimum` / `maximum` in the OpenAPI declaration. A small page size or a forgotten `size=` parameter silently caps the export; operators preserving the full audit history before a compliance-driven manual-resolve cycle should pass an explicit large value (e.g., `size=1000`) and continue paginating until the page is short. Default values can truncate without warning.
* **The read is inclusive of soft-deleted entities.** The endpoint reads through `existsIncludingSoftDeleted`, which returns alert history for entities whose own `status` is `DELETED`. Soft-deleted entities are hidden from the catalog's list surfaces but their alert history is still readable through this endpoint — useful for forensic recovery, surprising to operators who assume soft-delete extends to the alert-history layer.
* **There is no per-owner scoping at the endpoint layer.** The per-entity repository query has no `OWNERSHIP` join (contrast with the `My Objects` global view, which restricts to entities the signed-in user owns). Any authenticated user reads any data entity's alert history through this endpoint, regardless of which owners are linked to the entity. Operators reasoning about "per-team alert visibility" cannot enforce it at this URL today.

(Bulk-resolve and a UI export affordance are still absent — there is no "resolve all" control and no download button on either the global or per-entity Alerts surface; resolve alerts one at a time, and script the listing endpoints above when you need the data out of the platform.)

## Backwards-incompatible schema change — what triggers it

`Backwards incompatible schema change` is the alert type that fires when a producer drops something a downstream consumer was relying on. The platform compares the **previously-ingested** version of an entity to the **latest** ingest and raises this alert whenever any of three classes of removal is detected. **Adding** fields, sources, targets, or inputs is not a backwards-incompatible change and does not trigger an alert. For the user-facing diff surface (where every column add / remove / type change is rendered on the dataset's Structure tab, alert or not), see [Schema diff](/features/data-discovery/schema-diff).

The three detection paths:

| Entity class    | What triggers an alert                                                                                                           | Detail                                                                                                                                                                                                 |
| --------------- | -------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| **Dataset**     | A field that existed in the previous version is no longer present in the latest version, **or** a field's data type has changed. | Fields are compared by `(oddrn, type)`. Removing a column, renaming it (the new name produces a different ODDRN), or changing its type all surface the alert with the message `Missing field: {name}`. |
| **Transformer** | A source or target ODDRN that the transformer previously listed is no longer in its current source/target list.                  | Reported as `Missing source: {oddrn}` or `Missing target: {oddrn}`.                                                                                                                                    |
| **Consumer**    | An input ODDRN that the consumer previously listed is no longer in its current input list.                                       | Reported as `Missing input: {oddrn}`.                                                                                                                                                                  |

{% hint style="info" %}
**The first ingest of an entity never fires this alert.** Detection requires a previous (penultimate) version to compare against — there is nothing to "remove" relative to a non-existent prior state. Operators wiring up a new pipeline will see this alert begin to fire only from the second ingest onward.
{% endhint %}

`Backwards incompatible schema change` alerts do **not** auto-resolve — once raised they stay `OPEN` until an operator resolves them by hand. See [Alert lifecycle](#alert-lifecycle-statuses-resolution-cleanup) for the full lifecycle.

## Halt notifications per entity

Alert traffic on a single noisy data entity — a flaky job, an unstable test, a frequently re-shaping dataset — can drown out the rest of the queue. ODD lets owners **halt** notifications on one entity at a time, scoped per alert type, for a fixed duration. The halt is a temporary mute; the underlying detection pipeline keeps running, and notifications resume automatically when the timer expires.

Halts are configured from the entity's `Notification Settings` button. Each of the four alert types is toggled independently — you can mute "Failed data quality test" for a dataset that's actively being repaired while keeping "Backwards incompatible schema" alerts firing for the same entity:

| Alert type toggle                        | What it suppresses                                                                                                                                                                                                               |
| ---------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Backwards incompatible schema change** | New schema-drift alerts during the halt window.                                                                                                                                                                                  |
| **Failed data quality test**             | New alerts from quality-test failures.                                                                                                                                                                                           |
| **Failed job**                           | New alerts from job-run failures.                                                                                                                                                                                                |
| **Distribution anomaly**                 | *Currently unenforced — see* [*known limitation*](#distribution-anomaly-halt-is-currently-unenforced) *below. The toggle is exposed on the UI and persisted by the API, but the AlertManager webhook bypasses halt enforcement.* |

For each toggle, pick one of five durations:

* **Half an hour** (30 minutes)
* **Hour** (60 minutes)
* **3 hours**
* **1 day**
* **Week** (7 days)

The platform stores the halt as a future timestamp per alert type; once that timestamp passes, the toggle re-enables on its own without operator action.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-51674368a23ae358be69ce6acc35795d90daed52%2Fmedium-1-BGX_9bvYqXEkjS-_W2Ze6g.png.png?alt=media" alt="" height="372" width="700"><figcaption><p>Turning specific notifications off</p></figcaption></figure>

{% hint style="info" %}
**Halts suppress new alerts only — they do not silence auto-resolution.** If an open `Failed job` alert is already firing on an entity and you halt that alert type, a subsequent successful run still flips the existing alert to `RESOLVED_AUTOMATICALLY` (see [Alert lifecycle](#alert-lifecycle-statuses-resolution-cleanup) above). Halts stop the **next new alert** of that type from being created; they don't freeze alerts already in flight.
{% endhint %}

The halt configuration is also exposed over the API — the `getAlertConfig` / `updateAlertConfig` endpoints, the four halt-timestamp field names, the ISO-8601 format requirement, the `null`-clears semantics, and the `ALERT_HALT_CONFIG_UPDATED` activity-feed event emission are all documented at [API Reference → Alerts → Per-entity halt-notification configuration](/developer-guides/api-reference/alerts).

### Distribution anomaly halt is currently unenforced

{% hint style="warning" %}
**The Distribution anomaly halt toggle has no effect on alert creation.** The toggle is exposed on the entity's `Notification Settings` UI and persisted by `PUT /api/dataentities/{data_entity_id}/alert_config`, but the AlertManager-driven path that creates Distribution Anomaly alerts (`POST /ingestion/alert/alertmanager` → the platform's external-alert handler) does not consult the halt config — new alerts continue to fire on a "halted" entity until the halt timer expires.

Until the platform fix lands, mute Distribution Anomaly noise at the **Prometheus Alertmanager** layer instead of relying on the per-entity halt — use a `silences` entry or a `route` matcher on the `entity_oddrn` label, or an `inhibit_rules` block in the Alertmanager configuration to suppress alerts while a parent condition is active.

The other three halt types (`Failed job`, `Failed data quality test`, `Backwards incompatible schema change`) are unaffected — their halts are enforced on the ingestion-driven alert-creation path.
{% endhint %}

## Known UX limitations

A handful of behaviours on the Alerts UI surface that operators encounter in normal use, all of them small individually but cumulative enough to warrant calling out. Each item below states what an operator might assume and what the UI actually does today.

* **A user without a user-owner association sees only the `All` tab — the cross-team feed.** The `My Objects`, `Downstream`, and `Upstream` tabs are hidden until the signed-in user is linked to an [Owner](/configuration-and-deployment/enable-security/authorization/user-owner-association), so the `All` tab is the *only* visible tab to such users, and the implicit framing is "alerts = platform-wide" rather than "alerts I can action." Set up the user-owner binding in **Management → Associations** to enable the `My Objects`, `Downstream`, and `Upstream` tabs.

{% hint style="info" %}
**Resolving or reopening an alert asks for confirmation, and the per-entity tab reflects the change without a refresh.** Clicking `Resolve` (or `Reopen`) opens a confirmation dialog before the status flips, so an accidental click no longer changes an alert's triage state; and on the entity's own Alerts tab the row updates in place the moment you confirm, rather than keeping the old status until a reload. The change is also recoverable: a resolved alert is retained for the full `resolved_alerts_days` window (see [Auto-cleanup of resolved alerts](#auto-cleanup-of-resolved-alerts)), so you can **Reopen** it before the window elapses.
{% endhint %}

* **The Notification Settings dialog has no optimistic-concurrency check.** Two operators editing the same entity's halt configuration in parallel both submit their edits; the second submission overwrites the first silently. There is no version field, no `If-Match` header, no "this configuration was changed by another user — reload?" warning. Coordinate halt-config changes externally (Slack ping before editing, change-management ticket) until the upstream concurrency guard ships.

## API surface

The platform's HTTP surface for alerts — the filterable global listing (`getAlertsList`) behind the **All / My Objects / Downstream / Upstream** tabs, the `getAlertCounts` badge call, the per-entity alert listing, the manual status-flip endpoint, and the halt-configuration endpoints (plus the now-deprecated legacy listing endpoints, kept working) — is documented at [API Reference → Alerts](/developer-guides/api-reference/alerts).

## Where to next

* For how alerts get out of the platform — Slack, email, generic webhook, the AlertManager inbound webhook → [Notifications](/features/active-platform-features/notifications).
* For the activity-feed events that record every alert state transition (`OPEN_ALERT_RECEIVED`, `RESOLVED_ALERT_RECEIVED`, `ALERT_STATUS_UPDATED`, `ALERT_HALT_CONFIG_UPDATED`) → [Activity Feed](/features/active-platform-features/activity-feed).
* For the operator-side configuration of the outbound alert-notification pipeline — `notifications.enabled`, the PostgreSQL logical-replication prerequisite, AlertManager setup → [Configure ODD Platform → Enable Alert Notifications](/configuration-and-deployment/odd-platform#enable-alert-notifications).


# Notifications

How alerts move in and out of ODD Platform — outbound through Slack incoming webhook, generic webhook, or SMTP email; inbound from Prometheus AlertManager as Distribution Anomaly alerts.

Notifications is the subsystem that moves alerts **across the platform's boundary** — out, through Slack, generic webhook, or SMTP email; or **in**, from a Prometheus AlertManager pushing distribution-anomaly events through the inbound webhook. Alerts the platform raises internally are described under [Alerting](/features/active-platform-features/alerting); this page is about the channels that connect those alerts to the rest of an operator's stack.

The subsystem is **disabled out of the box** — the outbound dispatcher needs `notifications.enabled=true` plus a configured PostgreSQL [logical-replication slot](/configuration-and-deployment/odd-platform#postgresql-configuration), and the inbound AlertManager webhook is gated by network reachability and, from 0.29.0, by `auth.ingestion.filter.enabled` (off by default). Each channel is independently configurable; deployments use whatever subset matches their on-call workflow.

For setup steps and the full key list, see [Configure ODD Platform → Enable Alert Notifications](/configuration-and-deployment/odd-platform#enable-alert-notifications) and [Configure ODD Platform → Prometheus AlertManager Integration](/configuration-and-deployment/odd-platform#prometheus-alertmanager-integration). This page is the user-facing description of what each channel does, what it carries, and what to know before enabling it.

## What an outbound notification carries

Every alert dispatched out of the platform carries:

1. The name of the entity the alert was raised on.
2. The data source and namespace of that entity.
3. The owners attached to that entity (see [Owners](/configuration-and-deployment/enable-security/authorization/owners)).
4. Affected downstream entities — the lineage neighbours within `notifications.message.downstream-entities-depth` levels (default `1`).

{% hint style="warning" %}
**`notifications.message.downstream-entities-depth` has no built-in fallback — omitting it from an externalized config fails startup.** The default of `1` ships in the platform's bundled `application.yml`, but the code that reads the key has **no in-code default**. If you supply your own externalized configuration (a mounted `application.yml`, a config map, environment-variable overrides) that turns notifications on without also setting this key, the platform does **not** fall back to `1` — it fails to start with a Spring "Could not resolve placeholder" error. Whenever you set `notifications.enabled=true` in an override config, set `notifications.message.downstream-entities-depth` alongside it.
{% endhint %}

Clickable links inside notification messages resolve back to the platform UI using the operator-set `odd.platform-base-url` — both the Slack and email senders consume that key. The generic webhook receiver does **not** consume `odd.platform-base-url`; it gets the full alert payload directly and is expected to construct any URLs it needs from that payload.

## Outbound channels

The platform supports three outbound channels. They can be enabled together or individually; an alert dispatched to multiple channels is delivered to every channel that is enabled.

### Slack incoming webhook

The platform POSTs a formatted alert message to a [Slack incoming webhook](https://docs.slack.dev/messaging/sending-messages-using-incoming-webhooks) URL. This is **outgoing-only** — there is no thread state, no reply ingestion, no per-channel routing logic; the platform writes one message per alert dispatch.

Configured by `notifications.receivers.slack.url`. The same Slack workspace can also host the bidirectional [Data Collaboration](/features/active-platform-features/data-collaboration) Slack app — the two integrations use different Slack mechanisms (incoming webhook vs OAuth + Events API) and are configured independently.

{% hint style="info" %}
**This is the alert webhook, not the Discussions Slack app.** The alerting Slack integration is a one-way `notifications.receivers.slack.url` POST — no replies, no thread state. The full Slack app used by [Data Collaboration](/features/active-platform-features/data-collaboration) is a separate integration via OAuth (`datacollaboration.slack-oauth-token`) and the [Slack Events API](https://docs.slack.dev/apis/events-api/). Each is configured separately; enabling one does not enable the other. See [Main Concepts → Terms & Aliases](/introduction/main-concepts#terms-and-aliases) for the side-by-side comparison.
{% endhint %}

{% hint style="warning" %}
**An alert burst can silently lose most Slack messages — the sender does not honour Slack's rate limit.** Slack throttles incoming webhooks (roughly one message per second per webhook) and returns HTTP 429 with a `Retry-After` header when you exceed it. ODD Platform's sender treats every response other than `200 OK` as the same generic failure: it does not read the status code class, does not read `Retry-After`, does not wait, and does not retry. A 429 is logged and the alert is dropped from Slack. When one event raises a burst of alerts at once — a single failed dbt run can produce dozens — the first message or two land and the rest are silently lost, even though the underlying alerts are still recorded in the platform.

**Mitigation today:** keep alert volume per Slack webhook low (route only the alert classes you act on to Slack), or fan alerts through the generic webhook to a receiver that buffers and rate-limits its own posts to Slack. Treat Slack as a best-effort heads-up channel, not the system of record for which alerts fired — the [Alerts list](/features/active-platform-features/alerting) is.
{% endhint %}

### Email (SMTP)

The platform sends a formatted alert email through an operator-supplied SMTP relay. Configured by the `notifications.receivers.email.*` family of keys (host, port, protocol, sender, password, recipient list, optional STARTTLS). The reference walkthrough using Gmail's SMTP is on the operator-side configuration reference at [Configure ODD Platform → Example: Gmail SMTP](/configuration-and-deployment/odd-platform#example-gmail-smtp).

The SMTP integration carries several JavaMail-default-driven limitations that operators should know before relying on it for production on-call:

{% hint style="warning" %}
**SMTP timeouts are unset — an unreachable SMTP server will hang notification delivery.** The JavaMail defaults for connection / read / write timeouts are infinite, and ODD Platform does not override them. An unreachable or stalling SMTP relay will block the notification thread until the TCP stack tears the connection down. Use a relay you can monitor for availability separately from ODD.
{% endhint %}

{% hint style="danger" %}
**Silent partial delivery if one recipient fails.** The email sender iterates through `notifications.receivers.email.notification.emails` recipient by recipient; if recipient N fails (bad address, mailbox full, server-side rejection), the loop stops — recipients N+1, N+2, … never receive the alert. There is no retry and no partial-failure metric. Keep the recipient list short and use distribution lists on the SMTP side for fan-out.
{% endhint %}

{% hint style="danger" %}
**The `protocol` value must be lowercase `smtp` — `SMTP` silently disables AUTH and STARTTLS.** The platform compares the configured `notifications.receivers.email.protocol` against the exact lowercase string `smtp`. Only on that exact match does it apply your `smtp.auth` and `smtp.starttls` settings to the mail session. Any other value — including `SMTP` in uppercase — falls through to a branch that sets the transport protocol verbatim and **applies neither AUTH nor STARTTLS, regardless of how you configured them**. There is no startup warning: the platform boots cleanly, then either fails authentication against the relay or sends credentials over an unencrypted connection. Write `protocol: smtp` in lowercase, and copy the Gmail example exactly as written rather than retyping it.
{% endhint %}

The full set of email-side caveats (only STARTTLS supported, self-signed cert workaround, non-ASCII charset issue) lives on [Configure ODD Platform → Enable Alert Notifications → Known limitations](/configuration-and-deployment/odd-platform#known-limitations) — operators authoring the SMTP configuration should walk through that section before enabling the channel.

### Generic webhook

The platform POSTs the full alert payload (JSON) to an operator-supplied URL. Configured by `notifications.receivers.webhook.url`. Use this when you want to fan alerts into a tool the platform doesn't natively integrate with — your own incident-management system, an HTTP-driven on-call tool, a custom consumer that fans further to other channels.

Unlike the Slack and email senders, the generic webhook does **not** consume `odd.platform-base-url` — the receiver is expected to extract any URLs it needs from the alert payload itself.

## Inbound channel — Prometheus AlertManager webhook

In addition to the alerts the platform raises from its own ingestion / evaluation pipeline, ODD exposes an **inbound** webhook that accepts [Prometheus AlertManager](https://prometheus.io/docs/alerting/latest/alertmanager/) notifications. Each accepted alert becomes a **Distribution Anomaly** alert on the referenced data entity, indistinguishable from internally-raised alerts from there on (it shows on the Alerts section, on the entity's page, and in the activity feed).

The alert type is **always Distribution Anomaly**, regardless of what the AlertManager-side rule is about. The platform reads only the `entity_oddrn` label, the `generatorURL`, and the timestamp from each alert; it does **not** read `alertname`, `severity`, or any other label to choose a type. A rule named `DiskFillingUp` or `LatencySpike` still lands as a Distribution Anomaly alert. Treat this webhook as a generic "raise an alert on this entity" channel, not as a typed bridge that preserves your Prometheus alert taxonomy.

The endpoint is `POST /ingestion/alert/alertmanager`; the platform reads `alerts[].labels`, `alerts[].generatorURL`, and `alerts[].startsAt` from the AlertManager webhook body and ignores other top-level fields. The full payload shape, the AlertManager `route`/`receivers` example, the rule-side label requirement, and the authentication caveat live on [Configure ODD Platform → Prometheus AlertManager Integration](/configuration-and-deployment/odd-platform#prometheus-alertmanager-integration).

{% hint style="warning" %}
**The `entity_oddrn` label is required.** The platform reads `alerts[].labels["entity_oddrn"]` to attribute each inbound alert to a data entity. Alerts pushed without this label end up orphaned — stored, but not surfaced on any entity page. Configure your AlertManager route or your alerting rules to always include the target entity's ODDRN as a label. Configuring `entity_oddrn` on every alert this webhook receives is the operator's responsibility; the platform does not synthesise it.
{% endhint %}

{% hint style="warning" %}
**Inbound alerts are not de-duplicated — each POST creates a new alert row.** The in-platform alerting pipeline collapses repeated signals into a single open alert, but the AlertManager webhook does **not** go through that de-duplication path: every payload it accepts is inserted as-is, with no uniqueness check. AlertManager re-sends an active alert at its configured `repeat_interval`, so the same firing alert delivered three times produces three duplicate OPEN alert rows on the same entity. Tune the AlertManager route's `repeat_interval` high (or route only `resolved`/first-fire notifications to ODD) to limit duplication, and expect to see repeated rows for a long-firing alert until this is de-duplicated upstream.
{% endhint %}

{% hint style="danger" %}
**The AlertManager webhook is unauthenticated.** ODD Platform whitelists the entire `/ingestion/**` namespace at the Spring Security layer, and the ingestion auth filter (`auth.ingestion.filter.enabled`) only guards `POST /ingestion/entities` — it does **not** cover this AlertManager endpoint. Anyone with network reach to the platform can POST arbitrary alerts on any entity ODDRN they can guess. Protect the endpoint at the perimeter: a private network, a NetworkPolicy in Kubernetes that admits only the AlertManager pod, an authenticating reverse proxy, or mTLS termination at the load balancer. See [Configure ODD Platform → AlertManager Integration → Authentication](/configuration-and-deployment/odd-platform#authentication) for the recommended controls.
{% endhint %}

## Setting up notifications

The full step-by-step — the PostgreSQL replication prerequisites (`max_wal_senders`, `wal_level`, `max_replication_slots`, the `REPLICATION` role grant, AWS RDS specifics), the `notifications.*` configuration keys, the YAML and environment-variable formats, the Gmail SMTP example, and the AlertManager receiver / rule example — lives on [Configure ODD Platform → Enable Alert Notifications](/configuration-and-deployment/odd-platform#enable-alert-notifications) and [Configure ODD Platform → Prometheus AlertManager Integration](/configuration-and-deployment/odd-platform#prometheus-alertmanager-integration). Operators wiring up notifications work from those two sections — this page is the orientation surface, not the configuration reference.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-ea746550700619de367bd2e46b5c102a649967ef%2Fmedium-1-YwExRitevtMLioP3HKCorQ.png.png?alt=media" alt="" height="372" width="700"><figcaption><p>Email notification example</p></figcaption></figure>

## Disabling notifications

Set `notifications.enabled=false` to stop the platform from dispatching outbound notifications. The PostgreSQL replication slot and publication created by the platform persist after the toggle flips — clean them up explicitly to avoid the database holding WAL indefinitely. The cleanup SQL plus the SQL-injection-safe steps live on [Configure ODD Platform → Enable Alert Notifications → Cleaning up](/configuration-and-deployment/odd-platform#cleaning-up).

Disabling outbound notifications does **not** disable the AlertManager inbound webhook. By default the inbound endpoint is gated only by network reachability; from 0.29.0, `auth.ingestion.filter.enabled=true` additionally requires a token on it (see [Prometheus AlertManager Integration → Authentication](/configuration-and-deployment/odd-platform#prometheus-alertmanager-integration)). To stop accepting inbound AlertManager events, enable that flag, remove the AlertManager-side receiver pointing at the platform, or block the perimeter route to `/ingestion/alert/alertmanager`.

## Known operational caveats

The Notifications subsystem carries several operational behaviours that are non-obvious until they surface in production. Each item below states what an operator might assume, what the platform actually does, and what to do today.

{% hint style="danger" %}
**A single un-translatable alert row blocks all subsequent outbound notifications indefinitely.** The WAL subscriber reads each PostgreSQL logical-replication event, decodes it, and hands it to the message processor; the platform advances the replication slot's `AppliedLSN` / `FlushedLSN` **only after the processor returns normally**. The processor's per-channel send loop *does* catch send failures (a Slack timeout or a webhook 500 is logged and skipped) — but before that loop runs, the processor first **translates** the raw WAL row into a notification message, and that translation step is **not** wrapped in any error handling. Translation throws on an alert row it cannot interpret — an unknown alert-type code, a missing or duplicated alerted-entity row, or an alert pointing at a data entity that has since been hard-deleted. That exception propagates up, the LSN is not advanced, and the next subscriber loop re-reads the same WAL position — replaying the same poison row forever.

Operators see notifications silently stop. There is no error at any HTTP surface, but the failure is **not** invisible: the subscriber logs `Error occurred while subscribing` with the full stack trace, then sleeps and retries, so the same trace repeats in the platform logs every \~10 seconds. The slot lag also grows: query PostgreSQL's `pg_replication_slots` and inspect `confirmed_flush_lsn` against the current LSN.

**Mitigation today:** watch the platform logs for a repeating `Error occurred while subscribing` stack trace, and monitor the lag on the logical-replication slot (`pg_replication_slots.confirmed_flush_lsn` against the current LSN). If the slot lag grows while the catalog is otherwise idle, the subscriber is stuck on a poison row — the first repeating stack trace names the row that cannot be translated. The upstream fix is to wrap the translation step so an un-translatable event is quarantined and the LSN advanced past it.
{% endhint %}

{% hint style="warning" %}
**A failing email channel can silently abort delivery to Slack and the generic webhook on the same alert.** The dispatcher iterates the configured outbound senders and catches the typed `NotificationSenderException` from each — but the email sender wraps SMTP failures as a plain `RuntimeException`, which bypasses that catch and propagates up. If the iteration happens to place the email sender first and SMTP is failing, the dispatcher's fan-out aborts before reaching the Slack or generic-webhook senders. The same alert that would have reached your Slack channel silently never gets sent there.

**Mitigation today:** if you run multiple outbound channels and SMTP is your least-reliable one, monitor delivery parity between channels (the Slack channel should receive at least one message for every email message). The upstream fix is wrapping the email sender's SMTP failure in the typed exception the dispatcher catches.
{% endhint %}

{% hint style="info" %}
**The notification translator runs a downstream-lineage walk on every WAL event even with zero outbound channels configured.** The WAL-driven pipeline does not short-circuit when no senders are wired up: every alert / activity event triggers the recursive-CTE lineage walk that computes the affected downstream entities, even when the resulting `AlertNotificationMessage` would never be dispatched anywhere. For deployments with `notifications.enabled=true` but no `notifications.receivers.*` configured, this is pure database load with no operator benefit.

**Mitigation today:** if you are not using outbound notifications, set `notifications.enabled=false` and clean up the logical-replication slot per [Disabling notifications](#disabling-notifications). The upstream fix is a short-circuit when zero senders are configured.
{% endhint %}

{% hint style="warning" %}
**Failed deliveries are lost without trace — there is no idempotency key, no dead-letter queue, and no per-channel audit.** The dispatcher's per-sender `send` method returns `void`, so a partial failure (Slack succeeded, email failed) leaves no record of which channels did or did not receive a given alert. There is no retry, no replay, no per-channel delivery log, no metric distinguishing "the alert fired" from "the alert reached every channel." Operators who later ask "did Slack get the alert that was raised at 14:07?" have no platform-side answer.

**Mitigation today:** instrument delivery at the receiver — every outbound channel (Slack, the generic webhook, the SMTP relay) can record the inbound messages it receives. Cross-reference operator-side receiver logs against the alerts list (`GET /api/alerts/...`) to reconstruct which alerts reached which channel. The upstream fix is a delivery-status surface on the dispatcher SPI.
{% endhint %}

{% hint style="warning" %}
**Every outbound notification carries the affected entity's owner list verbatim — no redaction.** The "What an outbound notification carries" section above names owners and downstream-lineage entities as part of the payload; both are dispatched **as-is** to every configured channel. The owner display names that a Slack channel, a webhook receiver, or an SMTP relay sees are the same names operators see in the catalog UI. For multi-team deployments where owner identities are confidential (named consultants, intern accounts, hashed external user references), the notification fan-out is one place that information leaves the platform's trust boundary.

**Mitigation today:** scope your notification channels by team (one Slack workspace per team rather than a shared workspace; one webhook receiver per team rather than a shared one). The upstream fix is an opt-in PII redaction layer in the dispatcher.
{% endhint %}

{% hint style="danger" %}
**Slack notification bodies pass alert descriptions verbatim into Slack markdown — `@channel`, `<!here>`, and fake-link payloads render.** Each Slack notification embeds the alert chunk descriptions directly into a Slack `markdownText` block with no sanitisation. Operator-supplied alert descriptions, ingestion-supplied chunk text, and (most consequentially) the AlertManager-webhook-supplied `generatorURL` and description all reach Slack as live markdown. A description containing `<!channel>` triggers a workspace-wide broadcast; a description containing `<https://attacker.example|click here>` renders as a clickable link with attacker-controlled target text.

**Compound with the AlertManager webhook (see** [**Alerting → Inbound AlertManager webhook — operator caveats**](/features/active-platform-features/alerting#inbound-alertmanager-webhook-operator-caveats)**):** the AlertManager webhook is unauthenticated, accepts arbitrary `entity_oddrn` and `generatorURL` values from any caller with network reach, and the resulting alert flows straight into the Slack notification body. The combination is an **unauthenticated cross-tenant Slack-broadcast surface** — any caller who can reach the AlertManager endpoint can fire `@channel` to every Slack workspace integrated with the platform.

**Mitigation today:** restrict the AlertManager webhook at the network layer (see the alerting page caveat) AND scope the Slack incoming webhook URL to a low-blast-radius channel (not `#general`, not a channel with mass notification settings). Until the upstream sanitisation lands, treat the alert description as an untrusted-input surface that lands in Slack with no filter.
{% endhint %}

{% hint style="warning" %}
**The generic webhook is unsigned — receivers cannot verify the payload came from the platform.** The webhook sender issues a plain `POST` to the configured URL with the alert payload as JSON. There is no `Authorization` header, no `X-ODD-Signature` HMAC, no shared-secret challenge — anyone who knows the receiver URL can `POST` an arbitrary payload that the receiver cannot distinguish from a legitimate platform notification.

**Mitigation today:** host the generic webhook receiver inside a private network not reachable from outside, or wrap the platform-side webhook URL behind a reverse proxy that adds an HMAC header before forwarding the request. The upstream fix is a configurable shared-secret + HMAC signature header on every outbound webhook POST.
{% endhint %}

## Where to next

* For the alert types the platform raises internally (failed jobs, failed DQ tests, schema drift, distribution anomalies) and the alert lifecycle (`OPEN`, `RESOLVED`, `RESOLVED_AUTOMATICALLY`) → [Alerting](/features/active-platform-features/alerting).
* For the operator-side configuration keys, the PostgreSQL replication prerequisites, and the SMTP / AlertManager caveats → [Configure ODD Platform → Enable Alert Notifications](/configuration-and-deployment/odd-platform#enable-alert-notifications) and [Configure ODD Platform → Prometheus AlertManager Integration](/configuration-and-deployment/odd-platform#prometheus-alertmanager-integration).
* For the activity-feed events that record alert state transitions (`OPEN_ALERT_RECEIVED`, `RESOLVED_ALERT_RECEIVED`, `ALERT_STATUS_UPDATED`, `ALERT_HALT_CONFIG_UPDATED`) → [Activity Feed](/features/active-platform-features/activity-feed).


# Activity Feed

ODD Platform records every metadata change as a typed event on a global Activity feed and on per-entity Activity tabs — the catalog's audit trail and change-driven discovery surface.

Track changes to your data entities by monitoring the global **Activity** page or the **Activity** tab on a data entity's detail page. Every metadata edit the platform observes — entity lifecycle transitions, ownership changes, tag and term assignments, dataset-field edits, alerts — emits a typed event onto the feed. The feed is the catalog's audit trail and the change-driven discovery surface: who did what to which entity, and when.

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-27f591c1c17c0c6bd7555ce1713f02dc8d32ef42%2Factivity.gif?alt=media)

## Where to find it

* **Global Activity page** — top-level `Activity` entry in the platform's navigation. Shows every event across the catalog with an eight-facet filter panel (see below) and a four-tab axis (`All` / `My Objects` / `Upstream Dependents` / `Downstream Dependents`).
* **Per-entity Activity tab** — every data-entity detail page has an `Activity` tab that scopes the feed to events on that entity only (plus a few additional internal event types — entity overview / metadata / schema / relation updates and custom-metadata create / update / delete — that are recorded on the per-entity tab but hidden from the global filter to keep that view concise). The per-entity tab does **not** carry the four-tab axis the global page exposes — see [Per-entity Activity tab differences](#per-entity-activity-tab-differences) below for the asymmetries you'll hit if you navigate between the two.

## My Objects setup (user-owner association prerequisite)

The `My Objects`, `Upstream Dependents`, and `Downstream Dependents` tabs on the global Activity page narrow the feed to entities the signed-in user is bound to as an [Owner](/configuration-and-deployment/enable-security/authorization/owners). The binding lives in the platform's `user_owner_mapping` table; without a row in that table the platform cannot answer the question "what changed on the things you own" — the three personalised tabs silently render an empty feed.

The binding is created in **Management → Associations** and the workflow is documented at [Authorization → User-owner association](/configuration-and-deployment/enable-security/authorization/user-owner-association). The same prerequisite applies to the [Alerts → My Objects](/features/active-platform-features/alerting) tab.

{% hint style="info" %}
**Pre-flight checklist for platform admins.** If you are setting up Roles, Policies, and Owners for other people and your own `My Objects` tabs (here on Activity, on Alerts, on the recommended entities surface) render empty even though the catalog is populated, you likely have **no `user_owner_mapping` for your own account**. Adding yourself as an owner on the entities you want surfaced — Management → Associations → Create association — fixes the silent-empty failure mode without changing anyone else's access.
{% endhint %}

## Filters on the global Activity page

The Filters panel on the Activity page lets you narrow the feed by eight facets:

* **Calendar** — restrict to a date / date-range window.
* **Datasource** — limit to events on entities from a specific datasource.
* **Namespace** — limit to events on entities in a given namespace.
* **Event type** — pick a single event type from the enumeration in the next subsection (e.g. `OWNERSHIP_CREATED`, `OPEN_ALERT_RECEIVED`).
* **Tag** — show events on entities carrying one or more selected tags (multi-select).
* **Owner** — show events on data entities owned by one or more selected owners (multi-select) — the owner of the **affected asset**, not the person who made the change. Useful for "what happened to my team's data this week".
* **Made by (owner)** — show events **performed by** users currently associated with one or more selected owners. ODD maps each user to an [Owner](/configuration-and-deployment/enable-security/authorization/user-owner-association), and this facet uses that *current* association — so re-associating an owner changes which past events match. The dropdown lists Owners.
* **Made by (user)** — show events **performed by** one or more selected users, identified by their external username (the `created_by` actor recorded on each event). This is **immutable** — it always reflects who actually made the change — and it works even for users with **no** owner association. The dropdown lists the usernames seen in the feed.

{% hint style="info" %}
**Owner, Made by (owner), and Made by (user) answer three different questions** — the owner of the affected *asset*, the *current* owner associated with whoever made the change, and the *immutable* external username of whoever made the change. Each facet carries an **ⓘ** help tooltip that spells out exactly what it matches, and the **Made by (user)** dropdown lists the raw usernames (exactly the values it filters on). Every event row shows the **username** of whoever made the change plus, when that user has an owner association, their **current owner** (rendered as "alice — current owner: Team A"). The owner shown is the association *as of now*: ODD does not record the owner association at the time of the change, so an old event reflects the user's present owner — not necessarily who they were associated with when they made it.
{% endhint %}

## Event types

The **Event type** filter on the global Activity page exposes the following event types, grouped here by the area of the metadata they describe.

**Data entity lifecycle**

* `DATA_ENTITY_CREATED` – a data entity was created in the platform.
* `DATA_ENTITY_STATUS_UPDATED` – an entity's status changed (`UNASSIGNED`, `DRAFT`, `STABLE`, `DEPRECATED`, `DELETED`). This is the event to filter on to find entity deletions — there is no separate "deleted" event type.
* `BUSINESS_NAME_UPDATED` – the business name of an entity was edited.
* `DESCRIPTION_UPDATED` – the description of an entity was edited.

**Ownership**

* `OWNERSHIP_CREATED` – an owner was added to a data entity.
* `OWNERSHIP_UPDATED` – an owner's role on a data entity was changed.
* `OWNERSHIP_DELETED` – an owner was removed from a data entity.

{% hint style="warning" %}
**Owner changes on a Data Entity Group cascade to the group's members, but only the group emits an event — the member entities do not.** When you add or remove an owner on a [Data Entity Group](/features/data-discovery/groups-domains), the platform propagates that ownership to every member entity (each member silently gains or loses the owner). The feed records a single `OWNERSHIP_CREATED` / `OWNERSHIP_UPDATED` / `OWNERSHIP_DELETED` event on the **group**; the per-member ownership writes emit **no event**. An auditor asking "when did this child entity gain owner X" by reading the child's Activity tab sees nothing — the change has to be inferred from the parent group's event and its membership at that time. If you need a per-entity audit of cascaded ownership, reconstruct it from the group event plus the group's member list, or instrument it at the database layer.
{% endhint %}

**Tags and terms**

* `TAG_ASSIGNMENT_UPDATED` – tags on a data entity were added, removed, or changed. Carries before-and-after tag lists.
* `DATASET_FIELD_TAGS_UPDATED` – tags on a dataset field (column) were added, removed, or changed. Carries before-and-after tag lists.
* `TERM_ASSIGNMENT_UPDATED` – terms linked to a data entity were added, removed, or changed.

{% hint style="warning" %}
**Tag-change events are non-uniform across the three tag-assign endpoints.** Data-entity tag changes emit `TAG_ASSIGNMENT_UPDATED` and dataset-field (column) tag changes emit `DATASET_FIELD_TAGS_UPDATED` — both carry the full before-and-after tag lists; **term tag changes emit no activity event at all today**. An auditor querying "who changed which tags when" must compensate for term tag changes by polling the term's current tag list and diffing externally. See [Manual Object Tagging → Known limitations and operator caveats](/features/data-discovery/tagging#known-limitations-and-operator-caveats) for the full operator framing.
{% endhint %}

**Dataset fields (columns)**

* `DATASET_FIELD_VALUES_UPDATED` – enum values configured on a dataset field were edited.
* `DATASET_FIELD_DESCRIPTION_UPDATED` – a field's description was edited.
* `DATASET_FIELD_INTERNAL_NAME_UPDATED` – a field's internal (user-defined) name was edited.
* `DATASET_FIELD_TAGS_UPDATED` – tags on a dataset field were added, removed, or changed.
* `DATASET_FIELD_TERM_ASSIGNMENT_UPDATED` – terms linked to a dataset field were added, removed, or changed.

**Data entity groups**

* `CUSTOM_GROUP_CREATED` – a custom [data entity group](/features/data-discovery/groups-domains) was created.
* `CUSTOM_GROUP_UPDATED` – the members or metadata of a custom group were changed.

{% hint style="warning" %}
**DEG-membership mutations (add / remove an entity from a DEG) emit no Activity Feed event.** The `CUSTOM_GROUP_UPDATED` event above fires only when the DEG's own metadata (description, tags, owners, terms) is edited, not when the membership set changes. The two membership-write endpoints (`POST /api/dataentities/{id}/data_entity_group` + `DELETE /api/dataentities/{id}/data_entity_group/{group_id}`) emit nothing — `DATA_ENTITY_RELATION_UPDATED` exists in the enum but is a dead value not triggered by any code path today. Auditors querying activity for a DEG's membership history must instrument it externally. See [Data Entity Groups & Domains → Managing DEG Membership](/features/data-discovery/groups-domains#managing-deg-membership) for the operator workflow and the mitigation list.
{% endhint %}

**Alerts**

* `OPEN_ALERT_RECEIVED` – a new alert was opened for a data entity. Driven by the [Alerting](/features/active-platform-features/alerting) subsystem.
* `RESOLVED_ALERT_RECEIVED` – an existing alert was resolved.
* `ALERT_STATUS_UPDATED` – the status of an alert was changed manually.
* `ALERT_HALT_CONFIG_UPDATED` – the [per-entity alert halt configuration](/features/active-platform-features/alerting#halt-notifications-per-entity) was changed.

{% hint style="info" %}
The platform emits a few additional internal event types (entity overview / metadata / schema / relation updates) that are recorded on the entity's own Activity tab but are intentionally hidden from the global Activity filter to keep the feed concise.
{% endhint %}

{% hint style="warning" %}
**Custom-metadata mutations (create / update / delete a field value on an entity) emit no Activity Feed event today.** The `CUSTOM_METADATA_CREATED`, `CUSTOM_METADATA_UPDATED`, and `CUSTOM_METADATA_DELETED` values exist in the `ActivityEventTypeDto` enum, but no code path emits any of them — they are dead values, same shape as the `DATA_ENTITY_RELATION_UPDATED` DEG-membership case above. An entity's Activity tab will not show metadata-value changes. For compliance teams that need a who-changed-what-when audit on metadata mutations, instrument externally — see [Custom metadata → Known limitations](/features/data-discovery/custom-metadata#known-limitations-and-operator-caveats) and [Audit trail scope](/configuration-and-deployment/enable-security/audit-trail-scope) for the compensating-controls catalogue.
{% endhint %}

{% hint style="warning" %}
**Scope: the Activity Feed is structurally data-entity-only.** The activity table's primary foreign key — `activity.data_entity_id` — is `NOT NULL`, which means **every emitted event is anchored to a single catalog data entity**. RBAC mutations (Policy / Role / Permission CREATE / UPDATE / DELETE), Owner CRUD, Term CRUD, Namespace CRUD, Datasource registration, Collector token rotation, and the Integration Wizard's configuration writes have no data-entity to anchor against and therefore **cannot emit even if a future code change tried to annotate them**. The schema, not just the absence of `@ActivityLog` annotations, blocks platform-wide audit on the feed.

For compliance teams that need RBAC / lifecycle / configuration audit, this is the absence the platform-side instrumentation does not fill — operators wire external audit at the layer that **can** see the change: an API-gateway access log (records every authenticated mutation), the PostgreSQL WAL via `pgaudit` (records every SQL write), or the application log if the JVM is run with the appropriate framework. For the full audit-vs-no-audit picture and the compensating-controls catalogue, see [Audit trail scope](/configuration-and-deployment/enable-security/audit-trail-scope).
{% endhint %}

## Known caveats

A few behaviours of the Activity Feed are non-obvious from the page above. Each item below states what an operator might assume, what the platform actually does, and what to do today.

{% hint style="warning" %}
**By default, every authenticated user reads every entity's activity history.** The repository query behind the global feed has no per-owner predicate — the `All` tab is a cross-team feed. The `My Objects` / `Upstream Dependents` / `Downstream Dependents` tabs scope by entity-ownership (the entities the signed-in user is bound to as an Owner), not by actor-axis (events the signed-in user performed). Treat the Activity Feed as catalog-read-collaborative — anyone who can read the catalog can read every team's activity history. If your deployment requires per-team audit isolation, enforce it at the network perimeter rather than relying on platform RBAC on this surface.
{% endhint %}

{% hint style="warning" %}
**Under `auth.type=DISABLED`, mutations are attributed to no actor and render visually identical to system events.** Anonymous callers under DISABLED mode trigger activity events whose `created_by` column is null; the UI shows these alongside the auto-resolved-alert-style "system event" lozenge. An auditor walking a DISABLED-mode feed cannot distinguish "anonymous user did X" from "platform did X." DISABLED mode is non-production by design (see [DISABLED authentication](/configuration-and-deployment/enable-security/authentication/disabled-authentication)); the Activity Feed's null-actor rendering is one more reason not to run DISABLED in production.
{% endhint %}

{% hint style="warning" %}
**A failure writing the activity event rolls back the change the operator was making.** The event is emitted inside the same database transaction as the metadata mutation that triggered it — the platform runs the originating write (an ownership change, a description edit, a tag assignment) and the activity-event insert atomically. If the activity insert fails for any reason (a transient database error, a connection drop mid-write), the **whole transaction rolls back**: the operator's change is reverted and the request returns `500` with no indication that the mutation was undone. This is the opposite of the usual "audit-or-warn" expectation — here the audit write is load-bearing for the mutation itself, not a fire-and-forget side channel. In practice this is rare and self-correcting (retry the edit), but operators debugging a "my change didn't stick and I got a 500" report should know the activity-feed write is in the critical path.
{% endhint %}

## Per-entity Activity tab differences

The per-entity `Activity` tab on a data-entity detail page exposes a smaller filter surface than the global Activity page does:

| Feature                                        | Global Activity page                                                   | Per-entity Activity tab                                   |
| ---------------------------------------------- | ---------------------------------------------------------------------- | --------------------------------------------------------- |
| Tab axis                                       | `All` / `My Objects` / `Upstream Dependents` / `Downstream Dependents` | None — the tab is implicitly "all events for this entity" |
| Calendar filter                                | Yes                                                                    | Yes                                                       |
| Event type filter                              | Yes                                                                    | Yes                                                       |
| Made by (owner) filter (actor's current owner) | Yes                                                                    | Yes                                                       |
| Made by (user) filter (external username)      | Yes                                                                    | Yes                                                       |
| Datasource / Namespace / Tag / Owner filters   | Yes                                                                    | No (the entity is already fixed)                          |

The per-entity tab is the right surface for "what changed on this one entity, in this window" investigations; the global page is the right surface for "what changed across the catalog this week."

{% hint style="warning" %}
**The per-entity Activity tab is reachable for any data entity, including soft-deleted ones.** The route mounts without a permission gate or status-restriction; the underlying read endpoint applies no per-owner scoping. Any authenticated user can navigate to `/dataentities/{id}/activity` for any catalogued entity, and the tab returns the audit history even when the entity's status is `DELETED` (the catalog list endpoints hide soft-deleted entities, but the activity tab does not). Multi-tenant deployments expecting per-team isolation on entity-level audit history cannot enforce it on this surface today. The same cross-channel read posture applies to other per-entity read surfaces (see [Search and Filtering → Facet aggregators](/features/data-discovery/search#facet-aggregators-enumerate-cross-owner-data-by-default) for the wider pattern).
{% endhint %}

## Auto-resolved alert events

Auto-resolution events emitted from the [Alerting](/features/active-platform-features/alerting) subsystem are recorded as system events on the feed (no operator identity attached); manually-resolved alerts carry the operator's identity. This lets a reader walking the feed distinguish between alerts that were worked on by a human and alerts that simply cleared themselves on the next ingest.

## Configuration

Activity-feed **partitioning** is controlled by the platform-level setting [`odd.activity.partition-period`](/configuration-and-deployment/odd-platform#activity-feed-partitioning-odd-activity-partition-period) (default 30 days) on [Configure ODD Platform](/configuration-and-deployment/odd-platform). The key sets the **width** of each time partition on the `activity` table — it controls how the data is chunked, not how long it is kept. Adjust the partitioning cadence per the volume your deployment generates — the operator-side reference is the canonical home for this key.

{% hint style="warning" %}
**`odd.activity.partition-period` is not a retention window — the Activity Feed has no automatic deletion and grows without bound.** The setting governs only the size of each table partition; the platform creates new partitions as time advances but never drops a partition that holds activity rows. The single housekeeping job that touches activity partitions drops only *empty* past partitions, which is a near-no-op on any steadily-used deployment. There is no `activity`-table entry in the platform's TTL configuration (unlike resolved alerts, search facets, and soft-deleted entities, which each have a housekeeping TTL). On a busy catalog the `activity` table grows monotonically; plan for it in your PostgreSQL capacity, and if you need to reclaim space, prune old partitions out-of-band at the database layer. Shrinking `partition-period` makes each partition smaller (so out-of-band pruning is finer-grained) but does not introduce any automatic deletion.
{% endhint %}

## Where to next

* For the alert events that source four of the feed's event types → [Alerting](/features/active-platform-features/alerting).
* For per-entity user-authored discussion threads (a per-entity event stream complementary to this system-emitted one) → [Data Collaboration](/features/active-platform-features/data-collaboration).
* For the data-entity-group events that power the catalog's group view → [Data Entity Groups & Domains](/features/data-discovery/groups-domains).
* For the activity-feed partition setting → [Configure ODD Platform → Activity-feed partitioning](/configuration-and-deployment/odd-platform#activity-feed-partitioning-odd-activity-partition-period).


# Data Collaboration

In-app discussion threads anchored to specific data entities, with replies tracked back from a Slack workspace via OAuth + the Slack Events API. Per-entity scope; opt-in.

ODD Platform's **Data Collaboration** feature lets users start in-app discussions about a specific data entity, with replies tracked back into the platform from a messenger. Conversations stay attached to the entity that anchored them, so an operator returning to a dataset months later can read the original threads — context, decisions, and follow-ups — without leaving the catalog.

The feature is exposed as a **Discussions** tab on every data entity's detail page (per-entity scope; not a global hub). At the moment Slack is the only supported messenger; integration with other providers would extend the same per-entity threading model.

The feature is **disabled by default** (`datacollaboration.enabled=false`). When disabled, every `/api/datacollaboration/...` route plus the `/api/slack/events` webhook return `404 Not Found` — the controllers are gated by `@ConditionalOnDataCollaboration`.

{% hint style="warning" %}
**The Discussions tab is visible even when Data Collaboration is disabled.** The tab itself is currently rendered regardless of the flag (only hidden when the entity status is deleted). On a deployment that has not configured Data Collaboration the tab is visible but its content fails to load — operators who do not plan to enable the feature should be aware of this until the platform gates tab visibility on the flag.
{% endhint %}

## How a discussion flows

* A user opens the **Discussions** tab on a data entity, picks a Slack channel from the bot's autocomplete, and posts a thread-root message. The platform writes the message to its own message store and queues it for delivery into Slack.
* A background sender (`DataCollaborationMessageSenderJob`) drains the queue. Each message is retried up to `datacollaboration.sending-messages-retry-count` times (default `3`) before being marked failed.
* When a Slack user replies in the thread, Slack POSTs an `event_callback` to the platform's `/api/slack/events` webhook. The platform translates the reply into an in-platform message linked to the same data entity, and the new reply appears under the original thread on the Discussions tab.
* Per-entity history is queryable: thread-root messages and replies are paginated by entity ID. The platform retains its own copy of every message, so historical threads stay available even if the Slack channel rotates or the Slack workspace is migrated.

## Slack — the full Slack app, not the alert webhook

The Slack integration that powers Data Collaboration is a **full Slack app**, distinct from the outgoing webhook the [Notifications](/features/active-platform-features/notifications) subsystem uses for alert messages. The data-collaboration app uses OAuth (`datacollaboration.slack-oauth-token`) and the [Slack Events API](https://docs.slack.dev/apis/events-api/) to read replies back into the platform — bidirectional. The alerting Slack integration is a one-way [incoming webhook](https://docs.slack.dev/messaging/sending-messages-using-incoming-webhooks) that the platform POSTs alert messages to (`notifications.receivers.slack.url`) — no replies, no thread state.

An operator who has already set up the alert webhook still needs to set up the Slack app separately to enable Discussions; the two configurations are independent. See [Main Concepts → Terms & Aliases](/introduction/main-concepts#terms-and-aliases) for the canonical side-by-side comparison.

## Where to set it up

* **Operator setup** — config keys, the Slack app manifest, advisory-lock IDs, message-partition rationale, retry behavior: [Configure ODD Platform → Enable Data Collaboration](/configuration-and-deployment/odd-platform#enable-data-collaboration).
* **HTTP API** — the seven `/api/datacollaboration/...` routes plus the inbound `/api/slack/events` webhook contract, channel autocomplete, per-entity message paging: [API Reference → Data Collaboration](/developer-guides/api-reference/data-collaboration).

## Known operator caveats

The Data Collaboration surface — and specifically the Slack integration that powers it today — carries several behaviours that are non-obvious from the configuration reference and the feature description above. Each item below states what an operator might assume, what the platform actually does, and what to do today.

{% hint style="danger" %}
**The `POST /api/slack/events` webhook does not verify Slack request signatures — any internet caller can forge an event the platform will treat as Slack.** Slack's documented protocol mandates HMAC-SHA256 over the request body using the app's signing secret, delivered in the `X-Slack-Signature` header alongside `X-Slack-Request-Timestamp`. The platform's event-API controller reads the request body as a raw `Mono<String>` and dispatches it to the Slack event parser **without reading either header** — a code-side grep across the platform for `X-Slack-Signature`, `signing.secret`, `signingSecret`, `verifySignature`, and `HMAC.SHA256` returns zero matches. Any caller who can reach `/api/slack/events` over the network can `POST` a forged `event_callback` payload that the platform treats as a legitimate Slack reply, materialising arbitrary messages in the per-entity Discussions tab and triggering the same downstream processing as a real Slack delivery.

**Mitigation today.** Deploy the platform behind a reverse proxy that performs Slack HMAC-SHA256 verification on `/api/slack/events` before forwarding the request — typically a small middleware in front of an ingress controller or a dedicated Lambda-edge-style verifier. The upstream platform-side fix adds signature verification to the event-API controller itself; until it lands, the perimeter check is the only protection.
{% endhint %}

{% hint style="danger" %}
**Enabling Data Collaboration is the only access control on its routes — none of them carry an RBAC permission, and under `auth.type=DISABLED` the whole surface is anonymous.** There is no `TERM_*`-style permission for Data Collaboration: the platform's security-rule registry has no entry for the `/api/datacollaboration/...` routes or the per-entity message-history routes, so every one of them falls through to the global "any authenticated user" rule (the inbound webhook is allow-listed entirely, see the caveat above). On a `LOGIN_FORM`, `OAUTH2`, or `LDAP` deployment that means any logged-in user can post into and read every entity's discussions regardless of the Policy grants you have authored. On an `auth.type=DISABLED` deployment the global rule permits everyone, so flipping `datacollaboration.enabled=true` publishes the entire read-and-post surface to anonymous callers — the flag the feature description frames as the on/off switch is also, in that mode, the only thing between the internet and the discussion store.

**What to do.** Do not enable Data Collaboration on an internet-reachable deployment running `auth.type=DISABLED`. Run a real authentication mode, and combine it with the perimeter signature check above for the inbound webhook. Treat "Data Collaboration enabled" as "every authenticated user can use Discussions on every entity" when authoring roles — there is no per-entity or per-permission scoping today.
{% endhint %}

{% hint style="warning" %}
**The `datacollaboration.slack-oauth-token` bot OAuth token is the only thing standing between the platform and `chat:write` / `channels:read` / `channels:history` / `users:read` / `incoming-webhook` access on the Slack workspace.** The platform constructs a singleton Slack API client at boot from the token; the singleton is reused across every outbound Slack call for the platform's lifetime. Spring Boot masks **every** property value in `/actuator/env` by default (`show-values` defaults to `NEVER`), so the token value is not exposed there — but that masking is the only protection: there is no environment-variable rotation hook, no token-lifecycle integration, no fail-closed behaviour on Slack-side revocation. Any compromise of the platform process, the underlying config store, or a configured property value leaks **workspace channel enumeration plus post-as-bot capability across the bot's full OAuth scope**.

**Operator workflow.** Treat the OAuth token the same way you treat database credentials: store it only in your secrets manager (not in plaintext YAML), rotate it on a schedule, and restart the platform on every rotation so the singleton picks up the new value. If Slack-side revokes the token (admin action, app removal), the platform continues calling Slack with the revoked token until restart — there is no platform-side detection of revocation. After Slack-side revocation, restart the platform to surface the error and rotate to a fresh token.
{% endhint %}

{% hint style="warning" %}
**Slack delivers events at-least-once — the platform may materialise duplicate child messages for the same Slack thread reply.** Slack's Events API documents an at-least-once delivery contract; the platform writes incoming events to a `message_provider_event` table without a unique constraint on `(provider, event_id)` and inserts each event with a plain `INSERT` (no `ON CONFLICT` clause). A duplicate delivery for the same Slack `event_ts` inserts an additional row; the downstream message processor materialises an additional child message linked to the same per-entity thread. The retry section above describes the **outbound** retry behaviour; this caveat is about the **inbound** duplicate behaviour, which is a different mechanism.

**Operator-visible signal.** Two near-identical thread replies appearing seconds apart with the same author, text, and timestamp on the per-entity Discussions tab. The platform does not deduplicate them today; the upstream fix adds a unique constraint plus `ON CONFLICT DO NOTHING` on the event-insert path.
{% endhint %}

{% hint style="info" %}
**Slack channel autocomplete is cached for 60 seconds, matches on a prefix, and lists only channels the bot already belongs to.** The platform's Slack channel lookup uses a Caffeine async-loading cache keyed on a fixed sentinel, with `expireAfterWrite(1, MINUTES)`. When an operator invites the platform's bot to a new Slack channel, the channel becomes reachable from the bot's perspective immediately on the Slack side — but the platform's autocomplete continues to return the cached list (which does not include the new channel) for up to 60 seconds. After the cache TTL expires, the next autocomplete request triggers a fresh fetch and the channel appears.

Two further behaviours shape what the autocomplete shows. The typed filter is a **prefix** match (`startsWith`), not a substring match — typing the middle of a channel name returns no suggestions, so users must type from the start of the channel name. And the list only includes **public channels the bot has been added to**; private channels, DMs, and archived channels are never offered, so a channel that is missing from the picker usually means the bot has not been invited to it.

If you cannot wait 60 seconds (operator demo, time-sensitive setup), restarting the platform forces the cache to rebuild on first call.
{% endhint %}

## Where to next

* For the Slack alert webhook (a different Slack integration on the same workspace) → [Notifications → Slack incoming webhook](/features/active-platform-features/notifications#slack-incoming-webhook).
* For the system-driven per-entity event stream the platform emits alongside user-authored discussion messages → [Activity Feed](/features/active-platform-features/activity-feed).
* For the canonical side-by-side comparison of the two Slack integrations → [Main Concepts → Terms & Aliases](/introduction/main-concepts#terms-and-aliases).


# GenAI assistant

GenAI assistant — proxy natural-language questions to an external AI service. API-only today; configuration, contract, and operator caveats.

The **GenAI assistant** is an opt-in feature that lets the ODD Platform proxy natural-language questions to an **external AI service** that the operator deploys and operates separately. The platform itself does not embed an LLM; it forwards the question, waits for a response, and returns it through its API.

The feature is **disabled by default** (`genai.enabled: false`) and is **API-only today** — the generated TypeScript client (`GenaiApi.ts`, `GenAIRequest.ts`, `GenAIResponse.ts`) ships with the platform UI, but no in-app affordance currently calls it. Operators who turn this on either drive it from their own UI / scripts against the platform's `/api/genai/ask` endpoint, or wait for a future UI surface.

## What gets proxied

Each call from the operator → platform → external AI service has this shape:

```
[client] → POST /api/genai/ask  (JSON: {"body": "<question text>"})
              → platform forwards to: POST {genai.url}/query_data
                                       (JSON: {"question": "<question text>"})
              ← external service returns raw JSON-encoded string
              ← platform un-quotes + Java-unescapes, returns JSON: {"body": "<answer>"}
[client] ← 200 OK (JSON: {"body": "<answer>"})
```

The platform does not modify the question text it forwards (just rewraps it from `body` → `question`). Any catalog context, retrieval-augmentation, or prompt construction must happen inside the external AI service — the platform is a thin proxy.

## Configuration

The three `genai.*` keys (`enabled`, `url`, `request_timeout`), their defaults, the silent-misconfiguration warning when `enabled=true` is set without `url` and `request_timeout`, the working YAML / environment-variable example, and the platform-restart requirement when any of the three change all live on the operator-facing configuration reference at [Configure ODD Platform → GenAI Configuration](/configuration-and-deployment/odd-platform#genai-configuration). That page is the canonical home for the platform's configuration keys; this page links rather than embedding so the two surfaces never drift.

## External AI service contract

When `genai.enabled=true`, the platform's `genAiWebClient` is configured at startup with `baseUrl = genai.url` and `responseTimeout = Duration.ofMinutes(genai.request_timeout)`. Each call from `/api/genai/ask` forwards to the external service as:

* **Method:** `POST`
* **Path:** `{genai.url}/query_data` (the `/query_data` suffix is fixed in `GenAIServiceImpl.java:22`)
* **Headers:** none added by the platform (default WebClient headers; no auth, no API key)
* **Request body** (`application/json`):

  ```json
  { "question": "<the question text from the GenAIRequest.body field>" }
  ```
* **Response body** (the platform expects `application/json`): a **raw JSON-encoded string** — that is, the response payload is a single JSON string value (with leading and trailing `"` quotes). The platform strips the outer quotes via `CharMatcher.is('"').trimFrom(item)` and then runs `StringEscapeUtils.unescapeJava(...)` to interpret embedded escape sequences (`\"`, `\n`, etc.) before placing the result in the `GenAIResponse.body` field.

A minimal-but-conforming AI service implementation in Python (Flask), for reference:

```python
from flask import Flask, request, jsonify
import json

app = Flask(__name__)

@app.post("/query_data")
def query_data():
    payload = request.get_json(force=True)
    question = payload["question"]
    # ... your AI / RAG / LLM call here ...
    answer = my_ai_pipeline(question)
    # Return a raw JSON-encoded string. The platform expects to read this with
    # bodyToMono(String.class) and trim the surrounding quotes; jsonify wraps
    # it correctly.
    return app.response_class(json.dumps(answer), mimetype="application/json")
```

{% hint style="info" %}
The platform sends **no authentication** to the external service. If the service must reject anonymous traffic, deploy it behind a network policy / mesh / ingress that authenticates / restricts callers — there is no `genai.token` or similar in `GenAIProperties` today. The external service is also fully responsible for prompt construction, catalog-aware retrieval, and rate limiting; the platform forwards questions verbatim and returns whatever the service returns.
{% endhint %}

## Platform endpoint

The platform's GenAI surface is a single endpoint:

| Method | Path             | Operation ID    | Purpose                                                                         |
| ------ | ---------------- | --------------- | ------------------------------------------------------------------------------- |
| `POST` | `/api/genai/ask` | `genAiQuestion` | Forward a question to the configured external AI service and return its answer. |

Request schema (`GenAIRequest`):

```json
{ "body": "<question text>" }
```

Response schema (`GenAIResponse`):

```json
{ "body": "<answer text>" }
```

When `genai.enabled=false`, the endpoint responds with a `BadUserRequestException` carrying the message "Gen AI is disabled" (HTTP 400) — operators get a clear error rather than a silent no-op.

When the external service times out, the endpoint responds with a `GenAIException` carrying "Gen AI request take longer that {minutes} min" (HTTP 500) — the timeout duration in the message is the configured `genai.request_timeout` value, so operators see exactly what they configured.

For non-timeout errors from the external service (HTTP 5xx, connection refused, malformed response), the platform wraps the underlying cause in a `GenAIException` (HTTP 500) and surfaces it on the `/api/genai/ask` response. There is no retry loop; a single attempt per request.

## UI status

**API-only today.** The platform UI ships generated clients (`odd-platform-ui/src/generated-sources/apis/GenaiApi.ts` plus the request/response models) but no view, button, or panel currently calls them — verified via grep across `odd-platform-ui/src/` excluding `generated-sources/`. To use the feature, drive `POST /api/genai/ask` from your own client (curl, an internal app, a custom in-platform fork). When a UI affordance ships, this section will be updated.

## Platform-to-user security posture

The "Known limitations" section below covers the platform's posture toward the **external** AI service (no auth headers, no retry, no prompt modification, the misconfiguration-fail-at-first-request behaviour). This section covers the platform's posture toward the **user calling the platform** — the surface operators must harden when enabling GenAI.

{% hint style="danger" %}
**The `POST /api/genai/ask` endpoint has no RBAC entry — every authenticated caller can drive arbitrary cost on the operator's external LLM account.** The platform's authorization rules do not enumerate `/api/genai/**`; the route falls through to the catch-all "any authenticated user" rule under `LOGIN_FORM` / `OAUTH2` / `LDAP`, and is reachable **anonymously** under `auth.type=DISABLED`. The endpoint accepts any well-formed `GenAIRequest`, forwards it to the external service, and pays the request cost from the operator's LLM account. Five sub-gaps compound the exposure:

* **No per-user quota or rate limit.** A single client can issue as many requests per second as the network and the external service tolerate.
* **No in-platform audit trail.** The Activity Feed is structurally data-entity-scoped (see [Activity Feed → Scope](/features/active-platform-features/activity-feed)) — GenAI events have no data entity to anchor against and cannot be added to the feed without a schema migration. There is no platform-side answer to "who asked what at what time."
* **No PII redaction.** The user's question text, including any free-form content typed in, flows verbatim to the external LLM. Cross-team entity names, owner identities, and downstream-lineage names reach the external service if a question references them.
* **No GenAI-specific request-body size cap.** Large free-form prompts pass through up to the platform's global WebFlux in-memory codec limit (`spring.codec.max-in-memory-size`, default `20MB`); there is no tighter per-user or per-endpoint cap on the GenAI route.
* **Under `auth.type=DISABLED`, no per-user attribution at all.** Every request appears as an anonymous call; both the cost and any external-service-side audit trail attribute the request to the platform process, not to a specific user.

**Mitigation today.** Place a rate-limiting reverse proxy or an API gateway in front of `/api/genai/**` before enabling GenAI in production. Do **not** enable GenAI under `auth.type=DISABLED`; tighten who has `.authenticated()` access if the platform is fronted by a permissive auth mode. Treat the external LLM bill as user-driven cost and monitor it for spikes. The upstream platform hardening (RBAC entry, rate limit, body-size cap, PII scrubber) is on the roadmap.
{% endhint %}

{% hint style="warning" %}
**`genai.url` accepts any URL with any scheme — a config-driven SSRF surface.** The `GenAIProperties` class declares `url` as a plain string with no `@URL` constraint and no scheme / host allow-list. An operator (or any party with config-write access — a Helm overlay, an env-var injection, a leaked configmap) can point GenAI outbound at any reachable URL, **including the platform's own internal network**: cloud-metadata endpoints (`http://169.254.169.254/...`), internal services accessible from the platform's egress identity, file-protocol URIs that the underlying HTTP client may follow.

**Mitigation today.** Treat `genai.url` as a privileged configuration value — restrict who can modify it the same way you restrict database credentials or signing keys. Audit the resolved value at deployment time (don't accept a `genai.url` from a CI variable without a deploy-time review). The upstream fix is a configurable scheme / host allow-list on the property; until it ships, the only guard is operator discipline at the config layer.
{% endhint %}

## Known limitations

* **`@ConfigurationProperties` defaults bite when only `genai.enabled` is set.** `url` defaults to `null` (no field initializer in `GenAIProperties.java`) and `request_timeout` defaults to `0` (= immediate timeout). The platform accepts the misconfiguration at startup and fails at first request. Set `genai.url` and `genai.request_timeout` explicitly when enabling — the operator-side guidance lives on [Configure ODD Platform → GenAI Configuration](/configuration-and-deployment/odd-platform#genai-configuration). The upstream-side improvement (defaults declared in `GenAIProperties` or a startup validation) is queued as a separate platform issue.
* **No authentication to the external service.** If the external AI must reject anonymous callers, do it at the network layer (mesh, ingress, NetworkPolicy) — there is no per-request auth header or token added by the platform.
* **No retries.** A single `POST /query_data` per `/api/genai/ask` invocation. The external service must be reliable enough that a single attempt is acceptable, or operators must add retry / circuit-breaker logic upstream of the platform's caller.
* **`request_timeout` is the reply-wait timeout, in minutes** (not seconds, not milliseconds). It sets how long the platform waits for the model's response — the outbound response timeout on the WebClient call to the external service — not a budget for sending the request. The minimum effective value is 1 minute; setting `0` means immediate timeout (see above). It is read once at startup (see "Bean is built once at startup" below), so a change requires a platform restart.
* **Bean is built once at startup.** `WebClientConfiguration` reads `genai.url` and `genai.request_timeout` to construct the `genAiWebClient` bean — changing those values requires a Platform restart for the new WebClient to pick them up.
* **No UI today.** Generated TypeScript clients exist but are not wired into any view; the feature is callable only via the API.

## Where to next

* [Configure ODD Platform → GenAI](/configuration-and-deployment/odd-platform#genai-configuration) — the same three keys in the platform's full configuration reference, with environment-variable equivalents.
* [Main Concepts → AI aspects](/introduction/main-concepts#ai-aspects) — where GenAI sits among the other AI capabilities (data profiling, ML lineage).
* [API Reference → GenAI](/developer-guides/api-reference/genai) — the single `POST /api/genai/ask` endpoint (operationId `genAiQuestion`), the request / response shapes, status codes, and the authorisation posture (cross-link to the security caveat above).


# Metrics Ingestion

Push time-series metrics via \`/ingestion/metrics\` and surface them on each entity's Metrics tab — covers payload shape, two storage backends (PostgreSQL + Prometheus), and operator caveats.

The **Metrics Ingestion** surface accepts time-series metrics pushed into the platform by collectors or custom integrations and surfaces them on each affected data entity's **Metrics** tab. The platform supports the [OpenMetrics](https://openmetrics.io/) metric model — five metric types (`COUNTER`, `GAUGE`, `HISTOGRAM`, `SUMMARY`, `GAUGE_HISTOGRAM`) carrying labels and observation values — and stores them either in its own PostgreSQL database or in an external Prometheus instance, depending on the deployment's `metrics.storage` configuration.

Operators turning on metrics ingestion typically have one of two workflows in mind:

* **Catalog-side cardinality metrics** — row counts, on-disk size, freshness gauges emitted by a collector that scrapes a source system and pushes the result to ODD. These appear as cards on the entity's Metrics tab so an operator opening the entity sees the current row count alongside its schema, ownership, and lineage.
* **Custom-framework metrics** — an in-house pipeline (a daily ETL job, an external profiling tool, a side-process emitting per-entity health signals) pushes structured metrics into the catalog so the platform becomes the single source of truth for "what numbers describe this entity right now."

This page covers the inbound push surface (`POST /ingestion/metrics`), the entity-side read surface (the **Metrics** tab), and the three operator caveats that the configuration reference does not surface in full.

## Where to find it

Two surfaces consume the same data:

* **`POST /ingestion/metrics`** — the inbound push endpoint. Collectors and custom integrations call this with a `MetricSetList` payload (one or more `MetricSet`s, each anchored to a data entity's ODDRN and carrying a list of `MetricFamily` time series).
* **Per-entity Metrics tab** — on a data entity's detail page, the **Metrics** tab renders the ingested time series as charts. The platform reads from `GET /api/dataentities/{id}/metrics`, which fans out to either the internal PostgreSQL store or the configured Prometheus instance depending on `metrics.storage`.

For the platform-side configuration of the two storage backends (`metrics.storage`, `metrics.prometheus-host`, the Prometheus remote-write requirement), see [Configure ODD Platform → Enable Metrics](/configuration-and-deployment/odd-platform#enable-metrics). The configuration reference is the canonical home for the storage knobs; this page is the surface description and the operator-caveat list.

## The endpoint

```
POST /ingestion/metrics
Content-Type: application/json

{
  "items": [
    {
      "oddrn": "<data-entity-oddrn>",
      "metric_families": [
        {
          "name": "<metric-family-name>",
          "type": "COUNTER",                /* or GAUGE / HISTOGRAM / SUMMARY / GAUGE_HISTOGRAM */
          "metrics": [
            { "labels": {"<key>": "<value>", ...}, "metric_points": [ { "value": 123, ... } ] }
          ]
        }
      ]
    }
  ]
}
```

| Property                         | Notes                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                 |
| -------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Method                           | `POST`                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                |
| Path                             | `/ingestion/metrics`                                                                                                                                                                                                                                                                                                                                                                                                                                                                                  |
| Request body                     | `MetricSetList` — one or more `MetricSet`s; each `MetricSet` carries an `oddrn` (the target data entity) and a list of `MetricFamily` entries.                                                                                                                                                                                                                                                                                                                                                        |
| Body size cap                    | **20 MB.** The Spring WebFlux codec `max-in-memory-size` is set to `20MB` in `application.yml`. A request larger than that does **not** get a clean rejection — the platform raises an internal buffer-limit error during body decoding and returns **HTTP 500** (not a 413 "Payload Too Large"), with no body identifying the cap as the cause. Chunk large pushes into multiple `MetricSetList` calls to stay under the limit; a 500 from this endpoint on a large push is the symptom to look for. |
| Response                         | `201 Created` (no body). The platform does not return a per-metric acceptance result. See the empty-payload caveat below — an empty `MetricSetList` also returns `201`, so a `201` is not by itself proof that any metric was written.                                                                                                                                                                                                                                                                |
| Failure on misconfigured storage | If `metrics.storage` is set to an invalid value (anything other than `INTERNAL_POSTGRES` or `PROMETHEUS`), the platform fails to start with `NoSuchBeanDefinitionException` because the storage-backed `IngestionMetricsService` bean cannot be wired. Misconfiguration is caught at boot, not at first request.                                                                                                                                                                                      |

The exact OpenAPI shape (per-field schemas, the five metric-type discriminators) lives in the platform's ingestion contract; consult the [ODD Specification](https://github.com/opendatadiscovery/opendatadiscovery-specification) for the field-level reference.

## Known operator caveats

Several behaviours of the metrics ingestion surface are non-obvious from the configuration reference alone. Each item below states what an operator might assume, what the platform actually does, and what to do today.

{% hint style="danger" %}
**Tenant isolation works only when `metrics.storage=PROMETHEUS`. The default `INTERNAL_POSTGRES` backend has no tenant column — two deployments sharing the same Postgres conflate metrics into one stream.** The `odd.tenant-id` configuration key is **only** consulted on the Prometheus write / query path, where it is appended as a `tenant_id={value}` label on every series. On `INTERNAL_POSTGRES`, the tables backing metric storage (`metric_series`, `metric_point`, `metric_entity`) have **no `tenant_id` column** — the platform writes every metric to the shared schema without any tenant discriminator. Two ODD Platform deployments writing to the same Postgres instance see each other's metrics on every Metrics tab; there is no platform-side filter, and no operator-side mitigation short of running separate Postgres instances per deployment.

**Operator workflow today.** If your deployment needs multi-tenant metric isolation:

* Switch `metrics.storage` to `PROMETHEUS` and set `odd.tenant-id` on every deployment so each one writes (and reads) only its own tenant-labeled series.
* Or run each deployment against its own dedicated PostgreSQL instance (or its own dedicated schema within an instance) so the data path is physically separate.

The "Ignored when `metrics.storage=INTERNAL_POSTGRES`" framing in the configuration reference is technically correct but understates the operator consequence: choosing the default storage backend forfeits tenant isolation entirely, not just one minor labelling convenience. The same class of silent-default risk that previously affected attachment storage on container restart applies here — read the storage section before adopting the default in any multi-tenant context.
{% endhint %}

{% hint style="danger" %}
**`POST /ingestion/metrics` is unauthenticated under every `auth.type` value today.** The platform's Spring Security configuration whitelists the entire `/ingestion/**` namespace, and the optional `auth.ingestion.filter.enabled` filter only matches the exact path `/ingestion/entities` — it does **not** cover `/ingestion/metrics`. Any caller with network reach to the platform can `POST` a `MetricSetList` carrying any `oddrn` they can guess; the platform writes the metrics to the configured backend and surfaces them on the named entity's Metrics tab. Under `auth.type=DISABLED`, the same `POST` is reachable anonymously; under `LOGIN_FORM` / `OAUTH2` / `LDAP` the whitelist still applies.

**Operator workflow today.** Deploy the platform behind a reverse proxy (an authenticating ingress, a NetworkPolicy in Kubernetes restricting which pods can reach `/ingestion/**`, an mTLS-terminating load balancer) that performs the authentication you require on the `/ingestion/metrics` path before forwarding the request. The full picture of which `/ingestion/*` paths are covered by which filter under which `auth.type` is on [Enable Security → Ingestion](/configuration-and-deployment/enable-security). The upstream platform fix adds a dedicated metrics-ingestion filter mirroring `IngestionDataEntitiesFilter`; until it lands, perimeter authentication is the only protection.
{% endhint %}

{% hint style="warning" %}
**Switching `metrics.storage` after a deployment has been live is one-way — historical data does not migrate.** The two storage backends (`INTERNAL_POSTGRES` and `PROMETHEUS`) are independent data stores; the platform writes to whichever is configured at any given moment and reads from the same one. There is no operator tooling to migrate metric history from one backend to the other:

* **`INTERNAL_POSTGRES` → `PROMETHEUS`** — historical metric points in `metric_series` / `metric_point` remain in the PostgreSQL tables but become **unreadable from the platform UI / API** after the switch (the read path queries Prometheus). The Metrics tab on each entity shows only data points written after the switch; everything older is dark until a manual re-ingest or a direct SQL query against the Postgres tables outside the platform.
* **`PROMETHEUS` → `INTERNAL_POSTGRES`** — symmetric: historical points remain in Prometheus but are no longer visible through the platform; the Metrics tab starts fresh on the PostgreSQL side.

**Operator workflow today.** Treat the storage choice as a long-term commitment for any deployment that has been live long enough to accumulate historical metric data. If you must switch (for example to gain tenant isolation per the first caveat above), plan the cutover as a one-time event with a documented "history before this date is queryable from `<old backend>` directly" annotation in the platform's runbook. The platform does not surface the cutover boundary in the UI.
{% endhint %}

{% hint style="warning" %}
**An empty `MetricSetList` returns `201 Created` and writes nothing — a `201` does not confirm a metric landed.** Unlike `POST /ingestion/entities`, which rejects an empty payload with `400 Bad Request` (`Ingestion payload is empty`), the metrics endpoint accepts an empty `items: []` body as a successful no-op and returns `201`. If you use this endpoint as a liveness or smoke-test probe, a `201` only tells you the endpoint is reachable and your auth/proxy layer let the request through — it does **not** tell you that any series was actually persisted to the configured backend. To verify a real write, push at least one `MetricSet` with a known `oddrn` and then read it back from that entity's Metrics tab (`GET /api/dataentities/{id}/metrics`).
{% endhint %}

{% hint style="danger" %}
**The endpoint does not check that a `MetricSet.oddrn` belongs to a real catalog entity — any caller can mint metric series for ODDRNs that do not exist.** When a `MetricSet` arrives, the platform records its `oddrn` in a metric-entity table that has **no foreign key to the data-entity catalog** and performs no existence check; it then writes the series. A caller can therefore push metrics under arbitrary, fabricated ODDRNs and the platform will create rows (in `INTERNAL_POSTGRES`) or series (in `PROMETHEUS`) for every distinct one. Combined with the unauthenticated-endpoint caveat above, this is a cardinality / storage-exhaustion risk: an attacker (or a buggy collector emitting malformed ODDRNs) with network reach can pollute the metric store or the Prometheus series space without ever touching a real entity.

**Operator workflow today.** The same perimeter authentication that protects the unauthenticated endpoint (see the caveat above) is the only control — there is no platform-side ODDRN validation to lean on. If you operate the `PROMETHEUS` backend, additionally bound the blast radius with Prometheus-side series limits (`--storage.tsdb.max-*` / per-tenant limits) so a cardinality flood degrades gracefully rather than exhausting the time-series database. Validate ODDRNs in your collector before pushing so a misconfigured source cannot silently fan out junk series.
{% endhint %}

## Where to next

* [Configure ODD Platform → Enable Metrics](/configuration-and-deployment/odd-platform#enable-metrics) — `metrics.storage`, `metrics.prometheus-host`, the OTLP export channel, the Prometheus tenant label.
* [Enable Security → Ingestion](/configuration-and-deployment/enable-security) — the per-`auth.type` reachability matrix for every `/ingestion/*` path (including `/ingestion/metrics`).
* [Notifications](/features/active-platform-features/notifications) — the sibling subsystem that moves alerts out of the platform; the same WAL-driven pipeline reads ingested events.
* [API Reference](/developer-guides/api-reference) — the per-feature HTTP-endpoint index. The metrics push side lives in the [ODD Specification](https://github.com/opendatadiscovery/opendatadiscovery-specification) ingestion contract; the read side is covered by the per-entity API.


# Management

The operator-facing surface for everything configured inside the platform UI — nine tabs covering data sources, integrations, collectors, ownership, RBAC, taxonomy, and namespacing.

The **Management** section is the operator-facing surface inside the platform UI: every tab here lets an operator add, edit, or remove a piece of catalog configuration. Where the Catalog and the [Directory](/features/data-discovery/directory) are read-oriented (a user finds an existing entity), Management is mutating (an operator changes how the catalog is wired). Most operator workflows after the platform is running — registering a data source, issuing a collector token, granting roles, managing owners, curating tags — start here.

Open it from the top-level navigation **Management**. The page renders a vertical tab sidebar on the left (one entry per Management area) and a content pane on the right; clicking a sidebar entry navigates to `/management/{tab}` and mounts the corresponding sub-page.

## What is in Management

The nine Management tabs (in their UI order, from `ManagementTabs.tsx`):

| Tab              | Path                       | What it manages                                                                                                                                                                                                                                                                                                                                            | Typical workflow                                                                                                                                                                                                                                                                                                                  |
| ---------------- | -------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Namespaces**   | `/management/namespaces`   | Logical groupings used to scope tags, terms, and other taxonomy concepts. Acts as a label dimension applied across the catalog. See [Namespaces](/features/management/namespaces) for the full lifecycle and the four-sister-service auto-create caveat.                                                                                                   | Create a namespace before authoring tags or terms that should be scoped to a particular team or domain.                                                                                                                                                                                                                           |
| **Datasources**  | `/management/datasources`  | Registered data sources — the platform's view of every system a Collector or Push-client is reporting from. View existing sources, audit ingestion timestamps, edit metadata, link to a Collector + Namespace.                                                                                                                                             | Inspect what was registered after a Collector first reported; add a description / tag a source; remove a source no longer ingested.                                                                                                                                                                                               |
| **Integrations** | `/management/integrations` | The Integration Wizard surface — pick an integration template, fill in its parameters, and copy the generated `collector_config.yaml` snippet.                                                                                                                                                                                                             | Generate a working snippet for a new pull adapter; wired-up template registry is documented at the [Integration Wizard](/integrations/integrations/integration-wizard) page.                                                                                                                                                      |
| **Collectors**   | `/management/collectors`   | Registered Collectors and their tokens. Issue new tokens, view existing token IDs, regenerate or revoke.                                                                                                                                                                                                                                                   | Issue a token before deploying a Collector; rotate a leaked token; remove a Collector that's been retired.                                                                                                                                                                                                                        |
| **Owners**       | `/management/owners`       | Owner entities — the catalog-side identity that gets associated with users and attached to data entities for stewardship.                                                                                                                                                                                                                                  | Create owners that map to teams or individuals; attach them to data entities (the attach surface is on each entity's page). See [Owners](/configuration-and-deployment/enable-security/authorization/owners).                                                                                                                     |
| **Tags**         | `/management/tags`         | The catalog's tag taxonomy. Tags can be marked **important** (rendered visually distinct) and namespace-scoped.                                                                                                                                                                                                                                            | Curate a stable tag vocabulary so search facets and filters stay coherent.                                                                                                                                                                                                                                                        |
| **Associations** | `/management/associations` | Three sub-tabs: **New** (incoming pending requests — Accept / Reject), **Active** (existing user-owner bindings — Remove), **History** (resolved requests audit). The header carries **Create association**, the admin direct-bind affordance. **The Associations tab is hidden unless the signed-in user has the `OWNER_ASSOCIATION_MANAGE` permission.** | Process incoming association requests, audit who-approved-what, and create or remove bindings directly. The full workflow — three write-paths, sub-tabs, and operator caveats — is on [User-owner association](/configuration-and-deployment/enable-security/authorization/user-owner-association).                               |
| **Roles**        | `/management/roles`        | Named RBAC roles — bundles of policies applied to users (or owners) to grant catalog-side permissions.                                                                                                                                                                                                                                                     | Create roles (`Editor`, `Reader`, `Owner-of-Domain-X`) and attach Policies to them. See [Roles](/configuration-and-deployment/enable-security/authorization/roles).                                                                                                                                                               |
| **Policies**     | `/management/policies`     | Permission rules — the building blocks of RBAC. Each Policy defines who-can-do-what on resources matched by ODDRN patterns (or per-feature surfaces like Lookup Tables, Query Examples, Owner Association).                                                                                                                                                | Define fine-grained access (e.g. "data engineers can edit transformer entities under prefix `airflow://...`"). See [Policies](/configuration-and-deployment/enable-security/authorization/policies) and [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) for the available permission keys. |

The whole section is gated behind the platform's [authentication](/configuration-and-deployment/enable-security/authentication). Tab visibility is permission-aware (Associations is the explicit case today; other tabs are visible to any signed-in operator and the per-tab actions enforce permission checks). See [Tab visibility versus mutate gates](#tab-visibility-versus-mutate-gates) below for the per-tab breakdown.

![Management → Datasources tab — every registered data source on a deployment, each card showing the source's ODDRN, description, namespace, and a partially-redacted Collector token with a Regenerate action. The vertical sidebar lists every Management area (Namespaces, Datasources, Integrations, Collectors, Owners, Tags, Associations, Roles, Policies); the + Add datasource button at the top-right is the entry-point for registering a source the operator wants to ingest.](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-e71f23ba7c0808c94871fa31505b36c05106c7dc%2Fmanagement-datasources.png?alt=media)

## Other Management surfaces

Beyond the in-app Management tabs, several operator-facing controls live on the platform's authentication, configuration, and collector-secrets surfaces. They are part of how an operator manages the system, even though they don't render as a Management UI tab today:

* **Machine-to-Machine (M2M) tokens** — Server-to-server (S2S) API key authentication for non-UI programmatic callers (CI/CD jobs, ingestion pipelines, automation scripts). Disabled by default; configured on the platform's auth surface — see [Server-to-server (S2S) authentication](/configuration-and-deployment/enable-security/authentication/s2s).
* **Custom navigation links** — the App Info menu items (top-right toolbar) that surface to every signed-in user. Configured via `odd.links[]` on the platform side — see [Configure ODD Platform → Additional navigation links](https://docs.opendatadiscovery.org/features/pages/YH2ILihhfTPfYTyBhtw2#additional-navigation-links-odd.links).
* **Alternative Secrets Backend** — store collector configuration (Platform tokens, plugin credentials) in AWS SSM Parameter Store instead of plaintext in `collector_config.yaml`. Configured on the collector deployment — see [Collector secrets backend](/configuration-and-deployment/collectors-secrets-backend).
* [**Integration Wizard**](/integrations/integrations/integration-wizard) — the in-app generator for `collector_config.yaml` snippets that backs the **Integrations** tab above; handy when bootstrapping a new pull adapter without hand-authoring the YAML.

## Tab visibility versus mutate gates

The platform's authorization model on the Management section is **read-collaborative by default** — only the Associations sub-route enforces a route-level permission gate; the other eight Management areas render their list views and detail pages for any signed-in operator. Under `auth.type=DISABLED` (see [DISABLED authentication](/configuration-and-deployment/enable-security/authentication/disabled-authentication)) the same read surface is reachable by every anonymous network caller. The per-tab **mutate** actions (create, edit, delete, regenerate-token) enforce permissions at the controller; the **read** surface (lists, detail pages, Policy JSON, Role bindings, partially-redacted tokens) does not.

| Tab          | READ exposure                                                                                                     | MUTATE gate                                                                                                                                               | Read-side enforcement                   |
| ------------ | ----------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------- |
| Namespaces   | Any authenticated user (anonymous under DISABLED)                                                                 | `NAMESPACE_CREATE` / `_UPDATE` / `_DELETE`                                                                                                                | None at route or controller             |
| Datasources  | Any authenticated user                                                                                            | `DATA_SOURCE_CREATE` / `_UPDATE` / `_DELETE` / `_TOKEN_REGENERATE`                                                                                        | None at route or controller             |
| Integrations | Any authenticated user                                                                                            | No permission gate today — see the bare-route caveat below                                                                                                | None at route or controller             |
| Collectors   | Any authenticated user (anonymous under DISABLED — see the [Collectors caveats](#collectors-known-caveats) below) | `COLLECTOR_CREATE` / `_UPDATE` / `_DELETE` / `_TOKEN_REGENERATE`                                                                                          | None at route or controller             |
| Owners       | Any authenticated user                                                                                            | `OWNER_CREATE` / `_UPDATE` / `_DELETE`                                                                                                                    | None at route or controller             |
| Tags         | Any authenticated user                                                                                            | `TAG_CREATE` / `_UPDATE` / `_DELETE`                                                                                                                      | None at route or controller             |
| Associations | Only users holding `OWNER_ASSOCIATION_MANAGE`                                                                     | `OWNER_ASSOCIATION_MANAGE` (composite — see [User-owner association](/configuration-and-deployment/enable-security/authorization/user-owner-association)) | Route-level — `RestrictedRoute` wrapper |
| Roles        | Any authenticated user — full Role JSON including bound permissions                                               | `ROLE_CREATE` / `_UPDATE` / `_DELETE`                                                                                                                     | None at route or controller             |
| Policies     | Any authenticated user — **full Policy JSON including grants, ODDRN selectors, and role bindings**                | `POLICY_CREATE` / `_UPDATE` / `_DELETE`                                                                                                                   | None at route or controller             |

The "Read-side enforcement" column distinguishes between the UI's permission-aware affordance hiding (the Add / Edit / Delete buttons disappear for users without the mutate permission — this is a cosmetic UX gate, not an authorization gate) and the route / controller / network reachability of the read endpoint itself (the underlying GET reachability). The Associations tab is the only Management area whose route is gated against the read endpoint as well as the write endpoint.

{% hint style="warning" %}
**Read access on Management exposes information beyond the cosmetic list view.** An operator deep-linking to `/management/policies/{id}` reads the full Policy JSON — every permission grant, every ODDRN selector, every role binding. The same applies to `/management/roles/{id}` (full Role composition) and the Datasources / Collectors list views (partially-redacted tokens — the last six characters of the token leak through the list response). Operators expecting per-team read isolation on Management (a posture some compliance regimes assume by default) need a network-perimeter mitigation — a reverse-proxy authz filter on `/api/policies/**`, `/api/roles/**`, `/api/datasources/**`, `/api/collectors/**`, `/api/owners/**`, `/api/namespaces/**`, `/api/tags/**`, and `/api/integrations*`. The platform's authorization layer does not gate these reads today.
{% endhint %}

{% hint style="warning" %}
**The `/management/integrations` route has no route-level permission wrapper — any integration-specific permission check resolves via the wrong context.** The Integrations route is the only Management area whose route is not wrapped in a `WithPermissionsProvider` or `RestrictedRoute`; the inner `Integrations` component renders directly. The outer Management page seeds only `OWNER_ASSOCIATION_MANAGE` into the permissions context, so any `usePermissions().hasAccessTo(...)` call inside the Integrations subtree that names an integration-specific permission resolves to `false` by default. If a future integration ships a feature gated by a different permission, operators will see deny-by-default until the route's wrapper is fixed. The upstream fix is to add a `WithPermissionsProvider` wrapping the route with the integration-relevant permission list (or to make the deny-by-default deliberate via a no-op wrapper). The doc-side caveat is in place today; the bare-route reads continue to work, but write-actions gated on integration permissions silently deny.
{% endhint %}

## Cascade-block on Owner / Namespace / Datasource deletion

Three Management tabs (Owners, Namespaces, Datasources) share a uniform delete contract: the platform rejects the delete with `CascadeDeleteException` (HTTP 400, error code `USR004`) when dependent rows reference the entity. The UI's ConfirmationDialog says only "Are you sure? X will be deleted permanently." — it does not name the conditional outcome. The Roles and Policies tabs already document the equivalent block; the rule applies to the Owner / Namespace / Datasource trio just as deterministically.

{% hint style="warning" %}
**Owner delete is blocked when any of three referent tables still link to the owner.** `OwnerServiceImpl.delete` zips three existence-predicates — Term-ownership rows, Data-entity-ownership rows, and User-Owner association rows — and rejects the operation if any of the three returns true. The operator must clear the relevant relations first: re-assign or remove term-ownership rows on the [Business Glossary](/features/data-glossary/business-glossary); re-assign or remove data-entity ownership rows on each entity's Owners panel; remove user-owner associations on the [Associations tab](/configuration-and-deployment/enable-security/authorization/user-owner-association). After all three are clear, the delete succeeds.

A known related gap: the `owner_association_request` table is **not** part of the cascade-block guard today — a rejected or stale association-request row can survive owner deletion and surface in the Associations History tab as "rejected by NULL owner." Operators auditing the association-request history of a deleted owner see the legacy rows with a placeholder identifier; a future platform-side fix would add `owner_association_request` to the cascade-guard's predicate set.
{% endhint %}

{% hint style="warning" %}
**Namespace delete is blocked when any of four referent tables still link to the namespace.** `NamespaceServiceImpl.delete` zips four existence-predicates — Data-sources, Collectors, Terms, and non-deleted Data-entities — and rejects the operation if any returns true. Clearing namespace-linked data sources (re-assign the source to a different namespace, or remove the source entirely from the Datasources tab); clearing namespace-linked collectors (re-assign or remove via the Collectors tab); clearing namespace-linked terms (re-assign via the Business Glossary); and clearing or re-assigning live data entities (which arrive via ingestion — typically requires reconfiguring the collector's `namespace_name` and re-ingesting) frees the namespace for deletion.

A Namespace can also be **soft-deleted and re-created with the same name** later — the `namespace` table carries a partial-unique index that frees the name slot on soft-delete, so an operator who wants to "reset" a namespace by deleting and re-creating with the same name can do so once the cascade-block is clear.
{% endhint %}

{% hint style="warning" %}
**Datasource delete is blocked when any live (non-deleted) data entity still references the source.** `DataSourceServiceImpl.delete` checks one existence-predicate — non-deleted data entities under the source — and rejects the operation if any exist. The operator must either re-ingest the source's entities to a different source (rarely practical) or soft-delete every entity under the source first. Once the source has no live children, the delete succeeds — but the operation has two additional side-effects worth knowing about; see [Data Sources known caveats](#data-sources-known-caveats) below.

Both errors render through the same `ControllerAdvice` chain as a toast on the UI; the operator sees a brief "cannot be deleted" message and the dialog stays open with the cancel option highlighted. There is no per-row breakdown of what's blocking the delete — the operator has to enumerate the referents themselves.
{% endhint %}

## Collectors known caveats

{% hint style="danger" %}
**Under `auth.type=DISABLED`, every Collector CRUD endpoint is anonymously reachable — the UI's permission-aware affordance hiding is a cosmetic gate, not an authorization gate.** When the platform runs under [DISABLED authentication](/configuration-and-deployment/enable-security/authentication/disabled-authentication), the platform's security configuration bypasses every `SecurityRule` entry and accepts every request unauthenticated. The Management UI's `WithPermissionsProvider` HOC hides the Create / Edit / Delete / Regenerate-Token buttons because `/api/identity` returns an empty permission set under DISABLED — an operator inspecting the UI concludes "locked down." The backend disagrees: an attacker with network reach to the platform mints new Collectors, copies the last six characters of every existing Collector token through the list response, and regenerates tokens forcing in-flight Collectors to `401` on their next ingestion call. The same pattern applies to every Management mutate endpoint under DISABLED, not just Collectors — Collectors is the most operator-visible example because the token is operationally load-bearing.

**Mitigation today.** Do not run `auth.type=DISABLED` in production. If a non-production deployment must run DISABLED (for example a local Docker stack used in an evaluation), place a network-perimeter authz proxy in front of the platform — or accept that every Management surface is anonymously reachable.
{% endhint %}

{% hint style="danger" %}
**Collector tokens are stored verbatim plaintext at rest; the comparison path uses non-constant-time equality; and the token itself is generated from a non-cryptographic RNG.** The `TOKEN` table column is declared as `value VARCHAR(40) NOT NULL` with no hashing column and no UNIQUE constraint; the token generator writes a 40-character alphanumeric string verbatim into the column on mint. That string is produced by `RandomStringUtils.randomAlphanumeric(40)` (backed by `ThreadLocalRandom`), **not** a cryptographically-secure source — so the 40-character token does not carry CSPRNG-grade entropy and should not be treated as one. Every DB-side reader recovers every live credential — `pg_dump` outputs, streaming replica reads, scheduled backups, jOOQ statement logs (if enabled), and any DB observability pipeline that captures full SQL all expose the plaintext token. Soft-deleted Collectors leave their TOKEN row orphaned — the `TOKEN` table has no `deleted_at` column today, so retired Collector tokens persist in the table indefinitely. Two TOKEN rows may share the same value (no UNIQUE on `VALUE`), though the random-generation entropy makes a natural collision vanishingly unlikely.

Separately, the ingestion-filter's application-layer comparison (`tokenPojo.getValue().equals(token)`) is non-constant-time — a careful attacker with sub-millisecond timing measurement of the platform's `/ingestion/entities` endpoint can in principle build a timing oracle against the token. Combined with the plaintext storage, the operator-visible posture is: treat any DB backup, any log pipeline that captures SQL, and any monitoring stack that captures HTTP latencies as credential material.

**Mitigation today.** Restrict DB read access to the `TOKEN` table; audit `pg_stat_statements` for `SELECT * FROM TOKEN` patterns; treat application-server logs as credential material if jOOQ statement logging is on; treat WAL archives + backups as credential material. The upstream platform-side fix is a hash-at-rest migration (add a `value_hash` column, write only the hash on mint and rotate, compare via constant-time HMAC); the one-shot reveal at mint becomes the operator's only chance to copy the plaintext token.
{% endhint %}

{% hint style="warning" %}
**Token rotation has no grace period — and on default deployments rotation has no security effect on the bulk-ingestion path.** `CollectorServiceImpl.regenerateToken` issues a single in-place `UPDATE TOKEN SET value = ?, updated_at = ?` — the prior token is overwritten in one statement. In-flight Collectors using the prior token start returning `401` on their next ingestion call immediately. There is no grace window during which both tokens are honoured.

Separately, the default `application.yml` carries `auth.ingestion.filter.enabled: false` — the `IngestionDataEntitiesFilter` is inactive on the bulk-ingestion path (`POST /ingestion/entities`) by default. Rotating a leaked token under default config has **no security effect** on the bulk-ingestion path; it only affects the always-on data-source filter on `POST /ingestion/datasources`. Operators rotating a leaked token under a default deployment fix half the attack surface.

**Mitigation today.** Set `auth.ingestion.filter.enabled: true` if token rotation is part of the deployment's security posture (see [Configure ODD Platform](/configuration-and-deployment/odd-platform) for the configuration reference). Schedule rotations during quiet ingestion windows. Treat rotation as a destructive operation against in-flight collectors and coordinate with the team running the Collectors before rotating.
{% endhint %}

## Data Sources known caveats

{% hint style="danger" %}
**Datasource create and update silently mint Namespace rows through the `namespace_name` form field — bypassing `NAMESPACE_CREATE`.** Both `POST /api/datasources` and `PUT /api/datasources/{id}` call `NamespaceServiceImpl.getOrCreate(name)` when the form's `namespace_name` field is non-empty — the service does `getByName(name).switchIfEmpty(createByName(name))`, minting a new Namespace row if the name does not already exist. A caller holding `DATA_SOURCE_CREATE` (or `_UPDATE`) but **not** `NAMESPACE_CREATE` proliferates namespaces through this side-door. The Permissions page describes `DATA_SOURCE_CREATE` and `NAMESPACE_CREATE` as independent gates; the side-door collapses them. The same auto-create pattern exists on three other resource-creation endpoints (Term, Collector, Data-entity-group) — see [Namespaces → Auto-create side-door](/features/management/namespaces#auto-create-side-door) for the four-vertex cluster.

**Mitigation today.** Treat `DATA_SOURCE_CREATE` and `DATA_SOURCE_UPDATE` as implicitly granting namespace-creation rights when the `namespace_name` form field is supplied. Monitor the Namespaces list for unexpected growth (typo-introduced duplicates are the most common operator-visible effect). If strict separation between Datasource creation and Namespace creation is a deployment requirement, treat the `namespace_name` form field as a closed allowlist at the network-perimeter layer.
{% endhint %}

{% hint style="warning" %}
**Datasource delete orphans the Collector token row and leaves the full-text search index uncleared.** When a Datasource passes the cascade-block check and the soft-delete fires, two side-effects do not happen:

* The Datasource's `TOKEN` row is not deleted or marked. The `TOKEN` table has no `deleted_at` column, so the row persists indefinitely after the parent Datasource is soft-deleted. Operators auditing live tokens via `SELECT * FROM TOKEN` see retired tokens alongside live ones with no obvious distinguishing field.
* The full-text-search index entry for the Datasource is **not cleared**. The update path calls `updateSearchVectors`; the delete path does not. Catalog search continues to surface the soft-deleted Datasource's name in faceted results until some other event re-runs the index on the affected entries.

**Mitigation today.** Audit `TOKEN` rows for orphans on a schedule (any row whose `data_source_id` references a soft-deleted source); force a re-index after Datasource deletion if catalog search hygiene matters. The upstream platform-side fix is a one-commit symmetry fix on the delete path (clear the token row, clear the FTS vector).
{% endhint %}

{% hint style="warning" %}
**`regenerateDataSourceToken` returns the plaintext token in the response body without a `Cache-Control: no-store` header — and is the only non-`@ReactiveTransactional` mutating method on the Datasource service.** The mint, update, and delete paths all carry `@ReactiveTransactional`; the regenerate path does not. If the `tokenRepository.updateToken` step fails after the initial `dataSourceRepository.getDto` read, the partial state is undefined — the new token may or may not have been written depending on the exact failure mode.

Separately, the response body carries the new 40-character plaintext token; the controller does not set `Cache-Control: no-store` on the response. Intermediate proxies, browser-history archives, browser DevTools network logs, and any corporate inspection appliance in the response path may cache the response and the token along with it. No Activity Feed event is emitted on token regeneration — the rotation is invisible to the platform's audit trail (see [Activity Feed → Scope](/features/active-platform-features/activity-feed#known-caveats)).

**Mitigation today.** Rotate Datasource tokens during low-traffic windows; ensure TLS terminates at the operator's controlled boundary (no caching proxies in the response path); clear the browser DevTools network log immediately after a regenerate operation. Treat the regenerate operation as a non-atomic write and audit success via a follow-up `GET /api/datasources/{id}` rather than relying on the regenerate response.
{% endhint %}

## Audience and typical sequencing

The audience is **operators** — people who run an ODD deployment for their team. A typical first-deployment sequence touches several Management tabs in order:

1. **Namespaces** — create the logical groups (per team, per domain) you'll scope tagging and term curation to.
2. **Datasources** — verify that the first Collector has registered its sources after the initial ingest.
3. **Collectors** — issue a token and configure additional Collectors as more sources come online.
4. **Owners** — create the catalog-side owner entities for teams and individuals.
5. **Roles + Policies** — author the RBAC bundles that fit the operator's organisation, then attach roles to owners.
6. **Tags** — start curating the tag vocabulary as ingest expands.
7. **Integrations** (as needed) — generate per-integration snippets via the wizard when adding new pull adapters.
8. **Associations** — process incoming requests as users self-associate to owners.

Daily-operations workflows tend to live on tabs 2 (Datasources audit), 4 (Owners maintenance), 5 (RBAC tweaks), and 8 (Associations queue).

## Where to next

* For per-tab security model — RBAC building blocks, the permission keys, and the request flow for owner association — see the [Authorization](/configuration-and-deployment/enable-security/authorization) section.
* For the user-facing **Catalog** counterpart — search, the Directory, the Catalog Overview page — see the [Data Discovery](/features/data-discovery) pillar.
* For the operator's **first-run** path (deploy the platform, deploy a Collector, register a source) — see [Try locally](/configuration-and-deployment/trylocally) and the [Configure ODD Platform](/configuration-and-deployment/odd-platform) reference.
* For the integration template registry that the **Integrations** tab consumes — see the [Integration Wizard](/integrations/integrations/integration-wizard) page.
* For the API surface behind the **Integrations** tab — see [API Reference → Integrations](/developer-guides/api-reference/integrations).


# Namespaces

Logical scoping unit across terms, tags, data sources, collectors, and entity groups — covers the CRUD lifecycle, the four-sister-service auto-create side-door, and the audit-silence caveat.

A **Namespace** is a logical scoping unit applied across the catalog's taxonomy and resource graph. Every Term and Tag carries an optional namespace; every Data Source and Collector binds to one; Data Entity Groups can inherit a namespace through their parent. Namespaces are the catalog-side analogue of a team-or-domain label — operators use them to keep two teams' "customer" terms from colliding, to keep two teams' data sources visually separated in the catalog, and to scope collector ingestion to a known taxonomy.

This page covers the create / update / soft-delete / list lifecycle, the three permission gates, the cascade-on-delete contract, the case-sensitivity rule, the audit-silence shape Namespace CRUD shares with Owners, and the **four-sister-service auto-create side-door** that mints namespace rows without `NAMESPACE_CREATE`.

## Where to find it

Open the [Management](/features/management) page → **Namespaces** tab. The page lists every namespace with a pagination header and a free-text filter; the right-side panel renders the create form. Operators with `NAMESPACE_CREATE` see the **Add namespace** affordance; operators with `NAMESPACE_UPDATE` see an in-place edit on each row; operators with `NAMESPACE_DELETE` see a remove affordance.

## Lifecycle

Five operations exist on the Namespace surface:

| Operation                                                      | Endpoint                      | Permission                                       |
| -------------------------------------------------------------- | ----------------------------- | ------------------------------------------------ |
| List namespaces (paginated, optional `query` substring filter) | `GET /api/namespaces`         | Any authenticated user; anonymous under DISABLED |
| Get a single namespace                                         | `GET /api/namespaces/{id}`    | Any authenticated user; anonymous under DISABLED |
| Create a namespace                                             | `POST /api/namespaces`        | `NAMESPACE_CREATE`                               |
| Update a namespace                                             | `PUT /api/namespaces/{id}`    | `NAMESPACE_UPDATE`                               |
| Soft-delete a namespace                                        | `DELETE /api/namespaces/{id}` | `NAMESPACE_DELETE`                               |

The read endpoints are not gated by a custom-permission entry — the platform's security wiring leaves them at the default `.authenticated()` level. Under `auth.type=DISABLED` they are reachable anonymously (see [DISABLED authentication](/configuration-and-deployment/enable-security/authentication/disabled-authentication)).

## Case sensitivity

Namespace names are **case-sensitive**. `finance` and `Finance` are two distinct rows in the `namespace` table — an operator who creates `Finance` and a teammate who creates `finance` end up with two parallel namespaces that share no relations. The list endpoint's `query` parameter applies a case-insensitive substring match for the suggestion list, but resolution against the canonical row is by exact-string match.

Treat namespace names as a controlled vocabulary that benefits from a documented naming convention — `snake_case` and `lowercase-with-hyphens` are both common in deployments we have seen. Drift between case-variants is one of the most common Namespace-directory pollution shapes.

## Soft-delete and reincarnation

The Namespace delete path is a **soft delete** — the `DELETE /api/namespaces/{id}` endpoint sets `deleted_at = NOW()` on the row rather than removing it from the table. The `namespace` table carries a partial-unique index on `name` that scopes uniqueness to rows where `deleted_at IS NULL`; after a soft-delete, the name slot is free and an operator can create a new namespace with the same name. The previously-deleted row is preserved with its original `id`; downstream auditing tables that reference the namespace by id retain their integrity.

The reincarnation pattern is operationally useful for "reset this namespace" workflows — an operator who wants to clear a namespace's history can soft-delete it and immediately create a new namespace with the same name. The new namespace has a different `id`; any prior relations (terms, data sources, collectors) remain attached to the soft-deleted row and do not migrate.

## Cascade-on-delete guard

Namespace delete is blocked when any of four referent tables still reference the namespace. The platform's service layer zips four existence-predicates and rejects the operation if any returns true:

| Referent table                   | Operator-visible referent                        | Where to clear it                                                                                                                 |
| -------------------------------- | ------------------------------------------------ | --------------------------------------------------------------------------------------------------------------------------------- |
| `data_source` (live rows)        | A Data Source registered under this namespace    | Re-assign the source to a different namespace via [Management → Datasources](/features/management), or remove the source entirely |
| `collector` (live rows)          | A Collector registered under this namespace      | Re-assign the collector or remove it via [Management → Collectors](/features/management)                                          |
| `term` (live rows)               | A Glossary Term scoped to this namespace         | Re-assign or delete the term via the [Business Glossary](/features/data-glossary/business-glossary)                               |
| `data_entity` (non-deleted rows) | A live data entity ingested under this namespace | Re-configure the collector's `namespace_name` and re-ingest, or soft-delete the entities                                          |

When any predicate returns true, the platform returns `CascadeDeleteException` (HTTP 400, error code `USR004`) and the namespace remains live. The error message reads "Namespace cannot be deleted: there are still resources attached" — it does not enumerate which of the four classes is blocking the delete. The operator has to walk each referent class themselves.

{% hint style="warning" %}
**The cascade guard is best-effort, not transactional.** The delete path is not wrapped in a transaction, so the four existence-checks and the soft-delete that follows run as separate statements at `READ COMMITTED` with no lock held on the namespace. If a new referent — a data source, collector, term, or ingested data entity scoped to this namespace — is created in the brief window *after* the checks pass and *before* the soft-delete commits, the delete still succeeds and the new referent is left pointing at a soft-deleted namespace. This is a race only under concurrent writes (an operator deleting a namespace at the same moment another operator or a collector ingest attaches something to it); for the common case of a single operator clearing referents by hand it behaves exactly as the table above describes. If you need a hard guarantee, quiesce writes to the namespace before deleting it.
{% endhint %}

## Auto-create side-door

The Namespace surface carries a load-bearing structural quirk: **four sister services on the platform mint Namespace rows through the side-door `NamespaceServiceImpl.getOrCreate(name)`** when their request body carries a non-empty `namespace_name` field. The four callers are:

| Sister service            | Endpoint                                             | Gating permission for the parent operation |
| ------------------------- | ---------------------------------------------------- | ------------------------------------------ |
| Data Source service       | `POST /api/datasources`, `PUT /api/datasources/{id}` | `DATA_SOURCE_CREATE`, `DATA_SOURCE_UPDATE` |
| Term service              | `POST /api/terms`                                    | `TERM_CREATE`                              |
| Collector service         | `POST /api/collectors`                               | `COLLECTOR_CREATE`                         |
| Data Entity Group service | `POST /api/dataentitygroups`                         | `DATA_ENTITY_GROUP_CREATE`                 |

Each of these calls `getOrCreate(name)`, which does `getByName(name).switchIfEmpty(createByName(name))` — the service silently inserts a new Namespace row if the name does not already exist. The caller does **not** need to hold `NAMESPACE_CREATE`; holding any one of the four parent permissions is sufficient to mint a Namespace row that becomes immediately visible to every authenticated user via the catalogue read.

{% hint style="warning" %}
**The four-sister-service side-door collapses `NAMESPACE_CREATE` with four parent permissions.** Operators expecting `NAMESPACE_CREATE` to be the gate for namespace creation — as the [Permissions page](/configuration-and-deployment/enable-security/authorization/permissions) describes it — discover the side-door when their namespace directory proliferates with junk rows (typos, organic operator typing of distinct strings for the same intent through one of the four side-door endpoints).

**Mitigation today.** Treat `DATA_SOURCE_CREATE`, `DATA_SOURCE_UPDATE`, `TERM_CREATE`, `COLLECTOR_CREATE`, and `DATA_ENTITY_GROUP_CREATE` as implicitly granting namespace-creation rights when their request bodies carry `namespace_name`. Audit the Namespaces list growth on a cadence — typo-introduced duplicates and case-variants are the most common operator-visible drift shape (see [Case sensitivity](#case-sensitivity) above). If strict separation between Namespace creation and the four sister-service operations is a deployment requirement, treat the `namespace_name` form field as a closed allowlist at the network-perimeter layer rather than relying on platform RBAC.

The side-door is not a candidate for a one-commit upstream fix — closing it would either break the existing collector-ingestion workflow (which currently expects the side-door for first-time namespace bootstrap), or require a finer-grained `NAMESPACE_CREATE_VIA_RESOURCE` permission that adds UX complexity. Both are product-level decisions; the operator-side caveat is the right immediate ship.
{% endhint %}

A related sibling pattern exists on the [Owner](/configuration-and-deployment/enable-security/authorization/owners) surface — Owner CRUD has its own side-door cluster through three resource-creation endpoints. The Namespace cluster is the canonical example because four distinct sister services touch it, but the architectural pattern (auto-create on `getOrCreate(name)`-style helpers) is general.

## Activity trail

**Namespace CRUD emits no Activity Feed event.** Two independent facts of the platform's design both block it:

1. **No event type exists.** The Activity Feed's event-type catalogue has no `NAMESPACE_*` member at all — there is simply no type the platform could emit for a namespace create, update, or delete.
2. **The activity table requires a data-entity anchor.** Even if an event type existed, the activity table is schema-anchored to `data_entity_id NOT NULL` — every emitted event must reference a single data entity (see [Activity Feed → Scope](/features/active-platform-features/activity-feed#known-caveats)). Namespace lifecycle operations have no data-entity anchor.

Closing one of these alone would not make Namespace CRUD auditable; both would have to change. The same shape applies to Owner CRUD, Role CRUD, Policy CRUD, and every other RBAC and taxonomy mutation; see [Audit trail scope](/configuration-and-deployment/enable-security/audit-trail-scope) for the platform-wide audit-coverage matrix and the compensating-controls catalogue.

For compliance regimes that need who-changed-what-when on Namespaces, instrument the audit externally — an API-gateway access log records every authenticated mutation on `/api/namespaces*`; the PostgreSQL WAL via `pgaudit` records the `namespace` row writes. The audit-of-occurrence lives outside the platform until both the missing event type and the schema-tier `data_entity_id NOT NULL` anchor are addressed.

## Where to next

* [Management](/features/management) — the parent page; covers the tab-visibility model and the read-collaborative posture across the eight non-Associations Management areas.
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the canonical home for `NAMESPACE_CREATE`, `NAMESPACE_UPDATE`, `NAMESPACE_DELETE` and the four sister-service permissions the side-door collapses against.
* [Activity Feed → Scope](/features/active-platform-features/activity-feed#known-caveats) — the canonical home for the audit-silence pattern Namespace CRUD shares with Owners, Roles, and Policies.
* [Audit trail scope](/configuration-and-deployment/enable-security/audit-trail-scope) — the compliance-facing summary of what the platform audits today and the external instrumentation patterns for the silent-mutation surfaces.
* [Business Glossary](/features/data-glossary/business-glossary), [Manual Object Tagging](/features/data-discovery/tagging) — the two taxonomy surfaces that scope themselves to a Namespace; one canonical place to clear referents when preparing for a Namespace delete.


# Multilingual UI

Seven locale translations for the ODD Platform UI shell — loaded at SPA bootstrap, switched via the toolbar, persisted per browser in localStorage. Operator-authored content stays verbatim.

The ODD Platform UI ships with **seven locale translations** loaded at SPA bootstrap. Users switch the active locale from the **user-account menu** in the top-right of the toolbar; the choice persists per browser device in `localStorage`. The platform's API surface remains English-only — the localisation applies to the UI shell (toolbar labels, page titles, button captions, form field labels, error messages); operator-authored content (entity descriptions, glossary terms, custom-metadata field names, namespaces, tag names) is rendered verbatim regardless of the active locale.

## Supported locales

The platform's translation table currently includes seven entries, sourced from `odd-platform-ui/src/locales/translations/`:

| Code | Language             |
| ---- | -------------------- |
| `en` | English (default)    |
| `es` | Spanish              |
| `ch` | Chinese              |
| `fr` | French               |
| `ua` | Ukrainian            |
| `hy` | Armenian             |
| `br` | Brazilian Portuguese |

The default is `en` — a fresh browser session with no prior locale selection lands on English. The `br` locale (Brazilian Portuguese) ships from platform release 0.28.0 — a community contribution ([`odd-platform#1564`](https://github.com/opendatadiscovery/odd-platform/pull/1564)); deployments on earlier releases offer the original six.

## How users switch

The active locale is changed from the **user-account menu** in the top-right of the toolbar — the area showing your username next to a dropdown arrow. Click it to open the account dropdown (the same menu that holds **Logout**), then click the **Select language** entry — it shows the current language and a chevron. That opens a **Select language** dialog with one searchable entry per supported locale. Picking a locale takes effect immediately on the current page; subsequent SPA navigation continues in the chosen locale.

## Persistence model — per-device, not per-user-account

The chosen locale is stored in the browser's `localStorage` under the key `i18nextLng`. The implications operators should know:

* **Per browser device.** The locale preference is bound to the browser profile, not to the user's catalog account — signing in from a different browser, a different machine, or an incognito session starts from the default (`en`) until the user picks again.
* **Survives logout and re-login.** The `localStorage` value is not cleared by sign-out; the next sign-in from the same browser resumes the prior locale choice.
* **No server-side propagation.** The platform does not record the user's locale preference on the server, does not honour an `Accept-Language` HTTP header, and does not push the choice to other devices the same user is signed in on.

If the deployment serves a user population that uses multiple devices and expects a single, account-bound locale choice — for example a company-managed account propagating across the user's laptop and phone — this is a known absence; the per-device localStorage model is the only persistence path today.

## Known caveat — how missing translations behave (and the 0.28.0 catch-up)

Each locale's translation table uses the English text itself as the lookup key (for example `"Activity": "Activity"`). When a key a component asks for is missing from the active locale, i18next falls back to **English** (the `fallbackLng: 'en'` setting) — the English label renders with no warning and no visible marker. A locale can therefore look fully translated and still show English wherever its table trails the code.

**As of 0.28.0 every shipped locale table is complete.** Earlier releases carried a real gap: a June 2026 sweep found code-referenced keys (about 70, growing to 84 as more UI surfaces landed) absent from *every* non-English catalog — confirmation dialogs, the Data Quality dashboard headlines, lookup-table and query-example labels, the activity-feed actor tooltips — so a non-English locale showed English in those spots. [`odd-platform#1748`](https://github.com/opendatadiscovery/odd-platform/issues/1748) fixed the first slice (the three top-level navigation tabs — Data Quality, Data Modelling, Master Data — which had been absent from every bundle); [`odd-platform#1751`](https://github.com/opendatadiscovery/odd-platform/issues/1751) completed the rest, translating the remaining 84 keys into all six non-English catalogs (`es`, `ch`, `fr`, `ua`, `hy`) and the seventh, `br` — which had separately trailed by eight keys, including the **Master Data** tab. **All seven catalogs (`en`, `es`, `ch`, `fr`, `ua`, `hy`, `br`) now carry the same key set.** A separate gap was also closed in 0.28.0: a number of UI strings were hardcoded in the source with no translation lookup at all (so they showed English under every locale, independent of the catalogs) — these were wrapped so they pass through the translation layer and were translated across all seven locales. Three automated build checks now keep this from regressing: a key-parity check (every locale must carry the English key set), a no-untranslated-string check (a new user-facing label that skips the translation layer fails the build — covering both JSX text and component attributes such as placeholders and labels), and — added in 0.29.0 — a symbolic-key value check. So the gap should not silently reopen as new screens are built.

The third check guards a subtler defect than a missing key. Because the keys *are* the English text, a translator working from the key list alone can mistranslate the one **symbolic** key — `main search placeholder`, whose English value is the home-page search hint (`Search data tables, feature group, jobs and ML models via keywords`) rather than the key itself. All six non-English catalogs had rendered it as a literal gloss of the key (`"main search space"` / `"main search pointer"` / the i18n word "placeholder" in Chinese), so a non-English operator saw meaningless text on the first surface they meet — the home-page catalog search box. The 0.29.0 fix translated the hint into every locale, and the new check now requires every non-English value of a symbolic key to be a translated hint, not a literal gloss of the key ([`odd-platform#1776`](https://github.com/opendatadiscovery/odd-platform/issues/1776)).

These bulk catch-up translations were contributed in one pass; native-speaker refinements to any string are welcome — correcting an existing translation is the same workflow as adding a new locale (see [How to contribute a new locale](#how-to-contribute-a-new-locale) below), applied to the value already in the JSON.

The fallback **mechanism** remains by design: a future code change that introduces a new `t('...')` string renders the English label under any locale whose table has not yet caught up. For completeness audits, treat the translation-table JSON files as the source of truth, not the running UI — because a missing key shows the English text, an English-locale UI always looks complete. On releases that predate 0.28.0, the gaps described above are present.

## How to contribute a new locale

Adding an eighth locale (or any subsequent locale) is a contributor-facing workflow on the UI repository ([`odd-platform`](https://github.com/opendatadiscovery/odd-platform)). The shape:

1. Create a new translation file at `odd-platform-ui/src/locales/translations/{code}.json` (where `{code}` is the locale code — typically the 2-letter ISO 639-1 code, or the project's own short code such as `ch` for Chinese or `br` for Brazilian Portuguese). The file mirrors the structure of the existing translation files; the simplest start is to copy `en.json` and translate each value.
2. Register the locale in the bootstrap module at `odd-platform-ui/src/locales/i18n.ts` — add the import and add the entry to the `resources` map (and, to keep it consistent with the others, add the code to the `fallbackLng` array). The `resources` map is what populates the picker, so this step is what makes the locale selectable.
3. Add the new code to **both** maps in `odd-platform-ui/src/lib/constants.ts` — `LANGUAGES_MAP` (code → display name, shown in the picker) and `LANG_TO_COUNTRY_CODE_MAP` (code → flag country code). These are required: the **Select language** dialog renders each row by looking the code up in these maps, and a code that is missing from `LANGUAGES_MAP` will break the picker. The `Lang` type is derived from `LANGUAGES_MAP`, so adding the key here is also what makes the rest of the code recognise the new locale.
4. Open a pull request against the UI repository. The contribution does not require platform-API changes, and the **Select language** dialog needs no edits — it builds its list from the registered locales automatically. [`odd-platform#1564`](https://github.com/opendatadiscovery/odd-platform/pull/1564), which added Brazilian Portuguese, is a complete worked example of exactly this shape — three files, no other changes.

The build-and-run workflow for the platform (including the frontend UI) is documented at [Build and run ODD Platform](/developer-guides/build-and-run/build-and-run-odd-platform).

## Where to next

* [Management](/features/management) — the operator surface inside the platform UI; the localisation applies to the Management section's tab labels and form controls.
* [Main Concepts → Terms & Aliases](/introduction/main-concepts#terms-and-aliases) — the alias registry where "Multilingual UI", "i18n", "internationalisation", and "locale switching" point at this page.


# Overview

Cross-role use-case index — data compliance for data scientists, safe deprecation for data engineers, DQ visibility for QA, BI preparation for viz engineers, pre-sales for consultants.

## Contents

### Data compliance for Data Scientists

Develop ML-models meeting compliance standards and make sure that you manage Personally Identifiable Information (PII) properly. See the [Data compliance for Data Scientists use case](/use-cases/use-cases/dc-data-compliance) for the end-to-end walkthrough.

### Deprecation for Data Engineer \ Analyst

Be in control of making dramatic changes to your data. Provide transparent deprecation process so as to inform all stakeholders in proper time and manage risks of downstream failure. See the [Deprecation for Data Engineer / Analyst use case](/use-cases/use-cases/de-deprecation).

### Visibility for Data Quality Engineer

Import test suite results from pre-defined libraries or custom frameworks directly to the ODD Platform and share them with your team and other stakeholders to build trustworthy and transparent communication about data health of your product. See the [Visibility for Data Quality Engineer use case](/use-cases/use-cases/dq-visibility).

### Data preparation for Visualization Engineer

There are numerous BI tools and their data preparation capabilities vary. Examine your data sources, metadata and tags using the ODD Platform to predict BI tool performance, set dashboard security levels and prepare the data. See the [Data preparation for Visualization Engineer use case](/use-cases/use-cases/viz-preparation).

### Service Provider and Pre-Sales

Manage customer expectations successfully by examining an existing architectural landscape and gathering info about a toolset for better project scope planning. See the [Service Provider and Pre-Sales use case](/use-cases/use-cases/service-presales).


# Data compliance for Data Scientists

Data scientist walkthrough — using ODD Platform's catalogue search, tags, labels, and metadata to identify confidential data and develop GDPR-compliant ML models.

**Key words**: Personal Identifiable Information (PII), General Data Protection Regulation (GDPR), confidential data, anonymization.

### Challenge

As a Data Scientist, I have a task to develop a ML-model for behavioral segmentation of book shop clients. It aims at introducing customer tiers to customize communication for each segment.\
During model developing I need confidential and personal information of my customer to attribute my tiers right. I do not know if I have to anonymize the data or I can use it as-is as my model will be used internally only.

### Solution

The ODD Platform helps you identify confidential data by combining catalogue search with the [tags](/features/data-discovery/tagging), labels and metadata your team applies to each object — and, therefore, preventing potential monetary, legal or reputational losses. ODD does not classify sensitivity for you: search has no PII or sensitivity facet, and a tag named `PII` is ordinary free text, not a system-recognised sensitivity class. You search to locate the objects, then read each object's tags, labels and metadata — applied by data owners — to judge what is confidential.

### Scenario

1. I start developing a new ML-model. Its data source has to have the following parameters:\
   &#x20;\- customer age, gender, LTV (Lifetime Value), delivery address\
   &#x20;\- customer payment details (card issuer, account's currency, card type)\
   &#x20;\- transaction timestamp, payment type (card or cash)\
   &#x20;\- preferred genres and authors
2. I find the following objects in the sources:\
   &#x20;\- `Dim_Customers`: customer full name, date of birth, delivery address\
   &#x20;\- `Dim_Books`: ISBN, author and genre\
   &#x20;\- `Dim_Cards`: customer, card, card issuer name and currency\
   &#x20;\- `Fct_transactions`: transaction date, book, payment type, transaction amount, quantity, currency, customer and card\
   &#x20;\- `Dim_currency`: currency ISO3 code, currency name\
   &#x20;\- `Dim_payment_types`: payment type, payment type description
3. I have designed ways of joining the above tables but do not know if I should anonymize any data.
4. I go to the ODD Platform and start searching for the tables I need.
5. I check objects’ tags, labels and metadata.
6. I find out that `Dim_Customers` and `Dim_Cards` objects cannot be stored. Customer full name, age, address and payment details should be anonymized as these are PII data protected by GDPR and PCI DSS.

**Result**: ML-model meets GDPR, PCI DSS and company’s compliance standards.


# Deprecation for Data Engineer \ Analyst

Data engineer and analyst walkthrough — using ODD lineage and ownership to deprecate data objects safely, informing stakeholders, and mitigating downstream pipeline failure risk.

**Key words**: divestiture, communication process, identifying stakeholders.

### Challenge

As a Data Engineer, I initiate a deprecation process and have to deprecate my data objects mitigating the risks of other pipelines failing.

As a Data Analyst, I have found an outdated data object on books catalogue that my team has inherited from a legacy team. I know that it is of a poor quality and takes significant resources of my team to maintain it. I want to deprecate it and can't predict the consequences.

### Solution

The ODD Platform provides a [lineage diagram](/features/data-lineage/data-objects) to examine data flows and the ability to identify data owners so the deprecation process goes smoothly. It also has a built-in **deprecation status** that automates the "retire now, delete on a future date" step the scenario below performs by hand: set a data entity's status to **DEPRECATED** with a *switch date*, and a background job flips it to **DELETED** automatically when that date arrives. You can drive the whole timeline in the platform instead of tracking it in a calendar — see the note after the scenario.

### Scenario

1. My team has inherited a data object from a legacy team describing books (ISBN, code, author, publisher).
2. We examined the object and found out that it has not been updated for almost a year due to pipeline failovers and therefore does not contain recent book releases.\
   I have strong doubts that expenses on storage, calculation and team support can be justified.
3. I need to ensure that divestiture won’t impose downstream system failure or block my users:\
   &#x20;\- As a Data analyst, I log in to the ODD Platform to find the stakeholders, SMEs or primary PoCs of the object in doubt.\
   &#x20;\- As a Data Engineer, I explore a lineage diagram to check whether there are any downstream systems sourcing from the object in doubt (pipelines, dashboards, views).
4. I find out that though there is a dashboard sourcing from my object, it was not used for 6 months.
5. We decide to hold a session with stakeholders listed in ODD to double-check my findings and notify them about divestiture.
6. We send out a notification letter that this data object is going to be decommissioned in 3 months.
7. We archive the object and stop object increments.
8. After 3 months we delete the object, DAGs and archive the code base.

**Result**: Deprecation process is well-managed, all users are notified in advance and risks mitigated.

### Using ODD's built-in deprecation

The scenario above tracks the decommission timeline by hand. ODD can run that timeline for you:

* **Mark the object DEPRECATED with a switch date.** Setting a data entity's status to **DEPRECATED** lets you attach a *switch time* — the moment the object should be retired. A background job runs on a fixed schedule and automatically moves any DEPRECATED entity whose switch time has passed to **DELETED**. So "decommission in 3 months" becomes: set DEPRECATED with a switch date 3 months out, and the platform handles the flip — no calendar reminder required.
* **DELETED is a soft delete with a retention window — not a permanent archive.** Moving an object to DELETED hides it from the catalog and detaches its lineage and group memberships, but the record is retained *at first* — so you can restore it (move it back to an active status) and its lineage and group relationships return. It is **not** a permanent archive, though: the platform is designed to **hard-delete** a DELETED entity once it has been DELETED longer than a configurable retention window (`housekeeping.ttl.data_entity_delete_days`, default **30 days**), cascading the deletion to its lineage, metadata, alerts, **attached files (including objects in S3/MinIO storage)**, and group relations — with no restore path afterward. Treat DELETED as *"scheduled for permanent deletion, restorable only within the retention window,"* not as a safe long-term archive — on a default install the purge fires 30 days after deletion. See [Data Entity Statuses → The soft-delete TTL](/features/data-discovery/statuses#the-soft-delete-ttl) for the exact retention behaviour and how to configure the window. (The destruction of DAGs and code base in step 8 happens in your own systems, not inside ODD.)

{% hint style="info" %}
**Blast-radius check before you deprecate.** Lineage reads are not owner-scoped, so the downstream graph shows consumers across the whole catalog — exactly what you want when retiring an inherited object. To catch deeper chains (a view that feeds another view that feeds a dashboard), raise the depth control rather than trusting the default one-hop view. See [Data Objects Lineage](/features/data-lineage/data-objects) for how depth and graph traversal behave.
{% endhint %}


# Visibility for Data Quality Engineer

Data quality engineer walkthrough — ingesting Great Expectations, dbt tests, DataProfiler statistics, and custom DQ framework results into ODD Platform for cross-team visibility.

**Key words**: data quality metrics, Great Expectations, dbt tests, DataProfiler, custom DQ frameworks.

### Challenge

As a Quality Assurance Engineer, I cannot cover all data quality monitoring activities. I know that some book orders can be mapped to wrong dimensions or even miss crucial fields associated with an order. I want to automate the DQ monitoring process and have a place where my team and our users can monitor pipeline health on a given day.

### Solution

The ODD Platform ingests test results from [Great Expectations](/integrations/integrations/odd-great-expectations) and [dbt tests](/integrations/integrations/odd-dbt) (both push-clients), plus statistical profiles from [odd-collector-profiler](/integrations/integrations/odd-collector-profiler) (powered by Capital One's [DataProfiler](https://github.com/capitalone/DataProfiler)). Teams with a custom DQ framework can push their test results through the `POST /ingestion/entities` endpoint of the [ODD Specification](/introduction/main-concepts#odd-specification). See the [Test Results Import](/features/data-quality/test-results-import) page under [Data Quality](/features/data-quality) for the platform-side view.

### Scenario

1. My team’s pipeline is processing more than two billion book orders daily and uses two OLTP systems and ten dimensional tables as its sources.
2. I want to check the following DQ KPIs based on six DQ dimensions: \\

* **Timeliness**: how much time does it take for an order to become available in my product? \\
* **Completeness**: do I have any missing values in the most crucial fields, e.g. date, book ID, amount, etc.? \\
* **Uniqueness**: do I have any duplicated book orders in my dataset? \\
* **Validity**: do the values comply with expected value format, e.g. book ISBN has an expected number of digits? \\
* **Consistency**: when I do a lookup on dimensional table to return a book name, do I get all book IDs covered? \\
* **Accuracy**: does my sales data reconcile with other sources?

3. I cover the Timeliness, Completeness, Uniqueness and Validity dimensions with Great Expectations test suites and statistical profiles produced by `odd-collector-profiler`, both of which land in ODD alongside every other dataset's metadata.
4. For the Consistency and Accuracy dimensions I need to compare several profiles across datasets, which the out-of-the-box frameworks don't cover — I write a small SQL script, run it on a schedule, and push its results as custom DQ test outcomes through the `POST /ingestion/entities` endpoint so the custom KPIs show up next to the framework-produced test results.
5. I import test suite results from Great Expectations to ODD.
6. As ODD allows a DQ import not only from pre-defined libraries but also from custom frameworks, I add my custom test suite results to the Platform as well.
7. I can expose all my DQ KPIs to the ODD Platform and share it with my stakeholders: both my team and my users.

**Result**: I provide a transparent and accessible way of pipeline health monitoring and also use this feature when assessing reliability of other sources of my interest.

{% hint style="warning" %}
**Push custom DQ results to `POST /ingestion/entities`, not the statistics endpoint.** The `POST /ingestion/entities/datasets/stats` path — the route [`odd-collector-profiler`](/integrations/integrations/odd-collector-profiler) uses for per-column statistics — accepts a `DatasetStatisticsList`, not a `DataEntityList` of test results; a test-results payload sent there does not land. That statistics endpoint is also unauthenticated on every auth mode and writes are scoped only by field ODDRN — see [Enable security → Statistics endpoint](/configuration-and-deployment/enable-security#statistics-endpoint-write-shape-and-replay-behaviour) for its full posture and the perimeter controls.
{% endhint %}


# Data preparation for Visualization Engineer

Visualization engineer walkthrough — consulting ODD tags and metadata to predict BI-tool performance, set dashboard security levels, and prepare data for chart development.

**Key words**: BI tool, data chart, performance tuning, data preparation, data load mode, dashboard security level, underlying data.

### Challenge

I am a Viz Engineer in a team that develops and maintains Tableau dashboards for book orders reporting and ad hoc monitoring of online store performance. I got a task from my stakeholders to introduce a dashboard that tracks digital inventory during high demand (Black Friday, Christmas or Valentine's Day) and stays stable if 5+ people use the report simultaneously. Dashboard is expected to be refreshed near-real-time.

To build the dashboards I have to know the nature of the data since the majority of BI tools do not support complicated data preparation algorithms. I need to spend a lot of time on manual analysis of meta data and basic profiling.

### Solution

The ODD Platform [tagging system](/features/data-discovery/tagging) and metadata storage can be consulted during dashboard development to reach better performance and to plan your security standards, e.g. deciding where row-level security based on the user group is needed.

{% hint style="info" %}
ODD helps you **discover** what is sensitive and **plan** the controls; it does not enforce them. ODD tags are a single global directory with no per-tag access control and no user-group binding, so they cannot grant or restrict access by group. Row-level security and group-scoped access are enforced on the data warehouse or BI-tool side — use what you learn in ODD to design those controls there.
{% endhint %}

### Scenario

1. I examine my data source metadata and tags in ODD and find out that it is:\
   &#x20;\- Set to streaming data load mode.\
   &#x20;\- Does not have the KPIs I need but I might be able to calculate them using existing fields.\
   &#x20;\- Has a history depth of ten calendar years.\
   &#x20;\- Contains all sales data, not just the one of customers subscribed to a newsletter.\
   &#x20;\- Has denormalized structure.

{% hint style="info" %}
Treat the custom-metadata values you read here as informative, not as a validated source of truth. ODD does not type-check metadata values, and a collector-ingested value can be overwritten through the API and then silently reverts on the next ingestion run. Confirm anything load-bearing against the source system. See the [custom metadata caveats](/features/data-discovery/custom-metadata#known-limitations-and-operator-caveats) for the details.
{% endhint %}

2. I understand that if I establish a connection from Tableau to a data source as-is, a performance will be very poor and definitely won’t satisfy the near-real-time refresh requirement.
3. I decide to introduce the following data preparation steps:
   * I will develop a view that’ll have customers subscribed to a newsletter data only.
   * I will limit the history depth to one day only (run date) as it is an operational, not analytical dashboard.
   * I will select only the fields that I need for my dashboard.
   * I will pre-calculate all KPIs in my view to increase dashboard performance (set calculation resources on DWH side and not on Tableau as BI tools of this type work best with prepared and pre-aggregated data).

**Result**: I can prevent any collapses during high demand periods when the company requires operational data being reliable and accessible every minute.


# Service Provider and Pre-Sales

Service-provider and pre-sales consultant walkthrough — using the Platform API to gather a client's architectural landscape and toolset for better discovery-phase scope planning.

**Key words**: domain research, gap analysis, customer analysis, discovery phase, scope identification, resources planning, solution design, [lineage](/features/data-lineage/microservices).

### Challenge

As a Service provider or IT consultancy, I often mention that a scope of work refined in Pre-Sales provokes the following problems:

* drastic changes during Discovery / Implementation / Handover phase
* conflicts between an existent architectural landscape and best practices of organization

### Solution

The ODD Platform provides an [API](/developer-guides/api-reference) to gather details on existing architectural landscape and toolset available in organization, so that I have better planning and therefore better customer relations.

### Scenario

1. As a service provider, I usually engage in Pre-sales to facilitate with a potential client, estimate the scope of work, decide on the team setup and suggest solution design.
2. My company has encountered situations when:\
   &#x20;\- Client is dissatisfied with services provided and therefore not set up for a long-term cooperation.\
   &#x20;\- Client has been asking for additional features leading to a scope creep and changes to time-to-market.\
   &#x20;\- Enhancement/change request costs.\
   &#x20;\- Potential monetary, reputational and legal losses may occur.
3. I am sure that the above mentioned situations happen due to miscommunication or a technical proficiency level of people I am engaging with during Pre-Sales and not the quality of services I am providing.
4. To improve my Pre-sales processes I ask my clients to integrate the ODD [API](/developer-guides/api-reference) with their data landscapes. This helps me gather information on:\
   &#x20;\- The data sources, tools, and (where the client has instrumented them via OpenTelemetry) microservices appearing in the catalog, so that I set my project team right. Microservices are catalogued and traced like any other entity — they show up on the same class-agnostic [lineage](/features/data-lineage/microservices) canvas as datasets and transformers, not on a microservice-specific surface.\
   &#x20;\- Level of maturity / landscape complexity, so that I can propose appropriate solutions given the time and budget constraints.

**Result**: I can plan efficiently and suggest the solutions that are feasible to avoid miscommunication and client’s dissatisfaction.


# Overview

Hub for every way metadata reaches the ODD Platform — pull adapters (collector-hosted), push adapters (in-process plugins, standalone gateways, direct SDK use).

An **integration** is any path metadata takes from a source system into the ODD Platform. ODD ships two strategies — **pull** (a [collector](/introduction/main-concepts) polls the source on a schedule) and **push** (a [push adapter](/introduction/main-concepts) lives inside or alongside the source and emits as the source runs). Pick by where the work happens: pull when the source is a passive data store you want snapshotted on a cadence, push when the source is an application or a stream you want reporting per-run lineage and results in real time.

Push adapters ship in three deployment shapes:

* **In-process plugin / extension** — the adapter is embedded inside the source tool's own runtime (`odd-airflow-2`, `odd-dbt`, `odd-spark-adapter`, `odd-great-expectations`). Operators install the adapter into the existing source application.
* **Standalone gateway** — the adapter is its own service that source systems push to over an externally-defined wire protocol (today: `odd-tracing-gateway` over OpenTelemetry/OTLP). Operators deploy the gateway as a separate process and point their existing observability pipeline at it.
* **Direct SDK / CLI use** — the adapter is invoked as a CLI or a library call from custom code (`odd-cli`).

## Pull vs push at a glance

| Integration              | Strategy | Deployment shape   | What it integrates                                                                                         | Repo                                                                                                                    | Page                                                                        |
| ------------------------ | -------- | ------------------ | ---------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------- |
| `odd-collector`          | pull     | collector-hosted   | 41 generic adapters: databases, BI tools, streams, MLOps                                                   | [odd-collectors/odd-collector](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector)             | [odd-collector](/integrations/integrations/odd-collector)                   |
| `odd-collector-aws`      | pull     | collector-hosted   | 11 AWS adapters: Glue, S3, Athena, Kinesis, SageMaker, …                                                   | [odd-collectors/odd-collector-aws](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-aws)     | [odd-collector-aws](/integrations/integrations/odd-collector-aws)           |
| `odd-collector-azure`    | pull     | collector-hosted   | 4 Azure adapters: PowerBI, Azure SQL, Blob Storage, Data Factory                                           | [odd-collectors/odd-collector-azure](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-azure) | [odd-collector-azure](/integrations/integrations/odd-collector-azure)       |
| `odd-collector-gcp`      | pull     | collector-hosted   | 4 GCP adapters: BigQuery, BigTable, GCS, GCS Delta                                                         | [odd-collectors/odd-collector-gcp](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-gcp)     | [odd-collector-gcp](/integrations/integrations/odd-collector-gcp)           |
| `odd-collector-profiler` | pull     | collector-hosted   | Statistical data profiling for Postgres / Azure SQL                                                        | [odd-collector-profiler](https://github.com/opendatadiscovery/odd-collector-profiler)                                   | [odd-collector-profiler](/integrations/integrations/odd-collector-profiler) |
| `odd-airflow-2`          | push     | in-process plugin  | Airflow DAG / task / lineage metadata via a Listener                                                       | [odd-airflow-2](https://github.com/opendatadiscovery/odd-airflow-2)                                                     | [odd-airflow-2](/integrations/integrations/odd-airflow-2)                   |
| `odd-dbt`                | push     | in-process plugin  | dbt model lineage and test results                                                                         | [odd-dbt](https://github.com/opendatadiscovery/odd-dbt)                                                                 | [odd-dbt](/integrations/integrations/odd-dbt)                               |
| `odd-spark-adapter`      | push     | in-process plugin  | Spark job lineage (RDD, JDBC, Kafka batch, Snowflake, S3 Delta)                                            | [odd-spark-adapter](https://github.com/opendatadiscovery/odd-spark-adapter)                                             | [odd-spark-adapter](/integrations/integrations/odd-spark-adapter)           |
| `odd-great-expectations` | push     | in-process plugin  | Great Expectations checkpoint results                                                                      | [odd-great-expectations](https://github.com/opendatadiscovery/odd-great-expectations)                                   | [odd-great-expectations](/integrations/integrations/odd-great-expectations) |
| `odd-cli`                | push     | direct SDK / CLI   | Local files and ad-hoc dataset metadata                                                                    | [odd-cli](https://github.com/opendatadiscovery/odd-cli)                                                                 | [odd-cli](/integrations/integrations/odd-cli)                               |
| `odd-tracing-gateway`    | push     | standalone gateway | Microservice identities and dependencies inferred from OpenTelemetry traces (HTTP, JDBC, Kafka, gRPC, AWS) | [odd-tracing-gateway](https://github.com/opendatadiscovery/odd-tracing-gateway)                                         | [odd-tracing-gateway](/integrations/integrations/odd-tracing-gateway)       |

The same vocabulary appears in [Main Concepts](/introduction/main-concepts): a **collector** is the deployable container for pull adapters; a **push adapter** runs inside the source's runtime, beside it as a standalone gateway, or as a direct SDK / CLI call; a **plugin** is one configured pull-adapter instance inside a collector. "Pull adapter" is **not** a synonym for "collector" — pull adapters live inside collectors, plural per collector.

## Which integration do I need?

* **A database, data warehouse, or BI tool** (PostgreSQL, MySQL, Snowflake, Redshift, Tableau, …) → [`odd-collector`](/integrations/integrations/odd-collector).
* **An AWS service** (Glue, S3, Athena, Kinesis, …) → [`odd-collector-aws`](/integrations/integrations/odd-collector-aws).
* **An Azure service** (PowerBI, Azure SQL, Blob Storage, Data Factory) → [`odd-collector-azure`](/integrations/integrations/odd-collector-azure).
* **A GCP service** (BigQuery, GCS, BigTable) → [`odd-collector-gcp`](/integrations/integrations/odd-collector-gcp).
* **Dataset statistics / profiling** for Postgres or Azure SQL → [`odd-collector-profiler`](/integrations/integrations/odd-collector-profiler).
* **An Airflow scheduler** running DAGs you want lineage for → [`odd-airflow-2`](/integrations/integrations/odd-airflow-2).
* **dbt models and tests** you want surfaced in the catalog → [`odd-dbt`](/integrations/integrations/odd-dbt).
* **Spark jobs** you want lineage from → [`odd-spark-adapter`](/integrations/integrations/odd-spark-adapter).
* **Great Expectations** quality results → [`odd-great-expectations`](/integrations/integrations/odd-great-expectations).
* **Local CSV / Parquet files**, or an ad-hoc push from a script or CI step → [`odd-cli`](/integrations/integrations/odd-cli).
* **Microservices instrumented with OpenTelemetry** — identities, HTTP / JDBC / Kafka / gRPC / AWS-SDK dependencies inferred from distributed traces → [`odd-tracing-gateway`](/integrations/integrations/odd-tracing-gateway). Reach for this when your stack already collects OpenTelemetry traces and you want the catalog to also reflect the microservices and the dependencies your existing observability pipeline already sees.

A single deployment commonly mixes strategies and shapes — e.g., one `odd-collector` container ingesting your warehouses on a schedule, `odd-airflow-2` reporting DAG-level lineage as the orchestrator runs, and `odd-tracing-gateway` populating microservice identities from your OpenTelemetry pipeline. The platform is the same on the receiving end; pick per source.

## Common configuration (collectors)

All collectors share the same top-level configuration schema, defined once in the SDK. The full reference, with every field, lives in [Build and run ODD Collectors → Full configuration reference](/developer-guides/build-and-run/build-and-run-odd-collectors#full-configuration-reference); the abridged shape is:

```yaml
platform_host_url: http://your.odd.platform:8080  # required
token: <COLLECTOR_TOKEN>                          # required (see "Token and datasource registration" below)
default_pulling_interval: 10                      # optional, in minutes — when unset, the collector runs once and exits
plugins:                                          # required, list — see below
  - type: postgresql                              # adapter type literal
    name: warehouse_main                          # operator-chosen, must be unique within the file
    # …per-adapter fields
```

Push adapters are configured separately by their host tool (Airflow Connection, Spark configs, dbt env vars, GE action block) — they do **not** consume `collector_config.yaml`. See each push-adapter page for the per-tool configuration.

### One collector hosts many plugins

A single collector instance — one container, one process — hosts as many plugins as you list in `plugins:`. Plugins can mix adapter types, and you can add **multiple plugins of the same type** to ingest from several sources of the same kind (three PostgreSQL databases on different hosts, two S3 buckets in different accounts, …). Each plugin needs a unique `name`; that's the discriminator the collector uses in logs and metrics.

```yaml
platform_host_url: http://localhost:8080
token: <COLLECTOR_TOKEN>
default_pulling_interval: 10
plugins:
  # Two PostgreSQL plugins → two databases on different hosts.
  - type: postgresql
    name: warehouse_eu
    host: pg-eu.internal
    port: 5432
    database: warehouse
    user: odd_reader
    password: !ENV ${PG_EU_PASSWORD}
  - type: postgresql
    name: warehouse_us
    host: pg-us.internal
    port: 5432
    database: warehouse
    user: odd_reader
    password: !ENV ${PG_US_PASSWORD}
  # A different adapter type → MySQL, same container.
  - type: mysql
    name: legacy_billing
    host: mysql.internal
    port: 3306
    database: billing
    user: odd_reader
    password: !ENV ${MYSQL_PASSWORD}
```

Two plugins of the same type are a routine deployment pattern — one container scales to your full pull-side surface, you don't run one container per source.

### Beyond connection settings: per-adapter features

Many pull adapters expose features that go past "connect and read schema". Two of the most-used ones are surfaced once here so you know to look for them on individual adapter pages:

* **Ingestion filters** — `schemas_filter` (PostgreSQL, Snowflake), `filename_filter` (S3, Azure Blob Storage, GCS), `datasets_filter` (BigQuery), `pipeline_filter` (Azure Data Factory) and similar. Each takes regex `include` / `exclude` lists. When omitted, the default is "include everything" — i.e. the adapter ingests every schema / file / dataset it can see. Use filters to scope a plugin to the slice you actually want catalogued. See the dedicated [Ingestion filters](/integrations/integrations/ingestion-filters) page for the per-key shape, the include / exclude interaction rule, and a worked PostgreSQL example.
* **Foreign-key (ERD) relationships** — PostgreSQL and Snowflake plugins emit `ENTITY_RELATIONSHIP` entities for tables connected by foreign keys (cross-schema relations included). The platform renders these as ERD diagrams on the dataset detail page. Other adapters do not currently extract foreign-key relationships.

The full per-adapter capability matrix (which adapters support filters, which support ERD, which have additional knobs like dataset partitioning) lives on the per-collector pages.

### Secrets backend (optional)

Any field in `collector_config.yaml` can be sourced from AWS SSM Parameter Store instead of inline YAML — see [Collector secrets backend](/configuration-and-deployment/collectors-secrets-backend). Only `odd-collector` (the generic collector) ships with a Secrets Backend hook today; the cloud and profiler collectors read configuration from YAML and environment variables.

## Integration Wizard (in-app UI)

To shorten the path from "I picked an integration" to "I have a working `collector_config.yaml` snippet", the platform ships an **Integration Wizard** under **Management → Integrations**. The wizard is data-driven by manifests on the platform's classpath (`META-INF/wizard/*.yaml`) and exposes the same set through `GET /api/integrations` / `GET /api/integrations/{integration_id}`. For each integration the wizard shows a description, walks the operator through prerequisites, and renders a parameterised YAML snippet — fill in host / port / credentials and copy the result into the `plugins:` block of your `collector_config.yaml`.

The wizard is a **starting point**, not a replacement for `collector_config.yaml`: it generates one plugin's worth of YAML, not the full file. Operators still hand-author `platform_host_url`, `token`, `default_pulling_interval`, additional plugins, filters, and any [secrets-backend](/configuration-and-deployment/collectors-secrets-backend) references. For the per-card flow, the static-parameter substitution context (today only `platform_url`, resolved from `odd.platform-base-url`), and the API surface, see [Integration Wizard](/integrations/integrations/integration-wizard).

## Token and datasource registration

Every integration — pull or push — authenticates to the platform with a **collector token** issued by the ODD Platform. The token is created in the UI under [**Management → Collectors**](/features/management) (see [Try locally → Create Collector entity](/configuration-and-deployment/trylocally#create-collector-entity) for the step-by-step). The same flow issues the token regardless of whether the integration that consumes it is pull or push; what differs is **how each integration consumes the token**:

| Integration                            | How the token is supplied                                                                                                     |
| -------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------- |
| `odd-collector*` (all pull collectors) | `token: <COLLECTOR_TOKEN>` field in `collector_config.yaml`, or `TOKEN` environment variable                                  |
| `odd-airflow-2`                        | Airflow `Connection` named `odd`, `password` field                                                                            |
| `odd-dbt`                              | `ODD_PLATFORM_TOKEN` env var (or `--platform-token` flag)                                                                     |
| `odd-spark-adapter`                    | `spark.odd.host.url` / `spark.odd.oddrn.key` Spark configuration (no static token — the JAR identifies itself by `oddrn.key`) |
| `odd-great-expectations`               | `platform_token` field in the `ODDAction` block                                                                               |
| `odd-cli`                              | `ODD_PLATFORM_TOKEN` env var                                                                                                  |

On the platform side, every integration registers its data sources via `POST /ingestion/datasources`, which the platform exposes as part of the Ingress API. Pull collectors call this from their SDK; push adapters call it (or rely on the platform recognising entity ODDRNs implicitly on first push) per the [ODD Specification](https://github.com/opendatadiscovery/opendatadiscovery-specification).

{% hint style="danger" %}
**The metadata-push endpoint accepts any caller by default.** The collector token above is *not* checked on the entity-push path unless you turn it on. The `/ingestion/**` namespace is whitelisted in Spring Security, and the one filter that does validate the token (`POST /ingestion/entities`) is gated by `auth.ingestion.filter.enabled`, which **defaults to `false`**. With the default in place and the platform reachable on the network, any caller who can speak the Ingress API can push a spec-valid `DataEntityList` into **any** existing datasource — by writing that datasource's ODDRN in the payload — and the catalog renders the result to every user as authoritative metadata. The companion `POST /ingestion/entities/datasets/stats` endpoint is never covered by that filter under any setting. Enable the filter (and read the per-endpoint posture) before exposing the platform on any untrusted network: [Enable security → Ingestion authentication](/configuration-and-deployment/enable-security#ingestion-authentication).
{% endhint %}

## Ingestion error contract

The `POST /ingestion/entities` endpoint is the load-bearing call every collector makes for each metadata batch. Three client-side error conditions currently surface as **HTTP 5xx** (rather than 4xx) because the platform's controller has no `@ExceptionHandler` advice for the underlying exception classes. Collector authors writing retry-with-backoff logic against the public contract should treat the conditions below as **client errors that look like server errors** — retrying them compounds platform pressure without any chance of success.

| Client-side condition                      | Underlying exception                                                                   | Current HTTP shape | Recommended client behaviour                                                                                                                |
| ------------------------------------------ | -------------------------------------------------------------------------------------- | ------------------ | ------------------------------------------------------------------------------------------------------------------------------------------- |
| Duplicate ODDRN inside one batch           | `IllegalStateException: Duplicate key` (thrown by `Collectors.toMap`'s default merger) | 5xx                | Deduplicate the batch on the collector side before submitting; do not retry.                                                                |
| Unknown `data_source_oddrn` in the batch   | `NotFoundException`                                                                    | 5xx                | Verify the data-source has been registered via `POST /ingestion/datasources` before the entity batch; do not retry on this exception class. |
| Payload exceeds the configured codec limit | `DataBufferLimitException` (Spring WebFlux body codec)                                 | 5xx                | Reduce batch size or coordinate with the operator to raise `spring.codec.max-in-memory-size`; do not retry the same payload.                |

Use a per-condition pre-flight (a GET against the target data source, an in-batch deduplication pass, a payload-size check against the operator-documented limit) rather than blanket exponential backoff on 5xx. The platform-side hardening to convert these conditions to structured 4xx responses (`400`, `404`, `413`) is on the roadmap; until it ships, the doc-side contract above is the canonical client guidance.

A separate concern — **per-data-source serialisation under contention**. The `POST /ingestion/entities` pipeline holds a PostgreSQL `SELECT … FOR UPDATE` row-lock on the resolved `data_source` row for the entire pipeline duration (data-source resolve + the 14-step ingestion processor chain + OTLP metric export). Two collectors emitting concurrently to the **same** data source serialise on that lock; the loser may exceed the transaction timeout and fail with a 5xx — there is no `Retry-After` header, no `429 Too Many Requests` signal. Collectors that may emit concurrently to the same data source should apply **per-data-source backoff with jitter** at the client layer (a small randomised delay between consecutive `POST /ingestion/entities` calls for the same data source) until the platform-side fix ships either a narrower lock scope or an explicit contention signal.

A third structural concern — **destructive-path observability**. The ingestion service's rollback paths (every condition above plus the in-pipeline processor failures) have no structured logging today; operators investigating an ingestion failure need platform-side access to the application log to find the actual exception trace. The discriminators an SRE needs (collector identity, target data source ODDRN, entity count, batch identifier) are not present in the platform's logs on the rollback paths — only the raw exception trace surfaces. If your deployment treats ingestion failures as user-impacting, route the collector's own logs through your observability stack as the primary diagnostic surface rather than expecting the platform to mirror the failure detail.

## Where to next

* **Scoping what a plugin ingests** → [Ingestion filters](/integrations/integrations/ingestion-filters) — regex `include` / `exclude` per plugin.
* **Bootstrapping a `collector_config.yaml` snippet from the in-app wizard** → [Integration Wizard](/integrations/integrations/integration-wizard).
* **Storing collector secrets in AWS SSM** → [Collector secrets backend](/configuration-and-deployment/collectors-secrets-backend).
* **Building / running a collector locally** → [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors).
* **The wire contract** between any integration and the platform → [ODD Specification](https://github.com/opendatadiscovery/opendatadiscovery-specification).
* **Authoring a brand-new adapter** (when an existing one doesn't fit) → [Build a custom collector](/developer-guides/build-and-run/custom-collectors). The SDK lives at [odd-collectors/odd-collector-sdk](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-sdk).
* **Existing repository overview** — [GitHub organization overview](/developer-guides/github-organization-overview) lists every ODD repo with one-line summaries.


# odd-collector (generic)

Generic ODD Collector — 41 pull adapters for databases, data warehouses, BI tools, streams, and MLOps platforms.

{% hint style="info" %}
**Status: Stable.** Released as a tagged Docker image; the underlying SDK is the same one all `odd-collector-*` collectors share.
{% endhint %}

`odd-collector` is the general-purpose pull collector. It bundles 41 adapters covering relational databases, data warehouses, NoSQL stores, message brokers, BI tools, MLOps platforms, and a few catalog / orchestration sources. One container instance can host any combination of those adapters as plugins, including multiple plugins of the same type pointing at different sources.

For the broader pull-vs-push picture and the shared collector configuration schema, start at the [Integrations hub](/integrations/integrations). For deployment-side detail (build, Docker, env vars), see [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors).

## Supported adapters

The 41 adapters registered in `odd_collector/domain/plugin.py` (`PLUGIN_FACTORY`). Every adapter has per-field documentation below — three (`postgresql`, `snowflake`, `kafka`) get longer deep-dive spotlights with deployment guidance and feature notes; the remaining 38 are catalogued in the [per-adapter configuration reference](#per-adapter-configuration-reference) section.

| Type literal    | Source system                    | Spotlighted below |
| --------------- | -------------------------------- | ----------------- |
| `airbyte`       | Airbyte                          |                   |
| `cassandra`     | Apache Cassandra                 |                   |
| `ckan`          | CKAN                             |                   |
| `clickhouse`    | ClickHouse                       |                   |
| `cockroachdb`   | CockroachDB                      |                   |
| `couchbase`     | Couchbase                        |                   |
| `cubejs`        | Cube.js                          |                   |
| `databricks`    | Databricks (Unity Catalog)       |                   |
| `dbt`           | dbt Cloud (catalog import)       |                   |
| `druid`         | Apache Druid                     |                   |
| `duckdb`        | DuckDB                           |                   |
| `elasticsearch` | Elasticsearch                    |                   |
| `feast`         | Feast feature store              |                   |
| `fivetran`      | Fivetran                         |                   |
| `hive`          | Apache Hive                      |                   |
| `kafka`         | Apache Kafka                     | ✓                 |
| `kubeflow`      | Kubeflow Pipelines               |                   |
| `metabase`      | Metabase                         |                   |
| `mlflow`        | MLflow                           |                   |
| `mode`          | Mode Analytics                   |                   |
| `mongodb`       | MongoDB                          |                   |
| `mssql`         | Microsoft SQL Server             |                   |
| `mysql`         | MySQL / MariaDB                  |                   |
| `neo4j`         | Neo4j                            |                   |
| `odbc`          | Generic ODBC source              |                   |
| `odd_adapter`   | Another ODD Platform (federated) |                   |
| `opensearch`    | OpenSearch                       |                   |
| `oracle`        | Oracle Database                  |                   |
| `postgresql`    | PostgreSQL (incl. pgvector)      | ✓                 |
| `presto`        | Presto                           |                   |
| `redash`        | Redash                           |                   |
| `redshift`      | Amazon Redshift                  |                   |
| `scylladb`      | ScyllaDB                         |                   |
| `singlestore`   | SingleStore                      |                   |
| `snowflake`     | Snowflake                        | ✓                 |
| `sqlite`        | SQLite                           |                   |
| `superset`      | Apache Superset                  |                   |
| `tableau`       | Tableau                          |                   |
| `tarantool`     | Tarantool                        |                   |
| `trino`         | Trino                            |                   |
| `vertica`       | Vertica                          |                   |

The canonical YAML for each adapter lives at [`odd-collectors/odd-collector/config_examples/`](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector/config_examples) — one file per adapter, named after the type literal. The Pydantic models that define the accepted fields live at [`odd-collectors/odd-collector/odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); read those when an example field is unclear.

{% hint style="warning" %}
The repo's top-level README's "Implemented adapters" table lags behind the code — `databricks`, `couchbase`, `opensearch`, and `oracle` are present in `PLUGIN_FACTORY` but missing from the README table at the time of writing. Use the type literal table above (or `PLUGIN_FACTORY` in `plugin.py`) as the authoritative inventory.
{% endhint %}

## Installation

```bash
docker pull ghcr.io/opendatadiscovery/odd-collector:latest
```

Mount a `collector_config.yaml` at `/app/collector_config.yaml` inside the container. A reference Compose snippet is in the [generic collector README](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector#docker-compose-example) and a from-source build flow is in [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors#build-odd-collector-into-docker-container).

## Minimal config

The smallest `collector_config.yaml` that runs the collector:

```yaml
platform_host_url: http://localhost:8080
token: <COLLECTOR_TOKEN>          # see Token and datasource registration on the hub
default_pulling_interval: 10      # minutes; omit to run once and exit
plugins:
  - type: postgresql
    name: warehouse_main
    host: pg.internal
    port: 5432
    database: warehouse
    user: odd_reader
    password: !ENV ${PG_PASSWORD}
```

The shared top-level fields (`platform_host_url`, `token`, `default_pulling_interval`, `plugins`, plus the optional `connection_timeout_seconds` / `chunk_size` / `misfire_grace_time` / `max_instances` / `verify_ssl`) are documented once at [Build and run ODD Collectors → Full configuration reference](/developer-guides/build-and-run/build-and-run-odd-collectors#full-configuration-reference). Only the `plugins[*]` shape varies per adapter — the rest of this page covers that.

{% hint style="warning" %}
**Regenerating the collector token has no grace window — it stops ingestion until you update this file and restart.** The `token` above is a long-lived platform credential. Regenerating it (in **Management → Collectors**) is an in-place overwrite: every running collector still using the old value starts getting `401`s the instant the new token commits, and ingestion stops until you set the new value here and restart the collector. The token is also stored and returned in plaintext on the platform side, and regeneration is not recorded in the audit trail. See [Management → Collectors known caveats](/features/management#collectors-known-caveats) for the full token contract before rotating a token that running collectors depend on.
{% endhint %}

## Multiple plugins in one container

`plugins` is a list — add as many entries as you need, mixing types freely. Two plugins of the **same type** (e.g. several PostgreSQL databases on different hosts) is the common pattern:

```yaml
plugins:
  - type: postgresql
    name: warehouse_eu
    host: pg-eu.internal
    port: 5432
    database: warehouse
    user: odd_reader
    password: !ENV ${PG_EU_PASSWORD}
  - type: postgresql
    name: warehouse_us
    host: pg-us.internal
    port: 5432
    database: warehouse
    user: odd_reader
    password: !ENV ${PG_US_PASSWORD}
  - type: snowflake
    name: dwh_snowflake
    account: ab12345.eu-central-1
    warehouse: COMPUTE_WH
    database: PROD
    user: ODD_READER
    password: !ENV ${SNOWFLAKE_PASSWORD}
```

Each plugin's `name` must be unique within the file — the collector uses it to log per-plugin progress and to wire each plugin to its own scheduled job. The `default_pulling_interval` applies to every plugin uniformly; per-plugin overrides are not supported.

## Spotlight: PostgreSQL (`type: postgresql`)

Pulls schemas, tables, columns, foreign-key relationships, and (with `pgvector` installed in the source) vector indexes. PostgreSQL tables containing at least one `vector`-typed column are classified as the `Vector Store` dataset type — see [Vector Store metadata](/features/data-discovery/vector-stores) for the user-facing classification, the dedicated icon in the catalog, and the `Vector` column data type rendering on the Structure tab.

| Field                    | Type            | Required | Default  | Description                                                         |
| ------------------------ | --------------- | -------- | -------- | ------------------------------------------------------------------- |
| `name`                   | string          | yes      | —        | Operator-chosen unique plugin name.                                 |
| `host`                   | string          | yes      | —        | PostgreSQL server hostname.                                         |
| `port`                   | integer         | no       | `5432`   | TCP port.                                                           |
| `database`               | string          | yes      | —        | Database to scan; one plugin = one database.                        |
| `user`                   | string          | yes      | —        | Login. The user needs read on the system catalogs you want indexed. |
| `password`               | string (Secret) | yes      | empty    | Password. Use `!ENV ${VAR}` to source from an environment variable. |
| `schemas_filter.include` | list of regex   | no       | `[".*"]` | Schemas to include.                                                 |
| `schemas_filter.exclude` | list of regex   | no       | `[]`     | Schemas to drop after `include` matches.                            |

Source: [`PostgreSQLPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/postgresql.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/postgresql.yaml).

```yaml
plugins:
  - type: postgresql
    name: warehouse_main
    host: pg.internal
    port: 5432
    database: warehouse
    user: odd_reader
    password: !ENV ${PG_PASSWORD}
    schemas_filter:
      include: ["public", "analytics_.*"]
      exclude: ["analytics_archive_.*"]
```

The PostgreSQL adapter extracts foreign-key relationships and emits them as `ENTITY_RELATIONSHIP` entities — these render as ERD edges on the dataset detail page in the catalog. Cross-schema foreign keys are supported.

## Spotlight: Snowflake (`type: snowflake`)

Pulls databases, schemas, tables, views, columns, and foreign-key relationships.

| Field                    | Type            | Required | Default  | Description                                                                                                                     |
| ------------------------ | --------------- | -------- | -------- | ------------------------------------------------------------------------------------------------------------------------------- |
| `name`                   | string          | yes      | —        | Operator-chosen unique plugin name.                                                                                             |
| `account`                | string          | yes      | —        | Snowflake account identifier (e.g. `ab12345.eu-central-1`). The adapter derives the host as `{ACCOUNT}.snowflakecomputing.com`. |
| `warehouse`              | string          | yes      | —        | Compute warehouse used for the catalog query.                                                                                   |
| `database`               | string          | yes      | —        | Database to scan.                                                                                                               |
| `user`                   | string          | yes      | —        | Snowflake login.                                                                                                                |
| `password`               | string (Secret) | yes      | —        | Password.                                                                                                                       |
| `schemas_filter.include` | list of regex   | no       | `[".*"]` | Schemas to include.                                                                                                             |
| `schemas_filter.exclude` | list of regex   | no       | `[]`     | Schemas to drop after `include` matches.                                                                                        |

Source: [`SnowflakePlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/snowflake.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/snowflake.yaml).

```yaml
plugins:
  - type: snowflake
    name: dwh_snowflake
    account: ab12345.eu-central-1
    warehouse: COMPUTE_WH
    database: PROD
    user: ODD_READER
    password: !ENV ${SNOWFLAKE_PASSWORD}
    schemas_filter:
      include: [".*"]
      exclude: ["TEMP_.*", "SCRATCH"]
```

Like PostgreSQL, the Snowflake adapter extracts foreign-key constraints and emits `ENTITY_RELATIONSHIP` entities.

## Spotlight: Kafka (`type: kafka`)

Pulls Kafka topics and (when a Confluent-compatible Schema Registry is reachable) the registered schemas.

| Field                  | Type    | Required | Default | Description                                                                                                       |
| ---------------------- | ------- | -------- | ------- | ----------------------------------------------------------------------------------------------------------------- |
| `name`                 | string  | yes      | —       | Operator-chosen unique plugin name.                                                                               |
| `host`                 | string  | yes      | —       | Bootstrap broker host.                                                                                            |
| `port`                 | integer | yes      | —       | Bootstrap broker port.                                                                                            |
| `broker_conf`          | dict    | yes      | —       | Passed to `confluent_kafka.AdminClient` — e.g. SASL credentials, SSL settings.                                    |
| `schema_registry_conf` | dict    | no       | `{}`    | Passed to the Schema Registry client — e.g. URL, basic auth. When empty, the adapter does not query the registry. |

Source: [`KafkaPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/kafka.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/kafka.yaml).

```yaml
plugins:
  - type: kafka
    name: events_kafka
    host: kafka.internal
    port: 9092
    broker_conf:
      security.protocol: SASL_SSL
      sasl.mechanism: PLAIN
      sasl.username: !ENV ${KAFKA_USER}
      sasl.password: !ENV ${KAFKA_PASSWORD}
    schema_registry_conf:
      url: https://schema-registry.internal:8081
      basic.auth.user.info: !ENV ${SR_USER_INFO}
```

## Per-adapter configuration reference

The three spotlights above cover the deployment-shape questions; this section enumerates the per-field config schema for the remaining 38 adapters. Field names, types, and defaults are sourced from the Pydantic plugin classes in [`odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); each adapter links to its `config_examples/{type}.yaml` reference YAML where one exists. Two adapters — `mode` and `opensearch` — have no upstream config example; their tables come from the Pydantic model alone and the per-section note flags the gap.

Common shapes used across the families below:

* **`BasePlugin`** — every plugin carries `name` (required, operator-chosen, unique within the file). The optional metadata fields `description` and `namespace` are accepted by every plugin and omitted from the per-adapter tables to save space.
* **`DatabasePlugin` base** — adds `host: str` (required), `port: str` (required, often overridden to `int` by subclasses), `database: str | null` (optional in the base; many subclasses redeclare it as required), `user: str` (required), `password: str` (required, redeclared by most subclasses as `SecretStr` with an empty default).
* **`WithHost`** — adds only `host: str`. **`WithPort`** — adds only `port: str`. Both are mixed in by adapters that don't fit the full `DatabasePlugin` shape.

Each table below repeats every field the adapter accepts so that an entry is self-contained — operators don't need to chase the inheritance chain in `plugin.py`.

### Relational databases

#### Microsoft SQL Server (`type: mssql`)

Pulls schemas, tables, views, and columns from a Microsoft SQL Server / Azure SQL Server source via the SQL catalog views.

| Field      | Type            | Required | Default | Description                                                         |
| ---------- | --------------- | -------- | ------- | ------------------------------------------------------------------- |
| `name`     | string          | yes      | —       | Operator-chosen unique plugin name.                                 |
| `host`     | string          | yes      | —       | SQL Server host.                                                    |
| `port`     | integer         | yes      | —       | TCP port (typical: `1433`).                                         |
| `database` | string          | yes      | —       | Database to scan; one plugin = one database.                        |
| `user`     | string          | yes      | —       | SQL login.                                                          |
| `password` | string (Secret) | no       | empty   | Password. Use `!ENV ${VAR}` to source from an environment variable. |

Source: [`MSSQLPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/mssql.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/mssql.yaml).

```yaml
plugins:
  - type: mssql
    name: prod_sqlserver
    host: sqlserver.internal
    port: 1433
    database: warehouse
    user: odd_reader
    password: !ENV ${MSSQL_PASSWORD}
```

#### MySQL / MariaDB (`type: mysql`)

Pulls schemas, tables, views, and columns. Compatible with MariaDB.

| Field          | Type            | Required | Default | Description                                                                                                          |
| -------------- | --------------- | -------- | ------- | -------------------------------------------------------------------------------------------------------------------- |
| `name`         | string          | yes      | —       | Operator-chosen unique plugin name.                                                                                  |
| `host`         | string          | yes      | —       | MySQL server hostname.                                                                                               |
| `port`         | integer         | yes      | —       | TCP port (typical: `3306`).                                                                                          |
| `database`     | string          | yes      | —       | Database to scan.                                                                                                    |
| `user`         | string          | yes      | —       | Login.                                                                                                               |
| `password`     | string (Secret) | no       | empty   | Password.                                                                                                            |
| `ssl_disabled` | boolean         | no       | `false` | When `true`, disables TLS to the server — typically used only for local development against an unencrypted instance. |

Source: [`MySQLPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/mysql.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/mysql.yaml).

```yaml
plugins:
  - type: mysql
    name: legacy_billing
    host: mysql.internal
    port: 3306
    database: billing
    user: odd_reader
    password: !ENV ${MYSQL_PASSWORD}
```

#### ClickHouse (`type: clickhouse`)

Pulls databases, tables, and columns from a ClickHouse cluster.

| Field             | Type            | Required | Default | Description                                                                                                                       |
| ----------------- | --------------- | -------- | ------- | --------------------------------------------------------------------------------------------------------------------------------- |
| `name`            | string          | yes      | —       | Operator-chosen unique plugin name.                                                                                               |
| `host`            | string          | yes      | —       | ClickHouse server hostname.                                                                                                       |
| `port`            | integer or null | yes      | —       | HTTP (`8123`) or native (`9000`) port. The Pydantic model accepts `null`, but every reference example provides an explicit value. |
| `database`        | string or null  | no       | —       | Database to scan. When unset, the connection's default database is used.                                                          |
| `user`            | string          | yes      | —       | Login.                                                                                                                            |
| `password`        | string (Secret) | yes      | —       | Password.                                                                                                                         |
| `secure`          | boolean         | no       | `false` | Toggles TLS on the connection. Set to `true` for ClickHouse Cloud or any TLS-fronted deployment.                                  |
| `verify`          | boolean         | no       | `true`  | Whether to verify the server certificate when `secure: true`. Set to `false` only for self-signed certs on local clusters.        |
| `server_hostname` | string or null  | no       | `null`  | Optional hostname for SNI / certificate validation; defaults to the value of `host`.                                              |
| `query_limit`     | integer or null | no       | `0`     | Optional row cap applied to internal catalog queries. `0` means no limit.                                                         |

Source: [`ClickhousePlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/clickhouse.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/clickhouse.yaml).

```yaml
plugins:
  - type: clickhouse
    name: clickhouse_main
    host: clickhouse.internal
    port: 8123
    database: default
    user: default
    password: !ENV ${CLICKHOUSE_PASSWORD}
    secure: false
```

#### Amazon Redshift (`type: redshift`)

Pulls schemas, tables, views, and columns from an Amazon Redshift cluster.

| Field                | Type                   | Required | Default | Description                                                                                                                                                                                              |
| -------------------- | ---------------------- | -------- | ------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`               | string                 | yes      | —       | Operator-chosen unique plugin name.                                                                                                                                                                      |
| `host`               | string                 | yes      | —       | Redshift cluster endpoint (`{cluster}.{region}.redshift.amazonaws.com`).                                                                                                                                 |
| `port`               | string                 | yes      | —       | TCP port as a string (typical: `"5439"`).                                                                                                                                                                |
| `database`           | string or null         | no       | —       | Database to scan.                                                                                                                                                                                        |
| `user`               | string                 | yes      | —       | Login.                                                                                                                                                                                                   |
| `password`           | string (Secret)        | yes      | —       | Password.                                                                                                                                                                                                |
| `schemas`            | list of string or null | no       | `null`  | Allowlist of schema names. When omitted, every non-system schema is ingested. **Literal name list**, not a regex filter — different from the `schemas_filter` available on `postgresql` and `snowflake`. |
| `connection_timeout` | integer or null        | no       | `10`    | Connection timeout in seconds.                                                                                                                                                                           |

Source: [`RedshiftPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/redshift.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/redshift.yaml).

```yaml
plugins:
  - type: redshift
    name: warehouse_redshift
    host: my-cluster.abc123.us-east-1.redshift.amazonaws.com
    port: "5439"
    database: warehouse
    user: odd_reader
    password: !ENV ${REDSHIFT_PASSWORD}
    schemas: ["public", "analytics"]
    connection_timeout: 10
```

#### CockroachDB (`type: cockroachdb`)

Pulls schemas, tables, columns, and foreign-key relationships. Inherits from the PostgreSQL plugin — same field shape plus the same `schemas_filter` regex behavior; ERD edges are emitted for cross-schema foreign keys exactly as on PostgreSQL.

| Field                    | Type            | Required | Default  | Description                                                                                                                      |
| ------------------------ | --------------- | -------- | -------- | -------------------------------------------------------------------------------------------------------------------------------- |
| `name`                   | string          | yes      | —        | Operator-chosen unique plugin name.                                                                                              |
| `host`                   | string          | yes      | —        | CockroachDB SQL endpoint.                                                                                                        |
| `port`                   | integer         | no       | `5432`   | TCP port. CockroachDB's typical SQL port is `26257`; the model default is the PostgreSQL port inherited from `PostgreSQLPlugin`. |
| `database`               | string          | yes      | —        | Database to scan.                                                                                                                |
| `user`                   | string          | yes      | —        | Login.                                                                                                                           |
| `password`               | string (Secret) | no       | empty    | Password.                                                                                                                        |
| `schemas_filter.include` | list of regex   | no       | `[".*"]` | Schemas to include.                                                                                                              |
| `schemas_filter.exclude` | list of regex   | no       | `[]`     | Schemas to drop after `include` matches.                                                                                         |

Source: [`CockroachDBPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py) (extends `PostgreSQLPlugin`); reference YAML at [`config_examples/cocroachdb.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/cocroachdb.yaml). The upstream filename has a `cocroach` typo — the type literal `cockroachdb` is correct and is what you write in `collector_config.yaml`.

```yaml
plugins:
  - type: cockroachdb
    name: orders_crdb
    host: crdb.internal
    port: 26257
    database: orders
    user: odd_reader
    password: !ENV ${CRDB_PASSWORD}
```

#### Vertica (`type: vertica`)

Pulls schemas, tables, views, and columns from a Vertica analytic database.

| Field      | Type           | Required | Default | Description                         |
| ---------- | -------------- | -------- | ------- | ----------------------------------- |
| `name`     | string         | yes      | —       | Operator-chosen unique plugin name. |
| `host`     | string         | yes      | —       | Vertica host.                       |
| `port`     | string         | yes      | —       | TCP port (typical: `"5433"`).       |
| `database` | string or null | no       | —       | Database to scan.                   |
| `user`     | string         | yes      | —       | Login.                              |
| `password` | string         | yes      | —       | Password.                           |

Source: [`VerticaPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/vertica.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/vertica.yaml).

```yaml
plugins:
  - type: vertica
    name: vertica_main
    host: vertica.internal
    port: "5433"
    database: warehouse
    user: odd_reader
    password: !ENV ${VERTICA_PASSWORD}
```

#### SingleStore (`type: singlestore`)

Pulls schemas, tables, views, and columns from a SingleStore (formerly MemSQL) cluster. Wire-compatible with MySQL.

| Field          | Type            | Required | Default | Description                                                        |
| -------------- | --------------- | -------- | ------- | ------------------------------------------------------------------ |
| `name`         | string          | yes      | —       | Operator-chosen unique plugin name.                                |
| `host`         | string          | yes      | —       | SingleStore host.                                                  |
| `port`         | string          | yes      | —       | TCP port.                                                          |
| `database`     | string or null  | no       | —       | Database to scan.                                                  |
| `user`         | string          | yes      | —       | Login.                                                             |
| `password`     | string          | yes      | —       | Password.                                                          |
| `ssl_disabled` | boolean or null | no       | `false` | Disables TLS to the server — typically only for local development. |

Source: [`SingleStorePlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/singlestore.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/singlestore.yaml).

```yaml
plugins:
  - type: singlestore
    name: singlestore_main
    host: singlestore.internal
    port: "3306"
    database: warehouse
    user: odd_reader
    password: !ENV ${SINGLESTORE_PASSWORD}
```

#### Oracle Database (`type: oracle`)

Pulls schemas (one per Oracle user), tables, views, and columns from an Oracle Database.

| Field        | Type            | Required | Default | Description                                                                                                                                                                                                |
| ------------ | --------------- | -------- | ------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`       | string          | yes      | —       | Operator-chosen unique plugin name.                                                                                                                                                                        |
| `host`       | string          | yes      | —       | Oracle server hostname.                                                                                                                                                                                    |
| `port`       | string          | yes      | —       | TCP port (typical: `"1521"`).                                                                                                                                                                              |
| `user`       | string          | yes      | —       | Oracle login (becomes the schema name in Oracle's data model).                                                                                                                                             |
| `service`    | string          | yes      | —       | Oracle service name (e.g., `XEPDB1`). Use the service name, not the SID.                                                                                                                                   |
| `password`   | string (Secret) | yes      | —       | Password.                                                                                                                                                                                                  |
| `thick_mode` | boolean or null | no       | `false` | When `true`, switches the underlying Oracle client to thick mode (requires the Oracle Instant Client to be installed in the container). Default thin mode is pure Python and works without Instant Client. |

Source: [`OraclePlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/oracle.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/oracle.yaml).

```yaml
plugins:
  - type: oracle
    name: oracle_main
    host: oracle.internal
    port: "1521"
    user: odd_reader
    service: XEPDB1
    password: !ENV ${ORACLE_PASSWORD}
    thick_mode: false
```

#### Generic ODBC source (`type: odbc`)

Pulls schemas, tables, and columns from any source reachable through an ODBC driver registered on the collector container. Useful for sources without a dedicated adapter.

| Field      | Type                    | Required | Default                              | Description                                                                                                                                                                                                                                                                                                     |
| ---------- | ----------------------- | -------- | ------------------------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`     | string                  | yes      | —                                    | Operator-chosen unique plugin name.                                                                                                                                                                                                                                                                             |
| `host`     | string                  | yes      | —                                    | Source hostname.                                                                                                                                                                                                                                                                                                |
| `port`     | string                  | yes      | —                                    | TCP port.                                                                                                                                                                                                                                                                                                       |
| `database` | string                  | yes      | —                                    | Database to scan.                                                                                                                                                                                                                                                                                               |
| `user`     | string                  | yes      | —                                    | Login.                                                                                                                                                                                                                                                                                                          |
| `password` | string (Secret) or null | no       | —                                    | Password.                                                                                                                                                                                                                                                                                                       |
| `driver`   | string                  | no       | `"{ODBC Driver 17s for SQL Server}"` | ODBC driver name as registered in `odbcinst.ini` on the container. **The upstream default contains a typo (`17s` should be `17`)** — always set this field explicitly to the driver string for your environment (e.g., `{ODBC Driver 17 for SQL Server}` or your platform's equivalent). See Known limitations. |

Source: [`OdbcPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/odbc.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/odbc.yaml).

```yaml
plugins:
  - type: odbc
    name: legacy_odbc
    host: odbc.internal
    port: "1433"
    database: legacy
    user: odd_reader
    password: !ENV ${ODBC_PASSWORD}
    driver: "{ODBC Driver 17 for SQL Server}"
```

#### SQLite (`type: sqlite`)

Reads a SQLite database file from a local path on the collector container. In-memory SQLite databases are not supported (each connection sees its own private DB).

| Field         | Type               | Required | Default | Description                                                                                                                           |
| ------------- | ------------------ | -------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------- |
| `name`        | string             | yes      | —       | Operator-chosen unique plugin name.                                                                                                   |
| `data_source` | string (file path) | yes      | —       | Absolute path to the `.db` file inside the container. The file must exist at startup; the model uses Pydantic's `FilePath` validator. |

Source: [`SQLitePlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/sqlite.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/sqlite.yaml).

```yaml
plugins:
  - type: sqlite
    name: local_sqlite
    data_source: /data/local/file.db
```

### Wide-column, document, and key-value stores

#### MongoDB (`type: mongodb`)

Catalogs MongoDB databases, collections, and inferred field types.

| Field      | Type           | Required | Default | Description                                                                                                                                                         |
| ---------- | -------------- | -------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`     | string         | yes      | —       | Operator-chosen unique plugin name.                                                                                                                                 |
| `host`     | string         | yes      | —       | MongoDB host or seed-list host.                                                                                                                                     |
| `port`     | string         | yes      | —       | TCP port (typical: `"27017"`).                                                                                                                                      |
| `database` | string or null | no       | —       | Database to scan.                                                                                                                                                   |
| `user`     | string         | yes      | —       | Login.                                                                                                                                                              |
| `password` | string         | yes      | —       | Password.                                                                                                                                                           |
| `protocol` | string         | yes      | —       | Connection scheme passed to the MongoDB driver — `mongodb` for direct host/port connections, `mongodb+srv` for SRV-resolved seed lists (typical for MongoDB Atlas). |

Source: [`MongoDBPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/mongodb.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/mongodb.yaml).

```yaml
plugins:
  - type: mongodb
    name: mongo_orders
    host: mongo.internal
    port: "27017"
    database: orders
    user: odd_reader
    password: !ENV ${MONGO_PASSWORD}
    protocol: mongodb
```

#### Apache Cassandra (`type: cassandra`)

Catalogs keyspaces, tables, and columns from a Cassandra cluster.

| Field            | Type           | Required | Default | Description                                                                                                     |
| ---------------- | -------------- | -------- | ------- | --------------------------------------------------------------------------------------------------------------- |
| `name`           | string         | yes      | —       | Operator-chosen unique plugin name.                                                                             |
| `host`           | string         | yes      | —       | Cassandra contact host.                                                                                         |
| `port`           | string         | yes      | —       | TCP port (typical: `"9042"`).                                                                                   |
| `database`       | string or null | no       | —       | Keyspace name; one plugin scans one keyspace when supplied.                                                     |
| `user`           | string         | yes      | —       | Login.                                                                                                          |
| `password`       | string         | yes      | —       | Password.                                                                                                       |
| `contact_points` | list of string | no       | `[]`    | Additional contact-host endpoints for the cluster's gossip layer. Empty list means the driver uses `host` only. |

Source: [`CassandraPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/cassandra.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/cassandra.yaml).

```yaml
plugins:
  - type: cassandra
    name: cassandra_events
    host: cassandra-1.internal
    port: "9042"
    database: events
    user: odd_reader
    password: !ENV ${CASSANDRA_PASSWORD}
    contact_points: ["cassandra-2.internal", "cassandra-3.internal"]
```

#### ScyllaDB (`type: scylladb`)

Catalogs keyspaces, tables, and columns from a ScyllaDB cluster. Same field shape as Cassandra — Scylla is wire-compatible with the Cassandra driver.

| Field            | Type           | Required | Default | Description                         |
| ---------------- | -------------- | -------- | ------- | ----------------------------------- |
| `name`           | string         | yes      | —       | Operator-chosen unique plugin name. |
| `host`           | string         | yes      | —       | Scylla contact host.                |
| `port`           | string         | yes      | —       | TCP port (typical: `"9042"`).       |
| `database`       | string or null | no       | —       | Keyspace name.                      |
| `user`           | string         | yes      | —       | Login.                              |
| `password`       | string         | yes      | —       | Password.                           |
| `contact_points` | list of string | no       | `[]`    | Additional contact-host endpoints.  |

Source: [`ScyllaDBPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/scylladb.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/scylladb.yaml).

```yaml
plugins:
  - type: scylladb
    name: scylla_events
    host: scylla-1.internal
    port: "9042"
    database: events
    user: odd_reader
    password: !ENV ${SCYLLA_PASSWORD}
    contact_points: ["scylla-2.internal", "scylla-3.internal"]
```

#### Tarantool (`type: tarantool`)

Catalogs spaces and indexes from a Tarantool instance. Uses the standard `DatabasePlugin` shape with no Tarantool-specific fields.

| Field      | Type           | Required | Default | Description                             |
| ---------- | -------------- | -------- | ------- | --------------------------------------- |
| `name`     | string         | yes      | —       | Operator-chosen unique plugin name.     |
| `host`     | string         | yes      | —       | Tarantool host.                         |
| `port`     | string         | yes      | —       | TCP port (typical: `"3301"`).           |
| `database` | string or null | no       | —       | Database / space-collection identifier. |
| `user`     | string         | yes      | —       | Login.                                  |
| `password` | string         | yes      | —       | Password.                               |

Source: [`TarantoolPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/tarantool.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/tarantool.yaml).

```yaml
plugins:
  - type: tarantool
    name: tarantool_main
    host: tarantool.internal
    port: "3301"
    user: odd_reader
    password: !ENV ${TARANTOOL_PASSWORD}
```

#### Couchbase (`type: couchbase`)

Catalogs Couchbase buckets and infers document field types by sampling. Couchbase is schemaless, so the adapter samples N documents per collection to derive a structural view.

| Field               | Type            | Required | Default | Description                                                                                                               |
| ------------------- | --------------- | -------- | ------- | ------------------------------------------------------------------------------------------------------------------------- |
| `name`              | string          | yes      | —       | Operator-chosen unique plugin name.                                                                                       |
| `host`              | string          | yes      | —       | Couchbase connection string (e.g., `couchbase://node1.internal,node2.internal`).                                          |
| `bucket`            | string          | yes      | —       | Bucket name; one plugin scans one bucket.                                                                                 |
| `user`              | string          | yes      | —       | Login.                                                                                                                    |
| `password`          | string (Secret) | yes      | —       | Password.                                                                                                                 |
| `sample_size`       | integer or null | no       | `0`     | Number of documents to sample per collection for schema inference. `0` disables sampling and uses the metadata-only view. |
| `num_sample_values` | integer or null | no       | `10`    | When sampling is on, number of value examples to retain per inferred field.                                               |

Source: [`CouchbasePlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/couchbase.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/couchbase.yaml).

```yaml
plugins:
  - type: couchbase
    name: couchbase_orders
    host: couchbase://couchbase.internal
    bucket: orders
    user: odd_reader
    password: !ENV ${COUCHBASE_PASSWORD}
    sample_size: 100
    num_sample_values: 10
```

#### Neo4j (`type: neo4j`)

Catalogs Neo4j databases, node labels, and relationship types. Uses the standard `DatabasePlugin` shape; the typical Bolt port is `7687`.

| Field      | Type           | Required | Default | Description                                |
| ---------- | -------------- | -------- | ------- | ------------------------------------------ |
| `name`     | string         | yes      | —       | Operator-chosen unique plugin name.        |
| `host`     | string         | yes      | —       | Neo4j host.                                |
| `port`     | string         | yes      | —       | Bolt port (typical: `"7687"`).             |
| `database` | string or null | no       | —       | Database name (Neo4j 4.x+ multi-database). |
| `user`     | string         | yes      | —       | Login.                                     |
| `password` | string         | yes      | —       | Password.                                  |

Source: [`Neo4jPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/neo4j.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/neo4j.yaml).

```yaml
plugins:
  - type: neo4j
    name: neo4j_graph
    host: neo4j.internal
    port: "7687"
    database: neo4j
    user: neo4j
    password: !ENV ${NEO4J_PASSWORD}
```

### Search engines

#### Elasticsearch (`type: elasticsearch`)

Catalogs Elasticsearch indices and field mappings.

| Field          | Type            | Required | Default | Description                                                                                                                                          |
| -------------- | --------------- | -------- | ------- | ---------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`         | string          | yes      | —       | Operator-chosen unique plugin name.                                                                                                                  |
| `host`         | string          | yes      | —       | Elasticsearch host (typically including scheme — e.g., `https://es.internal`).                                                                       |
| `port`         | integer         | yes      | —       | TCP port (typical: `9200`).                                                                                                                          |
| `username`     | string          | yes      | —       | Login.                                                                                                                                               |
| `password`     | string (Secret) | yes      | —       | Password.                                                                                                                                            |
| `verify_certs` | boolean or null | no       | `null`  | Whether to verify TLS certificates on the Elasticsearch endpoint. `null` defers to the Elasticsearch client default (verify when scheme is `https`). |
| `ca_certs`     | string or null  | no       | `null`  | Optional path to a CA bundle file inside the container.                                                                                              |

Source: [`ElasticsearchPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/elasticsearch.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/elasticsearch.yaml).

```yaml
plugins:
  - type: elasticsearch
    name: es_logs
    host: https://es.internal
    port: 9200
    username: elastic
    password: !ENV ${ES_PASSWORD}
    verify_certs: true
    ca_certs: /etc/ssl/certs/ca-bundle.crt
```

#### OpenSearch (`type: opensearch`)

Catalogs OpenSearch indices and field mappings.

{% hint style="info" %}
**No `config_examples/opensearch.yaml` file exists upstream.** The fields below are read directly from `OpensearchPlugin` in `plugin.py`; the YAML below is hand-crafted from that model.
{% endhint %}

| Field           | Type                    | Required | Default | Description                                                                                                     |
| --------------- | ----------------------- | -------- | ------- | --------------------------------------------------------------------------------------------------------------- |
| `name`          | string                  | yes      | —       | Operator-chosen unique plugin name.                                                                             |
| `host`          | string                  | yes      | —       | OpenSearch host (include scheme when using HTTPS).                                                              |
| `port`          | integer or null         | no       | `443`   | TCP port. The model defaults to `443` (the typical AWS OpenSearch Service port); set to `9200` for self-hosted. |
| `http_compress` | boolean or null         | no       | `true`  | Whether to gzip request bodies.                                                                                 |
| `use_ssl`       | boolean or null         | no       | `true`  | Toggle TLS on the connection.                                                                                   |
| `username`      | string or null          | yes      | —       | Login. The model is `Optional[str]` with no explicit default — provide a value (or `null`) at config time.      |
| `password`      | string (Secret) or null | yes      | —       | Password. Same Pydantic shape as `username` — provide a value or `null`.                                        |
| `verify_certs`  | boolean or null         | no       | `null`  | Whether to verify TLS certificates. `null` defers to the OpenSearch client default.                             |
| `ca_certs`      | string or null          | no       | `null`  | Optional path to a CA bundle file inside the container.                                                         |

Source: [`OpensearchPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py).

```yaml
plugins:
  - type: opensearch
    name: opensearch_logs
    host: https://search-mydomain.us-east-1.es.amazonaws.com
    port: 443
    use_ssl: true
    username: opensearch_admin
    password: !ENV ${OPENSEARCH_PASSWORD}
    verify_certs: true
```

### Analytics engines and warehouses

#### Databricks Unity Catalog (`type: databricks`)

Catalogs Databricks Unity Catalog catalogs, schemas, tables, and columns via the Databricks workspace REST API.

| Field       | Type                   | Required | Default | Description                                                                                                                      |
| ----------- | ---------------------- | -------- | ------- | -------------------------------------------------------------------------------------------------------------------------------- |
| `name`      | string                 | yes      | —       | Operator-chosen unique plugin name.                                                                                              |
| `workspace` | string                 | yes      | —       | Databricks workspace URL (e.g., `https://adb-1234567890.0.azuredatabricks.net`).                                                 |
| `token`     | string (Secret)        | yes      | —       | Databricks personal access token (PAT) or service-principal token authorized for Unity Catalog.                                  |
| `catalogs`  | list of string or null | no       | `null`  | Allowlist of Unity Catalog catalogs. When omitted, every catalog the token can see is ingested. Literal name list — not a regex. |

Source: [`DatabricksPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/databricks_unity_catalog.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/databricks_unity_catalog.yaml). The upstream filename is `databricks_unity_catalog.yaml` while the type literal is the shorter `databricks` — write `type: databricks` in `collector_config.yaml`.

```yaml
plugins:
  - type: databricks
    name: databricks_main
    workspace: https://adb-1234567890.0.azuredatabricks.net
    token: !ENV ${DATABRICKS_TOKEN}
    catalogs: ["main", "analytics"]
```

#### DuckDB (`type: duckdb`)

Reads one or more DuckDB database files from local paths on the collector container; can scan multiple files or whole directories of `.db` files in a single plugin.

| Field   | Type                        | Required | Default       | Description                                                                                                |
| ------- | --------------------------- | -------- | ------------- | ---------------------------------------------------------------------------------------------------------- |
| `name`  | string                      | yes      | —             | Operator-chosen unique plugin name.                                                                        |
| `paths` | list of string (file paths) | yes      | —             | List of paths to `.db` files **or** directories containing `.db` files. Each path is opened independently. |
| `host`  | string or null              | no       | `"localhost"` | Logical hostname used when generating ODDRNs for the catalog entries.                                      |

Source: [`DuckDBPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/duckdb.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/duckdb.yaml).

```yaml
plugins:
  - type: duckdb
    name: duckdb_local
    paths:
      - /data/analytics/warehouse.db
      - /data/analytics/extras/
    host: analytics-runner
```

#### Presto (`type: presto`)

Catalogs schemas, tables, and columns from a Presto coordinator.

| Field          | Type           | Required | Default | Description                                                                                                                                                                                 |
| -------------- | -------------- | -------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`         | string         | yes      | —       | Operator-chosen unique plugin name.                                                                                                                                                         |
| `host`         | string         | yes      | —       | Presto coordinator host.                                                                                                                                                                    |
| `port`         | integer        | yes      | —       | Coordinator HTTP port (typical: `8080` or `8081`).                                                                                                                                          |
| `user`         | string         | yes      | —       | User identity (Presto authenticates by user header by default).                                                                                                                             |
| `principal_id` | string or null | yes      | —       | Optional principal identifier for LDAP-configured clusters. The model is `Optional[str]` with no default — pass `null` (or empty string, as the upstream example does) when not using LDAP. |
| `password`     | string or null | yes      | —       | LDAP password. Same Pydantic shape as `principal_id` — pass `null` / empty string on non-LDAP clusters.                                                                                     |

Source: [`PrestoPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/presto.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/presto.yaml).

```yaml
plugins:
  - type: presto
    name: presto_main
    host: presto.internal
    port: 8081
    user: odd_reader
    principal_id: null
    password: null
```

#### Trino (`type: trino`)

Catalogs schemas, tables, and columns from a Trino coordinator. Wire-compatible with Presto (same client family).

| Field      | Type           | Required | Default | Description                                                     |
| ---------- | -------------- | -------- | ------- | --------------------------------------------------------------- |
| `name`     | string         | yes      | —       | Operator-chosen unique plugin name.                             |
| `host`     | string         | yes      | —       | Trino coordinator host.                                         |
| `port`     | integer        | yes      | —       | Coordinator HTTP port (typical: `8080` / `8081`).               |
| `user`     | string         | yes      | —       | User identity.                                                  |
| `password` | string or null | yes      | —       | LDAP password. Pass `null` / empty string on non-LDAP clusters. |

Source: [`TrinoPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/trino.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/trino.yaml).

```yaml
plugins:
  - type: trino
    name: trino_main
    host: trino.internal
    port: 8081
    user: odd_reader
    password: null
```

#### Apache Druid (`type: druid`)

Catalogs Druid datasources via the broker API.

| Field  | Type    | Required | Default | Description                         |
| ------ | ------- | -------- | ------- | ----------------------------------- |
| `name` | string  | yes      | —       | Operator-chosen unique plugin name. |
| `host` | string  | yes      | —       | Druid broker host.                  |
| `port` | integer | yes      | —       | Broker HTTP port (typical: `8082`). |

Source: [`DruidPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/druid.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/druid.yaml).

```yaml
plugins:
  - type: druid
    name: druid_main
    host: druid-broker.internal
    port: 8082
```

#### Apache Hive (`type: hive`)

Catalogs Hive databases, tables, and columns via HiveServer2. Configuration is grouped under a nested `connection_params` object — Hive's auth surface is varied enough that the adapter exposes the full HS2 connection knob set.

| Field                                     | Type            | Required | Default | Description                                                                                                                                 |
| ----------------------------------------- | --------------- | -------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`                                    | string          | yes      | —       | Operator-chosen unique plugin name.                                                                                                         |
| `count_statistics`                        | boolean         | no       | `false` | Whether to collect row-count statistics (`SELECT COUNT(*)`) per table. Off by default — these queries can be expensive on large warehouses. |
| `connection_params`                       | object          | yes      | —       | Nested HS2 connection block — see fields below.                                                                                             |
| `connection_params.host`                  | string          | yes      | —       | HiveServer2 host.                                                                                                                           |
| `connection_params.port`                  | integer or null | no       | `null`  | HS2 port. Defaults to `10000` when `scheme` is unset, `1000` when `scheme: http` / `https` (per the upstream HS2 client convention).        |
| `connection_params.database`              | string          | yes      | —       | Hive database to scan.                                                                                                                      |
| `connection_params.scheme`                | string or null  | no       | `null`  | HS2 transport — `"http"` or `"https"` for HTTP transport; `null` for binary transport.                                                      |
| `connection_params.auth`                  | string or null  | no       | `null`  | Auth mode — one of `"BASIC"`, `"NOSASL"`, `"KERBEROS"`, `"NONE"`. Defaults to `NONE` when omitted.                                          |
| `connection_params.username`              | string or null  | no       | `null`  | Username. Used with `auth: LDAP` or `auth: CUSTOM`.                                                                                         |
| `connection_params.password`              | string or null  | no       | `null`  | Password. Used with `auth: LDAP` or `auth: CUSTOM`.                                                                                         |
| `connection_params.kerberos_service_name` | string or null  | no       | `null`  | Used with `auth: KERBEROS` only.                                                                                                            |
| `connection_params.configuration`         | object or null  | no       | `null`  | Free-form dict of Hive session configuration overrides.                                                                                     |
| `connection_params.check_hostname`        | string or null  | no       | `null`  | TLS hostname check toggle as a string `"true"` / `"false"`.                                                                                 |
| `connection_params.ssl_cert`              | string or null  | no       | `null`  | Path to a CA / client certificate file inside the container.                                                                                |

Source: [`HivePlugin` and `HiveConnectionParams` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/hive.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/hive.yaml).

```yaml
plugins:
  - type: hive
    name: hive_main
    count_statistics: false
    connection_params:
      host: hive.internal
      port: 10000
      database: default
      auth: NONE
```

### Business intelligence and dashboards

#### Tableau (`type: tableau`)

Catalogs Tableau site content (workspaces, projects, dashboards, sheets) via the Tableau REST API.

| Field             | Type                    | Required | Default | Description                                                                                                                   |
| ----------------- | ----------------------- | -------- | ------- | ----------------------------------------------------------------------------------------------------------------------------- |
| `name`            | string                  | yes      | —       | Operator-chosen unique plugin name.                                                                                           |
| `server`          | string                  | yes      | —       | Tableau Server / Tableau Cloud URL.                                                                                           |
| `site`            | string or null          | yes      | —       | Tableau site name (empty string for the default site). The model is `Optional[str]` with no default — pass an explicit value. |
| `user`            | string or null          | yes      | —       | Username. Pass `null` if authenticating via `token_name` / `token_value`.                                                     |
| `password`        | string (Secret) or null | yes      | —       | Password. Pass `null` if authenticating via PAT.                                                                              |
| `token_name`      | string or null          | yes      | —       | Personal access token name (for 2FA / SSO accounts that can't use password auth).                                             |
| `token_value`     | string (Secret) or null | yes      | —       | Personal access token value.                                                                                                  |
| `pagination_size` | integer                 | no       | `10`    | Page size for the REST API. Larger values reduce request count but increase per-request latency; tune for very large sites.   |

Source: [`TableauPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/tableau.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/tableau.yaml).

```yaml
plugins:
  - type: tableau
    name: tableau_main
    server: https://tableau.internal
    site: analytics
    user: null
    password: null
    token_name: odd-reader-pat
    token_value: !ENV ${TABLEAU_TOKEN}
    pagination_size: 50
```

#### Apache Superset (`type: superset`)

Catalogs Superset datasets, dashboards, and charts via the Superset REST API.

| Field      | Type            | Required | Default | Description                                 |
| ---------- | --------------- | -------- | ------- | ------------------------------------------- |
| `name`     | string          | yes      | —       | Operator-chosen unique plugin name.         |
| `server`   | string          | yes      | —       | Superset base URL (include trailing slash). |
| `username` | string          | yes      | —       | Superset login.                             |
| `password` | string (Secret) | yes      | —       | Password.                                   |

Source: [`SupersetPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/superset.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/superset.yaml).

```yaml
plugins:
  - type: superset
    name: superset_main
    server: https://superset.internal/
    username: admin
    password: !ENV ${SUPERSET_PASSWORD}
```

#### Metabase (`type: metabase`)

Catalogs Metabase dashboards, questions, and the underlying datasets they reference.

| Field      | Type            | Required | Default | Description                         |
| ---------- | --------------- | -------- | ------- | ----------------------------------- |
| `name`     | string          | yes      | —       | Operator-chosen unique plugin name. |
| `host`     | string          | yes      | —       | Metabase host.                      |
| `port`     | string          | yes      | —       | TCP port.                           |
| `login`    | string          | yes      | —       | Metabase login email.               |
| `password` | string (Secret) | yes      | —       | Password.                           |

Source: [`MetabasePlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/metabase.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/metabase.yaml).

```yaml
plugins:
  - type: metabase
    name: metabase_main
    host: metabase.internal
    port: "3000"
    login: odd-reader@example.com
    password: !ENV ${METABASE_PASSWORD}
```

#### Redash (`type: redash`)

Catalogs Redash queries and dashboards via the Redash API.

| Field     | Type   | Required | Default | Description                                                                                 |
| --------- | ------ | -------- | ------- | ------------------------------------------------------------------------------------------- |
| `name`    | string | yes      | —       | Operator-chosen unique plugin name.                                                         |
| `server`  | string | yes      | —       | Redash server base URL.                                                                     |
| `api_key` | string | yes      | —       | Redash API key (account-scoped — gives the adapter access to whatever the account can see). |

Source: [`RedashPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/redash.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/redash.yaml).

```yaml
plugins:
  - type: redash
    name: redash_main
    server: https://redash.internal
    api_key: !ENV ${REDASH_API_KEY}
```

#### Mode Analytics (`type: mode`)

Catalogs Mode reports and the underlying datasets they reference.

{% hint style="info" %}
**No `config_examples/mode.yaml` file exists upstream.** The fields below are read directly from `ModePlugin` in `plugin.py`; the YAML below is hand-crafted from that model.
{% endhint %}

| Field         | Type                    | Required | Default | Description                                                                                                           |
| ------------- | ----------------------- | -------- | ------- | --------------------------------------------------------------------------------------------------------------------- |
| `name`        | string                  | yes      | —       | Operator-chosen unique plugin name.                                                                                   |
| `host`        | string                  | yes      | —       | Mode workspace host (e.g., `https://app.mode.com`).                                                                   |
| `account`     | string                  | yes      | —       | Mode account / workspace identifier.                                                                                  |
| `data_source` | string                  | yes      | —       | Mode data-source identifier the adapter should report against.                                                        |
| `token`       | string (Secret) or null | yes      | —       | API token. The model is `Optional[SecretStr]` with no default — pass a value or `null` if relying on `password` auth. |
| `password`    | string (Secret) or null | yes      | —       | Password (legacy auth). Pass `null` if using token auth.                                                              |

Source: [`ModePlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py).

```yaml
plugins:
  - type: mode
    name: mode_main
    host: https://app.mode.com
    account: my_workspace
    data_source: my_warehouse
    token: !ENV ${MODE_TOKEN}
    password: null
```

#### Cube.js (`type: cubejs`)

Catalogs Cube.js cubes and members; uses the cube's underlying SQL data source to resolve lineage from cube measures back to the source columns.

| Field                            | Type                    | Required    | Default | Description                                                                                                                                                                                                                                                                                                                                                                                             |
| -------------------------------- | ----------------------- | ----------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`                           | string                  | yes         | —       | Operator-chosen unique plugin name.                                                                                                                                                                                                                                                                                                                                                                     |
| `host`                           | string                  | yes         | —       | Cube.js server base URL.                                                                                                                                                                                                                                                                                                                                                                                |
| `dev_mode`                       | boolean                 | no          | `false` | When `true`, the adapter relaxes auth — `token` may be `null`. In production (`dev_mode: false`), `token` is required and the adapter raises `ValueError` on startup if it isn't set.                                                                                                                                                                                                                   |
| `token`                          | string (Secret) or null | conditional | `null`  | Cube.js auth token — required unless `dev_mode: true`.                                                                                                                                                                                                                                                                                                                                                  |
| `predefined_datasource`          | object                  | yes         | —       | Sub-object describing the SQL data source backing the cubes — used by the adapter's SQL parser to generate lineage-edge ODDRNs. Only `postgres` and `clickhouse` are recognised types (see [`PostgresDatasource` / `ClickHouseDatasource` in `predefined_data_source.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/predefined_data_source.py)). |
| `predefined_datasource.type`     | string                  | yes         | —       | `"postgres"` or `"clickhouse"`.                                                                                                                                                                                                                                                                                                                                                                         |
| `predefined_datasource.host`     | string or null          | no          | `null`  | Source host — used as the lineage ODDRN host.                                                                                                                                                                                                                                                                                                                                                           |
| `predefined_datasource.database` | string or null          | no          | `null`  | Source database.                                                                                                                                                                                                                                                                                                                                                                                        |

Source: [`CubeJSPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/cubejs.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/cubejs.yaml).

```yaml
plugins:
  - type: cubejs
    name: cubejs_main
    host: http://cube.internal:4000
    dev_mode: false
    token: !ENV ${CUBEJS_TOKEN}
    predefined_datasource:
      type: postgres
      host: pg.internal
      database: warehouse
```

### Catalog, ingestion, and federation

#### CKAN (`type: ckan`)

Catalogs CKAN packages and resources from the CKAN action API.

| Field           | Type                    | Required | Default | Description                                                                                                                                       |
| --------------- | ----------------------- | -------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`          | string                  | yes      | —       | Operator-chosen unique plugin name.                                                                                                               |
| `host`          | string                  | yes      | —       | CKAN host.                                                                                                                                        |
| `port`          | string                  | yes      | —       | TCP port.                                                                                                                                         |
| `ckan_endpoint` | string                  | no       | empty   | Optional path prefix between the host and the CKAN action API (e.g., `"/additional/endpoint"`). When the API is mounted at the root, leave empty. |
| `token`         | string (Secret) or null | no       | `null`  | CKAN auth token. Some action endpoints require authorization.                                                                                     |

Source: [`CKANPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/ckan.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/ckan.yaml).

```yaml
plugins:
  - type: ckan
    name: ckan_main
    host: ckan.internal
    port: "80"
    ckan_endpoint: ""
    token: !ENV ${CKAN_TOKEN}
```

#### Airbyte (`type: airbyte`)

Catalogs Airbyte connectors, sources, destinations, and the lineage edges between them.

| Field               | Type           | Required | Default | Description                                                                                                                                                                                                                                                                            |
| ------------------- | -------------- | -------- | ------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`              | string         | yes      | —       | Operator-chosen unique plugin name.                                                                                                                                                                                                                                                    |
| `host`              | string         | yes      | —       | Airbyte API host.                                                                                                                                                                                                                                                                      |
| `port`              | string         | yes      | —       | Airbyte API port (typical: `"8000"`).                                                                                                                                                                                                                                                  |
| `user`              | string or null | yes      | —       | Airbyte username. The model is `Optional[str]` with no default — pass a value or `null` for unauthenticated deployments.                                                                                                                                                               |
| `password`          | string or null | yes      | —       | Airbyte password. Same Pydantic shape as `user`.                                                                                                                                                                                                                                       |
| `platform_host_url` | string         | yes      | —       | The ODD Platform URL the adapter advertises in generated ODDRNs for downstream destinations. **This is a per-plugin field on `AirbytePlugin` that overlaps with the collector-level `platform_host_url`** at the top of `collector_config.yaml` — both must be set when using Airbyte. |
| `store_raw_tables`  | boolean        | no       | `true`  | Whether to ingest Airbyte's `_airbyte_raw_*` staging tables. Set to `false` to keep them out of the catalog.                                                                                                                                                                           |

Source: [`AirbytePlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/airbyte.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/airbyte.yaml).

```yaml
plugins:
  - type: airbyte
    name: airbyte_main
    host: airbyte.internal
    port: "8000"
    platform_host_url: http://odd-platform.internal:8080
    user: airbyte
    password: !ENV ${AIRBYTE_PASSWORD}
    store_raw_tables: false
```

#### Fivetran (`type: fivetran`)

Catalogs a single Fivetran connector and its destination via the Fivetran REST API.

| Field            | Type            | Required | Default                      | Description                                                                                                     |
| ---------------- | --------------- | -------- | ---------------------------- | --------------------------------------------------------------------------------------------------------------- |
| `name`           | string          | yes      | —                            | Operator-chosen unique plugin name.                                                                             |
| `base_url`       | string          | no       | `"https://api.fivetran.com"` | Fivetran API base URL. Override only for Fivetran's regional API endpoints.                                     |
| `api_key`        | string          | yes      | —                            | Fivetran API key.                                                                                               |
| `api_secret`     | string (Secret) | yes      | —                            | Fivetran API secret.                                                                                            |
| `connector_id`   | string          | yes      | —                            | Fivetran connector identifier — one plugin = one connector. Add a second plugin entry per additional connector. |
| `destination_id` | string          | yes      | —                            | Fivetran destination identifier corresponding to the connector.                                                 |

Source: [`FivetranPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/fivetran.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/fivetran.yaml).

```yaml
plugins:
  - type: fivetran
    name: fivetran_orders
    api_key: !ENV ${FIVETRAN_API_KEY}
    api_secret: !ENV ${FIVETRAN_API_SECRET}
    connector_id: orders_connector
    destination_id: warehouse_destination
```

#### dbt Cloud catalog import (`type: dbt`)

Pulls dbt model lineage and metadata via a pre-uploaded `catalog.json` on a host the adapter can reach. This is the **pull** dbt adapter — distinct from [`odd-dbt`](/integrations/integrations/odd-dbt), the push-strategy adapter that emits live test results from dbt runs.

| Field             | Type   | Required | Default | Description                                                                                  |
| ----------------- | ------ | -------- | ------- | -------------------------------------------------------------------------------------------- |
| `name`            | string | yes      | —       | Operator-chosen unique plugin name.                                                          |
| `host`            | string | yes      | —       | Logical host used for ODDRN generation — typically the dbt Cloud / dbt Core deployment host. |
| `odd_catalog_url` | string | yes      | —       | URL the adapter fetches the `catalog.json` from.                                             |

Source: [`DbtPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/dbt.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/dbt.yaml).

```yaml
plugins:
  - type: dbt
    name: dbt_catalog
    host: dbt.internal
    odd_catalog_url: https://dbt.internal/catalog.json
```

#### Federated ODD Platform (`type: odd_adapter`)

Pulls metadata from another ODD Platform instance — federate a child platform's catalog into a parent platform.

| Field               | Type   | Required | Default | Description                                                                                                    |
| ------------------- | ------ | -------- | ------- | -------------------------------------------------------------------------------------------------------------- |
| `name`              | string | yes      | —       | Operator-chosen unique plugin name.                                                                            |
| `host`              | string | yes      | —       | URL of the source ODD service that implements the `odd_adapter` Ingress API.                                   |
| `data_source_oddrn` | string | yes      | —       | The ODDRN to advertise as the federated data source root (e.g., `//my_adapter/host/source-platform.internal`). |

Source: [`OddAdapterPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/odd_adapter.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/odd_adapter.yaml).

```yaml
plugins:
  - type: odd_adapter
    name: federated_eu
    host: http://odd-platform-eu.internal:8000
    data_source_oddrn: //my_adapter/host/odd-platform-eu.internal:8000
```

### Machine learning platforms

#### MLflow (`type: mlflow`)

Catalogs MLflow experiments, runs, and registered models from the MLflow tracking and model-registry APIs.

| Field                | Type                   | Required | Default | Description                                                                                                 |
| -------------------- | ---------------------- | -------- | ------- | ----------------------------------------------------------------------------------------------------------- |
| `name`               | string                 | yes      | —       | Operator-chosen unique plugin name.                                                                         |
| `dev_mode`           | boolean                | no       | `false` | Adapter-side dev mode toggle.                                                                               |
| `tracking_uri`       | string                 | yes      | —       | MLflow tracking server URI.                                                                                 |
| `registry_uri`       | string                 | yes      | —       | MLflow model-registry URI (often the same as `tracking_uri`).                                               |
| `filter_experiments` | list of string or null | no       | `null`  | Allowlist of experiment names. When omitted, every experiment is ingested. Literal name list — not a regex. |

Source: [`MlflowPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/mlflow.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/mlflow.yaml).

```yaml
plugins:
  - type: mlflow
    name: mlflow_main
    dev_mode: false
    tracking_uri: https://mlflow.internal
    registry_uri: https://mlflow.internal
    filter_experiments: ["churn_v2", "fraud_detection"]
```

#### Feast feature store (`type: feast`)

Catalogs Feast feature views and entities by reading the Feast repo definition from a path on the collector container.

| Field       | Type   | Required | Default | Description                                                    |
| ----------- | ------ | -------- | ------- | -------------------------------------------------------------- |
| `name`      | string | yes      | —       | Operator-chosen unique plugin name.                            |
| `host`      | string | yes      | —       | Logical host used for ODDRN generation.                        |
| `repo_path` | string | yes      | —       | Path to a checked-out Feast feature-repo inside the container. |

Source: [`FeastPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/feast.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/feast.yaml).

```yaml
plugins:
  - type: feast
    name: feast_features
    host: feast.internal
    repo_path: /opt/feast/feature_repo
```

#### Kubeflow Pipelines (`type: kubeflow`)

Catalogs Kubeflow pipelines, runs, and the lineage edges between them.

| Field             | Type           | Required | Default | Description                                                                                                                                                                                                                   |
| ----------------- | -------------- | -------- | ------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`            | string         | yes      | —       | Operator-chosen unique plugin name.                                                                                                                                                                                           |
| `host`            | string         | yes      | —       | Kubeflow Pipelines host (typically the KFP UI URL).                                                                                                                                                                           |
| `namespace`       | string         | yes      | —       | **Kubernetes namespace** Kubeflow runs in — not the same as ODD's `namespace` metadata field. The Kubeflow plugin redeclares `namespace` as required at the plugin level, which shadows BasePlugin's optional metadata field. |
| `session_cookie0` | string or null | yes      | —       | First half of the KFP session cookie (Istio AuthService split-cookie pattern). The model is `Optional[str]` with no default — provide a value or `null`.                                                                      |
| `session_cookie1` | string or null | yes      | —       | Second half of the KFP session cookie.                                                                                                                                                                                        |

Source: [`KubeflowPlugin` in `odd_collector/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/odd_collector/domain/plugin.py); reference YAML at [`config_examples/kubeflow.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/kubeflow.yaml).

```yaml
plugins:
  - type: kubeflow
    name: kubeflow_main
    host: https://kfp.internal
    namespace: kubeflow-user
    session_cookie0: !ENV ${KFP_COOKIE_0}
    session_cookie1: !ENV ${KFP_COOKIE_1}
```

## Per-adapter feature matrix

Cross-cutting capabilities and where they apply across the 41-adapter set:

| Feature                                                        | Where it applies                                                                                                                                                                                                                                                        | What it does                                                                                                                                                                                                                                                                                                     |
| -------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Regex ingestion filters (`Filter`)**                         | `postgresql.schemas_filter`, `snowflake.schemas_filter`, `cockroachdb.schemas_filter` (inherited from `PostgreSQLPlugin`)                                                                                                                                               | Regex `include` / `exclude` lists scope which schemas / objects the adapter sees. Defaults to "include everything" when omitted. Source: [`Filter` in `odd_collector_sdk/domain/filter.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-sdk/odd_collector_sdk/domain/filter.py). |
| **Literal-name allowlist filters**                             | `redshift.schemas` (schemas), `databricks.catalogs` (Unity Catalog catalogs), `mlflow.filter_experiments` (experiment names)                                                                                                                                            | Plain list of names the adapter restricts ingestion to. **Not** a regex — literal exact match. When omitted, the adapter ingests everything visible to the credentials.                                                                                                                                          |
| **ERD relationships (foreign keys)**                           | `postgresql`, `snowflake`, `cockroachdb` (via PostgreSQL inheritance)                                                                                                                                                                                                   | The adapter emits `ENTITY_RELATIONSHIP` entities for tables connected by foreign keys, including cross-schema. The platform renders these as ERD edges on dataset detail pages. No other adapter currently extracts foreign-key relationships.                                                                   |
| **TLS toggles on the source connection**                       | `clickhouse.secure` + `clickhouse.verify`, `mysql.ssl_disabled`, `singlestore.ssl_disabled`, `elasticsearch.verify_certs` + `elasticsearch.ca_certs`, `opensearch.use_ssl` + `opensearch.verify_certs` + `opensearch.ca_certs`                                          | Per-adapter knobs for TLS toggling and certificate validation. Defaults are tuned per adapter (see each section above) — only override for self-signed certs on local clusters or for unencrypted local development.                                                                                             |
| **Token-based auth (PAT / API token alternative to password)** | `tableau.token_name` + `tableau.token_value`, `databricks.token`, `redash.api_key`, `fivetran.api_key` + `fivetran.api_secret`, `cubejs.token`, `mlflow` (via `tracking_uri` auth), `ckan.token`, `mode.token`, `kubeflow.session_cookie0` + `kubeflow.session_cookie1` | Replaces username/password auth; required when the source enforces SSO / 2FA / MFA on user accounts.                                                                                                                                                                                                             |
| **Schema inference via document sampling**                     | `couchbase.sample_size` + `couchbase.num_sample_values`                                                                                                                                                                                                                 | The adapter samples N documents per collection to derive a structural view of fields and value types. Defaults to no sampling (`sample_size: 0`) — set explicitly to enable.                                                                                                                                     |
| **Sub-object connection block (advanced auth surface)**        | `hive.connection_params` (full HS2 connection knob set), `cubejs.predefined_datasource` (postgres / clickhouse only — used to resolve cube-to-source lineage)                                                                                                           | Some adapters expose a nested object instead of flat fields when the auth or lineage surface needs more knobs than a flat schema supports.                                                                                                                                                                       |
| **Multiple file paths in one plugin**                          | `duckdb.paths`                                                                                                                                                                                                                                                          | DuckDB accepts a list of `.db` files or directories of `.db` files in one plugin — every file is opened independently. Other file-source adapters (`sqlite`) take a single path.                                                                                                                                 |
| **Special operating modes**                                    | `oracle.thick_mode` (Oracle Instant Client vs. pure-Python), `cubejs.dev_mode` (relax token requirement), `mlflow.dev_mode`                                                                                                                                             | Adapter-level toggles that alter runtime behaviour or auth strictness; safe defaults are off.                                                                                                                                                                                                                    |

Other adapters either do not expose filters (the SDK ones don't carry a `Filter` field) or do not emit relationships. For the filter mechanism's user-facing explanation (include / exclude semantics, when filters apply, default behaviour without filters), see [Ingestion filters](/integrations/integrations/ingestion-filters). The full cross-adapter capability matrix — which adapter exposes which filter, which emits which relationship type — lives on the [`odd-collectors` monorepo README](https://github.com/opendatadiscovery/odd-collectors#ingestion-filters-configuration); check that table when planning a new deployment.

## Known limitations

* **README drift on the source repo**: as flagged above, the upstream README's adapter table omits four adapters (`databricks`, `couchbase`, `opensearch`, `oracle`) that exist in `PLUGIN_FACTORY`. This is a docs gap on the collector repo, not a missing capability — those four adapters work; they're just under-advertised.
* **Foreign-key extraction is PostgreSQL/Snowflake only** today. ClickHouse, MySQL, MSSQL, and others extract schemas and columns but not foreign-key relationships.
* **No per-plugin `pulling_interval`**: every plugin in the file shares `default_pulling_interval`. Splitting workloads with different cadences requires running multiple collector containers, each with its own config.
* **M1 / Apple Silicon build issues**: `pyodbc`, `confluent-kafka`, and `grpcio` need extra environment variables to build natively. See the [generic collector README → M1 building issue](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector#m1-building-issue).
* **`odbc.driver` upstream typo**: `OdbcPlugin.driver` defaults to `"{ODBC Driver 17s for SQL Server}"` (with an extra `s`) — `s` should not be in the driver string. Always set `driver:` explicitly in the plugin config to the registered driver name on your container (e.g., `{ODBC Driver 17 for SQL Server}` or your platform's equivalent). Without an explicit value, the adapter's connection attempt fails because no ODBC driver matches the typoed string. The reference YAML at `config_examples/odbc.yaml` uses the correct value, so copy from there rather than relying on the model default.
* **Missing upstream config examples for `mode` and `opensearch`**: both adapters are present in `PLUGIN_FACTORY` and shipped, but `odd-collectors/odd-collector/config_examples/` does not contain a `mode.yaml` or `opensearch.yaml`. The per-adapter sections above include hand-crafted YAML examples derived from the Pydantic models for both.
* **`config_examples/cocroachdb.yaml` filename typo**: the file containing the CockroachDB reference YAML is `cocroachdb.yaml` (missing the `k`). The type literal (`cockroachdb`) is correct — the file's contents work as-is; only the filename is misspelled.

## Where to next

* [`odd-collector-aws`](/integrations/integrations/odd-collector-aws) — when your source is an AWS managed service.
* [`odd-collector-azure`](/integrations/integrations/odd-collector-azure) / [`odd-collector-gcp`](/integrations/integrations/odd-collector-gcp) — for Azure / GCP.
* [`odd-collector-profiler`](/integrations/integrations/odd-collector-profiler) — when you want statistical profiles on a Postgres / Azure SQL source.
* [Collector secrets backend](/configuration-and-deployment/collectors-secrets-backend) — to source any field from AWS SSM instead of inline YAML.
* [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors) — full SDK config reference and from-source build / run instructions.


# odd-collector-aws

AWS-services pull collector — 11 adapters for Glue, S3, Athena, Kinesis, SageMaker, and more.

{% hint style="info" %}
**Status: Stable.** Released as a tagged Docker image alongside the rest of the `odd-collectors` monorepo.
{% endhint %}

`odd-collector-aws` packages adapters for AWS managed services. Like the other pull collectors, it ships as a daemon container that hosts one or more configured plugins; one container can host multiple plugins of any combination of types.

For the broader pull-vs-push picture, start at the [Integrations hub](/integrations/integrations). For deployment-side detail (build, Docker, env vars), see [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors).

## Supported adapters

The 11 adapters registered in `odd_collector_aws/domain/plugin.py` (`PLUGIN_FACTORY`). Every adapter has per-field documentation below — two (`glue`, `s3`) get longer deep-dive spotlights with deployment guidance and feature notes; the remaining 9 are catalogued in the [per-adapter configuration reference](#per-adapter-configuration-reference) section.

| Type literal             | AWS service                    | Spotlighted below |
| ------------------------ | ------------------------------ | ----------------- |
| `athena`                 | Amazon Athena                  |                   |
| `dms`                    | AWS Database Migration Service |                   |
| `dynamodb`               | DynamoDB                       |                   |
| `glue`                   | AWS Glue Data Catalog          | ✓                 |
| `kinesis`                | Amazon Kinesis                 |                   |
| `quicksight`             | Amazon QuickSight              |                   |
| `s3`                     | Amazon S3 (object catalog)     | ✓                 |
| `s3_delta`               | Amazon S3 — Delta Lake tables  |                   |
| `sagemaker`              | Amazon SageMaker               |                   |
| `sagemaker_featurestore` | SageMaker Feature Store        |                   |
| `sqs`                    | Amazon SQS                     |                   |

The reference YAML for each adapter lives at [`odd-collectors/odd-collector-aws/config_examples/`](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-aws/config_examples). The Pydantic models that define accepted fields live at [`odd-collector-aws/odd_collector_aws/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py).

## Common AWS authentication

Every adapter inherits from `AwsPlugin` and accepts the same set of optional AWS auth fields. When unset, the underlying `boto3` client falls back to its standard credential chain — environment variables, `~/.aws/credentials`, EC2 / EKS instance profile, etc.

| Field                   | Type   | Default | Description                                                                          |
| ----------------------- | ------ | ------- | ------------------------------------------------------------------------------------ |
| `aws_access_key_id`     | string | `None`  | Static access key.                                                                   |
| `aws_secret_access_key` | string | `None`  | Static secret key.                                                                   |
| `aws_session_token`     | string | `None`  | Required when using temporary credentials.                                           |
| `aws_region`            | string | `None`  | AWS region. Required for region-bound services when no environment default exists.   |
| `aws_account_id`        | string | `None`  | Account ID. Required by `kinesis`.                                                   |
| `profile_name`          | string | `None`  | Named profile from `~/.aws/credentials`.                                             |
| `aws_role_arn`          | string | `None`  | Role ARN to assume.                                                                  |
| `aws_role_session_name` | string | `None`  | Session name for the assumed role.                                                   |
| `endpoint_url`          | string | `None`  | Override the AWS endpoint — used for LocalStack and S3-compatible stores like MinIO. |

Source: [`AwsPlugin` base in `odd-collector-aws/odd_collector_aws/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py).

{% hint style="warning" %}
The container image pulls credentials from environment variables by convention (`AWS_REGION`, `AWS_ACCESS_KEY_ID`, `AWS_SECRET_ACCESS_KEY`). Inline YAML credentials work but are typically left empty for IAM-role-based deployments — the [reference Compose file](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-aws#docker-compose-example) wires them as env-vars only. Prefer IAM roles over static keys in production.
{% endhint %}

## Installation

```bash
docker pull ghcr.io/opendatadiscovery/odd-collector-aws:latest
```

Mount a `collector_config.yaml` at `/app/collector_config.yaml`. A reference Compose snippet is in the [aws collector README](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-aws#docker-compose-example).

## Minimal config

```yaml
platform_host_url: http://localhost:8080
token: <COLLECTOR_TOKEN>
default_pulling_interval: 10
plugins:
  - type: glue
    name: glue_main
    aws_region: eu-central-1
    # Static keys optional — falls back to the boto3 default credential chain.
```

## Multiple plugins in one container

A single `odd-collector-aws` instance commonly fans out across multiple AWS accounts or regions:

```yaml
plugins:
  - type: glue
    name: glue_eu
    aws_region: eu-central-1
    aws_role_arn: arn:aws:iam::111111111111:role/odd-reader
    aws_role_session_name: odd
  - type: glue
    name: glue_us
    aws_region: us-east-1
    aws_role_arn: arn:aws:iam::222222222222:role/odd-reader
    aws_role_session_name: odd
  - type: s3
    name: data_lake
    aws_region: eu-central-1
    dataset_config:
      bucket: my-data-lake
      prefix: gold/
```

Plugin `name` must be unique within the file.

## Spotlight: Glue (`type: glue`)

Pulls the AWS Glue Data Catalog — databases, tables, columns, partition keys.

| Field           | Type   | Required    | Default | Description                                      |
| --------------- | ------ | ----------- | ------- | ------------------------------------------------ |
| `name`          | string | yes         | —       | Operator-chosen unique plugin name.              |
| `aws_region`    | string | recommended | `None`  | AWS region. Glue is region-bound.                |
| AWS auth fields | —      | —           | —       | See the common AWS authentication section above. |

Source: [`GluePlugin` in `odd-collector-aws/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py); reference YAML at [`config_examples/glue.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/config_examples/glue.yaml).

```yaml
plugins:
  - type: glue
    name: glue_main
    aws_region: eu-central-1
    aws_access_key_id: !ENV ${AWS_ACCESS_KEY_ID}
    aws_secret_access_key: !ENV ${AWS_SECRET_ACCESS_KEY}
```

## Spotlight: S3 (`type: s3`)

Pulls a curated set of S3 objects (or folders treated as datasets) and infers their schema. Supports CSV / TSV / Parquet, with explicit support for Hive-style partitioning.

| Field                              | Type          | Required | Default  | Description                                                                     |
| ---------------------------------- | ------------- | -------- | -------- | ------------------------------------------------------------------------------- |
| `name`                             | string        | yes      | —        | Operator-chosen unique plugin name.                                             |
| `dataset_config.bucket`            | string        | yes      | —        | S3 bucket name.                                                                 |
| `dataset_config.prefix`            | string        | no       | empty    | Path prefix inside the bucket.                                                  |
| `dataset_config.folder_as_dataset` | object        | no       | —        | Treat a folder as a single partitioned dataset (see partitioned example below). |
| `endpoint_url`                     | string        | no       | `None`   | Override for S3-compatible stores (MinIO, LocalStack).                          |
| `filename_filter.include`          | list of regex | no       | `[".*"]` | Object names to include.                                                        |
| `filename_filter.exclude`          | list of regex | no       | `[]`     | Object names to drop after `include` matches.                                   |
| AWS auth fields                    | —             | —        | —        | See the common AWS authentication section above.                                |

Source: [`S3Plugin` in `odd-collector-aws/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py); reference YAML at [`config_examples/s3.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/config_examples/s3.yaml).

```yaml
plugins:
  # Single object as a dataset.
  - type: s3
    name: orders_csv
    aws_region: eu-central-1
    dataset_config:
      bucket: my_bucket
      prefix: folder/subfolder/orders.csv
    filename_filter:
      include: [".*\\.parquet$"]
      exclude: ["dev_.*"]
  # Hive-partitioned folder treated as one dataset.
  - type: s3
    name: events_partitioned
    aws_region: eu-central-1
    dataset_config:
      bucket: my_bucket
      prefix: events/
      folder_as_dataset:
        file_format: parquet
        flavor: hive
  # MinIO (S3-compatible) using endpoint_url.
  - type: s3
    name: dev_minio
    endpoint_url: http://localhost:9000
    aws_access_key_id: minioadmin
    aws_secret_access_key: minioadmin
    dataset_config:
      bucket: dev-bucket
```

{% hint style="warning" %}
The legacy `datasets:` field on `S3Plugin` is deprecated and rejected at validation time. Use `dataset_config` (singular) — the reference YAML and the Pydantic validator both enforce this.
{% endhint %}

## Per-adapter configuration reference

The two spotlights above cover the deployment-shape questions; this section enumerates the per-field config schema for the remaining 9 adapters. Field names, types, and defaults are sourced from the Pydantic plugin classes in [`odd_collector_aws/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py); each adapter links to its `config_examples/{type}.yaml` reference YAML.

Every adapter inherits from `AwsPlugin` (documented under [Common AWS authentication](#common-aws-authentication) above) and therefore accepts the standard AWS auth fields `aws_access_key_id`, `aws_secret_access_key`, `aws_session_token`, `aws_region`, `aws_account_id`, `profile_name`, `aws_role_arn`, `aws_role_session_name`, and `endpoint_url`. The per-adapter tables below list **only adapter-specific fields** plus call out which AWS auth fields a given service requires in practice.

### Amazon Athena (`type: athena`)

Catalogs Athena workgroups, databases, tables, and views.

The plugin declares no fields beyond the `AwsPlugin` base — `aws_region` is required in practice (Athena is region-bound) and the rest of the AWS auth set follows the boto3 default credential chain when unset.

| Field           | Type   | Required | Default | Description                                                                                        |
| --------------- | ------ | -------- | ------- | -------------------------------------------------------------------------------------------------- |
| `name`          | string | yes      | —       | Operator-chosen unique plugin name.                                                                |
| AWS auth fields | —      | —        | —       | See [Common AWS authentication](#common-aws-authentication). `aws_region` is required in practice. |

Source: [`AthenaPlugin` in `odd_collector_aws/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py); reference YAML at [`config_examples/athena.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/config_examples/athena.yaml).

```yaml
plugins:
  - type: athena
    name: athena_main
    aws_region: eu-central-1
    aws_access_key_id: !ENV ${AWS_ACCESS_KEY_ID}
    aws_secret_access_key: !ENV ${AWS_SECRET_ACCESS_KEY}
```

### AWS Database Migration Service (`type: dms`)

Catalogs DMS replication instances, endpoints, and tasks.

| Field           | Type   | Required | Default | Description                                                                                        |
| --------------- | ------ | -------- | ------- | -------------------------------------------------------------------------------------------------- |
| `name`          | string | yes      | —       | Operator-chosen unique plugin name.                                                                |
| AWS auth fields | —      | —        | —       | See [Common AWS authentication](#common-aws-authentication). `aws_region` is required in practice. |

Source: [`DmsPlugin` in `odd_collector_aws/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py); reference YAML at [`config_examples/dms.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/config_examples/dms.yaml).

```yaml
plugins:
  - type: dms
    name: dms_main
    aws_region: eu-central-1
    aws_access_key_id: !ENV ${AWS_ACCESS_KEY_ID}
    aws_secret_access_key: !ENV ${AWS_SECRET_ACCESS_KEY}
```

### DynamoDB (`type: dynamodb`)

Catalogs DynamoDB tables and infers attribute types from a row sample. The adapter scopes to one region per plugin.

| Field            | Type                   | Required | Default | Description                                                                                                                                                                        |
| ---------------- | ---------------------- | -------- | ------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`           | string                 | yes      | —       | Operator-chosen unique plugin name.                                                                                                                                                |
| `exclude_tables` | list of string or null | no       | `[]`    | Literal table-name list to skip (e.g., to exclude internal / staging tables). Plain name match — not regex.                                                                        |
| AWS auth fields  | —                      | —        | —       | See [Common AWS authentication](#common-aws-authentication). `aws_region` is required in practice; `endpoint_url` works for LocalStack and other DynamoDB-compatible local stores. |

Source: [`DynamoDbPlugin` in `odd_collector_aws/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py); reference YAML at [`config_examples/dynamodb.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/config_examples/dynamodb.yaml).

```yaml
plugins:
  - type: dynamodb
    name: dynamodb_main
    aws_region: eu-central-1
    aws_access_key_id: !ENV ${AWS_ACCESS_KEY_ID}
    aws_secret_access_key: !ENV ${AWS_SECRET_ACCESS_KEY}
    exclude_tables: ["staging_audit", "tmp_migration"]
```

### Amazon Kinesis (`type: kinesis`)

Catalogs Kinesis streams in one account / region per plugin.

| Field            | Type   | Required | Default | Description                                                                                                                                                                                              |
| ---------------- | ------ | -------- | ------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`           | string | yes      | —       | Operator-chosen unique plugin name.                                                                                                                                                                      |
| `aws_account_id` | string | **yes**  | —       | **Required for `kinesis`.** Other adapters inherit `aws_account_id` as `Optional[str]` from `AwsPlugin`; `KinesisPlugin` redeclares it as required. The collector errors out on startup if it isn't set. |
| AWS auth fields  | —      | —        | —       | See [Common AWS authentication](#common-aws-authentication). `aws_region` is required in practice.                                                                                                       |

Source: [`KinesisPlugin` in `odd_collector_aws/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py); reference YAML at [`config_examples/kinesis.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/config_examples/kinesis.yaml).

```yaml
plugins:
  - type: kinesis
    name: kinesis_main
    aws_region: eu-central-1
    aws_account_id: "123456789012"
    aws_access_key_id: !ENV ${AWS_ACCESS_KEY_ID}
    aws_secret_access_key: !ENV ${AWS_SECRET_ACCESS_KEY}
```

### Amazon QuickSight (`type: quicksight`)

Catalogs QuickSight datasets, dashboards, and analyses.

| Field           | Type   | Required | Default | Description                                                                                        |
| --------------- | ------ | -------- | ------- | -------------------------------------------------------------------------------------------------- |
| `name`          | string | yes      | —       | Operator-chosen unique plugin name.                                                                |
| AWS auth fields | —      | —        | —       | See [Common AWS authentication](#common-aws-authentication). `aws_region` is required in practice. |

Source: [`QuicksightPlugin` in `odd_collector_aws/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py); reference YAML at [`config_examples/quicksight.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/config_examples/quicksight.yaml).

```yaml
plugins:
  - type: quicksight
    name: quicksight_main
    aws_region: eu-central-1
    aws_access_key_id: !ENV ${AWS_ACCESS_KEY_ID}
    aws_secret_access_key: !ENV ${AWS_SECRET_ACCESS_KEY}
```

### S3 Delta Lake (`type: s3_delta`)

Catalogs Delta Lake tables stored in S3 (or any S3-compatible storage). The adapter reads the Delta `_delta_log/` to recover the table's evolved schema rather than inferring it from the underlying Parquet files.

| Field                         | Type                    | Required | Default  | Description                                                                                                                                                                                                                                                        |
| ----------------------------- | ----------------------- | -------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `name`                        | string                  | yes      | —        | Operator-chosen unique plugin name.                                                                                                                                                                                                                                |
| `delta_tables`                | object                  | yes      | —        | A **single** Delta-table descriptor (`bucket`, `prefix`, optional `filter`). Note: this is one object — not a list — different from `gcs_delta` on the GCP collector which takes a list. To catalog multiple Delta tables, use multiple `s3_delta` plugin entries. |
| `delta_tables.bucket`         | string                  | yes      | —        | S3 bucket name.                                                                                                                                                                                                                                                    |
| `delta_tables.prefix`         | string                  | yes      | —        | Path prefix inside the bucket pointing at the Delta table root (the directory containing `_delta_log/`).                                                                                                                                                           |
| `delta_tables.filter.include` | list of regex           | no       | `[".*"]` | Per-table regex include list applied during enumeration.                                                                                                                                                                                                           |
| `delta_tables.filter.exclude` | list of regex           | no       | `[]`     | Per-table regex exclude list.                                                                                                                                                                                                                                      |
| `delta_tables.scheme`         | string (alias `schema`) | no       | `"s3"`   | Storage scheme. Defaults to `s3` — override only when pointing the adapter at a non-S3 Delta location. The model accepts `schema` as an alias for backward compatibility.                                                                                          |
| `endpoint_url`                | string or null          | no       | `null`   | Override for S3-compatible endpoints (LocalStack, MinIO). Re-declared on `S3DeltaPlugin` over the inherited `AwsPlugin` field for clarity.                                                                                                                         |
| `aws_storage_allow_http`      | boolean or null         | no       | `false`  | Permit plain-HTTP access to the storage backend. Set to `true` for local MinIO / LocalStack deployments using `http://`; leave `false` for production S3.                                                                                                          |
| AWS auth fields               | —                       | —        | —        | See [Common AWS authentication](#common-aws-authentication).                                                                                                                                                                                                       |

Source: [`S3DeltaPlugin` and `DeltaTableConfig` in `odd_collector_aws/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py); reference YAML at [`config_examples/s3_delta.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/config_examples/s3_delta.yaml).

```yaml
plugins:
  # Production S3.
  - type: s3_delta
    name: lake_delta_prod
    aws_region: eu-central-1
    aws_access_key_id: !ENV ${AWS_ACCESS_KEY_ID}
    aws_secret_access_key: !ENV ${AWS_SECRET_ACCESS_KEY}
    delta_tables:
      bucket: data-lake
      prefix: gold/orders/
      filter:
        include: ["events"]
        exclude: ["_pii"]
  # MinIO (S3-compatible) for local dev.
  - type: s3_delta
    name: lake_delta_minio
    endpoint_url: http://localhost:9000
    aws_storage_allow_http: true
    aws_access_key_id: minioadmin
    aws_secret_access_key: minioadmin
    delta_tables:
      bucket: dev-bucket
      prefix: delta_data
```

### Amazon SageMaker (`type: sagemaker`)

Catalogs SageMaker experiments, trials, and model artifacts.

{% hint style="warning" %}
**`SagemakerPlugin` re-declares the AWS auth fields and `experiments` without defaults**, which makes them effectively required in Pydantic — the adapter will not start until you provide `aws_access_key_id`, `aws_secret_access_key`, `aws_region`, `aws_session_token`, `aws_account_id`, and `experiments` (each can be `null` if you intend to fall back to the boto3 credential chain or to ingest every experiment, but the keys must be present in the YAML). This is asymmetric with every other AWS adapter in the collector. Set values explicitly or pass `null` per field.
{% endhint %}

| Field                                                                   | Type                   | Required | Default | Description                                                                                                                                                                                                            |
| ----------------------------------------------------------------------- | ---------------------- | -------- | ------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`                                                                  | string                 | yes      | —       | Operator-chosen unique plugin name.                                                                                                                                                                                    |
| `aws_secret_access_key`                                                 | string or null         | yes      | —       | Required at the model level (re-declared without default).                                                                                                                                                             |
| `aws_access_key_id`                                                     | string or null         | yes      | —       | Required at the model level (re-declared without default).                                                                                                                                                             |
| `aws_region`                                                            | string or null         | yes      | —       | Required at the model level (re-declared without default).                                                                                                                                                             |
| `aws_session_token`                                                     | string or null         | yes      | —       | Required at the model level (re-declared without default).                                                                                                                                                             |
| `aws_account_id`                                                        | string or null         | yes      | —       | Required at the model level (re-declared without default).                                                                                                                                                             |
| `experiments`                                                           | list of string or null | yes      | —       | Allowlist of SageMaker experiment names to scope ingestion. The model is `Optional[list[str]]` with no default — pass an explicit list to scope or `null` to ingest every experiment. Literal name list — not a regex. |
| `profile_name`, `aws_role_arn`, `aws_role_session_name`, `endpoint_url` | —                      | —        | —       | Inherited from `AwsPlugin`; see [Common AWS authentication](#common-aws-authentication).                                                                                                                               |

Source: [`SagemakerPlugin` in `odd_collector_aws/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py); reference YAML at [`config_examples/sagemaker.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/config_examples/sagemaker.yaml).

```yaml
plugins:
  - type: sagemaker
    name: sagemaker_main
    aws_region: eu-central-1
    aws_access_key_id: !ENV ${AWS_ACCESS_KEY_ID}
    aws_secret_access_key: !ENV ${AWS_SECRET_ACCESS_KEY}
    aws_session_token: null
    aws_account_id: "123456789012"
    experiments: ["churn_v2", "fraud_detection"]
```

### SageMaker Feature Store (`type: sagemaker_featurestore`)

Catalogs SageMaker Feature Store feature groups and feature definitions.

| Field           | Type   | Required | Default | Description                                                                                        |
| --------------- | ------ | -------- | ------- | -------------------------------------------------------------------------------------------------- |
| `name`          | string | yes      | —       | Operator-chosen unique plugin name.                                                                |
| AWS auth fields | —      | —        | —       | See [Common AWS authentication](#common-aws-authentication). `aws_region` is required in practice. |

Source: [`SagemakerFeaturestorePlugin` in `odd_collector_aws/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py); reference YAML at [`config_examples/sagemaker_featurestore.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/config_examples/sagemaker_featurestore.yaml).

```yaml
plugins:
  - type: sagemaker_featurestore
    name: sagemaker_features
    aws_region: eu-central-1
    aws_access_key_id: !ENV ${AWS_ACCESS_KEY_ID}
    aws_secret_access_key: !ENV ${AWS_SECRET_ACCESS_KEY}
```

### Amazon SQS (`type: sqs`)

Catalogs SQS queues in one region per plugin.

| Field           | Type   | Required | Default | Description                                                                                        |
| --------------- | ------ | -------- | ------- | -------------------------------------------------------------------------------------------------- |
| `name`          | string | yes      | —       | Operator-chosen unique plugin name.                                                                |
| AWS auth fields | —      | —        | —       | See [Common AWS authentication](#common-aws-authentication). `aws_region` is required in practice. |

Source: [`SQSPlugin` in `odd_collector_aws/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py); reference YAML at [`config_examples/sqs.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/config_examples/sqs.yaml).

```yaml
plugins:
  - type: sqs
    name: sqs_main
    aws_region: eu-central-1
    aws_access_key_id: !ENV ${AWS_ACCESS_KEY_ID}
    aws_secret_access_key: !ENV ${AWS_SECRET_ACCESS_KEY}
```

## Per-adapter feature matrix

| Feature                                         | Where it applies                                                                                                                                                                   |
| ----------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Ingestion filters (`filename_filter`)**       | `s3`, `s3_delta` (via `delta_tables.filter`). Regex `include` / `exclude` lists; default includes everything.                                                                      |
| **Folder-as-dataset / Hive partitioning**       | `s3`. `dataset_config.folder_as_dataset` accepts `file_format` (`parquet` / `csv` / `tsv`), `flavor` (`hive` / `presto`), and an optional `field_names` list for non-Hive layouts. |
| **Cross-region credentials via `aws_role_arn`** | Every adapter inheriting from `AwsPlugin`.                                                                                                                                         |
| **`endpoint_url` override**                     | `s3`, `s3_delta`, `dynamodb` (and any AWS-SDK call boto3 routes through the configured endpoint). Used for LocalStack and MinIO.                                                   |
| **`exclude_tables`**                            | `dynamodb`. Plain list of table names to skip.                                                                                                                                     |
| **`aws_storage_allow_http` toggle**             | `s3_delta`. Enables plain-HTTP storage access (MinIO / LocalStack); off by default.                                                                                                |
| **Literal-name allowlist filters**              | `sagemaker.experiments` (experiment names). Plain list — not a regex. Required at the model level (no default); pass `null` to ingest every experiment, or a list to scope.        |
| **Required `aws_account_id`**                   | `kinesis`. Re-declared as required (the rest of the AWS adapters take `aws_account_id` as `Optional[str]`).                                                                        |

Source: [`PLUGIN_FACTORY` in `odd-collector-aws/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-aws/odd_collector_aws/domain/plugin.py).

The cloud collectors do **not** ship with the AWS SSM secrets backend hook that `odd-collector` (the generic one) ships — see [Collector secrets backend](/configuration-and-deployment/collectors-secrets-backend) for the supported scope.

## Known limitations

* **Static credentials in YAML are not the recommended path.** IAM roles via `aws_role_arn` (or pod-identity / instance-profile) avoid leaking long-lived keys into config files. The reference Compose template wires credentials only as env-vars.
* **`s3.datasets` field rejected at validation.** Use `dataset_config` (singular). The collector errors out on startup if `datasets:` is present — see the `validate_datasets` validator on `S3Plugin`.
* **No foreign-key / ERD extraction** in any AWS adapter — that capability is PostgreSQL- and Snowflake-only on the generic collector.
* **`kinesis` requires `aws_account_id` explicitly** — it's the only field outside the common AWS auth set that is required for `kinesis`.
* **`sagemaker` re-declares the AWS auth fields without defaults**, making them effectively required even when you intend to inherit from the boto3 credential chain. Provide each field explicitly (use `null` when you want the boto3 fallback). This is an asymmetry with the rest of the adapters in the collector.
* **`s3_delta.delta_tables` is a single object**, not a list. To catalog multiple Delta tables in one collector, use multiple `s3_delta` plugin entries. This is an asymmetry with `gcs_delta` on the GCP collector, which takes a list of `delta_tables`.
* **`s3.dataset_config` is a single object**, not a list. To catalog multiple S3 buckets, use multiple `s3` plugin entries.

## Where to next

* [`odd-collector`](/integrations/integrations/odd-collector) — generic collector with PostgreSQL, Snowflake, etc.
* [`odd-collector-azure`](/integrations/integrations/odd-collector-azure) / [`odd-collector-gcp`](/integrations/integrations/odd-collector-gcp) — sibling cloud collectors.
* [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors) — common SDK schema and from-source build flow.


# odd-collector-azure

Azure-services pull collector — adapters for PowerBI, Azure SQL, Blob Storage, and Data Factory.

{% hint style="info" %}
**Status: Stable.** Released as a tagged Docker image alongside the rest of the `odd-collectors` monorepo.
{% endhint %}

`odd-collector-azure` packages adapters for Azure managed services. Like the other pull collectors, it ships as a daemon container that hosts one or more configured plugins; one container can host multiple plugins of any combination of types.

For the broader pull-vs-push picture, start at the [Integrations hub](/integrations/integrations). For deployment-side detail, see [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors).

## Supported adapters

The 4 adapters registered in `odd_collector_azure/domain/plugin.py` (`PLUGIN_FACTORY`):

| Type literal         | Azure service                                                 | Spotlighted below |
| -------------------- | ------------------------------------------------------------- | ----------------- |
| `powerbi`            | Microsoft PowerBI (workspaces, datasets, reports, dashboards) | ✓                 |
| `azure_sql`          | Azure SQL Database                                            |                   |
| `blob_storage`       | Azure Blob Storage                                            | ✓                 |
| `azure_data_factory` | Azure Data Factory pipelines                                  |                   |

The reference YAML for each adapter lives at [`odd-collectors/odd-collector-azure/config_examples/`](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-azure/config_examples). The Pydantic models that define accepted fields live at [`odd-collector-azure/odd_collector_azure/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-azure/odd_collector_azure/domain/plugin.py).

## Installation

```bash
docker pull ghcr.io/opendatadiscovery/odd-collector-azure:latest
```

Mount a `collector_config.yaml` at `/app/collector_config.yaml`. A reference Compose snippet is in the [azure collector README](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-azure#docker-compose-example).

## Minimal config

```yaml
platform_host_url: http://localhost:8080
token: <COLLECTOR_TOKEN>
default_pulling_interval: 10
plugins:
  - type: powerbi
    name: powerbi_main
    client_id: <AAD_APP_CLIENT_ID>
    client_secret: !ENV ${POWERBI_CLIENT_SECRET}
    username: odd-reader@yourdomain.com
    password: !ENV ${POWERBI_PASSWORD}
    domain: yourdomain.com
```

## Multiple plugins in one container

```yaml
plugins:
  - type: powerbi
    name: powerbi_finance
    client_id: !ENV ${PB_FIN_CLIENT_ID}
    client_secret: !ENV ${PB_FIN_CLIENT_SECRET}
    username: odd-reader@finance.example.com
    password: !ENV ${PB_FIN_PASSWORD}
    domain: finance.example.com
  - type: blob_storage
    name: lake_raw
    account_name: rawlake
    account_key: !ENV ${BLOB_RAW_KEY}
    dataset_config:
      - container: events
        prefix: /
  - type: azure_data_factory
    name: adf_orchestration
    subscription: <SUBSCRIPTION_ID>
    resource_group: data-rg
    factory: dataflows
```

## Spotlight: PowerBI (`type: powerbi`)

Pulls workspaces, datasets, reports, and dashboards from PowerBI via the Azure AD-authenticated REST API.

| Field           | Type   | Required | Default | Description                                     |
| --------------- | ------ | -------- | ------- | ----------------------------------------------- |
| `name`          | string | yes      | —       | Operator-chosen unique plugin name.             |
| `client_id`     | string | yes      | —       | Client ID of the Azure AD app registration.     |
| `client_secret` | string | yes      | —       | Client secret of the Azure AD app registration. |
| `username`      | string | yes      | —       | PowerBI account email.                          |
| `password`      | string | yes      | —       | PowerBI account password.                       |
| `domain`        | string | yes      | —       | Tenant domain (e.g. `yourdomain.com`).          |

Source: [`PowerBiPlugin` / `AzurePlugin` in `odd-collector-azure/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-azure/odd_collector_azure/domain/plugin.py); reference YAML at [`config_examples/power_bi.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-azure/config_examples/power_bi.yaml).

```yaml
plugins:
  - type: powerbi
    name: powerbi_main
    client_id: <client_id>
    client_secret: !ENV ${POWERBI_CLIENT_SECRET}
    username: odd-reader@yourdomain.com
    password: !ENV ${POWERBI_PASSWORD}
    domain: yourdomain.com
```

## Spotlight: Blob Storage (`type: blob_storage`)

Pulls Blob containers and infers dataset schema from objects (files) inside them. The shape of `dataset_config` mirrors the AWS S3 plugin — the expected list pattern is `container` + `prefix` per dataset.

| Field                 | Type            | Required | Default  | Description                                                           |
| --------------------- | --------------- | -------- | -------- | --------------------------------------------------------------------- |
| `name`                | string          | yes      | —        | Operator-chosen unique plugin name.                                   |
| `account_name`        | string          | yes      | —        | Storage account name.                                                 |
| `account_key`         | string (Secret) | one-of   | —        | Account key. Use **either** `account_key` **or** `connection_string`. |
| `connection_string`   | string (Secret) | one-of   | —        | Full connection string from the Azure portal.                         |
| `dataset_config`      | list of objects | yes      | —        | List of `{ container, prefix }` entries.                              |
| `file_filter.include` | list of regex   | no       | `[".*"]` | File-name patterns to include.                                        |
| `file_filter.exclude` | list of regex   | no       | `[]`     | File-name patterns to drop after `include` matches.                   |

Source: [`BlobPlugin` in `odd-collector-azure/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-azure/odd_collector_azure/domain/plugin.py); reference YAML at [`config_examples/blob_storage.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-azure/config_examples/blob_storage.yaml).

```yaml
plugins:
  - type: blob_storage
    name: lake_raw
    account_name: rawlake
    account_key: !ENV ${BLOB_RAW_KEY}
    file_filter:
      include: [".*\\.parquet$"]
      exclude: ["dev_.*"]
    dataset_config:
      - container: events
        prefix: /
      - container: enriched
        prefix: gold/
```

{% hint style="warning" %}
The legacy `datasets:` field on `BlobPlugin` is deprecated and rejected at validation time. Use `dataset_config` (singular) — the Pydantic validator throws an error on startup if `datasets:` is present.
{% endhint %}

## Spotlight: Azure SQL (`type: azure_sql`)

Pulls databases, schemas, tables, views, and columns from Azure SQL Database via SQL Server's catalog views.

`AzureSQLPlugin` does **not** inherit from `AzurePlugin` (the AAD-app pattern that PowerBI uses) — Azure SQL authenticates with a SQL login (`username` + `password`), not with `client_id` + `client_secret` + tenant. Use a SQL Server contained user or an AAD password-grant user; AAD interactive / managed-identity is not supported by this adapter.

| Field                      | Type   | Required | Default | Description                                                                                                                                          |
| -------------------------- | ------ | -------- | ------- | ---------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`                     | string | yes      | —       | Operator-chosen unique plugin name.                                                                                                                  |
| `server`                   | string | yes      | —       | SQL Server host. For Azure SQL Database use `<server>.database.windows.net`; for a local instance, `localhost`.                                      |
| `port`                     | string | yes      | —       | TCP port, as a string (the Pydantic model is `port: str`). Typical Azure SQL value is `"1433"`.                                                      |
| `database`                 | string | yes      | —       | Database to scan; one plugin = one database.                                                                                                         |
| `username`                 | string | yes      | —       | SQL login.                                                                                                                                           |
| `password`                 | string | yes      | —       | Password.                                                                                                                                            |
| `encrypt`                  | string | no       | `"yes"` | TLS toggle for the SQL connection — `"yes"` / `"no"`. Azure SQL requires TLS; leave at default unless connecting to an unencrypted local SQL Server. |
| `trust_server_certificate` | string | no       | `"no"`  | Skip certificate validation — `"yes"` / `"no"`. Set to `"yes"` only for local development against a self-signed cert.                                |
| `connection_timeout`       | string | no       | `"30"`  | Driver-level connection timeout, in seconds, as a string.                                                                                            |

{% hint style="info" %}
The TLS-related fields (`encrypt`, `trust_server_certificate`, `connection_timeout`) are typed as `str` in the Pydantic model and the README expects literal string values like `"yes"` / `"no"` / `"30"` rather than booleans / integers. Quote them in YAML if your editor / linter is type-aware.
{% endhint %}

Source: [`AzureSQLPlugin` in `odd-collector-azure/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-azure/odd_collector_azure/domain/plugin.py); reference YAML at [`config_examples/azure_sql.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-azure/config_examples/azure_sql.yaml).

```yaml
plugins:
  - type: azure_sql
    name: prod_sql
    server: prod-sqlserver.database.windows.net
    port: "1433"
    database: warehouse
    username: odd_reader
    password: !ENV ${AZURE_SQL_PASSWORD}
    encrypt: "yes"
    trust_server_certificate: "no"
    connection_timeout: "30"
```

## Spotlight: Azure Data Factory (`type: azure_data_factory`)

Pulls Azure Data Factory pipelines, including pipeline-to-dataset lineage where the pipeline's activities reference a known catalogued dataset.

The adapter authenticates via [`DefaultAzureCredential`](https://learn.microsoft.com/en-us/python/api/azure-identity/azure.identity.defaultazurecredential?view=azure-python) — credentials are sourced from environment variables on the container, **not** from inline plugin fields. The standard env vars are `AZURE_TENANT_ID`, `AZURE_CLIENT_ID`, `AZURE_CLIENT_SECRET` for a service principal; alternatively `DefaultAzureCredential` will fall back to managed identity / Azure CLI / VS Code credentials when running on Azure infrastructure.

| Field                     | Type          | Required | Default  | Description                                           |
| ------------------------- | ------------- | -------- | -------- | ----------------------------------------------------- |
| `name`                    | string        | yes      | —        | Operator-chosen unique plugin name.                   |
| `subscription`            | string        | yes      | —        | Azure subscription ID containing the factory.         |
| `resource_group`          | string        | yes      | —        | Resource group containing the factory.                |
| `factory`                 | string        | yes      | —        | Data Factory resource name; one plugin = one factory. |
| `pipeline_filter.include` | list of regex | no       | `[".*"]` | Pipeline names to include.                            |
| `pipeline_filter.exclude` | list of regex | no       | `[]`     | Pipeline names to drop after `include` matches.       |

Source: [`DataFactoryPlugin` in `odd-collector-azure/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-azure/odd_collector_azure/domain/plugin.py); reference YAML at [`config_examples/azure_data_factory.yaml`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-azure/config_examples/azure_data_factory.yaml).

```yaml
plugins:
  - type: azure_data_factory
    name: orchestration_adf
    subscription: <azure_subscription_id>
    resource_group: data-rg
    factory: dataflows
    pipeline_filter:
      include: ["prod_.*"]
      exclude: ["prod_archive_.*"]
```

{% hint style="warning" %}
There is no plugin-level field for `client_id` / `client_secret` on `azure_data_factory`. Setting them inline in YAML has no effect — the adapter's underlying `azure-identity` client only reads from environment variables. Wire credentials onto the container via `AZURE_TENANT_ID`, `AZURE_CLIENT_ID`, `AZURE_CLIENT_SECRET` (or rely on workload identity in AKS / Container Apps).
{% endhint %}

## Per-adapter feature matrix

| Feature                                                                     | Where it applies                                                                                                                                                                                                                                                           |
| --------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Ingestion filters (`file_filter`)**                                       | `blob_storage`. Regex `include` / `exclude` lists; default includes everything.                                                                                                                                                                                            |
| **Ingestion filters (`pipeline_filter`)**                                   | `azure_data_factory`. Regex `include` / `exclude` lists scoping which pipelines are catalogued.                                                                                                                                                                            |
| **DefaultAzureCredential auth chain**                                       | `azure_data_factory`. Reads `AZURE_TENANT_ID` / `AZURE_CLIENT_ID` / `AZURE_CLIENT_SECRET` from the environment per the [DefaultAzureCredential docs](https://learn.microsoft.com/en-us/python/api/azure-identity/azure.identity.defaultazurecredential?view=azure-python). |
| **Connection string OR account key**                                        | `blob_storage`. Pick one; both is not required.                                                                                                                                                                                                                            |
| **TLS knobs (`encrypt`, `trust_server_certificate`, `connection_timeout`)** | `azure_sql`. String-typed; defaults `"yes"` / `"no"` / `"30"`.                                                                                                                                                                                                             |
| **SQL-login auth (no AAD app)**                                             | `azure_sql`. Username + password only — does not accept `client_id` / `client_secret`.                                                                                                                                                                                     |

Source: [`PLUGIN_FACTORY` in `odd-collector-azure/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-azure/odd_collector_azure/domain/plugin.py).

## Known limitations

* **Service-principal-only PowerBI auth.** PowerBI requires both an Azure AD app registration (`client_id` + `client_secret`) **and** a user account (`username` + `password`) — there is no service-principal-only path on this adapter today. Plan for an account that survives MFA changes.
* **`blob_storage.datasets` field rejected at validation.** Use `dataset_config` (singular).
* **`azure_data_factory` requires environment-variable auth.** The adapter uses `DefaultAzureCredential` from `azure-identity` and does not accept inline credentials in the plugin config — set `AZURE_TENANT_ID`, `AZURE_CLIENT_ID`, `AZURE_CLIENT_SECRET` as environment variables on the container.
* **No foreign-key / ERD extraction** in any Azure adapter.
* **`account_key` and `connection_string` are inline plaintext fields** by default — source them from environment variables (`!ENV`) or hand-managed secret storage.

## Where to next

* [`odd-collector`](/integrations/integrations/odd-collector) — generic collector for databases, BI, streams.
* [`odd-collector-aws`](/integrations/integrations/odd-collector-aws) / [`odd-collector-gcp`](/integrations/integrations/odd-collector-gcp) — sibling cloud collectors.
* [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors) — common SDK schema and from-source build flow.


# odd-collector-gcp

GCP-services pull collector — adapters for BigQuery, BigTable, Google Cloud Storage, and GCS Delta Lake tables.

{% hint style="info" %}
**Status: Stable.** Released as a tagged Docker image alongside the rest of the `odd-collectors` monorepo.
{% endhint %}

`odd-collector-gcp` packages adapters for Google Cloud managed services. Like the other pull collectors, it ships as a daemon container that hosts one or more configured plugins; one container can host multiple plugins of any combination of types.

For the broader pull-vs-push picture, start at the [Integrations hub](/integrations/integrations). For deployment-side detail, see [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors).

## Authentication

Authentication uses the [Google Cloud Application Default Credentials chain](https://google.aip.dev/auth/4110). When running outside GCP, set `GOOGLE_APPLICATION_CREDENTIALS` to a JSON key file path on the container — the adapters do not accept inline credentials in the plugin config. When running on GCP (GKE, GCE, Cloud Run), the workload identity / service-account attached to the runtime is used automatically.

## Supported adapters

The 4 adapters registered in `odd_collector_gcp/domain/plugin.py` (`PLUGIN_FACTORY`):

| Type literal       | GCP service                                 | Spotlighted below |
| ------------------ | ------------------------------------------- | ----------------- |
| `bigquery_storage` | BigQuery (datasets, tables, views, columns) | ✓                 |
| `bigtable`         | Cloud Bigtable                              |                   |
| `gcs`              | Google Cloud Storage (object catalog)       | ✓                 |
| `gcs_delta`        | Google Cloud Storage — Delta Lake tables    |                   |

The reference YAML for each adapter lives in the [GCP collector README](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-gcp). The Pydantic models that define accepted fields live at [`odd-collector-gcp/odd_collector_gcp/domain/plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-gcp/odd_collector_gcp/domain/plugin.py).

## Installation

```bash
docker pull ghcr.io/opendatadiscovery/odd-collector-gcp:latest
```

Mount a `collector_config.yaml` at `/app/collector_config.yaml` and the GCP service-account JSON key at the path named by `GOOGLE_APPLICATION_CREDENTIALS`. A reference Compose snippet is in the [gcp collector README](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-gcp#config-example).

## Minimal config

```yaml
platform_host_url: http://localhost:8080
token: <COLLECTOR_TOKEN>
default_pulling_interval: 10
plugins:
  - type: bigquery_storage
    name: bq_main
    project: my-gcp-project
```

## Multiple plugins in one container

```yaml
plugins:
  - type: bigquery_storage
    name: bq_finance
    project: finance-prod
  - type: bigquery_storage
    name: bq_marketing
    project: marketing-prod
  - type: gcs
    name: lake_raw
    project: lakes
    datasets:
      - bucket: raw-events
        prefix: events/
```

## Spotlight: BigQuery (`type: bigquery_storage`)

Pulls BigQuery datasets, tables, views, and column metadata for one project per plugin.

| Field                     | Type          | Required | Default  | Description                                    |
| ------------------------- | ------------- | -------- | -------- | ---------------------------------------------- |
| `name`                    | string        | yes      | —        | Operator-chosen unique plugin name.            |
| `project`                 | string        | yes      | —        | GCP project ID; one plugin = one project.      |
| `page_size`               | integer       | no       | `100`    | Pagination size for BigQuery list calls.       |
| `datasets_filter.include` | list of regex | no       | `[".*"]` | Dataset names to include.                      |
| `datasets_filter.exclude` | list of regex | no       | `[]`     | Dataset names to drop after `include` matches. |

Source: [`BigQueryStoragePlugin` in `odd-collector-gcp/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-gcp/odd_collector_gcp/domain/plugin.py).

```yaml
plugins:
  - type: bigquery_storage
    name: bq_main
    project: my-gcp-project
    datasets_filter:
      include: ["analytics_.*", "finance"]
      exclude: ["analytics_archive_.*"]
```

## Spotlight: Google Cloud Storage (`type: gcs`)

Pulls GCS objects (or folders treated as datasets) and infers schema. Supports CSV / Parquet, with explicit support for Hive-style partitioning.

| Field                     | Type            | Required | Default  | Description                                                             |
| ------------------------- | --------------- | -------- | -------- | ----------------------------------------------------------------------- |
| `name`                    | string          | yes      | —        | Operator-chosen unique plugin name.                                     |
| `project`                 | string          | yes      | —        | GCP project ID.                                                         |
| `datasets`                | list of objects | yes      | —        | List of `{ bucket, prefix?, folder_as_dataset? }` entries.              |
| `filename_filter.include` | list of regex   | no       | `[".*"]` | Object names to include.                                                |
| `filename_filter.exclude` | list of regex   | no       | `[]`     | Object names to drop after `include` matches.                           |
| `parameters`              | object          | no       | —        | Optional `pyarrow.fs.GcsFileSystem` knobs — see "GCS parameters" below. |

The `parameters` block accepts the optional GCS-client knobs documented in the [GCP collector README → GoogleCloudStorage](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-gcp#googlecloudstorage) — `anonymous`, `access_token`, `target_service_account`, `credential_token_expiration`, `default_bucket_location`, `scheme`, `endpoint_override`, `default_metadata`, `retry_time_limit`. They map onto `pyarrow.fs.GcsFileSystem` and are typically left at their defaults.

Source: [`GCSPlugin` in `odd-collector-gcp/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-gcp/odd_collector_gcp/domain/plugin.py).

```yaml
plugins:
  - type: gcs
    name: lake_raw
    project: lakes
    filename_filter:
      include: [".*\\.parquet$"]
      exclude: ["dev_.*"]
    datasets:
      - bucket: raw-events
        # Recursive fetch of all objects in the bucket.
      - bucket: enriched
        prefix: gold/specific_dataset.parquet
      - bucket: enriched
        prefix: events/
        folder_as_dataset:
          file_format: parquet
          flavor: hive
```

## Spotlight: BigTable (`type: bigtable`)

Pulls Cloud Bigtable instances, tables, and column families. The adapter samples the first N rows per table to infer the column-family-to-qualifier shape — Bigtable has no fixed schema, so a row sample is the only way to reflect real-world data layout into the catalog.

| Field        | Type    | Required | Default | Description                                                                                                                                                                                                                                                                                                       |
| ------------ | ------- | -------- | ------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name`       | string  | yes      | —       | Operator-chosen unique plugin name.                                                                                                                                                                                                                                                                               |
| `project`    | string  | yes      | —       | GCP project ID; one plugin = one project (inherited from `GcpPlugin`).                                                                                                                                                                                                                                            |
| `rows_limit` | integer | no       | `10`    | Number of rows the adapter reads per table to derive the type combination across qualifiers. Higher values widen the sample (better schema coverage on heterogeneous tables) at the cost of more read units; the literal README phrasing is "get combination of all types in table used across the first N rows". |

Source: [`BigTablePlugin` in `odd-collector-gcp/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-gcp/odd_collector_gcp/domain/plugin.py); reference YAML in the [GCP collector README → BigTable](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-gcp).

```yaml
plugins:
  - type: bigtable
    name: events_bigtable
    project: my-gcp-project
    rows_limit: 10
```

## Spotlight: GCS Delta tables (`type: gcs_delta`)

Pulls Delta Lake tables stored in GCS — schemas, columns, and partitioning. Each entry under `delta_tables:` declares one Delta table by `bucket` + `prefix`; the adapter reads the Delta `_delta_log/` to recover the table's evolved schema rather than inferring it from underlying Parquet.

| Field                            | Type            | Required | Default  | Description                                                                                                                                                                                                                                                                                                                                                                                                                                                        |
| -------------------------------- | --------------- | -------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `name`                           | string          | yes      | —        | Operator-chosen unique plugin name.                                                                                                                                                                                                                                                                                                                                                                                                                                |
| `project`                        | string          | yes      | —        | GCP project ID (inherited from `GcpPlugin`).                                                                                                                                                                                                                                                                                                                                                                                                                       |
| `delta_tables`                   | list of objects | yes      | —        | One entry per Delta table; each is a `DeltaTableConfig` (`bucket`, `prefix`, optional `filter`). The list is required (not the same pattern as `gcs.datasets`, which the GCS plugin treats differently).                                                                                                                                                                                                                                                           |
| `delta_tables[*].bucket`         | string          | yes      | —        | GCS bucket name.                                                                                                                                                                                                                                                                                                                                                                                                                                                   |
| `delta_tables[*].prefix`         | string          | yes      | —        | Path prefix inside the bucket; should point at the Delta table root (the directory that contains `_delta_log/`).                                                                                                                                                                                                                                                                                                                                                   |
| `delta_tables[*].filter.include` | list of regex   | no       | `[".*"]` | Per-table regex include list applied during enumeration.                                                                                                                                                                                                                                                                                                                                                                                                           |
| `delta_tables[*].filter.exclude` | list of regex   | no       | `[]`     | Per-table regex exclude list.                                                                                                                                                                                                                                                                                                                                                                                                                                      |
| `parameters`                     | object          | no       | —        | Optional `GCSAdapterParams` block — same shape as on the `gcs` plugin (`anonymous`, `access_token`, `target_service_account`, `credential_token_expiration`, `default_bucket_location`, `scheme`, `endpoint_override`, `default_metadata`, `retry_time_limit`). Documented inline in the [GCP collector README → GoogleCloudStorageDeltaTables](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-gcp); the Pydantic model defers to it. |

Source: [`GCSDeltaPlugin` in `odd-collector-gcp/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-gcp/odd_collector_gcp/domain/plugin.py); reference YAML in the [GCP collector README → GoogleCloudStorageDeltaTables](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-gcp).

```yaml
plugins:
  - type: gcs_delta
    name: lake_delta
    project: my-gcp-project
    delta_tables:
      - bucket: lake-bucket
        prefix: gold/orders/
        filter:
          include: [".*"]
          exclude: ["_temp_.*"]
      - bucket: lake-bucket
        prefix: gold/customers/
```

{% hint style="info" %}
`delta_tables[*].scheme` exists in the Pydantic model with default `gs` (mapped from a `schema` alias for backward compat with older configs); leave at default unless you are pointing the adapter at a non-GCS Delta location.
{% endhint %}

## Per-adapter feature matrix

| Feature                                                | Where it applies                                                                                            |
| ------------------------------------------------------ | ----------------------------------------------------------------------------------------------------------- |
| **Ingestion filters (`datasets_filter`)**              | `bigquery_storage`. Regex `include` / `exclude` for BigQuery dataset names; default includes everything.    |
| **Ingestion filters (`filename_filter`)**              | `gcs`. Regex `include` / `exclude` for GCS object names.                                                    |
| **Ingestion filters (`filter` inside `delta_tables`)** | `gcs_delta`. Per-Delta-table regex include / exclude.                                                       |
| **Folder-as-dataset / Hive partitioning**              | `gcs`. `folder_as_dataset` with `file_format` (`parquet` / `csv` / `tsv`) and `flavor` (`hive` / `presto`). |
| **GCS client parameter overrides**                     | `gcs`, `gcs_delta`. Overrides for endpoint, bucket location, retry, etc.                                    |
| **Row-sampling for schema inference**                  | `bigtable`. `rows_limit` controls the sample size used to derive column-family / qualifier types.           |

Source: [`PLUGIN_FACTORY` in `odd-collector-gcp/.../plugin.py`](https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector-gcp/odd_collector_gcp/domain/plugin.py).

## Known limitations

* **No inline credentials**: every adapter expects credentials via `GOOGLE_APPLICATION_CREDENTIALS` or the GCP runtime's workload identity. There is no plugin-level auth field.
* **One project per plugin**: each `bigquery_storage` / `bigtable` / `gcs` / `gcs_delta` plugin scans exactly one project. Cross-project ingestion needs additional plugins (one per project).
* **No foreign-key / ERD extraction** in any GCP adapter.
* **The README's BigQuery / GCS examples are the canonical reference for `parameters`** (the Pydantic model defers to `GCSAdapterParams` which is documented in the README, not in `plugin.py`). The repo's anchor `#googlecloudstoragedeltatables` has a typo in the markdown (`##` instead of `#`) — link from the [README](https://github.com/opendatadiscovery/odd-collectors/tree/main/odd-collector-gcp) directly if anchors don't resolve.

## Where to next

* [`odd-collector`](/integrations/integrations/odd-collector) — generic collector for databases, BI, streams.
* [`odd-collector-aws`](/integrations/integrations/odd-collector-aws) / [`odd-collector-azure`](/integrations/integrations/odd-collector-azure) — sibling cloud collectors.
* [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors) — common SDK schema and from-source build flow.


# odd-collector-profiler

Statistical data-profiling collector — runs DataProfiler against datasets and pushes per-dataset statistics to the platform.

{% hint style="info" %}
**Status: Stable, narrow scope.** Released as its own Docker image. Currently supports profiling of PostgreSQL and Azure SQL sources only.
{% endhint %}

`odd-collector-profiler` is a separate single-purpose collector that runs Capital One's [DataProfiler](https://github.com/capitalone/DataProfiler) library against your datasets and pushes the resulting statistics (column-level distributions, null ratios, type detection, basic anomaly tags) into the catalog. The statistics it produces are what populate the per-column figures (nulls count, min / mean / max values, and similar) on a dataset's **Structure** tab in the platform UI.

It complements (does **not** replace) one of the regular pull collectors — `odd-collector-profiler` reads sample rows out of the source to compute statistics; the regular collector still does the schema-level catalog ingestion.

For the broader pull-vs-push picture, start at the [Integrations hub](/integrations/integrations).

## Supported sources

| Profiler type literal | Source system      |
| --------------------- | ------------------ |
| `postgres`            | PostgreSQL         |
| `azure_sql`           | Azure SQL Database |

Source: [profiler README](https://github.com/opendatadiscovery/odd-collector-profiler#supported-data-sources). Other source types (Snowflake, BigQuery, MySQL, etc.) are not currently profiled by this collector.

## Installation

```bash
docker pull ghcr.io/opendatadiscovery/odd-collector-profiler:latest
```

Or build from source with `docker build . -t odd_collector_profiler` from the [repo](https://github.com/opendatadiscovery/odd-collector-profiler) root.

## Configuration shape

The profiler config layout is similar to a normal collector but the list field is **`profilers:`** rather than `plugins:`, and per-profiler fields are slightly different — most notably, an explicit `tables:` list per profiler scopes which tables get profiled (you typically do **not** profile every table in a database — DataProfiler reads sample rows and would be expensive across the full surface).

| Top-level field            | Description                                                                            |
| -------------------------- | -------------------------------------------------------------------------------------- |
| `default_pulling_interval` | Minutes between profiling runs. Profilers can be expensive — common values are 60–360. |
| `token`                    | Collector token issued by the platform.                                                |
| `platform_host_url`        | ODD Platform URL.                                                                      |
| `profilers`                | List of per-source profiler configs.                                                   |

Source: [profiler README → Config example](https://github.com/opendatadiscovery/odd-collector-profiler#config-example).

```yaml
default_pulling_interval: 360
token: <COLLECTOR_TOKEN>
platform_host_url: http://localhost:8080
profilers:
  - type: postgres
    name: my_postgres
    host: pg.internal
    port: 5432
    username: odd_reader
    password: !ENV ${PG_PASSWORD}
    database: warehouse
    tables: ["public.orders", "public.customers"]
```

## Multiple profilers in one container

The same multi-plugin pattern as the regular collectors applies — a single container can profile multiple sources, including multiple sources of the same type:

```yaml
profilers:
  - type: postgres
    name: warehouse_eu
    host: pg-eu.internal
    port: 5432
    username: odd_reader
    password: !ENV ${PG_EU_PASSWORD}
    database: warehouse
    tables: ["public.orders", "public.customers"]
  - type: postgres
    name: warehouse_us
    host: pg-us.internal
    port: 5432
    username: odd_reader
    password: !ENV ${PG_US_PASSWORD}
    database: warehouse
    tables: ["public.orders", "public.customers"]
```

## Known limitations

* **Two source types only** — `postgres` and `azure_sql`. Profiling other source types isn't supported by this collector today.
* **Explicit `tables:` list required.** The profiler does not auto-discover tables; you must list each `schema.table` (or just `table`) in the per-profiler `tables` field. This is a deliberate cost guard — DataProfiler reads sample rows.
* **Heavy dependency stack.** DataProfiler pulls TensorFlow as a dependency for its automatic data-labeling. On Apple Silicon (M1/M2) `tensorflow` and `pyodbc` need extra build steps — see the [profiler README → M1 Issue](https://github.com/opendatadiscovery/odd-collector-profiler#m1-issue).
* **Independent of the catalog collector.** The profiler does not register data sources — it expects each profiled table to already exist in the catalog (ingested by `odd-collector` or another integration). Run a catalog collector first, then point the profiler at the same source.

{% hint style="danger" %}
**The statistics endpoint the profiler pushes to is unauthenticated and unscoped — on every `auth.type`.** The profiler delivers its results to `POST /ingestion/entities/datasets/stats`. On the platform side that endpoint has **no authentication gate**: the `/ingestion/**` namespace is whitelisted in Spring Security, and the optional token filter only ever covers `POST /ingestion/entities`, never the stats path — so the stats endpoint is reachable by an unauthenticated caller under `auth.type` = `DISABLED`, `OAUTH2`, or `LDAP`, regardless of `auth.ingestion.filter.enabled`. The write is also **scoped only by field ODDRN, with no parent-child consistency check** — any caller who knows a field's ODDRN can overwrite that field's stored statistics (the `dataset_field.stats` value), and those values render on the Structure tab as authoritative. This is a platform-side property, not a profiler bug; before exposing the platform on an untrusted network, read [Enable security → Statistics endpoint](/configuration-and-deployment/enable-security#statistics-endpoint-write-shape-and-replay-behaviour) and apply the perimeter controls described there.
{% endhint %}

## Where to next

* [`odd-collector`](/integrations/integrations/odd-collector) — generic catalog collector. Run this before the profiler so the tables exist in the catalog.
* [Quality Dashboard](/features/data-quality/dashboard) — where profiler-driven statistics surface in the UI.
* [DataProfiler upstream](https://github.com/capitalone/DataProfiler) — the library doing the heavy lifting.


# odd-airflow-2

Airflow plugin that captures DAG, task, and task-run metadata via Airflow Listeners and pushes it to the ODD Platform.

{% hint style="info" %}
**Status: Stable, listener-based.** Distributed as `odd-airflow2-integration` on PyPI; the [repo](https://github.com/opendatadiscovery/odd-airflow-2)'s default branch is `master` and the latest release at the time of writing is `v0.0.8`.
{% endhint %}

`odd-airflow-2` is a push adapter for Apache Airflow 2.x. It runs **inside the Airflow scheduler process** as an Airflow Listener — DAG / task / task-run metadata is captured as Airflow emits its own lifecycle events, and lineage is collected from each task's `inlets` / `outlets` attributes. There's no DAG-side instrumentation — once the plugin is installed and the platform connection is configured, every DAG benefits.

For the broader pull-vs-push picture, start at the [Integrations hub](/integrations/integrations).

## Requirements

* **Apache Airflow 2.5.1 or later** (the listener API matured in 2.5; earlier 2.x versions are not supported by this plugin).
* **Python 3.9 or later** — matches the Airflow runtime, no separate Python version concern.
* **An ODD Platform-side collector token**, created in the UI under **Management → Collectors** (see [Try locally → Create Collector entity](/configuration-and-deployment/trylocally#create-collector-entity)).

For Airflow 1.x (or any setup where the Listener API isn't available), the legacy `odd-airflow-adapter` repo exists as a different implementation; it is not maintained on the same release cadence as `odd-airflow-2`.

## Installation

Install alongside Airflow in the same Python environment:

```bash
pip install odd-airflow2-integration
# or
poetry add odd-airflow2-integration
```

The package registers an Airflow plugin entry-point on import — no `airflow.cfg` plugin entry is required.

## Configuration

The plugin reads the platform URL and collector token from an Airflow **Connection** that **must be named `odd`**:

| Connection field | Value                                                              |
| ---------------- | ------------------------------------------------------------------ |
| `Conn Id`        | `odd`                                                              |
| `Conn Type`      | HTTP                                                               |
| `Host`           | ODD Platform host (e.g. `odd-platform.internal`)                   |
| `Port`           | optional — port if the platform is not on the standard HTTP/S port |
| `Password`       | the collector token issued by the platform                         |

Define this connection **before** the scheduler starts — the Listener loads it once at scheduler startup and does not refresh it dynamically.

## What gets sent

* **DAGs** — definition, schedule, owner, tags.
* **Tasks** — operator, task ID, configuration.
* **Task runs** — start / end timestamps, status (success / failure / skipped / …).
* **Lineage edges** — derived from each task's `inlets` and `outlets` attributes.

A typical lineage-aware task:

```python
@task(
    task_id="transform_orders",
    inlets=["//airflow/dev/dags/etl/tasks/load_orders"],
)
def transform(data_dict: dict):
    ...
```

Or with the operator API:

```python
task_2 = PythonOperator(
    task_id="transform_orders",
    python_callable=transform,
    inlets=["//airflow/dev/dags/etl/tasks/load_orders"],
)
```

The string passed to `inlets` / `outlets` is an [ODDRN](/introduction/main-concepts#oddrn) — the cross-system identifier ODD uses to recognise the same entity across ingests.

{% hint style="warning" %}
**Lineage push is replace-not-merge — a run that drops an edge silently deletes it.** The platform's ingestion endpoint rewrites lineage per emitting entity: when this adapter sends an entity's lineage, the platform first deletes *all* edges previously recorded for that entity and then inserts only the edges in the current payload, in a single transaction with a 200 response and no warning. So if a DAG run changes or removes a task's `inlets` / `outlets`, the edges from the earlier run vanish — there is no "remove just this one edge" call and no merge with prior state. Treat each task's `inlets` / `outlets` as the *complete* lineage for that task on every run; if you intend an edge to persist, keep emitting it.
{% endhint %}

{% hint style="warning" %}
**On a default platform deployment, this push is unauthenticated — the collector token is not checked.** The `Password` token is only validated when the operator has explicitly enabled ingestion authentication on the platform (`auth.ingestion.filter.enabled`, which defaults to off). With the default in place, the platform accepts pushes to `/ingestion/entities` from any caller that can reach it, regardless of the token. Setting the token here does not by itself protect the endpoint. See [Enable security → Ingestion authentication](/configuration-and-deployment/enable-security) to turn it on.
{% endhint %}

## Known limitations

* **Airflow 2.5.1 minimum.** Earlier 2.x releases lacked the Listener hooks this plugin depends on.
* **`inlets` / `outlets` do not support templating.** Airflow's `template_fields` mechanism does not apply to these attributes — values are read verbatim at task definition time, not at runtime.
* **Connection name is fixed.** The plugin looks up the connection by the literal name `odd`; renaming it disables the integration silently.
* **Connection loaded at scheduler start.** Changing the platform URL or token requires a scheduler restart for the Listener to pick up the new value.
* **Airflow 1.x is not supported** by this package; use the legacy `odd-airflow-adapter` repo (separate maintenance).
* **Repo default branch is `master`**, not `main`. URLs that hit `/blob/main/...` 404 — use `/blob/master/...` (or browse the [repo root](https://github.com/opendatadiscovery/odd-airflow-2)).

## Troubleshooting

* **No metadata appears in the platform.** Check that the `odd` Airflow connection is defined, the `Password` field carries the token, and the scheduler was restarted after defining the connection.
* **Lineage edges missing.** Confirm `inlets` / `outlets` are set on the relevant tasks, that they are valid ODDRNs, and that the values are constants — not templated.
* **Verbose logging.** Airflow's standard `logging.level` controls the plugin's logs.

## Where to next

* [Repo](https://github.com/opendatadiscovery/odd-airflow-2) — sources and releases.
* [`odd-dbt`](/integrations/integrations/odd-dbt) — pair with this when your DAGs run dbt models.
* [Lineage feature in the catalog](/features/data-lineage/data-objects) — what the platform does with the lineage edges.


# odd-dbt

CLI push adapter that ingests dbt test results and model lineage into the ODD Platform.

{% hint style="info" %}
**Status: Stable for the supported targets**, narrow scope: Postgres and Snowflake only, generic tests only.
{% endhint %}

`odd-dbt` is a push adapter for [dbt](https://www.getdbt.com/). It reads dbt's `target/` folder after a run, maps test results and model lineage into the ODD specification, and pushes them to the ODD Platform. It functions as a standalone CLI (`odd_dbt_test`) and is also bundled into [`odd-cli`](/integrations/integrations/odd-cli) (the `odd dbt` subcommand) for users who want a single CLI entry point.

For the broader pull-vs-push picture, start at the [Integrations hub](/integrations/integrations).

## Supported targets

| dbt target | Supported version    | Notes                                                                                         |
| ---------- | -------------------- | --------------------------------------------------------------------------------------------- |
| Postgres   | dbt-postgres `^1.6`  |                                                                                               |
| Snowflake  | dbt-snowflake `^1.6` | The Snowflake account identifier must include the region segment, e.g. `hj1234.eu-central-1`. |

| Test type                              | Supported                   |
| -------------------------------------- | --------------------------- |
| Generic tests (built-in + `dbt_utils`) | ✓                           |
| Singular tests                         | ✗ — not currently supported |

Source: [`odd-dbt` README](https://github.com/opendatadiscovery/odd-dbt#readme).

## Installation

```bash
pip install odd-dbt
```

## Configuration

Three environment variables wire the adapter to the platform:

| Variable                | Value                                                                                                                                                          |
| ----------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `ODD_PLATFORM_HOST`     | Platform URL (e.g. `http://localhost:8080`).                                                                                                                   |
| `ODD_PLATFORM_TOKEN`    | Collector token issued by the platform under **Management → Collectors**.                                                                                      |
| `DBT_DATA_SOURCE_ODDRN` | The dbt data source's [ODDRN](/introduction/main-concepts#oddrn) — e.g. `//dbt/host/localhost`. Used as the namespace under which dbt entities are registered. |

The same values can be passed as flags on every CLI invocation in lieu of environment variables.

## CLI commands

| Command                                                          | Purpose                                                                                                            |
| ---------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------ |
| `odd_dbt_test create-datasource --name=<name> --dbt-host=<host>` | Registers the dbt project as a data source in the platform. Run once per project.                                  |
| `odd_dbt_test ingest-test --profile=<profile>`                   | Reads dbt's `target/run_results.json` + `target/manifest.json` from the current directory and pushes test results. |
| `odd_dbt_test ingest-lineage --profile=<profile>`                | Reads dbt's `manifest.json` and pushes model-to-model lineage.                                                     |
| `odd_dbt_test test --profile=<profile>`                          | Convenience: runs `dbt test`, then ingests the produced results.                                                   |

For invocations from outside the dbt project root, pass `--project-dir=<path>` and `--profiles-dir=<path>` explicitly.

```bash
export ODD_PLATFORM_HOST=http://localhost:8080
export ODD_PLATFORM_TOKEN=token***
export DBT_DATA_SOURCE_ODDRN=//dbt/host/dbt-cloud

odd_dbt_test create-datasource --name=analytics_dbt --dbt-host=dbt-cloud
odd_dbt_test ingest-test --profile=prod_warehouse
odd_dbt_test ingest-lineage --profile=prod_warehouse
```

For the full flag list: `odd_dbt_test --help`.

## What gets sent

* **dbt models** as Data Entity entities under the `DBT_DATA_SOURCE_ODDRN` namespace.
* **Model-to-model lineage** edges derived from `manifest.json`.
* **Generic test results** with status (pass / fail / error / warn) and pointers to the tested column / model.

The platform displays the test results on the affected dataset's detail page and contributes to the [Quality Dashboard](/features/data-quality/dashboard).

{% hint style="warning" %}
**`ingest-lineage` is replace-not-merge — a model that loses an upstream ref silently loses the edge.** The platform's ingestion endpoint rewrites lineage per emitting entity: it first deletes *all* edges previously recorded for a model and then inserts only the edges in the current payload, in a single transaction with a 200 response and no warning. So if you edit a model to drop an upstream `ref()` / `source()` and re-run `ingest-lineage`, the removed edge disappears from the platform — there is no merge with what was ingested before. This is correct when the model genuinely no longer depends on that upstream; the hazard is an *incomplete* re-ingest (e.g. running against a partial `manifest.json`), which prunes edges you did not mean to remove. Re-ingest from a complete build of the project.
{% endhint %}

{% hint style="warning" %}
**On a default platform deployment, `ingest-test` and `ingest-lineage` are unauthenticated — the token is not checked.** The two push paths are guarded differently. `create-datasource` (`/ingestion/datasources`) always validates `ODD_PLATFORM_TOKEN`. But `ingest-test` and `ingest-lineage` ride `/ingestion/entities`, whose token check is only active when the operator has enabled ingestion authentication on the platform (`auth.ingestion.filter.enabled`, which defaults to off). With the default in place, the platform accepts those data pushes from any caller that can reach it, regardless of the token. See [Enable security → Ingestion authentication](/configuration-and-deployment/enable-security) to turn it on.
{% endhint %}

## Programmatic usage

The package exposes its mappers (`DbtTestMapper`, `DbtLineageMapper`) for direct Python use — useful when you want to wire the ingestion into a custom orchestration step rather than the CLI. See the repo source for the import paths.

## Known limitations

* **Two adapters only.** `dbt-postgres` and `dbt-snowflake` are supported; other dbt adapters (BigQuery, Redshift, Databricks, Trino, …) are not.
* **Generic tests only.** Singular tests (the ones you write as a single SQL query under `tests/`) are not currently parsed.
* **dbt 1.6+.** Earlier dbt versions are not supported.
* **`DBT_DATA_SOURCE_ODDRN` must be stable.** Changing it after first ingest registers the same dbt project as a new data source on the platform side.
* **Snowflake account identifier must include region.** The bare account form (e.g. `hj1234`) does not work — use `hj1234.eu-central-1`.

## Where to next

* [`odd-cli`](/integrations/integrations/odd-cli) — bundles this adapter under `odd dbt`; useful when you want one CLI for dbt + local files + token management.
* [Quality Dashboard](/features/data-quality/dashboard) — where dbt test results aggregate alongside other quality signals.
* [Repo](https://github.com/opendatadiscovery/odd-dbt) — sources, releases, and issues.


# odd-spark-adapter

Spark Listener that captures Spark job lineage and pushes it to the ODD Platform.

{% hint style="warning" %}
**Status: v0.0.1 — Spark 3.3.1 only.** Other Spark versions are not currently supported. Spark Structured Streaming is on the roadmap but not yet implemented.
{% endhint %}

`odd-spark-adapter` is a push adapter for Apache Spark distributed as a JVM JAR. It runs as a [Spark Listener](https://spark.apache.org/docs/latest/api/scala/org/apache/spark/scheduler/SparkListener.html) attached to the driver, captures lineage from each job's read / write operations, and pushes the resulting metadata to the ODD Platform.

For the broader pull-vs-push picture, start at the [Integrations hub](/integrations/integrations).

## Requirements

* **Spark 3.3.1.** No other Spark version is supported by v0.0.1 today.
* The driver must be able to reach the ODD Platform over HTTP.

## Supported lineage sources

The v0.0.1 release captures lineage from:

* **RDD** low-level jobs.
* **JDBC** data sources (read and write).
* **Kafka topics** in batch mode.
* **Snowflake tables.**
* **S3 Delta tables.**

Spark Structured Streaming is not currently supported.

Source: [`odd-spark-adapter` README](https://github.com/opendatadiscovery/odd-spark-adapter#readme).

## Installation

Download the latest JAR from the [Releases](https://github.com/opendatadiscovery/odd-spark-adapter/releases) page on the repo. Attach it to your `spark-submit` (or your Spark cluster's classpath via your platform's standard mechanism — `--jars`, EMR bootstrap, Databricks libraries, etc.).

## Configuration

The adapter reads two configuration parameters from Spark's configuration:

| Spark config key      | Value                                                                                                                                  |
| --------------------- | -------------------------------------------------------------------------------------------------------------------------------------- |
| `spark.odd.host.url`  | URL of your ODD Platform deployment (e.g. `http://odd-platform.internal:8080`).                                                        |
| `spark.odd.oddrn.key` | A unique string identifier for **this Spark cluster**. The adapter uses it to construct ODDRNs for entities emitted from this cluster. |

A representative `spark-submit`:

```bash
spark-submit \
  --jars /path/to/odd-spark-adapter.jar \
  --conf spark.extraListeners=org.opendatadiscovery.adapters.spark.OddSparkListener \
  --conf spark.odd.host.url=http://odd-platform.internal:8080 \
  --conf spark.odd.oddrn.key=prod-cluster-eu \
  your-application.jar
```

Refer to the README for the up-to-date listener class name in case of changes.

## What gets sent

* **Spark applications** — application name, run ID, start / end times.
* **Lineage edges** — from each supported source (JDBC, Kafka, Snowflake, S3 Delta) to each supported sink, derived from the Spark plan as the listener observes it.

The platform stitches Spark-emitted lineage to the rest of the catalog via ODDRNs — JDBC reads of a table already catalogued by `odd-collector` (PostgreSQL, MySQL, …) connect to the existing dataset entity automatically.

{% hint style="warning" %}
**Lineage push is replace-not-merge — a re-run with a changed plan silently deletes the prior edges.** The platform's ingestion endpoint rewrites lineage per emitting entity: when a Spark job emits its read / write set, the platform first deletes *all* edges previously recorded for that entity and then inserts only the edges from the current run, in a single transaction with a 200 response and no warning. Because this adapter re-emits the lineage of the *current* plan on every job run, a run that reads fewer tables — a dropped source, a removed join, a code path that skips an input — erases the edges the earlier plan recorded, with no operator-visible signal. The platform always reflects the most recent run's plan, not the union of all runs. Account for this if you rely on lineage from runs whose plan varies between executions.
{% endhint %}

## Known limitations

* **Spark 3.3.1 only.** Other 3.x versions and any 2.x version are not supported by v0.0.1. The roadmap mentions broader version coverage but has not shipped.
* **No Structured Streaming.** Streaming jobs are not captured.
* **No static collector token, and the push is unauthenticated by default.** The adapter sends no token; it identifies itself only via `spark.odd.oddrn.key`. On a default platform deployment, ingestion authentication is off (`auth.ingestion.filter.enabled` defaults to off), so the platform accepts this push from any caller that can reach `/ingestion/entities` — there is no per-ODDRN allow-step. Turn ingestion authentication on for any deployment reachable from an untrusted network (see [Enable security → Ingestion authentication](/configuration-and-deployment/enable-security)).
* **JAR is the only delivery format.** No PyPI package; no container image. Operators bundle the JAR with their Spark deployments.

## Where to next

* [Lineage feature in the catalog](/features/data-lineage/data-objects) — what the platform does with the lineage edges this adapter emits.
* [Repo](https://github.com/opendatadiscovery/odd-spark-adapter) — sources, releases, and issues.


# odd-great-expectations

Great Expectations checkpoint ValidationAction that pushes expectation results to the ODD Platform.

{% hint style="info" %}
**Status: Stable, V3 API only.** No Great Expectations Cloud Solution support; no V2 API support.
{% endhint %}

`odd-great-expectations` is a push adapter for [Great Expectations](https://greatexpectations.io/). It plugs in as a `ValidationAction` on a GE checkpoint — every time the checkpoint runs, the action serialises the validation results into the ODD specification and pushes them to the ODD Platform. The result: GE expectation outcomes show up alongside other data-quality signals in the catalog.

For the broader pull-vs-push picture, start at the [Integrations hub](/integrations/integrations).

## Requirements

* **Great Expectations V3 API.** The action targets the V3 checkpoint mechanism (`great_expectations.checkpoint.Checkpoint`).
* One of the supported execution engines:
  * SQLAlchemy engine.
  * Pandas engine.

The V2 API and the GE Cloud Solution are not supported.

| Capability        | Supported |
| ----------------- | --------- |
| GE V3 API         | ✓         |
| SqlAlchemyEngine  | ✓         |
| PandasEngine      | ✓         |
| GE V2 API         | ✗         |
| GE Cloud Solution | ✗         |

Source: [`odd-great-expectations` README → Supporting](https://github.com/opendatadiscovery/odd-great-expectations#supporting).

## Installation

```bash
pip install odd-great-expectations
```

The package exposes `odd_great_expectations.action.ODDAction`, a class derived from GE's `ValidationAction`.

## Configuration

Add `ODDAction` to your checkpoint's `action_list`:

```yaml
name: <CHECKPOINT_NAME>
config_version: 1.0
template_name:
module_name: great_expectations.checkpoint
class_name: Checkpoint
run_name_template: '%Y%m%d-%H%M%S-my-run-name-template'
expectation_suite_name:
batch_request: {}
action_list:
  # ...other actions
  - name: store_metadata_to_odd
    action:
      module_name: odd_great_expectations.action
      class_name: ODDAction
      platform_host: http://odd-platform.internal:8080
      platform_token: <COLLECTOR_TOKEN>
      data_source_name: my_local_qa_test
evaluation_parameters: {}
```

| Action field       | Value                                                                                    |
| ------------------ | ---------------------------------------------------------------------------------------- |
| `module_name`      | `odd_great_expectations.action` (literal).                                               |
| `class_name`       | `ODDAction` (literal).                                                                   |
| `platform_host`    | ODD Platform URL.                                                                        |
| `platform_token`   | Collector token issued by the platform under **Management → Collectors**.                |
| `data_source_name` | Unique name for the GE data source as it appears in the platform — e.g. `local_qa_test`. |

Run the checkpoint as you normally would:

```bash
great_expectations checkpoint run <CHECKPOINT_NAME>
```

The ODDAction runs on every checkpoint execution after the validation completes; success / failure / partial-success outcomes are all pushed.

## What gets sent

* **Quality test results** for every expectation in the checkpoint.
* The dataset(s) the expectations apply to (if not already in the catalog, they are registered under the supplied `data_source_name`).
* The expectation outcome status (pass / fail) and any GE result payload that maps cleanly onto the ODD quality-test schema.

The platform surfaces these on the dataset's detail page and aggregates them into the [Quality Dashboard](/features/data-quality/dashboard).

{% hint style="warning" %}
**On a default platform deployment, this push is unauthenticated — a wrong or blank `platform_token` is silently accepted.** The action always sends `platform_token`, but the platform only validates it when the operator has enabled ingestion authentication (`auth.ingestion.filter.enabled`, which defaults to off). With the default in place, the platform accepts pushes to `/ingestion/entities` from any caller that can reach it, regardless of the token value — so a misconfigured token does not surface as an error, and the endpoint is open to any caller on the network. See [Enable security → Ingestion authentication](/configuration-and-deployment/enable-security) to turn it on.
{% endhint %}

## Known limitations

* **V3 API only.** GE V2 API checkpoints are not compatible.
* **No GE Cloud Solution support.** The push happens from the Python process running the checkpoint; the action does not integrate with GE Cloud's hosted execution.
* **Two engines.** Outside SqlAlchemyEngine and PandasEngine (e.g. SparkDFExecutionEngine), the action is not exercised — file an issue if you need other engines.
* **`platform_token` is plain text in the checkpoint YAML by default.** Source it from a secret store / environment via your YAML loader if your deployment requires non-plaintext config.

## Where to next

* [Quality Dashboard](/features/data-quality/dashboard) — where GE results aggregate alongside other quality signals.
* [`odd-dbt`](/integrations/integrations/odd-dbt) — paired adapter when GE expectations and dbt tests cover overlapping datasets.
* [Repo](https://github.com/opendatadiscovery/odd-great-expectations) — sources, releases, and issues.


# odd-cli

Operator-side CLI for pushing local file metadata, running dbt ingestion, and managing platform tokens.

{% hint style="info" %}
**Status: Stable, evolving.** A small operator-facing CLI; the [repo](https://github.com/opendatadiscovery/odd-cli) is the source of truth for the command surface as it grows.
{% endhint %}

`odd-cli` is the operator-side command-line companion to the ODD Platform. It exposes a small set of subcommands for ad-hoc metadata pushes (CSV / Parquet folders), running dbt ingestion (re-using [`odd-dbt`](/integrations/integrations/odd-dbt) under the hood), and managing platform tokens. It is the right tool for "I have a folder of files I want to register" and "give me a token for a script" without standing up a full collector.

For the broader pull-vs-push picture, start at the [Integrations hub](/integrations/integrations).

## Installation

```bash
pip install odd-cli
```

Installs the `odd` executable into your Python environment.

## Configuration

The CLI reads two environment variables for platform addressing:

| Variable             | Value                                                                                              |
| -------------------- | -------------------------------------------------------------------------------------------------- |
| `ODD_PLATFORM_HOST`  | Platform URL (e.g. `http://localhost:8080`).                                                       |
| `ODD_PLATFORM_TOKEN` | A collector token. Create one in the UI (**Management → Collectors**) or with `odd tokens create`. |

Source: [`odd-cli` README](https://github.com/opendatadiscovery/odd-cli#readme).

{% hint style="warning" %}
**The `ODD_PLATFORM_TOKEN` is a long-lived plaintext credential — handle it accordingly.** It is the platform's collector token, and on the platform side it is stored in plaintext (no hashing at rest) and returned in plaintext when minted or regenerated, so anything that can read the database, a backup, or the create/regenerate response body sees the live secret. Regenerating it is an in-place overwrite with **no grace window** (a script or collector still using the old value starts getting `401`s the instant the new one commits), and regeneration is **not** recorded in the platform's audit trail. Prefer a short-lived, narrowly-scoped token for CI use, keep it in your secret store rather than a shell history or `.env` committed to a repo, and coordinate before regenerating one that other jobs depend on. The full platform-side token contract and mitigations are documented at [Management → Collectors known caveats](/features/management#collectors-known-caveats).
{% endhint %}

## Commands

| Command                              | Purpose                                                                                                                                                                                                             |
| ------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `odd collect <path_to_folder>`       | Walks a local folder of dataset files (CSV / Parquet / similar), maps them to ODD entities, and pushes to the platform.                                                                                             |
| `odd dbt test <path_to_dbt_project>` | Runs `dbt test` and ingests the resulting `target/` artefacts. Re-uses [`odd-dbt`](/integrations/integrations/odd-dbt) — same supported targets (Postgres, Snowflake) and same generic-tests-only constraint apply. |
| `odd tokens create <collector_name>` | Issues a new collector token from the platform. Useful in CI scripts.                                                                                                                                               |

```bash
export ODD_PLATFORM_HOST=http://localhost:8080
export ODD_PLATFORM_TOKEN=token***

# Create a token (alternative to the UI flow).
odd tokens create my_local_dbt_runs

# Push a folder of local files.
odd collect ./datasets

# Run dbt tests and ingest the results.
odd dbt test ./analytics_dbt
```

## What gets sent

* **`odd collect`** — dataset entities for each detected file under the path, with inferred schema where possible.
* **`odd dbt test`** — same payload as [`odd-dbt`](/integrations/integrations/odd-dbt): models, model-to-model lineage, generic test results.
* **`odd tokens create`** — no metadata is emitted; the command interacts with the platform's token-management API.

## Known limitations

* **`odd dbt` inherits `odd-dbt`'s constraints.** Postgres and Snowflake targets only; generic tests only; dbt 1.6+ only. See the [`odd-dbt` page](/integrations/integrations/odd-dbt) for full detail.
* **`odd collect` is for batch pushes**, not continuous tail-and-push from a folder. Run it on a schedule (cron / CI) for periodic refresh.
* **`odd tokens create` requires a token** that is itself authorised to create tokens — the bootstrap token still has to come from somewhere (typically the UI for the first one).

## Where to next

* [`odd-dbt`](/integrations/integrations/odd-dbt) — the standalone dbt push adapter that `odd dbt` wraps.
* [Repo](https://github.com/opendatadiscovery/odd-cli) — sources, releases, and the latest command surface.


# odd-tracing-gateway

Optional standalone push-adapter service that ingests OpenTelemetry traces from operator microservices and exposes the inferred services as ODD entities for the Platform to pull.

`odd-tracing-gateway` is an optional standalone Java service that bridges OpenTelemetry distributed tracing into the ODD catalog. Operators deploy the gateway alongside their existing OpenTelemetry collection pipeline; their microservices emit traces to it, and the gateway extracts service identities and dependencies from those traces and exposes them as ODD Data Entities.

In the [two-axis adapter taxonomy](/introduction/main-concepts#the-architecture-chain), the gateway is a **push adapter** with the **standalone gateway** deployment shape — operator microservices push (over OpenTelemetry/OTLP), the gateway processes the spans and caches the inferred entities, and the ODD Platform (or a collector configured to pull from the gateway) reads those entities through the standard adapter-contract entities API. Operator-mental-model is "my services push to the gateway"; the Platform-side leg is a pull hidden behind the gateway's standalone deployment.

The gateway is **optional**. Deployments that already populate the catalog through pull collectors (databases, BI, MLOps) and in-process push adapters (dbt, Airflow, Spark, Great Expectations) do not need it. Reach for the gateway when the catalog should also include the **microservices in your stack** — their identities, the HTTP endpoints they expose, the databases / Kafka topics / AWS resources they call — automatically inferred from the same distributed traces your observability stack already collects.

## What it does

Per the gateway's source code (Spring Boot WebFlux + gRPC; entry point at [`Application.java`](https://github.com/opendatadiscovery/odd-tracing-gateway/blob/main/src/main/java/org/opendatadiscovery/tracing/gateway/Application.java)):

1. **Receives OpenTelemetry traces** over OTLP/gRPC at port `9090`. Sources can either point their OTel SDK directly at the gateway (`OTEL_EXPORTER_OTLP_TRACES_ENDPOINT`), or — more commonly — emit through an existing OpenTelemetry collector that fans traces to the gateway as one of its exporters.
2. **Resolves the service that emitted each trace** through a chain of [`ServiceNameResolver`](https://github.com/opendatadiscovery/odd-tracing-gateway/tree/main/src/main/java/org/opendatadiscovery/tracing/gateway/resolver) implementations, sorted by priority:
   * **Default** (`DefaultServiceNameResolver`, priority `app.defaultNamePriority`, default `0`) — uses the OpenTelemetry `service.name` resource attribute. Always active.
   * **Docker** (`DockerServiceNameResolver`, priority `app.docker.namePriority`, default `10`) — gated by `app.docker.enabled=true`. Resolves the source's `container.id` resource attribute against a Docker daemon to find the container's image, and uses that image as the canonical service name. Useful when source-side OpenTelemetry instrumentation reports container IDs but not service names (e.g., generic JVM auto-instrumentation in Docker Compose).
   * **Kubernetes** (`K8sServiceNameResolver`, priority `app.k8s.namePriority`, default `10`) — gated by `app.k8s.enabled=true`. Resolves `host.name` (the pod) plus `container.id` against the Kubernetes API and reads the container's image from the pod's `spec.containers`. Useful when you want the canonical image to be the service identity, not the OpenTelemetry-supplied service name.
3. **Processes spans** through type-specific [`SpanProcessor`](https://github.com/opendatadiscovery/odd-tracing-gateway/tree/main/src/main/java/org/opendatadiscovery/tracing/gateway/processor) implementations, each accepting a specific OpenTelemetry instrumentation library:
   * **`HttpSpanProcessor`** — accepts `io.opentelemetry.netty`, `io.opentelemetry.jetty`, `io.opentelemetry.spring-webflux` libraries. Server spans become `API_SERVICE` (the host) + `API_CALL` (per host+method+path) entities; client spans add inputs to the calling service. IPs and the configurable `app.http.staticPrefix` (default `/static/`) are excluded.
   * **`JdbcSpanProcessor`** — emits dataset entities for tables observed in JDBC client spans (uses `jsqlparser` to extract table names from SQL).
   * **`KafkaSpanProcessor`** — emits Kafka topic entities for producer / consumer spans, scoped by the configured `app.kafkaServers`.
   * **`GrpcSpanProcessor`** — emits service / method entities for inter-service gRPC.
   * **`AwsSpanProcessor`** — emits AWS-resource entities for AWS SDK client spans (DynamoDB tables observed via OTel auto-instrumentation, etc.).
4. **Caches** every observed `(service, version)` and its inputs / outputs in **Redis**, keyed by ODDRN. The cache is what the Platform-side leg of the integration reads.
5. **Exposes the inferred entities** through `GET /entities` on port `8080`, with an optional `changedSince` ISO-8601 query parameter. The endpoint implements [`org.opendatadiscovery.adapter.contract.api.EntitiesApi`](https://github.com/opendatadiscovery/opendatadiscovery-specification-contracts) — the same contract every pull adapter / collector exposes — so an ODD pull collector can subscribe to the gateway as if it were any other source.

## What it does NOT do

* **Does not store, ship, or replay OpenTelemetry traces.** The gateway extracts service-identity and dependency metadata from each trace and discards the trace itself. Use a separate observability backend (Tempo, Jaeger, an OTel-compatible APM) if you need the full trace stream.
* **Does not push to the Platform's Ingestion API.** Despite the historical "transfers metadata to the Platform" framing, the gateway does not call `/ingestion/entities`. Entities flow Platform-ward only when an ODD pull collector is configured to read the gateway's `GET /entities` endpoint.
* **Does not authenticate inbound OTLP traffic.** The gRPC trace receiver is open to whoever can reach `:9090`. Run the gateway inside a network perimeter that already restricts who can push (a private subnet, a service mesh, a network policy).
* **Does not authenticate `GET /entities`.** The REST endpoint is unauthenticated. Treat the gateway as an internal service that only the ODD Platform / a trusted collector talks to.
* **Does not perform retention or cleanup of cached entities.** Redis holds the inferred catalog as long as the gateway is running against it; restarting the gateway with a fresh Redis empties the cache. There is no built-in TTL or operator-managed retention window today.
* **Does not deduplicate across replicas.** A single Redis backs a single gateway instance; running multiple gateway replicas without a shared Redis produces divergent catalogs.

## How the data flows

A typical operator setup wires four components together:

```
[microservices with OpenTelemetry instrumentation]
     │
     │ OTLP (gRPC/HTTP)
     ▼
[OpenTelemetry collector]                  ← optional fan-out / batching layer
     │
     │ OTLP/gRPC :4317
     ▼
[odd-tracing-gateway :9090 (gRPC)] ──────► [Redis cache]
     ▲                                          │
     │                                          │
     │ HTTP GET /entities :8080                 │
     │                                          │
[ODD Platform / pull collector] ◄─────────────────
     │
     │ /ingestion/entities
     ▼
[ODD Platform PostgreSQL]
```

The OpenTelemetry collector is optional but recommended — it lets you fan trace traffic to the gateway and to your observability backend in parallel without instrumenting every microservice with two exporters.

## Operator setup

### Prerequisites

* A running ODD Platform (any deployment shape from [Deployment Options](/configuration-and-deployment/deployment)).
* A reachable Redis instance for the gateway to use as its cache. The default Helm chart bundles a Redis sub-chart for evaluation; production deployments should point at a managed Redis (`spring.redis.host`, `spring.redis.port`, `spring.redis.database`).
* An OpenTelemetry trace pipeline already collecting traces from your microservices, or microservices instrumented with the OpenTelemetry SDK and configured to export OTLP/gRPC.

### Install via Helm (recommended)

The gateway ships as a Helm chart in the same chart repository as the Platform — [`charts/odd-tracing-gateway`](https://github.com/opendatadiscovery/charts/tree/main/charts/odd-tracing-gateway). Add the chart repo and install:

```bash
helm repo add opendatadiscovery https://opendatadiscovery.github.io/charts
helm repo update
helm install odd-tracing-gateway opendatadiscovery/odd-tracing-gateway
```

The chart exposes a `config` field for the gateway's runtime environment variables — set the resolver flags (`APP_DOCKER_ENABLED`, `APP_K8S_ENABLED`, `APP_K8S_NAMESPACES`), the Redis connection (`SPRING_REDIS_HOST`, `SPRING_REDIS_PORT`, `SPRING_REDIS_DATABASE`), and any HTTP-processor tuning (`APP_HTTP_STATIC_PREFIX`, `APP_HTTP_EXCLUDE_IPS`) through this map. See the chart's [`values.yaml`](https://github.com/opendatadiscovery/charts/tree/main/charts/odd-tracing-gateway) for the full surface.

### Install via Docker Compose (local evaluation)

For a local or demo deployment, run the gateway directly from its published Docker image. The image is published to two registries:

* **Docker Hub**: `opendatadiscovery/odd-traces-gateway:latest` (note the plural "traces" — this is the Jib build target). New images are pushed on every `main` build.
* **GitHub Container Registry**: `ghcr.io/opendatadiscovery/odd-tracing-gateway:<version>` (singular "tracing"). Released versions are retagged here on `release` events; no `latest` tag.

A minimal Docker Compose setup wiring the gateway, Redis, and an OpenTelemetry collector:

```yaml
version: "3.8"
services:
  redis:
    image: redis

  odd-tracing-gateway:
    image: opendatadiscovery/odd-traces-gateway:latest
    depends_on:
      - redis
    environment:
      - SPRING_REDIS_HOST=redis
      - SPRING_REDIS_PORT=6379
      - SPRING_REDIS_DATABASE=0
      # Resolve service names from container image when service.name is missing
      - APP_DOCKER_ENABLED=true
      - APP_DOCKER_HOST=unix:///var/run/docker.sock
    volumes:
      - /var/run/docker.sock:/var/run/docker.sock
    ports:
      - "8081:8080"   # GET /entities
      - "9090:9090"   # OTLP gRPC

  otel-collector:
    image: otel/opentelemetry-collector:latest
    command: ["--config=/etc/otel.yaml"]
    volumes:
      - ./otel.yaml:/etc/otel.yaml
    depends_on:
      - odd-tracing-gateway
```

A reproducible end-to-end example — the gateway plus a sample Spring Boot app emitting traces through an OpenTelemetry collector — lives in the gateway repo's [`test/test-app/`](https://github.com/opendatadiscovery/odd-tracing-gateway/tree/main/test/test-app) directory.

### Wire the Platform to pull from the gateway

The gateway exposes the standard adapter-contract entities endpoint (`GET /entities`). Configure an ODD pull collector to point at the gateway as one of its plugin sources, or have the Platform fetch entities directly. The exact wiring depends on which collector you operate; see your collector's configuration reference under [Integrations](/integrations/integrations).

## Configuration reference

The gateway reads its configuration from environment variables (or a Spring Boot `application.yml` mounted into the container). Sources cited inline are paths inside the [gateway's source tree](https://github.com/opendatadiscovery/odd-tracing-gateway/tree/main).

### Application

| Key                       | Env var                     | Default   | What it does                                                                                                                                                                                                                                       | Source                      |
| ------------------------- | --------------------------- | --------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------- |
| `app.oddrn`               | `APP_ODDRN`                 | (none)    | The gateway's own ODDRN, set as `dataSourceOddrn` on every `DataEntityList` it returns. Used by the Platform to attribute entities back to this gateway instance.                                                                                  | `config/AppProperties.java` |
| `app.defaultNamePriority` | `APP_DEFAULT_NAME_PRIORITY` | `0`       | Priority of `DefaultServiceNameResolver` in the resolver chain. Lower-priority resolvers run last; the first resolver returning a name wins.                                                                                                       | `config/AppProperties.java` |
| `app.kafkaServers`        | `APP_KAFKA_SERVERS`         | `unknown` | Bootstrap-servers identifier used in Kafka-topic ODDRN composition. Set to your Kafka cluster's bootstrap address (`host:port[,host:port...]`) for the gateway to produce topic ODDRNs that match what your collectors and pull adapters generate. | `config/AppProperties.java` |
| `app.exposeLatestVersion` | `APP_EXPOSE_LATEST_VERSION` | `true`    | When `true` (default), `GET /entities` returns only the latest version of each service ODDRN. When `false`, every observed version is exposed.                                                                                                     | `config/AppProperties.java` |

### Docker resolver

| Key                       | Env var                    | Default | What it does                                                                                                                                                                                                                    |
| ------------------------- | -------------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `app.docker.enabled`      | `APP_DOCKER_ENABLED`       | `false` | Enables `DockerServiceNameResolver`. When `false`, the gateway never queries Docker.                                                                                                                                            |
| `app.docker.host`         | `APP_DOCKER_HOST`          | (none)  | Docker daemon endpoint (`unix:///var/run/docker.sock` for Docker Compose deployments).                                                                                                                                          |
| `app.docker.tlsVerify`    | `APP_DOCKER_TLS_VERIFY`    | `false` | Enables TLS verification for the Docker client.                                                                                                                                                                                 |
| `app.docker.namePriority` | `APP_DOCKER_NAME_PRIORITY` | `10`    | Priority of `DockerServiceNameResolver` in the resolver chain. With the default value, the Docker resolver runs after the default resolver but its result wins (the resolver chain stops at the first match in priority order). |

### Kubernetes resolver

| Key                    | Env var                 | Default                         | What it does                                                                                                                                                                                                                             |
| ---------------------- | ----------------------- | ------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `app.k8s.enabled`      | `APP_K8S_ENABLED`       | `false`                         | Enables `K8sServiceNameResolver`. When `false`, the gateway never queries the Kubernetes API.                                                                                                                                            |
| `app.k8s.host`         | `APP_K8S_HOST`          | (none — uses in-cluster config) | Kubernetes API endpoint. Leave unset when the gateway runs as a pod inside the cluster (the fabric8 client picks up in-cluster credentials).                                                                                             |
| `app.k8s.namespaces`   | `APP_K8S_NAMESPACES`    | (all namespaces)                | Comma-separated list of namespaces the gateway is allowed to inspect. When unset, the gateway lists every namespace at startup — make sure the service account has cluster-wide read on `pods` and `namespaces` if you leave this empty. |
| `app.k8s.namePriority` | `APP_K8S_NAME_PRIORITY` | `10`                            | Priority of `K8sServiceNameResolver` in the resolver chain.                                                                                                                                                                              |

### HTTP-span processor

| Key                     | Env var                  | Default    | What it does                                                                                                                                                                                                                |
| ----------------------- | ------------------------ | ---------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `app.http.staticPrefix` | `APP_HTTP_STATIC_PREFIX` | `/static/` | HTTP paths starting with this prefix are skipped — useful for excluding asset bundles, health checks, or admin endpoints from the catalog. Set to an empty string to ingest every observed path.                            |
| `app.http.excludeIps`   | `APP_HTTP_EXCLUDE_IPS`   | `true`     | When `true`, server hosts and client URLs whose host portion is a literal IP address are skipped (the inferred service identity tends to be unstable when the host is an ephemeral pod IP). Set to `false` to include them. |

### Redis cache

| Key                     | Env var                 | Default                           | What it does          |
| ----------------------- | ----------------------- | --------------------------------- | --------------------- |
| `spring.redis.host`     | `SPRING_REDIS_HOST`     | `localhost` (Spring Boot default) | Redis hostname.       |
| `spring.redis.port`     | `SPRING_REDIS_PORT`     | `6379` (Spring Boot default)      | Redis port.           |
| `spring.redis.database` | `SPRING_REDIS_DATABASE` | `0` (Spring Boot default)         | Redis database index. |

The full Spring Boot Redis configuration surface (auth, sentinel, cluster mode, SSL) is available — see the [Spring Boot reference](https://docs.spring.io/spring-boot/docs/2.6.x/reference/html/application-properties.html#application-properties.data.spring.data.redis.host) for the complete property list. The gateway uses `spring-boot-starter-data-redis-reactive`.

## API surface

The gateway exposes two surfaces. Neither is part of the ODD Platform's HTTP API — both surfaces live on the gateway process itself.

### Inbound — OpenTelemetry traces (sources push)

| Protocol  | Port (default) | Endpoint                                                     | Spec                                                                |
| --------- | -------------- | ------------------------------------------------------------ | ------------------------------------------------------------------- |
| OTLP/gRPC | `9090`         | `opentelemetry.proto.collector.trace.v1.TraceService/Export` | [OpenTelemetry Protocol](https://opentelemetry.io/docs/specs/otlp/) |

Source applications (or an OpenTelemetry collector in front of them) push traces over OTLP/gRPC. The gateway uses `grpc-server-spring-boot-starter` to host the receiver; instrumentation libraries the gateway extracts metadata from are listed under "How the data flows" above.

### Outbound — Adapter-contract entities (Platform pulls)

| Protocol | Port (default) | Endpoint                                  | Spec                                                                                                                                                            |
| -------- | -------------- | ----------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| HTTP     | `8080`         | `GET /entities[?changedSince=<ISO-8601>]` | [`org.opendatadiscovery.adapter.contract`](https://github.com/opendatadiscovery/opendatadiscovery-specification-contracts) — the contract every adapter exposes |

The endpoint returns a `DataEntityList` JSON shape — `dataSourceOddrn` (set from `app.oddrn`) plus an `items` array of inferred services / API calls / API services / data inputs. The `changedSince` query parameter scopes the response to entities whose cached `updatedAt` is strictly greater than the supplied timestamp.

## Where it sits architecturally

In the [two-axis adapter taxonomy](/introduction/main-concepts#the-architecture-chain), the gateway is a **Push adapter (standalone gateway)** — distinct from in-process plugins (which live inside a source tool's runtime, like dbt or Airflow) and from collectors (which host pull adapters in a single Python container). The standalone-gateway shape is the right answer when:

* The "source" is a population of microservices, not a single application — instrumenting each microservice with an in-process plugin is impractical.
* The metadata you want catalogued comes from observability infrastructure (distributed traces) rather than from the source tool's own configuration / runtime.
* The platform-side integration can be a single read-only fetch rather than continuous ingestion.

For the architectural overview that places the gateway among the Platform, collectors, and in-process push adapters, see [Architecture → Deployment topology](/introduction/architecture#deployment-topology).

## Known limitations

{% hint style="warning" %}
**The OTLP receiver is unauthenticated.** Anyone who can reach the gateway's port `9090` can push arbitrary traces — and therefore arbitrary "service" entities — into the cache. Run the gateway only inside a network perimeter that restricts inbound traffic (private subnet, service mesh policy, Kubernetes NetworkPolicy). The same applies to `GET /entities` on port `8080`: the endpoint is unauthenticated; treat it as an internal service exposed only to the ODD Platform / a trusted pull collector.
{% endhint %}

{% hint style="warning" %}
**Cached entities have no built-in retention.** Redis holds every observed `(service, version)` indefinitely. A noisy or compromised source can grow the cache without bound. If you need eviction, configure it at the Redis layer (LRU max-memory policy, scheduled `FLUSHDB`); the gateway has no operator-tunable TTL today.
{% endhint %}

{% hint style="warning" %}
**Multiple gateway replicas need a shared Redis.** The gateway stores state in Redis, but each gateway replica writes independently. Running two replicas pointing at separate Redis instances produces two divergent catalogs; pointing both at the same Redis works, but at-most-once semantics on writes are not guaranteed. The simplest production posture is a single replica behind a Kubernetes Deployment with `replicas: 1` and a managed Redis.
{% endhint %}

* **The default `latest` tag on `opendatadiscovery/odd-traces-gateway` floats.** Pin the image tag to a specific gateway version (or pin the GHCR `ghcr.io/opendatadiscovery/odd-tracing-gateway:<version>` released image) for reproducible deployments.
* **The Docker resolver requires Docker socket access.** Mounting `/var/run/docker.sock` into the gateway container grants the gateway read access to every container on the host. Use the Kubernetes resolver in production K8s deployments; the Docker resolver is for Docker Compose / single-host setups.
* **The Kubernetes resolver needs cluster-wide pod read** when `app.k8s.namespaces` is unset. Restrict to a known namespace list to scope the service-account permissions tightly.
* **`app.kafkaServers` defaults to the literal string `unknown`.** Kafka topic ODDRNs the gateway emits will carry that placeholder unless you set the key — they will not match the topic ODDRNs your Kafka pull adapter generates, and lineage edges between the two surfaces will not converge. Set `app.kafkaServers` to your Kafka cluster's bootstrap address before deploying.
* **Two image-name spellings are in circulation** — the Docker Hub image is `opendatadiscovery/odd-traces-gateway` (plural "traces"; this is the Jib build target) and the GHCR retag is `ghcr.io/opendatadiscovery/odd-tracing-gateway` (singular "tracing"). Both publish from the same source repo. Prefer the GHCR pinned-version tag for production; the Docker Hub `latest` is for evaluation.

## Where to next

* **The architectural overview** that places this gateway alongside the Platform, collectors, and in-process push adapters → [Architecture → Deployment topology](/introduction/architecture#deployment-topology).
* **The two-axis adapter taxonomy** that classifies this component as a Push adapter (standalone gateway) → [Main Concepts → The architecture chain](/introduction/main-concepts#the-architecture-chain).
* **Other ways to feed the catalog** — pull collectors, in-process push adapters → [Integrations](/integrations/integrations).
* **Source code** → [opendatadiscovery/odd-tracing-gateway](https://github.com/opendatadiscovery/odd-tracing-gateway).
* **Helm chart** → [opendatadiscovery/charts → `odd-tracing-gateway`](https://github.com/opendatadiscovery/charts/tree/main/charts/odd-tracing-gateway).


# Ingestion filters

Ingestion filters — collector-side regex include / exclude rules that scope what schemas, tables, files, datasets, or pipelines a plugin ingests. Configured per-plugin in \`collector\_config.yaml\`.

Pull adapters in ODD's collectors ingest **everything they can see** by default — every schema in a database, every file in a bucket, every dataset in a warehouse. **Ingestion filters** scope a plugin to a slice of that surface using regex `include` / `exclude` rules, so an operator can keep the catalog focused on what their teams actually care about.

This page covers the filter mechanism — the per-key shape, how `include` and `exclude` interact, and a worked PostgreSQL example. For per-adapter filter coverage (which adapter exposes which filter keys), see the per-collector pages under [Integrations](/integrations/integrations).

{% hint style="info" %}
**Not the same as the platform's "ingestion filter".** The ODD Platform has a separate, unrelated feature that also carries the name *ingestion filter* — a token-based authentication gate on the `/ingestion/**` endpoints, enabled with the `auth.ingestion.filter.enabled` setting (off by default). It controls **who may push** ingestion requests to the platform, not **what a collector reads** from a source. The filters on this page are collector-side and decide which schemas, tables, files, datasets, or pipelines an adapter ingests; they have nothing to do with authentication. If you came here to secure the ingestion endpoint, see [Ingestion authentication](/configuration-and-deployment/enable-security) instead.
{% endhint %}

## Where filters are configured

Filters live in `collector_config.yaml` under the **per-plugin block** — not at the collector level. Each plugin type exposes its own filter keys named after the dimension being filtered:

* `schemas_filter` — PostgreSQL, Snowflake (filter by database schema).
* `filename_filter` — S3, Azure Blob Storage, GCS (filter by file path / name).
* `datasets_filter` — BigQuery (filter by dataset).
* `pipeline_filter` — Azure Data Factory (filter by pipeline name).

Other adapters expose filters under names that match their domain. The shape — `include` and `exclude` regex lists — is consistent across them.

## Shape of a filter

Every filter takes two regex lists:

```yaml
schemas_filter:
  include: ['regex_1', 'regex_2', ...]
  exclude: ['regex_1', 'regex_2', ...]
```

* **`include`** — the plugin only ingests items matching at least one regex in the list. If `include` is set and no regex matches, the item is skipped.
* **`exclude`** — the plugin skips items matching at least one regex in the list, even if they matched `include`.

When **both** lists are set, the rule is "**included AND not excluded**":

1. The item must match at least one `include` pattern.
2. The item must match **zero** `exclude` patterns.

Either list is optional. Omitting `include` means "include everything that isn't excluded". Omitting both filters off entirely means "ingest everything the adapter can see" — the default.

Patterns are **regular expressions**, not glob patterns. Anchor with `^` / `$` if you need exact-prefix or exact-suffix matching; otherwise the regex matches anywhere in the candidate string.

## Worked example — PostgreSQL `schemas_filter`

Suppose a PostgreSQL source has these schemas:

* `test_prod`
* `application_dev`
* `data_in_prod`
* `test_data_in_prod_for_application`

Configuring this filter on the PostgreSQL plugin:

```yaml
schemas_filter:
  include: ['test', '^in.*prod']    #(1) include if matches at least one
  exclude: ['prod$', '^dev']        #(2) exclude if matches at least one
```

The plugin processes each schema:

* **`test_prod`** → matches `include[0]` (`test`) ✓ → matches `exclude[0]` (`prod$`) ✗ — **excluded**.
* **`application_dev`** → matches no `include` rule — **skipped (not included)**.
* **`data_in_prod`** → matches no `include` rule — **skipped (not included)**. (Note: `^in.*prod` requires the schema name to start with `in`, which `data_in_prod` does not.)
* **`test_data_in_prod_for_application`** → matches `include[0]` (`test`) ✓ → matches no `exclude` rule ✓ — **ingested**.

Net effect: only `test_data_in_prod_for_application` is ingested. The other three are filtered out at collection time and never appear in the catalog.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2F7SmqM29YhPc9ga7n34xY%2Fimage.png?alt=media&amp;token=f55edaa6-5452-471c-8889-5d2e7f46b09d" alt=""><figcaption><p><a href="https://github.com/opendatadiscovery/odd-collectors/blob/main/odd-collector/config_examples/postgresql.yaml">Filtering setup template in the Collector configuration file for PostgreSQL</a></p></figcaption></figure>

## When filters apply

Filters apply at **ingestion time**, on the collector side — the platform never sees the filtered-out items. This means:

* Filtered-out items consume zero database storage, zero search index, zero entity-page rendering cost. The filter is not a UI hide; it is a non-ingest.
* Changing a filter rule and restarting the collector does **not** retroactively remove already-ingested items. To prune previously-ingested items the operator must also delete them from the platform (manual delete, or a controlled re-ingest after the filter change clears them from the source-truthy set).
* Per-source coverage on [Management → Datasources](/features/management) reflects what the filter let through — the entity counts there are post-filter.

## Default behaviour without filters

When a plugin's filter block is absent or empty, the plugin ingests everything the source exposes. This is the default — for a fresh deployment, every schema, file, or dataset shows up in the catalog until the operator scopes the surface down.

## Per-adapter coverage

Most pull adapters that read from sources with multiple "namespaceable" dimensions (schemas, datasets, paths, projects, ...) expose a corresponding filter. The complete adapter-by-adapter capability list lives on the [`odd-collectors` repository's filtering documentation](https://github.com/opendatadiscovery/odd-collectors#ingestion-filters-configuration). When in doubt, consult the per-adapter page under [Integrations](/integrations/integrations) for the exact key name.

## Where to next

* [`odd-collector` (generic)](/integrations/integrations/odd-collector) — the collector hosting most pull adapters that expose ingestion filters.
* [Common configuration (collectors) → Beyond connection settings](/integrations/integrations#beyond-connection-settings-per-adapter-features) — the integrations hub's brief on per-adapter feature surfaces, including filters.
* [Build and run ODD Collectors → Full configuration reference](/developer-guides/build-and-run/build-and-run-odd-collectors#full-configuration-reference) — the canonical reference for the collector-config schema.
* [Integrations overview](/integrations/integrations) — the bucket landing this page sits under.


# Integration Wizard

The Integration Wizard — the in-app UI under Management → Integrations that generates collector\_config.yaml snippets for the integrations the platform recognises.

The **Integration Wizard** is an in-app UI under [**Management → Integrations**](/features/management) that helps operators bootstrap a `collector_config.yaml` for the integrations the platform recognises. It is a **template generator**, not an installer: it does not deploy a collector, write to disk, or talk to any source system. It produces a parameterised YAML snippet that the operator copies into their own `collector_config.yaml`.

## What the wizard does

* Lists every integration the platform's classpath registers (one card per integration; sorted case-insensitively by id).
* For each integration, renders a multi-section wizard panel:
  * **Title and description** — taken from the integration's manifest (`IntegrationPreview` model: `id`, `name`, `description`).
  * **Content blocks** — ordered sections, each with a title, prose content, and zero-or-more code snippets. Use these to walk the operator through prerequisites, snippet selection, and post-deploy verification (whatever the manifest author put there).
  * **Code snippets** — parameterised templates with form fields. The operator fills in the inputs; the wizard interpolates them; the rendered output is shown ready to copy.

## What it does NOT do

* It does not deploy or launch a collector — that is operator-side work, see [Deployment Options](/configuration-and-deployment/deployment).
* It does not write `collector_config.yaml` for you — the file lives on the host running the collector; the wizard only feeds you a snippet.
* It does not validate the snippet against a target source — credentials, hosts, and ports are typed at face value.
* It is not the same surface as the [Integrations hub](/integrations/integrations) — the hub documents what each integration is, the wizard generates configuration for some of them.

## How operators use it

1. **Open** [Management → Integrations](/features/management) in the platform UI.
2. **Pick** an integration card (PostgreSQL, Snowflake, …).
3. **Read** the wizard's content blocks (prerequisites, instructions).
4. **Fill in** the form parameters the wizard prompts for (host, port, credentials, …). The wizard pre-fills any **static** parameter — see "Static parameters" below.
5. **Copy** the rendered YAML snippet into the `plugins:` list of your `collector_config.yaml`.
6. **Run** your collector with the updated config — see [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors) or the [chart-based deployment options](/configuration-and-deployment/deployment).

## Static parameters

A code-snippet argument has an `isStatic` flag (and a `staticValue` field on the wire). When `isStatic = true`, the platform — not the operator — supplies the value. Today exactly one parameter is wired up this way: **`platform_url`**, read from `odd.platform-base-url` (`StaticArgumentMappingContext.java:11-19`). The Java field default is the placeholder string `http://your.odd.platform`, so on a fresh deployment without the key set explicitly the wizard will pre-fill `platform_url` with that placeholder — see [Configure ODD Platform → odd.platform-base-url](/configuration-and-deployment/odd-platform#odd-platform-base-url) for the full caveat about this default. Always set `odd.platform-base-url` to your real deployment URL in any non-local environment, **then** open the wizard so the snippets carry a working URL out of the box.

All other arguments default to `isStatic = false` and are entered by the operator.

## API surface

The wizard's two backing endpoints — `GET /api/integrations` (list) and `GET /api/integrations/{integration_id}` (full overview with content blocks and code snippets) — are documented at [API Reference → Integrations](/developer-guides/api-reference/integrations). Call them directly to script integration-snippet generation outside the in-app UI.

{% hint style="warning" %}
**The wizard endpoints carry no RBAC permission gate — any authenticated user reads the full integration registry, and under `auth.type=DISABLED` the registry is anonymously reachable.** Both `GET /api/integrations` and `GET /api/integrations/{integration_id}` fall through to the platform's default `.authenticated()` matcher; the platform's security wiring has no `SecurityRule` entry for `/api/integrations*`, and the controller methods carry no `@PreAuthorize`. The UI's placement under **Management → Integrations** suggests admin-only access (sibling tabs like Datasources, Collectors, and Owners gate their write actions on `*_CREATE` / `_UPDATE` / `_DELETE` permissions), but the wizard endpoints are not gated even at write — they are read-only by shape, and the read surface is the entire wizard registry including each integration's content blocks and the `platform_url` value rendered into them.

Operators expecting the wizard registry to be admin-only — including the values pre-filled into each integration's static parameters (today exactly one: `platform_url`) — discover the any-authenticated reach only through API enumeration. Under DISABLED, the registry is reachable by any anonymous network caller. This is consistent with the platform's broader read-collaborative authorization posture across the Management section (see [Management → Tab visibility versus mutate gates](/features/management#tab-visibility-versus-mutate-gates)).

**Mitigation today.** Apply a reverse-proxy authz filter on `/api/integrations*` if admin-only read of the wizard registry is a deployment requirement. Treat the `platform_url` static parameter as deployment-public — do not put sensitive information in the integration manifests' content blocks. The upstream platform-side fix is either to introduce an `INTEGRATION_READ` permission and gate the controller, or to add a `SecurityRule` entry that restricts the path to an existing permission — both are read-posture decisions that fit the broader ODD Platform authorization-model work.
{% endhint %}

## Integration registry

The wizard is data-driven. Every integration card is one YAML manifest packaged on the platform's classpath at `META-INF/wizard/*.yaml`. At startup `IntegrationRegistryFactory` scans `classpath*:META-INF/wizard/*.yaml` (Spring's `PathMatchingResourcePatternResolver`), parses each manifest into an `IntegrationOverviewDto`, and stores them in a case-insensitive `TreeMap` keyed by `id`. Adding a new integration to the wizard means dropping a new manifest into a JAR on the platform's classpath; the platform does not currently support hot-reload — a restart is required.

The exact manifest schema is the contract defined by `IntegrationOverviewDto` and its nested DTOs (`IntegrationPreviewDto`, `IntegrationContentBlockDto`, `IntegrationCodeSnippetDto`, `IntegrationCodeSnippetArgumentDto`, `IntegrationCodeSnippetArgumentTypeEnum`).

## Wizard vs `collector_config.yaml`

|                  | Integration Wizard                              | `collector_config.yaml`                                                                                     |
| ---------------- | ----------------------------------------------- | ----------------------------------------------------------------------------------------------------------- |
| Where it lives   | In the Platform UI (Management → Integrations)  | On the host running the collector                                                                           |
| What it produces | A YAML snippet for one plugin (one integration) | The full collector configuration: `platform_host_url`, `token`, `default_pulling_interval`, `plugins:` list |
| Who reads it     | The operator setting up an integration          | The collector process at startup                                                                            |
| Persistence      | None — the wizard re-renders each time          | The file you keep under source control                                                                      |

The wizard is a **starting point**, not a replacement. Operators still maintain `collector_config.yaml` themselves — combining wizard-generated snippets with hand-authored ones (multiple plugins of the same type, custom filters, secrets backend references, environment-variable overrides). For the full file shape see the [Integrations hub → Common configuration](/integrations/integrations#common-configuration-collectors) and the [collector build-and-run guide](/developer-guides/build-and-run/build-and-run-odd-collectors).

## Where to next

* [Integrations hub](/integrations/integrations) — what each integration is, paired with the wizard cards on the same in-app surface.
* [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors) — fields the wizard does not surface (filters, secrets, `default_pulling_interval`, …).
* [Configure ODD Platform → `odd.platform-base-url`](/configuration-and-deployment/odd-platform#odd-platform-base-url) — set this before opening the wizard so static `platform_url` substitution carries a working URL.
* [Collector secrets backend](/configuration-and-deployment/collectors-secrets-backend) — keep wizard-generated credentials out of the YAML you commit.


# Deployment Options

Pick a deployment path for ODD Platform and Collector — Docker Compose, Helm, AWS EKS, or from source — with step-by-step setup and pointers to the config deep-dives.

ODD Platform and ODD Collector ship with several supported deployment paths. This page is the entry point: it lists every option, what each is for, and where the deep-dive lives. For configuration details after deployment, the canonical reference is [Configure ODD Platform](/configuration-and-deployment/odd-platform); per-collector / per-adapter detail lives under the [Integrations hub](/integrations/integrations).

## Choose your option

| # | Option                                      | Use case                                             | Components                                                      | Persistence                                   | Production-ready?                                        | Deep-dive                                                                                                                                                                               |
| - | ------------------------------------------- | ---------------------------------------------------- | --------------------------------------------------------------- | --------------------------------------------- | -------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| 1 | **Docker Compose**                          | Local evaluation / demo on a workstation             | Platform + Collector + sample PostgreSQL                        | Container-local volumes                       | No — evaluation only                                     | [Try locally](/configuration-and-deployment/trylocally)                                                                                                                                 |
| 2 | **Helm on self-managed Kubernetes**         | Production deployments on a cluster you operate      | Platform + Collector (separate releases)                        | External PostgreSQL (recommended)             | Yes — when you supply persistent PostgreSQL              | [opendatadiscovery/charts](https://github.com/opendatadiscovery/charts)                                                                                                                 |
| 3 | **Helm Quick Launch (all-in-one)**          | Demo / staging on Kubernetes; AWS Marketplace launch | Platform + bundled Bitnami PostgreSQL (sub-chart)               | Bundled PostgreSQL pod (ephemeral by default) | No — bundled DB is not persistent in the default config  | [`odd-quicklaunch` chart](https://github.com/opendatadiscovery/charts/tree/main/charts/odd-quicklaunch)                                                                                 |
| 4 | **AWS EKS via CloudFormation Quick Launch** | One-click EKS deployment in a supported AWS region   | EKS cluster + bundled Bitnami PostgreSQL + Platform + Collector | Bundled PostgreSQL pod (ephemeral by default) | No — demo-grade; HTTPS not configured, DB not persistent | [Deploy to Amazon Elastic Kubernetes Service (EKS)](/configuration-and-deployment/quick_launch_on_amazon_elastic_kubernetes_service)                                                    |
| 5 | **Build from source**                       | Contributors and deep customisation                  | Platform + Collector built locally                              | Operator's choice                             | Yes — when paired with a production runtime              | [Build and run ODD Platform](/developer-guides/build-and-run/build-and-run-odd-platform) + [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors) |

The optional `odd-tracing-gateway` is **not** one of these deployment paths — it is a separate Push adapter (standalone gateway shape) that operators deploy **alongside** the Platform when their stack already collects OpenTelemetry traces and they want microservice identities catalogued automatically. See [`odd-tracing-gateway`](/integrations/integrations/odd-tracing-gateway) under Integrations for the operator-facing setup, configuration, and caveats.

## Option 1: Docker Compose (local / demo)

{% hint style="info" %}
**Status: Evaluation only.** Container-local volumes; no operator-managed persistence; not for production. Use this to try the platform end-to-end on a workstation in a few minutes.
{% endhint %}

### When to use it

* You want to evaluate ODD without provisioning infrastructure.
* You're a contributor running the stack locally during development.
* You want a sample data source pre-loaded so the catalog isn't empty on first open.

### Prerequisites

* Docker Engine 19.03.0+
* `docker-compose` (latest)
* Free local ports `8080` (Platform UI / API) and `5432` (sample PostgreSQL)

### Install

1. Clone the platform repo: `git clone https://github.com/opendatadiscovery/odd-platform.git`
2. From the project root, start the demo stack with the bundled enricher:

   ```bash
   docker-compose -f docker/demo.yaml up -d odd-platform-enricher
   ```
3. Open the UI at <http://localhost:8080/>.

### Verify

* Visit <http://localhost:8080/management/datasources> — you should see \~10 predefined data sources from the bundled sample.
* Visit the **Catalog** tab — the metadata sample should be visible.

### Deep dive

* [Try locally](/configuration-and-deployment/trylocally) — full walkthrough including the Collector → token → `collector_config.yaml` workflow for connecting your own data source.

### Known gotchas

* Data persists only as long as the named Docker volumes do; `docker-compose down -v` wipes the catalog.
* The bundled enricher is for first-impression sample data; it should not be left running long-term against a real catalog.

## Option 2: Helm on self-managed Kubernetes

{% hint style="success" %}
**Status: Production-ready** — when you supply your own PostgreSQL with persistent storage, configure ingress / TLS, and run the bundled charts on a cluster you operate.
{% endhint %}

### When to use it

* You operate a Kubernetes cluster (self-managed, EKS, GKE, AKS, on-prem) and want long-lived ODD installations on it.
* You need to wire ODD to an existing managed PostgreSQL (RDS, Cloud SQL, Aurora, on-prem).
* You want independent release cadences for Platform and Collector(s) — they are separate charts.

### Prerequisites

* A Kubernetes cluster you have admin access to (`kubectl get nodes` succeeds).
* [Helm 3](https://helm.sh/docs/intro/install/) installed locally.
* A reachable PostgreSQL instance for the Platform (operator-supplied — bundled PostgreSQL is **not** included in this chart; that's Option 3).

### Install

1. Add the chart repo:

   ```bash
   helm repo add opendatadiscovery https://opendatadiscovery.github.io/charts
   helm repo update
   ```
2. Install the Platform with your PostgreSQL connection details:

   ```bash
   helm install odd-platform opendatadiscovery/odd-platform \
     --set config.yaml.spring.datasource.username=<your_pg_user> \
     --set config.yaml.spring.datasource.password=<your_pg_password> \
     --set config.yaml.spring.datasource.url="jdbc:postgresql://<pg_host>:5432/<db_name>"
   ```
3. Create a Collector entity in the Platform UI (**Management → Collectors**) and copy the issued token.
4. Install the Collector with that token wired into `collectorConfig`:

   ```bash
   helm install odd-collector opendatadiscovery/odd-collector \
     --set image.repository=ghcr.io/opendatadiscovery/odd-collector \
     --set-file collectorConfig=./your-collector-config.yaml
   ```

   Replace `./your-collector-config.yaml` with a `collector_config.yaml` matching the [per-adapter reference](/integrations/integrations/odd-collector) for the data sources you want to ingest. Mount sensitive values via `passwordSecretsEnvs` rather than baking them into the YAML.

### Minimal example: external PostgreSQL

```yaml
# odd-platform-values.yaml
config:
  yaml:
    spring:
      datasource:
        username: odd-platform
        password: !ENV ${PG_PASSWORD}
        url: "jdbc:postgresql://pg.internal.example.com:5432/odd-platform"
service:
  type: ClusterIP        # use LoadBalancer / Ingress for external access
ingress:
  enabled: true
  className: nginx
  hosts:
    - host: odd.example.com
      paths:
        - path: /
          pathType: Prefix
```

Apply with `helm install odd-platform opendatadiscovery/odd-platform -f odd-platform-values.yaml`.

### Verify

* `kubectl get pods` — every Platform pod is `Running`.
* `kubectl logs deploy/odd-platform | head` — no datasource-connection errors.
* Open the configured ingress / LoadBalancer URL — the UI loads.

### Deep dive

* [opendatadiscovery/charts → README](https://github.com/opendatadiscovery/charts) — chart-repo usage (add, install, uninstall).
* [`odd-platform` chart values](https://github.com/opendatadiscovery/charts/tree/main/charts/odd-platform) — full `values.yaml` reference.
* [`odd-collector` chart values](https://github.com/opendatadiscovery/charts/tree/main/charts/odd-collector) — Collector chart reference (image, `collectorConfig`, `env` overrides, secret-env injection via `passwordSecretsEnvs`).
* [Configure ODD Platform](/configuration-and-deployment/odd-platform) — every Platform-side `application.yml` key and how it maps to `config.yaml.*` Helm values.
* [Build a custom collector](/developer-guides/build-and-run/custom-collectors) — when the bundled adapters don't fit and you need a custom Collector image.

### Known gotchas

* **External PostgreSQL is not a chart concern.** The `odd-platform` chart points at the URL you give it; bring-up assumes the database exists, the user has rights, and the schema can be created. Test connectivity from a debug pod (`kubectl run pg-test --rm -it --image=postgres:15 -- psql -h pg.internal.example.com -U odd-platform`) before installing the chart.
* **Chart versions**: don't pin `--version` to a stale release. `helm repo update` and let Helm pick the latest unless you have a reason to lock — the charts are versioned in `Chart.yaml` (`odd-platform` 0.1.10 at the time of writing).
* **Image tag** defaults to `latest` per the chart's `appVersion` — pin `image.tag` explicitly in production to avoid surprise upgrades on pod restart.
* **Ingress is off by default** (`ingress.enabled: false`); set it explicitly with your cluster's ingress controller class and TLS configuration.
* **Upgrade / rollback**: `helm upgrade odd-platform opendatadiscovery/odd-platform -f odd-platform-values.yaml` for upgrades, `helm rollback odd-platform <revision>` for rollback. Always run `helm diff upgrade` (via the [helm-diff plugin](https://github.com/databus23/helm-diff)) on production releases first.

## Option 3: Helm Quick Launch (all-in-one)

{% hint style="warning" %}
**Status: Demo / staging only.** The bundled Bitnami PostgreSQL sub-chart runs as a single pod with `persistence.enabled: false` by default — restarting the pod erases the catalog. Graduate to Option 2 with an external persistent PostgreSQL before going to production.
{% endhint %}

### When to use it

* You want a one-command Platform deployment on a Kubernetes cluster for staging or a longer-running demo.
* You're publishing through AWS Marketplace, where this chart is the QuickLaunch delivery method.
* You don't yet have a managed PostgreSQL and want to evaluate the Platform first.

### Prerequisites

* A Kubernetes cluster (managed or self-managed).
* Helm 3.

### Install

```bash
helm repo add opendatadiscovery https://opendatadiscovery.github.io/charts
helm repo update
helm install odd-quicklaunch opendatadiscovery/odd-quicklaunch \
  --set global.postgresql.auth.postgresPassword=<choose-a-strong-password> \
  --set global.platformServiceType=LoadBalancer \
  --set global.loadBalancerSourceRanges=<your-cidr>/32
```

The single command installs:

* `odd-platform` — the Platform application.
* `postgresql` (Bitnami sub-chart, version `13.2.9`) — bundled database.

### Verify

* `kubectl get pods` — both `odd-quicklaunch-odd-platform-*` and `odd-quicklaunch-postgresql-*` pods are `Running`.
* `kubectl get svc odd-quicklaunch-odd-platform` — note the LoadBalancer external IP / hostname.
* Open `http://<external-ip-or-hostname>/` in your browser — the UI loads. **HTTP only** in this configuration; do not send sensitive data over it.

### Deep dive

* [`odd-quicklaunch` chart](https://github.com/opendatadiscovery/charts/tree/main/charts/odd-quicklaunch) — chart source, including the AWS Marketplace QuickLaunch override-parameter mapping.

### Known gotchas

* **PostgreSQL is non-persistent by default** (`postgresql.primary.persistence.enabled: false` in the chart's `values.yaml`). A pod restart wipes the data.
* **HTTPS is not configured.** The default service is a LoadBalancer over plain HTTP. Don't ingest production credentials.
* **The platform ships unauthenticated, and its config endpoint is publicly readable.** With the default `auth.type=DISABLED`, every UI and API route is permit-all — anyone who can reach the LoadBalancer has full admin access. On top of that, `/actuator/env` is exposed and not behind auth: it leaks the platform's **configuration-key schema** — which properties and sources are wired (that a PostgreSQL datasource is configured, which OAuth2 providers, whether LDAP is set up). Property *values* — including `spring.datasource.url` and the DB password — are masked (`******`) by default (`show-values` defaults to `NEVER`), but the key schema alone tells an attacker how the deployment is wired. Restrict the service to known source ranges with `--set global.loadBalancerSourceRanges=<cidr>`, and enable authentication before this is reachable by anyone you don't trust. See [Enable security](/configuration-and-deployment/enable-security) for turning auth on.
* **No Collector is bundled.** Add a separate `odd-collector` install (Option 2) to actually ingest metadata.
* **Chart version drift.** The Quick Launch chart bundles a pinned `odd-platform` sub-chart version — when you `helm upgrade`, both move together; check the [Chart.yaml](https://github.com/opendatadiscovery/charts/blob/main/charts/odd-quicklaunch/Chart.yaml) for the dependency pin.

## Option 4: AWS EKS via CloudFormation Quick Launch

{% hint style="warning" %}
**Status: Demo-grade.** Provisions an EKS cluster with bundled non-persistent PostgreSQL over HTTP only. Excellent first-look on AWS; not a production posture.
{% endhint %}

### When to use it

* You want to try ODD on AWS without provisioning EKS yourself.
* You're already on one of the supported AWS regions.

### Prerequisites

* An AWS account with permissions to create CloudFormation stacks, EKS clusters, and EC2 nodes.
* You're operating in one of the supported regions: **us-west-2, us-west-1, us-east-2, us-east-1**. Other regions require manual EKS provisioning (Option 2).

### Install

The CloudFormation template is hosted at `https://odd-ct-templates.s3.us-east-2.amazonaws.com/odd_cloudformation.yaml`. Launch from the AWS console with that template URL — full step-by-step (cluster setup, node group, role, post-deploy access via `kubectl`, Bitnami PostgreSQL install, Platform install, Collector install with token wiring) lives on the dedicated EKS page below.

### Verify

* `kubectl get pods` shows `odd-platform-*`, `postgresql-*`, and `odd-collector-*` pods all `Running`.
* `kubectl get svc odd-platform -o=custom-columns=EXTERNAL-IP:.status.loadBalancer.ingress[0].hostname` returns the public hostname.
* `http://<load-balancer-hostname>/` loads the UI (HTTP only — see gotchas).

### Deep dive

* [Deploy to Amazon Elastic Kubernetes Service (EKS)](/configuration-and-deployment/quick_launch_on_amazon_elastic_kubernetes_service) — the canonical AWS onboarding walkthrough; covers the Quick Launch flow, kubectl auth, Bitnami PostgreSQL install, Platform install, Collector install with the `collector-values.yaml` pattern.
* [`charts/QUICKSTART.md`](https://github.com/opendatadiscovery/charts/blob/main/QUICKSTART.md) — same walkthrough on the chart repo.
* [`charts/cloudformation/odd_cloudformation.yaml`](https://github.com/opendatadiscovery/charts/blob/main/cloudformation/odd_cloudformation.yaml) — the CloudFormation template itself.

### Known gotchas

* **HTTP only** — the LoadBalancer is plain-HTTP. Don't send sensitive data over it. For production, terminate TLS at an Ingress / ALB or graduate to Option 2 with HTTPS.
* **The platform's configuration is exposed over that same plain HTTP.** The shipped config exposes the Spring Boot environment endpoint at `/actuator/env`, and that path is reachable without authentication in the default deployment (it is whitelisted out of the auth chain, and this Quick Launch ships with auth disabled — see the EKS page below). By default the endpoint masks **every** property value (`show-values` defaults to `NEVER`), so `spring.datasource.url`, the DB password, and any Slack / webhook URLs are all redacted (`******`) — what it exposes without authentication is the **configuration-key schema**: which properties and sources are wired (that a PostgreSQL datasource, Slack, and any webhooks are configured), not their values. Over plain HTTP that schema is readable by anyone who can reach the LoadBalancer. Lock the LoadBalancer down to known source ranges, and turn `/actuator/env` off (or put real auth in front of it) before exposing this beyond a throwaway demo.
* **PostgreSQL is non-persistent** — the Bitnami chart is installed with `primary.persistence.enabled=false`.
* **Region restriction** — only `us-west-2`, `us-west-1`, `us-east-2`, `us-east-1` are supported by the CloudFormation template. For other regions, do Option 2 by hand.
* **Cleanup costs** — leaving the EKS cluster running incurs AWS charges. `helm uninstall odd-platform` then [delete the CloudFormation stack](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/cfn-console-delete-stack.html) when you're done.
* **Token regeneration breaks active ingestion.** If you don't securely store the Collector token issued by the Platform UI, you must regenerate it; the original is not recoverable from the platform. Regeneration is **not** a zero-downtime rotation: the Platform overwrites the token in place and invalidates the old value the instant you confirm — there is no overlap window where both the old and new token are accepted. A Collector that is already running with the old token starts getting `401`s on every ingestion request immediately, and stops ingesting until you put the new token into its config and restart it. Plan the regeneration as a brief ingestion outage: regenerate, update the Collector's `collector_config.yaml` (or the Helm `collectorConfig` / secret), then redeploy the Collector.

## Option 5: Build from source / developer deployment

{% hint style="info" %}
**Status: Contributor / customisation path.** Build artefacts from source for development or to ship a customised image. Not the standard operator path.
{% endhint %}

### When to use it

* You're contributing to ODD Platform or Collector and need to run a build locally.
* You want to customise the Platform or Collector beyond what the charts expose (custom image, code patches).
* You want to test an unreleased branch before it ships as a chart.

### Prerequisites

Per [Build and run ODD Platform](/developer-guides/build-and-run/build-and-run-odd-platform) — Java 17, Gradle, Node, Docker. Per [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors) — Python 3.9 or higher, Poetry 1.2.0, Docker.

### Install

* Platform: see [Build and run ODD Platform](/developer-guides/build-and-run/build-and-run-odd-platform) for the gradle build and Docker image steps.
* Collector: see [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors) for the Poetry / Docker flow per sub-collector.
* Custom Collector authoring: [Build a custom collector](/developer-guides/build-and-run/custom-collectors) — when an existing adapter doesn't fit.

### Deep dive

* [Build and run ODD Platform](/developer-guides/build-and-run/build-and-run-odd-platform)
* [Build and run ODD Collectors](/developer-guides/build-and-run/build-and-run-odd-collectors)
* [Build a custom collector](/developer-guides/build-and-run/custom-collectors)

### Known gotchas

* The build paths are validated for the Linux / macOS path; Windows users typically run via WSL2.
* M1 / Apple Silicon collector builds need extra environment variables for `pyodbc`, `confluent-kafka`, and `grpcio` — see the [build-and-run troubleshooting section](/developer-guides/build-and-run/build-and-run-odd-collectors#troubleshooting).

## Optional companion: `odd-tracing-gateway`

`odd-tracing-gateway` is an optional companion service that bridges OpenTelemetry distributed tracing into the ODD catalog — operator microservices push OpenTelemetry traces to the gateway, and the gateway exposes the inferred service entities for the Platform to pull. It is **not** an alternative to the deployment options above; it sits beside the Platform as a separate process (the Push adapter / standalone gateway shape in the [adapter taxonomy](/introduction/main-concepts#the-architecture-chain)).

For installation (Helm or Docker Compose), the configuration reference, the API surfaces (inbound OTLP and outbound entities), and the operator caveats, see [`odd-tracing-gateway`](/integrations/integrations/odd-tracing-gateway) under Integrations — that page is the canonical home.

## Still stuck?

* File an issue against the relevant repo:
  * [opendatadiscovery/odd-platform](https://github.com/opendatadiscovery/odd-platform/issues) — Platform bugs and feature requests
  * [opendatadiscovery/odd-collectors](https://github.com/opendatadiscovery/odd-collectors/issues) — Collector / adapter issues
  * [opendatadiscovery/charts](https://github.com/opendatadiscovery/charts/issues) — Helm chart bugs
* Join the community Slack: <https://go.opendatadiscovery.org/slack>
* Read the [How to contribute](/developer-guides/how-to-contribute) guide for the contribution flow.


# Try locally

Run ODD locally with docker-compose — a demo sandbox with the platform, sample database, lightweight pull collector, and metadata enricher. For production paths see Deployment Options.

This section includes instructions to run the ODD Platform locally using docker and docker-compose. This configuration is basic and best suited as a demo sandbox. For other deployment paths (Helm on Kubernetes, AWS EKS, build from source), see [Deployment Options](/configuration-and-deployment/deployment).

This environment consists of:

* ODD Platform – an application that ingests, structurizes, indexes and provides a collected metadata via REST API and UI
* ODD Platform Enricher – a tool to inject a metadata sample into the Platform
* PostgreSQL sample database
* `odd-collector` – the bundled lightweight pull collector (one implementation in the [Collector](/introduction/main-concepts#the-architecture-chain) family); gathers metadata from your data sources via pull adapters.

## Prerequisites

* Docker Engine 19.03.0+
* Preferably the latest docker-compose

## Step 1: Configuring and running ODD Platform with a metadata sample in it

### Assumptions

* Ports 5432 and 8080 are free. Commands to check that might be:
  * Linux/Mac: `lsof -i -P -n | grep LISTEN | grep <PORT_NUMBER>`
  * Windows Powershell: `Get-NetTCPConnection | where Localport -eq <PORT_NUMBER> | select Localport,OwningProcess` Replace `<PORT_NUMBER>` with 5432 and 8080. Empty output mean that the port is free and ready to go

### Execution

First, clone the GitHub repository <https://github.com/opendatadiscovery/odd-platform> and then just run from the **project root folder** `docker-compose -f docker/demo.yaml up -d odd-platform-enricher`.

### Result

1. Open <http://localhost:8080/management/datasources> in your browser.\
   You should be able to see 10 predefined data sources in the list.
2. Go to the **Catalog**.\
   You should be able to see metadata sample injected in the Platform.

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-30b55affb7f259db8ecdc9635e55050f47697e27%2Ftrylocally1.gif?alt=media)

## Step 2: Configuring and running Collector to gather metadata from the sample data source

### Create Collector entity

1. Go to the <http://localhost:8080/management/collectors> and select `Add collector`
2. Complete the following fields:
   * **Name**
   * **Namespace** (optional)
   * **Description** (optional)
3. Click **Save**. Your collector should appear in the list
4. Copy the token by clicking **Copy** right to the token value

### Configure and run the Collector

1. Paste the token obtained in the previous step into the `docker/config/collector_config.yaml` file under the `token` entry
2. If you'd like, you may change the name of the `postgresql` plugin under the `name` entry
3. Save the changed file and run **from the project root folder** `docker-compose -f docker/demo.yaml up -d odd-collector`

{% hint style="warning" %}
**This demo does not actually enforce the token.** The bundled stack ships with ingestion authentication turned off (`auth.ingestion.filter.enabled` defaults to `false`), so the local Platform accepts metadata at `/ingestion/entities` from any caller — the token you paste here is what a real Collector sends, but the demo Platform never checks it. That is fine on a local workstation. Before exposing a Platform on a network, turn ingestion authentication on so the token actually gates ingestion — see [Enable security → Ingestion authentication](/configuration-and-deployment/enable-security).
{% endhint %}

### Result

1. Open <http://localhost:8080/management/datasources> in your browser.\
   You should be able to see a new data source with the name you've passed into the collector\_config.yaml file (Default is `Sample demo data source`). Overall you should see 11 data sources in the list.
2. Go to the **Catalog**. Select the created data source in the **Datasources** filter.\
   You should be able to see 11 new entities of different types injected into the Platform.

![](https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-ac74a56b2189d9a161747d16dea6602f2e8dde5c%2Ftrylocally2.gif?alt=media)

## Step 3 (Optional): Configuring and running Collector to gather metadata from your own data sources

### Assumptions

* You've done Step 1 and Step 2
* You already have locally accessible data sources and want to ingest metadata from these data sources into the Platform
* These data sources are supported by collectors:
  * [supported data sources by odd-collector](/integrations/integrations/odd-collector)
  * [supported data sources by odd-collector-aws](/integrations/integrations/odd-collector-aws)
  * [supported data sources by odd-collector-gcp](/integrations/integrations/odd-collector-gcp)
  * [supported data sources by odd-collector-azure](/integrations/integrations/odd-collector-azure)

### Configure the existing Collector

1. Add new entries under plugin list in the `docker/config/collector_config.yaml`\
   See the [`odd-collector` configuration reference](/integrations/integrations/odd-collector) for per-source-type configuration shapes (per-adapter spotlights with YAML examples + the full per-adapter configuration reference table).
2. Restart the Collector by running **from the project root folder** `docker-compose -f docker/demo.yaml restart odd-collector`

### Result

You should be able to see new data sources and data entities that correspond with them.

### Troubleshooting

**My entities from the sample data aren't shown in the Platform.**

Check the logs by running from the project root folder `docker-compose -f docker/demo.yaml logs -f`.


# Deploy to Amazon Elastic Kubernetes Service (EKS)

Quick Launch of Open Data Discovery platform and collector on Amazon Elastic Kubernetes Service (EKS)

This page is the AWS-EKS-specific walkthrough; for the broader picture (Docker Compose, self-managed Helm, build from source), start at [Deployment Options](/configuration-and-deployment/deployment).

***

## What will be deployed

This is the new way for data teams to discover, understand, trust, and collaborate on data assets. ODD serves as a tool to put Data Governance strategies into practice and this guide will show you an easy way to get Open Data Discovery up and running on Amazon EKS.

New environment will consist of:

* ODD Platform – an application that collects, structures, indexes, and provides metadata via REST API and UI
* PostgreSQL database that is used by ODD Platform as a persistence storage
* ODD Collector with configured PostgreSQL adapter that grabs metadata from the ODD Platform's database

## Prerequisites

* Before you start, ensure that you have an **AWS account** and if not, then you have to create one.

## Overview of the Quick Launch

* Provision an EKS Cluster
* Install and deploy PostgreSQL
* Deploy and run Open Data Discovery (ODD)
* Configure, deploy, and run Collector

## Start an EKS Cluster

* **Step 1**. Click on [Quick launch](https://us-east-2.console.aws.amazon.com/cloudformation/home?region=eu-central-1#/stacks/create/review?templateURL=https://odd-ct-templates.s3.us-east-2.amazonaws.com/odd_cloudformation.yaml\&stackName=ODD-EKS) and you’ll be redirected to the Cloud Formation Stack in the AWS account where you are logged in. Please check that you are in one of the supported regions: us-west-2, us-west-1, us-east-2, us-east-1.
* **Step 2**. You’ll be directed through several setup stages, including following ones:
  * **Cluster Setup**
    * Cluster Name: Supply a unique and descriptive name for your EKS cluster, like “MyEKS-Cluster”. The default name is pre-set as: ODD-EKS.
  * **Node Group**
    * Instance Types: Choose EC2 Instance types for your worker nodes. The default type is pre-set as: t3.large.
    * Desired Capacity: Indicate the quantity of worker nodes you want in the node group. The default is configured as 1.
    * SSH Key Pair: Opt for an existing or create a new one for secure worker node access.
  * **Role**
    * Provide an existing role with sufficient privileges or create and assign a new one.
* **Step 3**. Check all your configurations to confirm their correctness.
* **Step 4**. Click “Create Stack” to confirm the EKS cluster creation process.

## Access and Manage your EKS Cluster

### Authentication with AWS EKS

To begin, authenticate kubectl with your EKS cluster. AWS offers a convenient command:

`aws eks --region <region> update-kubeconfig --name <cluster-name>`

Replace `<region>` with the AWS region where your EKS cluster is deployed and `<cluster-name>` with the name of your EKS cluster to have a command similar to the following:

`aws eks --region us-east-1 update-kubeconfig --name ODD-EKS`

At the current state only following regions are available:

* **us-west-2**
* **us-west-1**
* **us-east-2**
* **us-east-1**

### Verification and Configuration

Confirm that your kubectl configuration is correctly set by listing the available nodes in your cluster:

`kubectl get nodes`

## Install Helm for your EKS Cluster

### Obtain the Helm binary

Visit the Helm [Github releases page](https://github.com/helm/helm/releases) and download the suitable Helm binary. You can use the following command:

`sudo yum install -y openssl && curl -sSL https://raw.githubusercontent.com/helm/helm/master/scripts/get-helm-3 | bash`

To ensure a successful installation, use the command:

`helm version --short`

### Add a Helm Chart Repository

Add a repository to access pre-built charts:

`helm repo add bitnami https://charts.bitnami.com/bitnami`

## Install PostgreSQL using Helm

Install PostgreSQL with the command:

`helm install postgresql bitnami/postgresql --set primary.persistence.enabled=false --set global.postgresql.auth.database=odd-platform`

This basic deployment can be tailored by adjusting values in the Helm chart to meet your specific requirements.

To check the status of your deployment after the installation is done, use:

`kubectl get pods`

Upon the successful installation of PostgreSQL, an auto-generated password becomes available. It’s a good practice to store this password as an environment variable and use it when working with the ODD platform.

To do that, execute the following command:

`export POSTGRES_PASSWORD=$(kubectl get secret --namespace default postgresql -o jsonpath="{.data.postgres-password}" | base64 -d)`

## Deploy Open Data Discovery (ODD)

To deploy ODD platform, first you need to add a repository:

`helm repo add opendatadiscovery https://opendatadiscovery.github.io/charts`

### Install the platform

`helm install odd-platform opendatadiscovery/odd-platform --set config.yaml.spring.datasource.username=postgres --set config.yaml.spring.datasource.password="$POSTGRES_PASSWORD" --set config.yaml.spring.datasource.url="jdbc:postgresql://postgresql:5432/odd-platform" --set service.type=LoadBalancer --set service.annotations."service\.beta\.kubernetes\.io/load-balancer-source-ranges"="<IPAddressOfYourLocalStationHere>/32"`

To find your IP address follow these instructions.

* For Windows OS, you can search for “What is my IP” in your preferred search engine.
* For MacOS and Linux, use the command `wget -qO- ipecho.net/plain` And your public IP address will be displayed in the terminal output. Also, if you are behind a router firewall, the IP address you retrieve will be the public IP assigned to your router by your ISP.

For example,

`helm install odd-platform opendatadiscovery/odd-platform --set config.yaml.spring.datasource.username=postgres --set config.yaml.spring.datasource.password="$POSTGRES_PASSWORD" --set config.yaml.spring.datasource.url="jdbc:postgresql://postgresql:5432/odd-platform" --set service.type=LoadBalancer --set service.annotations."service\.beta\.kubernetes\.io/load-balancer-source-ranges"="83.3.12.58/32"`

If you wish to enable connectivity with multiple IPs, you’ll need to execute the following set of commands instead:

`helm upgrade odd-platform opendatadiscovery/odd-platform --set config.yaml.spring.datasource.username=postgres --set config.yaml.spring.datasource.password="$POSTGRES_PASSWORD" --set config.yaml.spring.datasource.url="jdbc:postgresql://postgresql:5432/odd-platform" --set service.type=LoadBalancer --set service.annotations."service\.beta\.kubernetes\.io/load-balancer-source-ranges"="<YourIPAddressHere>/32\,<AnotherIPAddressHere>/32"`

Do not forget to replace `<YourIPAddressHere>` and `<AnotherIPAddressHere>` in this command with your IP addresses, separated with commas and written in double quotation marks.

### How to be sure everything is Up and Running?

There is a common command for this action:

`kubectl get pods`

`kubectl get svc`

After completing the setup and ensuring everything is up and running, you can start using the ODD platform through your web browser. To do this, obtain the hostname of your Load Balancer and use it to establish a connection to your EKS.

`kubectl get svc odd-platform -o=custom-columns=EXTERNAL-IP:.status.loadBalancer.ingress[0].hostname | tail -n 1`

If the setup is successful, you will be able to access the platform demo page directly from your web browser.

*With versions of the platform >= 0.18.0, you can browse the platform API at the Swagger UI hosted on your running platform: `http://<your-load-balancer-host>/api/v3/webjars/swagger-ui/index.html`. For example, if your Load Balancer host is `a1e67ff8befc54b75969f9834a6e329a-948212351.us-east-1.elb.amazonaws.com`, you would visit `http://a1e67ff8befc54b75969f9834a6e329a-948212351.us-east-1.elb.amazonaws.com/api/v3/webjars/swagger-ui/index.html`.*

## Important Note!

This Quick Launch is **demonstration-grade**, and exposes a fully open platform on a public LoadBalancer. Read the three caveats below before you point it at anything you care about.

**No HTTPS.** There are no certificates created to use encrypted communication. Only the http protocol is supported in this setup — for example, `http://a1e67ff8befc54b75969f9834a6e329a-948212351.us-east-1.elb.amazonaws.com/`. This protocol is not secure; do not send any sensitive information over this connection. For production cases please configure the HTTPS protocol.

**No authentication.** The platform ships with authentication turned off (`auth.type=DISABLED`), and the `helm install` commands above do not change that. Every UI page and every API endpoint is permit-all: anyone who can reach the LoadBalancer address has full administrator access — they can read your whole catalog, edit it, and delete data sources. The only thing standing between the open platform and the public internet is the `load-balancer-source-ranges` annotation in the install command, which restricts access to the single IP you supplied. Keep that source-range filter in place, and turn on real authentication before sharing the address with anyone — see [Enable security](/configuration-and-deployment/enable-security) for the login-form, OAuth2, and LDAP options.

**The platform's configuration is exposed over that same open HTTP.** You pass the PostgreSQL password into the platform on the command line with `--set config.yaml.spring.datasource.password="$POSTGRES_PASSWORD"`. The platform exposes Spring Boot's environment endpoint at `/actuator/env`, and that path is reachable without authentication (it is whitelisted out of the auth chain, and auth is disabled anyway). By default `/actuator/env` masks **every** property value (`show-values` defaults to `NEVER`), so `spring.datasource.url` and the password are both redacted (`******`) — but it still reveals the **configuration-key schema**: that a PostgreSQL datasource is configured, plus the rest of the wired property keys and sources. Combined with the unauthenticated platform and plain HTTP, the deployment's configuration shape is readable by anyone who reaches the LoadBalancer. This is acceptable for a throwaway demo behind a locked-down source range; it is not acceptable for anything else. Before going further, restrict the source ranges, enable authentication, and disable `/actuator/env` (or put authentication in front of the actuator endpoints).

## How to delete Cloudformation Stack?

Deletion starts with uninstalling the platform

`helm uninstall odd-platform`

To avoid incurring additional charges or when you’re confident that you no longer require your current resources any longer you can [delete your Cloudformation Stack](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/cfn-console-delete-stack.html).

## ODD Collector Configuration for AWS EKS

Setting up the Collector involves several steps.

* Create a **Namespace** and proceed to initiate the addition of **a new collector**. Choose a namespace from the drop-down list of available options, optionally include a description, and save the settings.
* Make sure to securely copy and store the **token** generated by the platform — there is no way to retrieve it again later, so you will need to regenerate it if it is lost. Regenerating is **not** a zero-downtime rotation: the platform overwrites the token in place and invalidates the old value immediately, with no overlap window. If the Collector is already running, regenerating the token makes it start failing ingestion right away — you must put the new token into `collector-values.yaml` (re-run the `sed` substitution below) and `helm upgrade` the Collector before ingestion resumes.
* Now, it is time to proceed with adding the ODD repository and configuring the collector files. This can be accomplished by executing the following commands in the specified order.

`helm repo add opendatadiscovery https://opendatadiscovery.github.io/charts`

`wget https://raw.githubusercontent.com/opendatadiscovery/charts/main/cloudformation/collector-values.yaml`

**Note:** you need to replace the **Generated token** part in following command with the token you have copied earlier and run it.

`sed -i 's/odd-token/<Generated token>/g' collector-values.yaml`

`export POSTGRES_PASSWORD=$(kubectl get secret --namespace default postgresql -o jsonpath="{.data.postgres-password}" | base64 -d)`

`helm install odd-collector opendatadiscovery/odd-collector --set nameOverride=odd-collector --set passwordSecretsEnvs.POSTGRES_PASSWORD=$POSTGRES_PASSWORD -f collector-values.yaml`

If you’ve followed the instructions correctly, you should see in outcome in your Cloudshell informing you that ODD Collector is up and running.

Furthermore, we’ve made it available for you to include additional plugins if desired.

To do that, manually update the `collector-values.yaml` file with your chosen text editor and then run the following command in the CloudShell:

`helm upgrade --install odd-collector opendatadiscovery/odd-collector --set nameOverride=odd-collector --set passwordSecretsEnvs.POSTGRES_PASSWORD=$POSTGRES_PASSWORD -f collector-values.yaml`


# Configure ODD Platform

This section defines how to configure ODD Platform in order to leverage all of its functionality and features.

This page is the post-deployment configuration reference for the running Platform — every `application.yml` key the Platform consumes. For the deployment path itself (Docker Compose, Helm, AWS EKS, build from source), start at [Deployment Options](/configuration-and-deployment/deployment).

## Configuration approaches

There are two ways to configure the Platform:

* **Environment variables** are used for simple entries
* Configuring via **YAML** can come in handy when it is necessary to define a complex configuration block (e.g OAuth2 authentication or logging levels).

<details>

<summary>YAML entries VS environment variables</summary>

Here is an example of how to define the following block and configure the Platform with it using environment variables.

YAML:

```yaml
spring:
    datasource:
        url: URL
        username: USERNAME
        password: PASSWORD
    custom-datasource:
        url: URL
        username: USERNAME
        password: PASSWORD
```

To configure the Platform using environment variables, replace semicolons with underscores and uppercasing words, like so:

* `SPRING_DATASOURCE_URL=URL`
* `SPRING_DATASOURCE_USERNAME=USERNAME`
* `SPRING_DATASOURCE_PASSWORD=PASSWORD`
* `SPRING_CUSTOM_DATASOURCE_URL=URL`
* `SPRING_CUSTOM_DATASOURCE_USERNAME=USERNAME`
* `SPRING_CUSTOM_DATASOURCE_PASSWORD=PASSWORD`

</details>

## Connect your database

For all of its features ODD Platform uses PostgreSQL database and PostgreSQL database only. These variables are needed to be defined to connect ODD Platform to database:

* `spring.datasource.url`: [JDBC string](https://jdbc.postgresql.org/documentation/80/connect.html) of your PostgreSQL database. Default value is `jdbc:postgresql://127.0.0.1:5432/odd-platform`
* `spring.datasource.username`: your PostgreSQL user's name. Default value is `odd-platform`
* `spring.datasource.password`: your PostgreSQL user's password. Default value is `odd-platform-password`. **Override this before any non-localhost deployment** — see [Management endpoint exposure and credential hygiene](#management-endpoint-exposure-and-credential-hygiene) for why the shipped default is a load-bearing operator-override.

These variables are optional and will be used to connect to PostgreSQL and store Lookup Tables. Each of the three keys is declared in `R2DBCConfiguration` as `@Value("${spring.custom-datasource.X:}")` — the trailing colon with no value means **the @Value default is the empty string**, not the JDBC URL / username / password values listed below. When a key is unset (or blank), the bean factory falls back to the corresponding primary `spring.datasource.*` value at startup. The values below are therefore the **fallback** an operator observes with a default deployment, not the `spring.custom-datasource.*` keys' own defaults — so overriding `spring.datasource.url` will also change what `spring.custom-datasource.url` resolves to:

* `spring.custom-datasource.url`: [JDBC string](https://jdbc.postgresql.org/documentation/80/connect.html) of your PostgreSQL database where we store Lookup Tables. Falls back to `spring.datasource.url` when unset; the platform's primary `spring.datasource.url` default is `jdbc:postgresql://127.0.0.1:5432/odd-platform`. Note: you can specify any {database\_host}, {database\_port} or {database\_name} but schema, where Lookup Tables are stored always is lookup\_tables\_schema.
* `spring.custom-datasource.username`: your PostgreSQL user's name for custom-datasource. Falls back to `spring.datasource.username` when unset; the platform's primary `spring.datasource.username` default is `odd-platform`.
* `spring.custom-datasource.password`: your PostgreSQL user's password for custom-datasource. Falls back to `spring.datasource.password` when unset; the platform's primary `spring.datasource.password` default is `odd-platform-password`.

So that your database connection defining block would look like this:

{% tabs %}
{% tab title="YAML" %}

```yaml
spring:
    datasource:
        url: jdbc:postgresql://{database_host}:{database_port}/{database_name}
        username: {database_username}
        password: {database_password}
#    [OPTIONAL]
     custom-datasource:
        url: jdbc:postgresql://{database_host}:{database_port}/{database_name}
        username: {database_username}
        password: {database_password}
```

{% endtab %}

{% tab title="Environment variables" %}

```
SPRING_DATASOURCE_URL=jdbc:postgresql://{database_host}:{database_port}/{database_name}
SPRING_DATASOURCE_USERNAME={database_username}
SPRING_DATASOURCE_PASSWORD={database_password}
# [OPTIONAL]
SPRING_CUSTOM_DATASOURCE_URL=jdbc:postgresql://{database_host}:{database_port}/{database_name}
SPRING_CUSTOM_DATASOURCE_USERNAME={database_username}
SPRING_CUSTOM_DATASOURCE_PASSWORD={database_password}
```

{% endtab %}
{% endtabs %}

## Security

Please follow the [Enable security](/configuration-and-deployment/enable-security) section for enabling security in ODD Platform.

### Management endpoint exposure and credential hygiene

The platform's Spring Boot Actuator endpoints (`/actuator/**`) are intentionally **whitelisted ahead of the authentication chain** in every `auth.type`, and the shipped configuration enables the `env` and `info` endpoints. The shipped database password is a well-known string. Together these defaults turn a default deployment into a one-line-away-from-full-PostgreSQL-compromise system if exposed on a non-trusted network. The mitigations below are the operator's responsibility today. For the *monitoring* use of these endpoints — wiring liveness/readiness probes to `/actuator/health` and scraping `/actuator/prometheus` — see [Health and monitoring](/configuration-and-deployment/health-and-monitoring).

#### `/actuator/**` is anonymously reachable in every auth mode

`SecurityConstants.WHITELIST_PATHS` contains `/actuator/**`. Reachable before the auth chain runs in `DISABLED`, `LOGIN_FORM`, `OAUTH2`, and `LDAP` alike. The shipped `application.yml` enables `management.endpoint.env.enabled=true` but sets **no** `management.endpoint.env.show-values`, so the Spring Boot default (`NEVER`) applies — `/actuator/env` redacts *every* property **value** (`******`) for every caller, authenticated or not, including `spring.datasource.url`. What an unauthenticated caller scraping `/actuator/env` *does* learn is the **configuration-key schema**: which keys and property sources are present — which OAuth2 providers are wired (by their key prefixes), whether LDAP is configured, whether REMOTE attachment storage is set up, and that a JDBC datasource is configured (the key, not its value). Values stay masked unless an operator sets `show-values` to `WHEN_AUTHORIZED` or `ALWAYS`; the exposure to mitigate is the unauthenticated reachability of the endpoint and the configuration schema it reveals.

Apply at least one of the mitigations below for any deployment reachable from outside a fully-trusted network:

| Mitigation                 | How                                                                                                               | Recommended for                                                                       |
| -------------------------- | ----------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------- |
| Separate management port   | Set `management.server.port: 8081` and route `:8081` only on your internal management network.                    | All production deployments.                                                           |
| Firewall the actuator path | Add a reverse-proxy rule rejecting `/actuator/**` from the public CIDR range; allow only your monitoring network. | Single-port deployments where a separate management port is infeasible.               |
| Restrict default exposure  | Set `management.endpoints.web.exposure.include: health,prometheus` (drop `env, info`).                            | All production deployments — combine with one of the network-level mitigations above. |

A platform-side default-restriction is tracked upstream; until it ships, do not rely on the platform default for any reachable deployment.

#### The database password ships with a well-known default

`application.yml` ships `spring.datasource.password: odd-platform-password` as the default. An operator deploying ODD without explicitly overriding the property deploys with a public, documented credential. (The JDBC URL *value* is masked at `/actuator/env` under the default `show-values: NEVER` described above — but the password itself is public, and a database whose host is co-located with or guessable from the deployment topology is then one well-known credential away from compromise.) Override `spring.datasource.password` (and `spring.custom-datasource.password` if `spring.custom-datasource.*` is configured separately from the primary datasource) before exposing the platform on any non-localhost network. This is the same class of silent-insecure-default risk that previously affected attachment storage on container restart — read once, override before deployment, never assume the shipped default is safe.

#### Configuration-properties classes include credentials in `toString()`

`ODDLDAPProperties` and `ODDOAuth2Properties.OAuth2Provider` carry Lombok's `@Data` annotation alongside their `password` and `clientSecret` fields, respectively. `@Data` generates a `toString()` that includes every field verbatim — there is no `@ToString.Exclude` on any credential field today. A future log statement (`log.info("loaded properties: {}", properties)`) or an exception handler that emits properties on boot failure would write LDAP passwords and OAuth client secrets in cleartext to log infrastructure. Treat the platform's application logs as credential-sensitive: route them to an audit-grade log sink, redact at the log-pipeline tier if you cannot guarantee end-to-end access control, and do not store them in unrestricted long-term archives. A platform-side `@ToString.Exclude` rollout across credential fields is tracked upstream.

## Select session provider

ODD Platform stores HTTP session state in one of three places: the platform JVM (in-memory), the platform's PostgreSQL database, or an external Redis data store. The provider is selected with `session.provider` (`SESSION_PROVIDER` env var) and accepts one of three values:

* `IN_MEMORY` — sessions live in a `ConcurrentHashMap` inside the JVM. **ODD Platform defaults to this value.**
* `INTERNAL_POSTGRESQL` — sessions are persisted to the platform's PostgreSQL database (`SPRING_SESSION` / `SPRING_SESSION_ATTRIBUTES` tables).
* `REDIS` — sessions are persisted to an external [Redis](https://redis.io/) data store via Spring Session's `@EnableRedisWebSession`.

Quick selection guidance:

* Single-instance deployment, restart-tolerant logout acceptable → `IN_MEMORY`
* Multi-instance deployment or persistence across restarts is required → `INTERNAL_POSTGRESQL` (no extra infrastructure) or `REDIS` (if you already operate Redis or need sub-millisecond session reads)

Each provider has operator-visible characteristics that affect sizing, multi-instance behavior, and connection wiring. Read the relevant subsection before deploying.

### `IN_MEMORY` (default)

Sessions are kept in a `ConcurrentHashMap` inside the platform JVM, wrapped by Spring Session's `ReactiveMapSessionRepository`. Suitable for local development and single-instance evaluations where session loss on restart is acceptable.

#### Characteristics & caveats

* **Sessions are lost on every platform restart.** The session map lives in heap; any restart (deploy, crash, container recycle) clears it and forces every authenticated user to log in again.
* **No multi-instance support.** Two ODD Platform instances behind a load balancer each maintain a separate session map. A request that lands on a different instance than the one that authenticated the user appears unauthenticated. **Collector data-source registration is especially affected** — the `/ingestion/datasources` filter writes a `collectorId` into the request's session, and the subsequent `POST /ingestion/datasources` handler reads it back; if the two requests hit different replicas, the handler raises an `IllegalStateException("Collector id is null")` returned to the collector as HTTP 500. For multi-replica deployments choose `INTERNAL_POSTGRESQL` or `REDIS`.
* **Eviction is by Spring Session expiry only.** The repository wraps a raw `ConcurrentHashMap` with no secondary eviction policy (no LRU, no max-entries cap). A long-running platform with many short-lived sessions accumulates map entries until each entry's TTL elapses; high-traffic deployments running with the shipped default `spring.session.timeout: -1` (no timeout) accumulate sessions indefinitely. **Set a finite `spring.session.timeout`** (see [Session lifetime](#session-lifetime-spring-session-timeout) below) to bound the in-memory footprint.

{% tabs %}
{% tab title="YAML" %}

```yaml
session:
  provider: IN_MEMORY
```

{% endtab %}

{% tab title="Environment variables" %}

```
SESSION_PROVIDER=IN_MEMORY
```

{% endtab %}
{% endtabs %}

### `INTERNAL_POSTGRESQL`

Sessions are persisted in the platform's own PostgreSQL database, in the `SPRING_SESSION` and `SPRING_SESSION_ATTRIBUTES` tables. ODD Platform implements a custom JOOQ-based reactive `JooqSessionRepository` for this provider — the standard `spring.session.jdbc.*` Spring Session keys do **not** apply. Connection settings reuse the existing platform `spring.datasource.*` configuration; no additional database wiring is required.

#### Characteristics & caveats

* **Sessions survive platform restarts.** Authenticated users remain logged in across deploys (until their session row's TTL has passed).
* **Multi-instance support.** All ODD Platform instances point at the same database, share the session tables, and can serve requests for any authenticated user regardless of which instance answered the original login.
* **Expired-session cleanup runs hourly and is not configurable.** A `@Scheduled(fixedRate = 1, timeUnit = HOURS)` housekeeping job (`PostgreSQLSessionHousekeepingJobHandler.deleteExpiredSessions`) deletes rows whose `EXPIRY_TIME` is in the past from both `SPRING_SESSION` and `SPRING_SESSION_ATTRIBUTES`. Expired session rows therefore remain in the tables for **up to one hour past their TTL** before being cleaned. The cadence is hardcoded — there is no config key to tune it.
* **Sizing implication.** When sizing the database (connection pool, disk, vacuum schedule), assume the session tables hold the high-water-mark count of authenticated users plus up to one hour of post-expiry stragglers. For high-cardinality / short-TTL deployments (many users, short `spring.session.timeout`), the post-expiry overhang can dominate steady-state row count.

{% tabs %}
{% tab title="YAML" %}

```yaml
session:
  provider: INTERNAL_POSTGRESQL
```

{% endtab %}

{% tab title="Environment variables" %}

```
SESSION_PROVIDER=INTERNAL_POSTGRESQL
```

{% endtab %}
{% endtabs %}

### `REDIS`

Sessions are persisted to an external Redis data store via Spring Session's `@EnableRedisWebSession`. Suitable for multi-instance deployments that already operate Redis, or that need sub-millisecond session reads. ODD Platform does not bundle Redis; the operator must provide a Redis 6+ instance and supply its connection settings under the `spring.data.redis.*` namespace (Spring Boot 3.x; the legacy `spring.redis.*` prefix from Spring Boot 2.x has been removed and will not bind).

#### Characteristics & caveats

* **Sessions survive platform restarts and span instances** — same persistence behavior as `INTERNAL_POSTGRESQL`, but reads and writes happen against Redis directly.
* **Connection wiring is operator-supplied.** Unlike `INTERNAL_POSTGRESQL` (which reuses the platform's existing PostgreSQL connection), Redis settings must be configured separately. ODD Platform's `application.yml` ships **no Redis defaults** — every operator deploying with `REDIS` must set at least the host and port, plus credentials and TLS for any production deployment.
* **TLS, pool sizing, and command timeouts inherit Spring Data Redis defaults** unless explicitly overridden. For managed Redis providers (AWS ElastiCache, Redis Cloud, Azure Cache for Redis) and any TLS-required Redis deployment, set `spring.data.redis.ssl.enabled: true`. For high-concurrency deployments, tune the Lettuce connection pool with `spring.data.redis.lettuce.pool.*`.
* **Eviction is delegated to Redis.** ODD Platform does not run a housekeeping job for Redis-stored sessions; the Redis server's own per-key TTL and `maxmemory-policy` govern session eviction. Configure your Redis instance accordingly.

{% hint style="warning" %}
**The** [**health endpoint**](/configuration-and-deployment/health-and-monitoring) **is blind to Redis by default.** With `REDIS` selected, every authenticated request depends on Redis — but the bundled configuration ships `management.health.redis.enabled: false`, and the `REDIS` session wiring registers no health contributor of its own. A Redis outage (server down, unreachable, or evicting under `maxmemory`) therefore returns errors to every logged-in user while `/actuator/health` keeps reporting `UP` — a load balancer or Kubernetes readiness probe pointed at it keeps routing traffic to a platform that cannot serve a single authenticated request. If you deploy with `REDIS`, set `management.health.redis.enabled: true` so the Redis indicator participates in the health verdict, and do not rely on a bare `/actuator/health` probe alone to detect a session-store outage.
{% endhint %}

#### Required and optional connection keys (Spring Boot 3.x — `spring.data.redis.*`)

* `spring.data.redis.host`: Redis host. Defaults to `localhost`.
* `spring.data.redis.port`: Redis port. Defaults to `6379`.
* `spring.data.redis.username`: Redis ACL username. Optional; omit for password-only or no-auth Redis.
* `spring.data.redis.password`: Redis password. Optional but recommended for any production deployment.
* `spring.data.redis.database`: Redis logical database index. Defaults to `0`.
* `spring.data.redis.ssl.enabled`: enable TLS for the Redis connection. Boolean, defaults to `false`. Set to `true` for any managed-Redis or TLS-terminated Redis deployment.
* `spring.data.redis.timeout`: command timeout. Duration string (for example `5s`). Defaults to Spring Data Redis's internal default.
* `spring.data.redis.lettuce.pool.*`: Lettuce connection-pool sizing (`max-active`, `max-idle`, `min-idle`, `max-wait`). Optional; tune for high-concurrency deployments.

ODD Platform does not extend or override Spring Boot's Redis property catalogue — the full set of keys recognized under `spring.data.redis.*` in your Spring Boot version applies as-is.

{% tabs %}
{% tab title="YAML" %}

```yaml
session:
  provider: REDIS
spring:
  data:
    redis:
      host: redis.your-domain.com
      port: 6380
      username: odd-platform
      password: ${REDIS_PASSWORD}
      database: 0
      ssl:
        enabled: true
      timeout: 5s
```

{% endtab %}

{% tab title="Environment variables" %}

```
SESSION_PROVIDER=REDIS
SPRING_DATA_REDIS_HOST=redis.your-domain.com
SPRING_DATA_REDIS_PORT=6380
SPRING_DATA_REDIS_USERNAME=odd-platform
SPRING_DATA_REDIS_PASSWORD=...
SPRING_DATA_REDIS_DATABASE=0
SPRING_DATA_REDIS_SSL_ENABLED=true
SPRING_DATA_REDIS_TIMEOUT=5s
```

{% endtab %}
{% endtabs %}

{% hint style="warning" %}
**`spring.redis.*` (the Spring Boot 2.x prefix) is silently ignored.** Spring Boot 3.x removed the `spring.redis.*` namespace and relocated all Redis properties under `spring.data.redis.*`. Configuration written against the older prefix will not bind, the platform falls back to `localhost:6379` defaults, and the symptom is connection failures against your real Redis instance with no obvious "wrong key" error. Migrate any pre-3.x configuration to `spring.data.redis.*` (and `SPRING_DATA_REDIS_*` for env vars).
{% endhint %}

### Session lifetime (`spring.session.timeout`)

Spring Session's timeout controls how long an authenticated session remains valid between requests. ODD Platform's shipped default is `-1`, which means **sessions never expire**.

{% hint style="warning" %}
**`spring.session.timeout: -1` means sessions never expire.** A user who logs in once remains authenticated until their session record is explicitly invalidated (logout, cache eviction, or — for `IN_MEMORY` — platform restart). For any deployment that is internet-facing or serves multiple users, set `spring.session.timeout` to a finite duration so stolen cookies and forgotten sessions eventually lapse.
{% endhint %}

* `spring.session.timeout`: session idle timeout. Duration string (for example `30m`, `8h`, `1d`). Defaults to `-1` (no timeout). Applies to all three providers (`IN_MEMORY`, `INTERNAL_POSTGRESQL`, `REDIS`).

{% tabs %}
{% tab title="YAML" %}

```yaml
spring:
    session:
        timeout: 30m
```

{% endtab %}

{% tab title="Environment variables" %}

```
SPRING_SESSION_TIMEOUT=30m
```

{% endtab %}
{% endtabs %}

### Cookie attributes (`Secure`, `SameSite`, `HttpOnly`)

ODD Platform does **not** stamp `Secure`, `SameSite`, or `HttpOnly` attributes on the session cookie at the application tier — there is no `CookieWebSessionIdResolver` bean in the platform's session configuration today. The browser-side cookie posture is whatever Spring's default `SESSION` cookie defaults are (no `Secure`, no `SameSite` directive, `HttpOnly` set), which is unsuitable for any internet-facing deployment.

Operators **must** stamp the production attributes at the deployment topology layer — typically the TLS-terminating reverse proxy or load balancer. For nginx, the directive looks like:

```nginx
location / {
    proxy_pass http://odd-platform:8080;
    proxy_cookie_path / "/; Secure; HttpOnly; SameSite=Strict";
}
```

Match the equivalent for your ingress controller (Traefik, Envoy, Cloud Load Balancer, etc.). Until a platform-side default-stamping bean ships upstream, this stamping is the operator's responsibility — running ODD over plain HTTP or behind a permissive proxy means the session cookie travels in clear and is vulnerable to cross-site-request and cookie-leak attacks regardless of which `auth.type` is configured.

### Java-serialised session attributes under `INTERNAL_POSTGRESQL`

The `INTERNAL_POSTGRESQL` provider stores session attribute values as raw bytes produced by Java's native `SerializationUtils.serialize` / `.deserialize`. Java native serialisation has a well-known deserialisation-gadget surface — code paths reachable on attribute load are influenced by the byte stream, so a write-access compromise of the `SPRING_SESSION_ATTRIBUTES` table yields a deserialisation entry point on the next session read.

Defence-in-depth recommendations for deployments running `INTERNAL_POSTGRESQL`:

* Restrict write access to the `SPRING_SESSION_ATTRIBUTES` table to a single platform service account; do not share database credentials with other applications that store data in the same Postgres instance.
* Deploy the platform's PostgreSQL with strong network segmentation — the database should not be reachable from any service except the platform itself.
* If you cannot guarantee write-access isolation, prefer the `REDIS` provider — Spring Session's Redis serialiser uses a string-key Jackson JSON serialiser rather than Java native serialisation.

A platform-side migration to JSON serialisation for session attributes is tracked upstream.

## Enable Metrics

ODD Platform can represent some of the metadata it ingests as time-series charts — for example, row counts on a MySQL table or the on-disk size of a Redshift database. Metrics handling splits into two independent concerns that share the `metrics.*` config namespace but do different jobs:

* **Storage** (`metrics.storage`) — the storage tier the platform uses for ingested metrics. This selects where the platform **writes** metric points as they arrive from collectors **and** where it **reads them back** when rendering UI charts. Both directions hit the same backend — you cannot write to one and read from another.
* **Export** (`metrics.export.*`) — where the platform **pushes metrics out** as OpenTelemetry telemetry, for long-term retention and dashboarding in your observability stack.

Configure the two independently; it is valid (and common) to run with `INTERNAL_POSTGRES` storage and no OTLP export, or with `PROMETHEUS` storage and OTLP export disabled, or any other combination.

### Metric storage backend

`metrics.storage` selects the storage tier for metric writes and reads:

* `INTERNAL_POSTGRES` (default) — metrics are **written to and read from** the ODD Platform's own PostgreSQL database (`metric_series` / `metric_point` tables). Zero additional infrastructure; suitable for most single-cluster deployments.
* `PROMETHEUS` — metrics are **remote-written to** an external Prometheus instance (via the [Prometheus remote-write protocol](https://prometheus.io/docs/specs/remote_write_spec/) at `/api/v1/write`, using Snappy-compressed Protobuf-encoded write requests) **and queried from** the same instance (via the [instant-query API](https://prometheus.io/docs/prometheus/latest/querying/api/#instant-queries) at `/api/v1/query`). Suitable when you already run Prometheus for observability and want to avoid storing duplicate metric data in ODD's PostgreSQL.

`metrics.prometheus-host` is the base URL of the Prometheus instance and is only consulted when `metrics.storage=PROMETHEUS`. Both `/api/v1/write` and `/api/v1/query` are called on this single host. Defaults to `http://localhost:9090`.

{% hint style="warning" %}
**`metrics.storage=PROMETHEUS` requires `metrics.prometheus-host` to be set.** The platform validates this at startup — if `metrics.prometheus-host` is empty (or unset) while `metrics.storage=PROMETHEUS`, ODD Platform fails to start with `IllegalStateException: Prometheus host is not defined`. Set it to the Prometheus base URL (for example `http://prometheus:9090`) in the same configuration change that flips the storage backend.
{% endhint %}

{% hint style="warning" %}
**The Prometheus instance must accept remote-write AND queries on the same endpoint.** ODD Platform does not support splitting read and write paths across different hosts.

* **Prometheus server flag** — `--web.enable-remote-write-receiver` must be enabled on the Prometheus process. It is **disabled by default** in Prometheus v2.33+; without it, every ODD Platform metric write returns `404 Not Found` and is silently dropped. The ingestion API still returns `200` to the collector because the remote-write happens downstream of the HTTP acknowledgement, so collector logs will not surface the failure — the symptom is empty charts in the UI.
* **Endpoint must support both paths** — `POST /api/v1/write` (for writes) and `GET /api/v1/query` (for reads) must both resolve to the same Prometheus-compatible host.
* **Read-only Prometheus-compatible backends do not work.** A [Thanos](https://thanos.io/) querier, [Mimir](https://grafana.com/oss/mimir/) in query-only mode, or any other backend that exposes `/api/v1/query` but rejects `/api/v1/write` cannot be used as a `metrics.storage=PROMETHEUS` target. Point `metrics.prometheus-host` at the write-accepting Prometheus instance itself (or at a Mimir distributor that terminates both paths).
  {% endhint %}

{% tabs %}
{% tab title="YAML" %}

```yaml
metrics:
    storage: PROMETHEUS        # INTERNAL_POSTGRES (default) or PROMETHEUS
    prometheus-host: http://prometheus:9090
```

{% endtab %}

{% tab title="Environment variables" %}

```
METRICS_STORAGE=PROMETHEUS
METRICS_PROMETHEUS_HOST=http://prometheus:9090
```

{% endtab %}
{% endtabs %}

{% hint style="danger" %}
**Multi-tenant deployments cannot share an `INTERNAL_POSTGRES` instance — the default backend has no tenant column.** The `odd.tenant-id` configuration is **only** appended to Prometheus series (see [Prometheus tenant label](#prometheus-tenant-label-odd-tenant-id) below); on `INTERNAL_POSTGRES` the metric tables (`metric_series`, `metric_point`, `metric_entity`) have no `tenant_id` column at all. Two ODD Platform deployments writing to the same Postgres instance see each other's metrics on every entity's Metrics tab — there is no platform-side filter. If your deployment needs metric isolation across tenants, choose `PROMETHEUS` storage and configure `odd.tenant-id` per deployment, or run each deployment against its own Postgres instance / schema. The same class of silent-default risk that previously affected attachment storage on container restart applies here. The operator-facing framing of this caveat — including the workflow guidance for choosing between the two backends — is on [Active platform features → Metrics Ingestion](/features/active-platform-features/metrics-ingestion#known-operator-caveats).
{% endhint %}

{% hint style="warning" %}
**Switching `metrics.storage` after a deployment has been live is one-way — historical metric data does not migrate.** The two storage backends are independent stores; the platform writes to whichever is configured and reads from the same one. After a switch (either direction), the previously-stored history remains in the old backend but is **no longer queryable from the platform UI or API**. Plan storage-backend changes as one-time cutovers and annotate the cutover date in your runbook — the Metrics tab on each entity will show no data older than the switch. Operator-facing framing on [Active platform features → Metrics Ingestion](/features/active-platform-features/metrics-ingestion#known-operator-caveats).
{% endhint %}

### Metric export to OTLP

Independent of where metrics are stored, ODD Platform can push metrics as OpenTelemetry telemetry to an [OTLP collector](https://opentelemetry.io/docs/collector/). Downstream you can forward that stream to [Prometheus](https://prometheus.io/), [New Relic](https://newrelic.com/), or any backend that accepts [OTLP exporters](https://aws-otel.github.io/docs/components/otlp-exporter).

* `metrics.export.enabled`: must be set to `true` to build and wire the OTLP exporter bean. Defaults to `false`.
* `metrics.export.otlp-endpoint`: OTLP collector endpoint (gRPC). Defaults to `http://localhost:4317`.

{% tabs %}
{% tab title="YAML" %}

```yaml
metrics:
    export:
        enabled: true
        otlp-endpoint: {otlp-endpoint-url}
```

{% endtab %}

{% tab title="Environment variables" %}

```
METRICS_EXPORT_ENABLED=true
METRICS_EXPORT_OTLP_ENDPOINT={otlp-endpoint-url}
```

{% endtab %}
{% endtabs %}

## Enable Alert Notifications

Any alert that is created inside the platform can be sent via webhook and/or [Slack incoming webhook](https://docs.slack.dev/messaging/sending-messages-using-incoming-webhooks) and/or email notifications (via [Google SMTP](https://support.google.com/a/answer/176600?hl=en), [AWS SMTP](https://repost.aws/knowledge-center/ses-set-up-connect-smtp), etc). Such notifications contain information such as:

1. Name of the entity upon which alert has been created
2. Data source and namespace of an entity
3. Owners of an entity
4. Possibly affected entities

ODD Platform's outbound notification delivery tails the `alert` table through a PostgreSQL logical-replication slot. Because the slot durably tracks its position in the write-ahead log, delivery resumes from the last unprocessed alert after a platform restart or a transient interruption of the database connection — alerts raised during the downtime are delivered once delivery catches up, not dropped. Alert *creation* itself is a plain database insert and does not depend on replication; this prerequisite applies only to outbound notification delivery. To enable it, the underlying PostgreSQL database must be configured for logical replication.

For the user-facing description of the alerting feature — alert types, the per-entity alert tabs, the lifecycle, and per-entity halt configuration — see [Active platform features → Alerting](/features/active-platform-features/alerting). For the user-facing description of the outbound notification channels (Slack incoming webhook, email, generic webhook) and the Prometheus AlertManager inbound webhook, see [Active platform features → Notifications](/features/active-platform-features/notifications).

{% hint style="info" %}
**Slack here is the outgoing alert webhook, not the Discussions Slack app.** The alert-notifications integration is a one-way [Slack incoming webhook](https://docs.slack.dev/messaging/sending-messages-using-incoming-webhooks) — the platform POSTs alert messages to a channel via `notifications.receivers.slack.url`. It is **distinct** from the [full Slack app](#enable-data-collaboration) used by Data Collaboration for in-app per-entity discussion threads (OAuth + Events API; bidirectional). Each integration is configured separately: enabling the alert webhook does not surface the **Discussions** tab on data-entity pages, and enabling Data Collaboration does not route alerts. See [Main Concepts → Terms & Aliases](/introduction/main-concepts#terms-and-aliases) for the side-by-side comparison.
{% endhint %}

### PostgreSQL Configuration

PostgreSQL database must be [configured](https://www.postgresql.org/docs/current/config-setting.html) in order to leverage the replication mechanism of the Platform along with the granting the database user replication permissions.

#### Database settings

To configure the database, add the following entries to the `postgresql.conf` file:

```
max_wal_senders = 1
wal_keep_size = 16
wal_level = logical
max_replication_slots = 1
```

Or if the replication mechanism is already configured, just increment the `max_wal_senders` and `max_replication_slots` numbers.

#### Database user permissions

ODD Platform database user must be granted with replication permissions:

```sql
ALTER ROLE {database_username} WITH REPLICATION
```

{% hint style="info" %}
User permissions and database configuration may vary from one on-demand/cloud provider to another.

For instance, In AWS RDS, PostgreSQL instances are managed services where certain aspects of replication management are automated. This is done to minimize the risk of misconfiguration. Due to this managed nature, some settings are either not exposed or are altered differently compared to a standard PostgreSQL setup. To enable notifications in such an environment, follow these steps (only differences are mentioned): 1. Alter the `rds.logical_replication` parameter in your database instance's Parameter Group by setting it to `1`, instead of directly modifying the `wal_level` parameter. 2. Ensure the ODD user connecting to the database has the `rds_replication` role. The Master username of the database typically already has this role by default. If using a different username, you may need to assign the necessary role using the command `GRANT rds_replication TO {your_database_username}; 3.`If you changed max\_wal\_senders to 5 (as it's mentioned as a minimal value in Parameter Group) and then constantly getting messages like "The parameter max\_wal\_senders was set to a value incompatible with replication. It has been adjusted from 5 to 55" in the events list of the database instance, please, consider adjusting the parameter from 5 to the mentioned value in the parameter group to exclude automatic change done by RDS.
{% endhint %}

### ODD Platform configuration

Following variables need to be defined:

* `notifications.enabled`: must be set to `true`. Defaults to `false`. **Feature toggling**: this value is captured at JVM boot and frozen for the lifetime of the process; restart the JVM for a change to take effect. The same boot-immutable pattern applies to every platform-feature flag in this document — see [Features → Data Collaboration](/features/features#data-collaboration) for the catalogue and the chrome-invariance framing.
* `notifications.message.downstream-entities-depth`: limits the amount of fetching of affected data entities **in terms of lineage graph level.** Defaults to 1
* `notifications.wal.advisory-lock-id`: ODD Platform uses [PostgreSQL advisory lock](https://www.postgresql.org/docs/current/explicit-locking.html#ADVISORY-LOCKS) in order to make sure that in a case of horizontal scaling only one instance of the Platform processes alert messages. This setting defines advisory lock id. Defaults to `100`
* `notifications.wal.replication-slot-name`: PostgreSQL replication slot name will be created if it doesn't exist yet. Defaults to `odd_platform_replication_slot`
* `notifications.wal.publication-name`: PostgreSQL publication name will be created if it doesn't exist yet. Defaults to `odd_platform_publication_alert`
* `notifications.receivers.slack.url`: [Slack incoming webhook](https://docs.slack.dev/messaging/sending-messages-using-incoming-webhooks) URL. The clickable links rendered inside Slack messages use [`odd.platform-base-url`](#odd-platform-base-url) — there is **no** `notifications.receivers.slack.*` base-URL setting.
* `notifications.receivers.webhook.url`: Generic webhook URL
* `notifications.receivers.email.host`: the SMTP server.
* `notifications.receivers.email.port`: the port used for the email protocol (SMTP, IMAP, or POP3)
* `notifications.receivers.email.protocol`: the email transport protocol. **Use the lowercase value `smtp`** — any other value (including uppercase `SMTP`) silently disables STARTTLS and SMTP AUTH; see the caveat below.
* `notifications.receivers.email.smtp.auth`: a boolean value (true or false) indicating whether the SMTP server requires authentication
* `notifications.receivers.email.smtp.starttls`: a boolean indicating whether to use STARTTLS, a security protocol that upgrades an unencrypted connection to an encrypted one
* `notifications.receivers.email.password`: the password used for email authentication
* `notifications.receivers.email.sender`: the email address sending the notifications
* `notifications.receivers.email.notification.emails`: the list of recipients for the email notifications

{% hint style="warning" %}
**A generic-webhook receiver must respond `HTTP 200` — `201` / `202` / `204` are treated as a delivery failure and the alert is dropped.** The platform's webhook sender treats any response status other than exactly `200 OK` as a failed delivery, so a receiver that returns `202 Accepted` (a common async-ingest convention) silently loses alerts with no operator-visible cause. Configure the endpoint behind `notifications.receivers.webhook.url` to return `200` on accept.
{% endhint %}

{% hint style="warning" %}
**The email `protocol` value must be the lowercase string `smtp` for STARTTLS and SMTP AUTH to engage.** The platform sets `mail.smtp.auth` and `mail.smtp.starttls.enable` only when `notifications.receivers.email.protocol` equals `smtp` exactly. Any other value — including uppercase `SMTP` — takes a fall-through branch that sets neither, so authentication and STARTTLS never engage and credentials can transit unauthenticated and unencrypted, with no boot warning. Always configure `protocol: smtp` (lowercase).
{% endhint %}

#### `odd.platform-base-url`

ODD Platform URL exposed to **three** internal consumers — the Slack-notification sender, the email-notification sender, and the integration-parameter substitution context. The two notification senders use it to build clickable links inside alert messages (the generic webhook receiver does **not** consume this key — it gets the full alert payload directly and is expected to construct any URLs it needs from that payload). The platform also substitutes the resolved value as the `platform_url` parameter in integration configurations — this is how Airflow plugins, dbt artifacts, and similar integrations resolve their reference to the ODD platform URL at runtime. **Defaults are inconsistent across consumers**: the notification senders default to `http://localhost:8080`, while the integration-substitution context defaults to the placeholder string `http://your.odd.platform`. Both defaults are unreachable from outside the host machine; set this key to your real deployment URL (for example `https://odd.your-domain.com`) in any non-local environment.

{% hint style="warning" %}
**Operators deploying integrations must set `ODD_PLATFORM_BASE_URL` even if alert notifications are disabled.** The integration-parameter substitution context reads the same key to populate the `platform_url` parameter exposed to integration configurations. If the key is unset, integrations that reference `platform_url` receive the literal string `http://your.odd.platform` — a placeholder that will not connect to anything — and the integration will fail in confusing ways at runtime with no error from ODD Platform itself.
{% endhint %}

ODD Platform configuration would look like this:

{% tabs %}
{% tab title="YAML" %}

```yaml
notifications:
  enabled: true
  message:
    downstream-entities-depth: {downstream_entities_depth_to_fetch}
  wal:
    advisory-lock-id: {postgresql_advisory_lock_id}
    replication-slot-name: {postgresql_replication_slot_name}
    publication-name: {postgresql_publication_name}
  receivers:
    slack:
      url: {slack_incoming_webhook_url}
    webhook:
      url: {webhook_url}
    email: 
      host: {host} 
      port: {port}
      protocol: {protocol}  # SMTP, SMTPS, IMAP, IMAPS, POP3, POP3S 
      smtp: 
        auth: true # Set to true if SMTP server requires authentication 
        starttls: true # Set to true to enable STARTTLS 
      password: {email_password}
      sender: {sender_email} 
      notification: 
        emails: {1@mail.com,2@mail.com}   
odd:
  platform-base-url: {platform_url}
```

{% endtab %}

{% tab title="Environment variables" %}

```
NOTIFICATIONS_ENABLED=true
NOTIFICATIONS_MESSAGE_DOWNSTREAM_ENTITIES_DEPTH={downstream_entities_depth_to_fetch}
NOTIFICATIONS_WAL_ADVISORY_LOCK_ID={postgresql_advisory_lock_id}
NOTIFICATIONS_WAL_REPLICATION_SLOT_NAME={postgresql_replication_slot_name}
NOTIFICATIONS_WAL_PUBLICATION_NAME={postgresql_publication_name}
NOTIFICATIONS_RECEIVERS_SLACK_URL={slack_incoming_webhook_url}
NOTIFICATIONS_RECEIVERS_WEBHOOK_URL={webhook_url}
NOTIFICATIONS_RECEIVERS_EMAIL_HOST={host}
NOTIFICATIONS_RECEIVERS_EMAIL_PORT={port}
NOTIFICATIONS_RECEIVERS_EMAIL_PROTOCOL={protocol} # SMTP, SMTPS, IMAP, IMAPS, POP3, POP3S
NOTIFICATIONS_RECEIVERS_EMAIL_SMTP_AUTH=true      # Set to true if SMTP server requires authentication
NOTIFICATIONS_RECEIVERS_EMAIL_SMTP_STARTTLS=true  # Set to true to enable STARTTLS
NOTIFICATIONS_RECEIVERS_EMAIL_PASSWORD={email_password}
NOTIFICATIONS_RECEIVERS_EMAIL_SENDER={sender_email}
NOTIFICATIONS_RECEIVERS_EMAIL_NOTIFICATION_EMAILS={1@mail.com,2@mail.com}
ODD_PLATFORM_BASE_URL={platform_url}
```

{% endtab %}
{% endtabs %}

### Example: Gmail SMTP

A minimal, working configuration for Gmail's SMTP over STARTTLS. Gmail requires an [**app password**](https://support.google.com/accounts/answer/185833) (generated from your Google account with 2-Step Verification enabled) — your regular account password will not work.

{% tabs %}
{% tab title="YAML" %}

```yaml
notifications:
  enabled: true
  wal:
    advisory-lock-id: 100
    replication-slot-name: odd_platform_replication_slot
    publication-name: odd_platform_publication_alert
  receivers:
    email:
      host: smtp.gmail.com
      port: 587
      protocol: SMTP
      smtp:
        auth: true
        starttls: true
      sender: odd-alerts@your-domain.com
      password: {gmail_app_password}
      notification:
        emails: ops@your-domain.com,data-team@your-domain.com
odd:
  platform-base-url: https://odd.your-domain.com
```

{% endtab %}

{% tab title="Environment variables" %}

```
NOTIFICATIONS_ENABLED=true
NOTIFICATIONS_WAL_ADVISORY_LOCK_ID=100
NOTIFICATIONS_WAL_REPLICATION_SLOT_NAME=odd_platform_replication_slot
NOTIFICATIONS_WAL_PUBLICATION_NAME=odd_platform_publication_alert
NOTIFICATIONS_RECEIVERS_EMAIL_HOST=smtp.gmail.com
NOTIFICATIONS_RECEIVERS_EMAIL_PORT=587
NOTIFICATIONS_RECEIVERS_EMAIL_PROTOCOL=SMTP
NOTIFICATIONS_RECEIVERS_EMAIL_SMTP_AUTH=true
NOTIFICATIONS_RECEIVERS_EMAIL_SMTP_STARTTLS=true
NOTIFICATIONS_RECEIVERS_EMAIL_SENDER=odd-alerts@your-domain.com
NOTIFICATIONS_RECEIVERS_EMAIL_PASSWORD={gmail_app_password}
NOTIFICATIONS_RECEIVERS_EMAIL_NOTIFICATION_EMAILS=ops@your-domain.com,data-team@your-domain.com
ODD_PLATFORM_BASE_URL=https://odd.your-domain.com
```

{% endtab %}
{% endtabs %}

### Known limitations

ODD Platform builds its `JavaMailSender` with only the keys documented above. The JavaMail session inherits defaults for every other SMTP parameter, and several of those defaults are operator-hostile in production deployments. None of the following is currently exposed as an ODD configuration key — where a workaround exists it is noted, but the limitations are real and should drive your choice of SMTP relay.

{% hint style="warning" %}
**SMTP timeouts are unset — an unreachable SMTP server will hang notification delivery.** The JavaMail defaults for `mail.smtp.connectiontimeout`, `mail.smtp.timeout` (read), and `mail.smtp.writetimeout` are **infinite**. If the configured SMTP host is unreachable, slow, or stalls mid-response, the notification thread blocks until the TCP stack eventually tears the connection down — there is no application-level timeout to cut it short. Use an SMTP relay you control (or a trusted managed service) and monitor its availability separately from ODD Platform.
{% endhint %}

{% hint style="warning" %}
**Only STARTTLS is supported — implicit-TLS ports (e.g. Gmail port 465, many corporate relays) will not work.** ODD Platform exposes `notifications.receivers.email.smtp.starttls` but does not expose `mail.smtp.ssl.enable`, which is the JavaMail flag required to open an implicit-TLS connection. If your SMTP server only accepts connections on an implicit-TLS port, you must front it with a STARTTLS-capable relay (port 587 is the common choice). Gmail over port 587 with STARTTLS (the example above) works; Gmail over port 465 does not.
{% endhint %}

{% hint style="warning" %}
**Self-signed or internal-CA SMTP certificates require a JVM-level workaround.** `mail.smtp.ssl.trust` is not exposed as an ODD configuration key. If your SMTP relay presents a certificate signed by a private CA, the connection will fail certificate validation unless you either (a) add the CA to the JVM truststore of the ODD Platform container (`$JAVA_HOME/lib/security/cacerts` or a `-Djavax.net.ssl.trustStore=...` override) before starting the process, or (b) use an SMTP relay with a publicly-trusted certificate. There is no configuration-file path to this.
{% endhint %}

{% hint style="warning" %}
**Non-ASCII subjects and bodies may be mangled.** The MIME message is built without an explicit charset, so JavaMail falls back to the JVM default. Containers that do not set `file.encoding` or `LANG` explicitly can end up with `US-ASCII` defaults, which corrupt non-Latin alert content. If your alert text includes non-ASCII characters, set `JAVA_TOOL_OPTIONS=-Dfile.encoding=UTF-8` on the ODD Platform container.
{% endhint %}

{% hint style="danger" %}
**Silent partial delivery: if one recipient fails, subsequent recipients are skipped.** `EmailNotificationSender` iterates over the recipient list in `notifications.receivers.email.notification.emails` and calls the SMTP server once per recipient. If recipient N fails (bad address, mailbox full, server-side policy rejection), the exception is wrapped as a `RuntimeException` and the loop terminates — recipients N+1, N+2, … **never receive the alert**. There is no retry and no partial-failure metric. Keep the recipient list short, use distribution lists on the SMTP side for fan-out, and validate addresses before adding them to the list.
{% endhint %}

### Cleaning up

{% hint style="danger" %}
ODD Platform **doesn't clean up** replication slot it has created. If you need to disable Alert Notification functionality, please perform the following steps along with disabling a feature on a ODD Platform side
{% endhint %}

In order to remove replication slot and publication, these SQL queries must be run against the database:

* ```sql
  SELECT pg_drop_replication_slot('<>');
  ```

  where `<>` is a name of replication slot defined in the ODD Platform. Default is `odd_platform_replication_slot`
* ```sql
  DROP PUBLICATION IF EXISTS <>;
  ```

  where `<>` is a name of publication defined in the ODD Platform. Default is `odd_platform_publication_alert`

## Prometheus AlertManager Integration

In addition to raising alerts internally (failed jobs, data-quality tests, schema changes, distribution anomalies — see the [Alerting](/features/active-platform-features/alerting) feature), ODD Platform exposes an **inbound webhook** that accepts Prometheus [AlertManager](https://prometheus.io/docs/alerting/latest/alertmanager/) notifications. Each inbound alert becomes a **Distribution Anomaly** alert on the referenced data entity, visible in the Alerts section and on the entity's page.

### Endpoint

```
POST /ingestion/alert/alertmanager
```

Response: `204 No Content` on success. The endpoint consumes the AlertManager webhook body and always returns empty.

### Authentication

The webhook lands on `/ingestion/alert/alertmanager`, part of the `/ingestion/**` surface.

* **By default (`auth.ingestion.filter.enabled=false`) it is unauthenticated** — gated only by network reachability. Any caller that can reach the endpoint can post AlertManager-shaped bodies and raise Distribution Anomaly alerts on any entity whose ODDRN they supply. On a network-reachable deployment, apply perimeter controls (network segmentation, an authenticating reverse proxy, mTLS).
* **From 0.29.0, `auth.ingestion.filter.enabled=true` requires a token** on this webhook like every other ingestion route ([ADR-0079](/developer-guides/architecture-decision-log/adr-0079-ingestion-authentication-filter-coverage)). Configure AlertManager to send a registered collector/datasource token via its [`http_config`](https://prometheus.io/docs/alerting/latest/configuration/#http_config):

```yaml
receivers:
  - name: odd-platform
    webhook_configs:
      - url: https://odd-platform.example.com/ingestion/alert/alertmanager
        http_config:
          authorization:
            type: Bearer
            credentials: <a registered collector or datasource token>
```

See the [Enable security deployment matrix](/configuration-and-deployment/enable-security#deployment-matrix-per-endpoint-per-auth-config) for the per-`auth.type` picture.

### Payload shape

The platform accepts a subset of the [AlertManager webhook schema](https://prometheus.io/docs/alerting/latest/configuration/#webhook_config) — specifically `alerts[].labels`, `alerts[].generatorURL`, and `alerts[].startsAt`. Other top-level AlertManager fields (`version`, `status`, `receiver`, `groupLabels`, `commonLabels`, …) are accepted and ignored.

```json
{
  "alerts": [
    {
      "labels": {
        "entity_oddrn": "//postgresql/host/pg-host/databases/shop/schemas/public/tables/orders",
        "alertname": "OrdersRowCountDropped"
      },
      "generatorURL": "https://prometheus.example.com/graph?g0.expr=...",
      "startsAt": "2026-04-24T12:34:56"
    }
  ]
}
```

{% hint style="warning" %}
**The `entity_oddrn` label is required for the alert to route to a data entity.** ODD Platform reads `alerts[].labels["entity_oddrn"]` to determine which data entity the alert belongs to. An alert submitted without this label is stored with an empty owner, will not appear on any entity's page, and is effectively orphaned. Configure your AlertManager route or your alerting rules to include the target entity's ODDRN as a label.
{% endhint %}

### Example AlertManager receiver configuration

A minimal `alertmanager.yml` receiver forwarding every alert to ODD Platform:

```yaml
route:
  group_by: ['job']
  group_wait: 1s
  group_interval: 5m
  repeat_interval: 12h
  receiver: odd-platform
receivers:
  - name: odd-platform
    webhook_configs:
      - url: 'http://odd-platform:8080/ingestion/alert/alertmanager'
```

The reference example shipped with the platform is at [`docker/examples/config/alertmanager.yaml`](https://github.com/opendatadiscovery/odd-platform/blob/main/docker/examples/config/alertmanager.yaml) in the odd-platform repo. To make an alert route to a specific entity, attach `entity_oddrn` as a label in your Prometheus alerting rules — for example:

```yaml
groups:
  - name: orders
    rules:
      - alert: OrdersRowCountDropped
        expr: row_count{table="orders"} < 1000
        labels:
          entity_oddrn: "//postgresql/host/pg-host/databases/shop/schemas/public/tables/orders"
        annotations:
          summary: "Orders table row count dropped below 1000"
```

### Authentication

{% hint style="danger" %}
**The AlertManager webhook endpoint is not authenticated.** ODD Platform whitelists the entire `/ingestion/**` namespace in Spring Security, and the ingestion auth filter controlled by `auth.ingestion.filter.enabled` only guards `/ingestion/entities` (POST) — it does **not** cover `/ingestion/alert/alertmanager`. Anyone with network reach to the platform can POST arbitrary AlertManager-shaped payloads and create alerts on any data entity whose ODDRN they can guess. Toggling `auth.ingestion.filter.enabled` has no effect on this endpoint.
{% endhint %}

Because no application-level authentication is enforced on this endpoint today, protect it at the perimeter. Any of these approaches works:

* **Network segmentation** — expose ODD Platform only on a private network or VPN; in Kubernetes, keep AlertManager and the platform in the same cluster and use a NetworkPolicy so only the AlertManager pod can reach `/ingestion/alert/alertmanager`.
* **Reverse proxy with its own authentication** — put an authenticating proxy in front of ODD Platform (for example, nginx with `auth_request` delegating to an SSO sidecar, or Envoy with `ext_authz`) and require AlertManager to present a proxy-validated credential on every webhook call.
* **mTLS termination** — require client certificates on `/ingestion/alert/alertmanager` at the ingress or load balancer layer, and issue a certificate only to the AlertManager pod.

A platform-side fix to extend the ingestion auth filter to cover this endpoint is tracked upstream. Until it ships, apply one of the perimeter controls above for any deployment where the platform's network is not fully trusted.

For the broader ingestion-auth model — what `auth.ingestion.filter.enabled` does cover, the [per-endpoint deployment matrix](/configuration-and-deployment/enable-security#deployment-matrix-per-endpoint-per-auth-config) showing reachability under each `auth.type` value, and the write-shape caveats on the [statistics endpoint](/configuration-and-deployment/enable-security#statistics-endpoint-write-shape-and-replay-behaviour) — see [Enable security](/configuration-and-deployment/enable-security) and [Server-to-server (S2S) API keys](/configuration-and-deployment/enable-security/authentication/s2s).

## Enable Data Collaboration

Data collaboration feature allows users to initiate discussion about specific data entity in messengers directly from the ODD Platform. Thread replies are tracked by ODD Platform and saved in it, allowing users to retrieve conversation's context and decisions from one place.

For the user-facing description of the feature — the per-entity **Discussions** tab, how a discussion flows from the platform out to Slack and back, the message-lifecycle model — see [Active platform features → Data Collaboration](/features/active-platform-features/data-collaboration).

At the moment ODD Platform supports only Slack as a target messenger. It uses Slack APIs to send messages and [Slack Events API](https://docs.slack.dev/apis/events-api/) to receive message's thread replies.

{% hint style="info" %}
**Slack here is the full Slack app for in-app discussions, not the alert webhook.** The Data Collaboration integration uses an OAuth-token-driven Slack app (`datacollaboration.slack-oauth-token`) and the [Slack Events API](https://docs.slack.dev/apis/events-api/) webhook to read replies back into the platform — bidirectional. It is **distinct** from the [outgoing alert webhook](#enable-alert-notifications) used by alert notifications (`notifications.receivers.slack.url`, one-way write only). Each integration is configured separately: enabling this one does not route alerts, and enabling the alert webhook does not surface the **Discussions** tab on data-entity pages. See [Main Concepts → Terms & Aliases](/introduction/main-concepts#terms-and-aliases) for the side-by-side comparison.
{% endhint %}

### Creating Slack application

Go to the [Slack apps](https://api.slack.com/apps) website and click on `Create New App -> From an app manifest`

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-11d270ac3d6302cd98594943c746ba17fe42033b%2Fimage.png?alt=media" alt=""><figcaption><p>Creating an app</p></figcaption></figure>

Select a workspace you want to add an application to and click `Next`

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-f2496b2b43d1be3b005c76bdc2dec8a147c0de1b%2Fimage.png?alt=media" alt=""><figcaption><p>Selecting a workspace to install application to</p></figcaption></figure>

Enter the following manifest into the YAML section, replace the `<ODD_PLATFORM_BASE_URL>` with URL of your ODD Platform deployment and click `Next`.

The four bot scopes below match exactly what the platform exercises today (`channels:history` and `channels:read` for reading messages and metadata, `chat:write` for posting via the OAuth bot token, `users:read` for resolving user display names). Previous versions of this manifest also requested `incoming-webhook` — that scope was copy-paste leftover from a Slack example and was never used by the platform; if you are reinstalling or auditing scopes, you can safely omit it.

```yaml
display_information:
  name: ODD Data Collaboration
features:
  bot_user:
    display_name: ODD Data Collaboration
    always_online: false
oauth_config:
  scopes:
    bot:
      - channels:history
      - channels:read
      - chat:write
      - users:read
settings:
  event_subscriptions:
    request_url: https://<ODD_PLATFORM_BASE_URL>/api/slack/events
    bot_events:
      - message.channels
  org_deploy_enabled: false
  socket_mode_enabled: false
  token_rotation_enabled: false
```

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-5c190d5dec118a72d886c9ac64257ed87d99f053%2Fimage.png?alt=media" alt=""><figcaption><p>Inserting a YAML manifest</p></figcaption></figure>

Review your application's scopes and permissions and click `Create`

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-d513c0e26fa9390e25eaba0ce60a440d75d34b67%2Fimage.png?alt=media" alt=""><figcaption><p>Reviewing scopes and permissions</p></figcaption></figure>

Proceed with Slack instructions on how to install application into workspace and you should be good to go.

### ODD Platform configuration

Following variables need to be defined:

* `datacollaboration.enabled`: must be set to `true`. Defaults to `false`. **Feature toggling**: this value is captured at JVM boot and frozen for the lifetime of the process — runtime configuration changes (for example via Spring Boot Actuator's `/actuator/refresh`) are not reflected by the feature resolver or by the platform's feature-active endpoint. Restart the JVM process for a change to take effect. Top-level UI navigation tabs (Data Modelling and adjacent surfaces) remain visible regardless of this setting; the per-page affordances inside those tabs do honour the flag. See [Features → Data Collaboration](/features/features#data-collaboration) for the chrome-invariance caveat.
* `datacollaboration.receive-event-advisory-lock-id`: PostgreSQL advisory lock id for a job, which translates events from messengers to messages. Defaults to `110`
* `datacollaboration.sender-message-advisory-lock-id`: PostgreSQL advisory lock id for a job, which sends messages created in the platform to messengers. Defaults to `120`
* `datacollaboration.message-partition-period`: time interval in days for a message table partition in PostgreSQL. Defaults to `30`
* `datacollaboration.sending-messages-retry-count`: how many times the Platform will attempt to send a message to provider. Cannot be less than zero. Defaults to `3`
* `datacollaboration.slack-oauth-token`: Slack application OAuth token used for communicating with Slack. Can be retrieved in the `OAuth & Permissions` section of a Slack application.\\

  <figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-dd98ef4f4d854f1d47f5ff5f560925874faa2bad%2Fimage.png?alt=media" alt=""><figcaption><p>Retrieving OAuth Token</p></figcaption></figure>

{% tabs %}
{% tab title="YAML" %}

```yaml
datacollaboration:
  receive-event-advisory-lock-id: {receive_event_advisory_lock_id}
  sender-message-advisory-lock-id: {sender_message_advisory_lock_id}
  message-partition-period: {message_partition_period}
  sending-messages-retry-count: {sending-messages-retry-count}
  enabled: true
  slack-oauth-token: {slack_oauth_token}

odd:
  platform-base-url: {platform_url}
```

{% endtab %}

{% tab title="Environment variables" %}

```
DATACOLLABORATION_ENABLED=true
DATACOLLABORATION_RECEIVE_EVENT_ADVISORY_LOCK_ID={receive_event_advisory_lock_id}
DATACOLLABORATION_SENDER_MESSAGE_ADVISORY_LOCK_ID={sender_message_advisory_lock_id}
DATACOLLABORATION_MESSAGE_PARTITION_PERIOD={message_partition_period}
DATACOLLABORATION_SENDING_MESSAGES_RETRY_COUNT={sending_messages_retry_count}
DATACOLLABORATION_SLACK_OAUTH_TOKEN={slack_oauth_token}
ODD_PLATFORM_BASE_URL={odd_platform_base_url}
```

{% endtab %}
{% endtabs %}

### Known limitations

#### Slack at-least-once delivery surfaces as duplicate messages

Slack's Events API retries an event delivery whenever the platform's `POST /api/slack/events` handler does not return a 2xx acknowledgement within roughly three seconds — the API guarantees at-least-once delivery, not exactly-once. ODD Platform does not currently deduplicate incoming events: the `message_provider_event` table has no `UNIQUE (provider, event_id)` constraint, and the INSERT in `ReactiveMessageRepository.createMessageEvent` issues no `ON CONFLICT` clause. The result is that occasional Slack retries — which happen routinely on transient network or processing delays — insert duplicate rows; the downstream processor materialises a child `message` row for each, so the same Slack reply can appear two or more times on the data-entity **Discussions** tab.

**Operator-side mitigation today.** Until the platform-side dedup ships upstream, audit `message_provider_event` for `(provider, event_id)` duplicates as a one-off clean-up baseline; the duplicate rows are safe to delete after confirming the downstream `message` rows have been similarly deduplicated. Long-term, expect the platform to add the `UNIQUE` constraint + `ON CONFLICT DO NOTHING` on the INSERT — track the upstream issue if you depend on exactly-once delivery.

#### Slack Events webhook has no signature verification

ODD Platform does not verify Slack's `X-Slack-Signature` header on incoming `/api/slack/events` callbacks. Any caller on the network that can reach the platform's events endpoint can submit Slack-shaped payloads and have them processed as if they came from Slack. Restrict network reach to the platform's `/api/slack/events` path to Slack's IP ranges at your reverse proxy, or terminate at a proxy that verifies the signature itself; a platform-side verifier is tracked upstream.

`datacollaboration.message-partition-period` (default `30`) is read by `MessageTablePartitionManager` (`@Value("${datacollaboration.message-partition-period:30}")`) — separate from `DataCollaborationProperties`, which only carries the two advisory-lock IDs and the retry count. The partition manager creates a new PostgreSQL partition for the messages table every N days; lowering the value increases partition churn, raising it reduces partition count but enlarges each partition.

### API surface

The full HTTP API for Data Collaboration is documented at [API Reference → Data Collaboration](/developer-guides/api-reference/data-collaboration) — 7 routes across three groups (outbound to the provider, per-entity threads & history, inbound webhook from Slack), all gated by `@ConditionalOnDataCollaboration` and returning `404 Not Found` when `datacollaboration.enabled=false`.

## Housekeeping Settings Configuration

ODD Platform runs a background **housekeeping job** that permanently deletes stale data on a schedule. The job fires every **15 minutes**, is guarded by a ShedLock so only one platform instance runs it at a time in a multi-instance deployment, and iterates through five cleanup tasks: resolved alerts, search-facet history, soft-deleted data entities, empty `activity` table partitions, and empty `message` table partitions. The first three consume the `housekeeping.ttl.*` keys below; the two partition reapers do not consume any TTL key — they drop empty past partitions when the partition-rotation orchestrator advances the partition window (see [Activity-feed partitioning](#activity-feed-partitioning-odd-activity-partition-period) for the partition WIDTH key, and the [Advisory-lock registry](#advisory-lock-registry) for the orchestrator's leader election).

### Configuration keys

* `housekeeping.enabled`: enables the background job. Defaults to `true`. See the caveat below before disabling.
* `housekeeping.ttl.resolved_alerts_days`: how many days a resolved alert is kept after its status-update timestamp before the housekeeping job permanently deletes it (alongside its chunk records). Applies to **both** `RESOLVED` (manual) and `RESOLVED_AUTOMATICALLY` (system) states — they are retained symmetrically. Integer, days. Defaults to `30`. **Note:** if you supply a partial `housekeeping.ttl` override that omits this key it binds to `0`, which deletes resolved alerts on the next cycle regardless of age — always set it explicitly (the shipped default is `30`). See [Alerting → Auto-cleanup of resolved alerts](/features/active-platform-features/alerting#auto-cleanup-of-resolved-alerts).
* `housekeeping.ttl.search_facets_days`: how many days a saved search-facet entry is kept past its `last_accessed_at` timestamp before being deleted. Integer, days. Defaults to `30`.
* `housekeeping.ttl.data_entity_delete_days`: how many days a data entity with status `DELETED` is kept after its status-update timestamp. After this, the entity and its cascading related rows — metadata values, ownerships, lineage, tags, terms, alerts, messages, metrics, **attachment files (including objects in S3 / MinIO storage)**, task runs, group relations, and (for datasets) dataset structure and enum values — are **permanently and irreversibly deleted** on the next housekeeping cycle, with no restore path. Integer, days. Defaults to `30`. The retention clock is the entity's `status_updated_at` timestamp, which the soft-delete path stamps at the moment the entity is moved to `DELETED` — so the key is honoured exactly as documented; a default install purges `DELETED` entities 30 days after deletion. See [Data entity statuses → soft-delete TTL](/features/data-discovery/statuses#the-soft-delete-ttl) for the user-facing lifecycle (a separate, cosmetic `status_updated_at` mapper defect affects only non-`DELETED` transitions and does not change this retention behaviour).

For the user-facing entity lifecycle (how operators set `DELETED` and the other status states from the UI), see [Data entity statuses](/features/data-discovery/statuses).

{% hint style="warning" %}
**Disabling housekeeping (`housekeeping.enabled: false`) stops all five cleanup jobs.** Resolved alerts, search-facet history, soft-deleted data entities, and empty `activity` / `message` partitions will accumulate indefinitely and the PostgreSQL database will grow without bound. Leave the job enabled in production; disable only for debugging or offline migrations, and re-enable (or run a manual cleanup) afterwards.
{% endhint %}

{% hint style="danger" %}
**The Java-side default for every `housekeeping.ttl.*` key is `0`. A partial-override deployment silently wipes historical data on the next 15-minute cycle.** The shipped `application.yml` supplies `30` for each of the three TTL keys, so a default install behaves as documented. But the `HousekeepingTTLProperties` class declares the fields as `private int` with no field initialiser — Spring binds primitive `int` default `0` if an operator-supplied override (typical Helm-chart values overlay, `--spring.config.location` to a profile that omits the `housekeeping:` block, Spring Cloud Config slice, Kubernetes ConfigMap mount) does not re-supply the block. With `0`, the housekeeping cycle computes `cutoff = now() - 0 days = now()` and deletes every RESOLVED alert + every search-facet entry + every soft-deleted data entity (and cascades through \~25 child tables, including S3 attachments). The platform emits no boot warning, no log line above DEBUG, no Prometheus counter — operators discover the loss only when the data is gone.

**Always re-supply the full `housekeeping:` block in Helm/Kustomize overlays**, OR set explicit non-zero values for every TTL key, AND verify post-restart by sampling `pg_stat_user_tables.n_tup_del` after one cycle. This is the same class of silent-default risk that previously affected attachment storage on container restart — read once, configure explicitly, never trust a partial overlay to inherit the bundled YAML defaults.
{% endhint %}

{% hint style="warning" %}
**Housekeeping deletions are unobservable on a default deployment — no metric, no audit trail, DEBUG-only logs.** The subsystem that permanently deletes data exposes no operational telemetry: there is no metrics counter or gauge for any of the five jobs (nothing housekeeping-related appears at [`/actuator/prometheus`](/configuration-and-deployment/health-and-monitoring#prometheus-metrics)), no structured audit event records what was deleted and when, and every per-job deletion count is logged at `DEBUG` — below the shipped `info` default for the package — so a default deployment emits **nothing** on a successful cycle (only failures log at `ERROR`). Three consequences: (a) you cannot observe that deletions are happening or at what volume; (b) there is no signal that would reveal a **stuck or wedged cycle** (for example, one blocked behind a held advisory lock); (c) a compliance requirement that "deletions are logged/audited" is **not** satisfied out of the box — and raising the log level still yields best-effort log lines, not a durable audit trail. To observe deletions, set `logging.level.org.opendatadiscovery.oddplatform.housekeeping: debug` (see [Logging Settings Configuration](#logging-settings-configuration)); to verify a cycle ran at all, sample `pg_stat_user_tables.n_tup_del` across a 15-minute window, as in the TTL caveat above.
{% endhint %}

{% hint style="info" %}
**The session-housekeeping job runs N× redundantly on multi-replica deployments.** Spring's `PostgreSQLSessionHousekeepingJobHandler` fires hourly with `@Scheduled(fixedRate = 1, timeUnit = HOURS)` and has **no leader-election guard** — no `@SchedulerLock`, no advisory-lock acquisition (inconsistent with the rest of the platform's scheduled jobs, which join the [Advisory-lock registry](#advisory-lock-registry)). On an `INTERNAL_POSTGRESQL` session-provider deployment with N replicas, every replica runs the `DELETE FROM SPRING_SESSION WHERE expiry_time < now()` query every hour. The deletes are idempotent so data integrity is fine — the operator cost is N× redundant database load. Note that with the shipped default `spring.session.timeout: -1` ([sessions never expire](#session-lifetime-spring-session-timeout)), the job is a no-op regardless of leader count.
{% endhint %}

{% tabs %}
{% tab title="YAML" %}

```yaml
housekeeping:
  enabled: true
  ttl:
    resolved_alerts_days: 30
    search_facets_days: 30
    data_entity_delete_days: 30
```

{% endtab %}

{% tab title="Environment variables" %}

```
HOUSEKEEPING_ENABLED=true
HOUSEKEEPING_TTL_RESOLVED_ALERTS_DAYS=30
HOUSEKEEPING_TTL_SEARCH_FACETS_DAYS=30
HOUSEKEEPING_TTL_DATA_ENTITY_DELETE_DAYS=30
```

{% endtab %}
{% endtabs %}

## Advisory-lock registry

Several ODD Platform subsystems use PostgreSQL **advisory locks** to ensure that only one platform replica runs a given background loop at a time (the leader-election pattern for multi-replica deployments). Each subsystem owns one or more advisory-lock IDs, configured via dedicated `*.advisory-lock-id` keys. Operators overriding any of these IDs in a deployment overlay must treat them as a **single flat namespace across the platform** — collisions are not detected at startup and produce silent feature wedges (see the warning below).

| Configuration key                                   | Default ID | Owning subsystem                                                                                       | `@ConfigurationProperties` class | Single-leader role                                     |
| --------------------------------------------------- | ---------- | ------------------------------------------------------------------------------------------------------ | -------------------------------- | ------------------------------------------------------ |
| `notifications.wal.advisory-lock-id`                | `100`      | Notifications subscriber that reads from the WAL `replication-slot-name` and dispatches alert messages | `OddNotificationsProperties`     | One platform replica subscribes to the WAL stream      |
| `partition.advisory-lock-id`                        | `90`       | Partition orchestrator that creates next-period partitions on `activity` and `message` tables          | `PartitionProperties`            | One platform replica advances the partition window     |
| `datacollaboration.receive-event-advisory-lock-id`  | `110`      | Data Collaboration inbound event reader (Slack Events → `message_provider_event` queue)                | `DataCollaborationProperties`    | One platform replica drains the inbound event queue    |
| `datacollaboration.sender-message-advisory-lock-id` | `120`      | Data Collaboration outbound message sender (`message` queue → Slack)                                   | `DataCollaborationProperties`    | One platform replica drains the outbound message queue |

**`partition.advisory-lock-id` is deliberately shared between two managers** — `ActivityTablePartitionManager` and `MessageTablePartitionManager` both acquire ID `90`. This is intentional: one platform replica is elected as the global partition leader and serialises the partition-rotation work for both tables. Treat it as one logical leader, not two colliding subsystems.

{% hint style="warning" %}
**`pg_advisory_lock` blocks forever — on collision a subsystem wedges silently with no diagnostic signal.** The platform's leader-election manager executes the **blocking** variant of `pg_advisory_lock` against the configured ID — there is no `pg_try_advisory_lock` fast-path, no `statement_timeout`, no fallback to a degraded-mode bean. If two subsystems are configured to use the same advisory-lock ID (typically because an operator overrode one key in a Helm overlay and unintentionally matched another), the second subsystem's startup thread enters PostgreSQL lock-wait state and never returns. The Spring container does not detect the wedge — Spring's bean construction returned, so `/actuator/beans` and `/actuator/health` continue to report "running" — the wedge surfaces only as **one feature silently not working** (notifications stop arriving, Data Collaboration thread replies stop flowing, partition rotation stops creating future partitions). Operators MUST audit any per-environment advisory-lock-id override against the table above before applying it.

A platform-side fail-fast wrapper (`pg_try_advisory_lock` + a configurable timeout + a `subsystem_leader_state` Prometheus gauge + a boot-time INFO log enumerating the registry) is tracked upstream.
{% endhint %}

The Housekeeping orchestrator (see [Housekeeping Settings Configuration](#housekeeping-settings-configuration) above) does not appear in this table because it uses **ShedLock** (a Spring-side distributed-lock library) rather than a PostgreSQL advisory lock. ShedLock writes to a `shedlock` table to coordinate the leaders, so its multi-replica behaviour is documented separately.

## Platform-level settings (`odd.*`)

The `odd.*` namespace groups four platform-wide settings that do not belong to any subsystem: stale-metadata detection, the optional Prometheus tenant label, the Activity-feed partitioning period, and a list of additional navigation links surfaced in the App Info menu. A fifth key in the same namespace, `odd.platform-base-url`, is documented above in [Enable Alert Notifications → `odd.platform-base-url`](#odd-platform-base-url) — that section is the primary operator-facing context where the key is introduced, but the same key is also consumed by the integration-parameter substitution context, so any non-local deployment must set it regardless of which subsystems (notifications, integrations, or both) are enabled.

### Detecting stale metadata

Stale metadata is metadata that has not been refreshed from its source for longer than an operator-defined window. This typically happens when a collector is paused, deactivated, or failing to reach the source system. When the platform judges an entity to be stale, the UI surfaces it with a "Stale" indicator so users can distinguish data whose freshness is uncertain from actively-maintained metadata. For the user-facing surface (where the indicator appears, how the freshness signal differs from runtime alerts), see [Stale-metadata indicator](/features/data-discovery/metadata-stale).

* `odd.data-entity-stale-period`: number of days after the entity's last successful ingestion before it is labeled "Stale" in the UI and API. Integer, days. Defaults to `7`.

Operators running collectors on schedules longer than a week should raise this value to match the collector cadence — otherwise entities that were ingested successfully will be flagged stale between runs.

{% tabs %}
{% tab title="YAML" %}

```yaml
odd:
  data-entity-stale-period: 7 # days
```

{% endtab %}

{% tab title="Environment variables" %}

```
ODD_DATA_ENTITY_STALE_PERIOD=7
```

{% endtab %}
{% endtabs %}

### Prometheus tenant label (`odd.tenant-id`)

When [`metrics.storage`](#metric-storage-backend) is set to `PROMETHEUS`, the platform appends `tenant_id={value}` as a label on every Prometheus instant query it issues. This lets a single shared Prometheus instance serve metric data for multiple ODD Platform deployments without their metric series colliding — each deployment queries only its own tenant-labeled series.

* `odd.tenant-id`: tenant identifier appended as a Prometheus query label. String, no default (empty means no label is applied, and the Prometheus query returns series across all tenants). Ignored when `metrics.storage=INTERNAL_POSTGRES`.

{% tabs %}
{% tab title="YAML" %}

```yaml
odd:
  tenant-id: my-odd-deployment
```

{% endtab %}

{% tab title="Environment variables" %}

```
ODD_TENANT_ID=my-odd-deployment
```

{% endtab %}
{% endtabs %}

### Activity-feed partitioning (`odd.activity.partition-period`)

The ODD Platform `activity` table is range-partitioned on a rolling date window; `odd.activity.partition-period` sets the partition width in days. The default creates a new partition every 30 days, which is appropriate for most deployments. Operators running high-volume deployments (millions of activity events per day) can tune this downward to narrow partitions — smaller partitions speed up vacuum and partition-prune operations on the activity feed.

* `odd.activity.partition-period`: partition width in days for the `activity` table. Integer, days. Defaults to `30`.

{% tabs %}
{% tab title="YAML" %}

```yaml
odd:
  activity:
    partition-period: 30
```

{% endtab %}

{% tab title="Environment variables" %}

```
ODD_ACTIVITY_PARTITION_PERIOD=30
```

{% endtab %}
{% endtabs %}

### Additional navigation links (`odd.links`)

Operators can attach a list of arbitrary navigation links — pointers to internal wikis, runbooks, dashboards, or any other page teams should reach from inside ODD Platform. The platform UI surfaces them inside the App Info menu (the popup behind the **information icon** in the top-right toolbar). Each link renders as a menu item showing its title and opens the configured URL in a new tab when clicked.

* `odd.links`: list of link objects. Each entry has two required fields:
  * `title`: the menu-item label shown in the App Info menu. String, required.
  * `url`: the absolute URL the menu item opens in a new tab. String, required.

Defaults to an empty list — when unset, the App Info menu omits the additional-links section entirely.

{% tabs %}
{% tab title="YAML" %}

```yaml
odd:
  links:
    - title: Internal Wiki
      url: https://wiki.example.com/data-platform
    - title: On-call Runbook
      url: https://runbook.example.com/odd
```

{% endtab %}

{% tab title="Environment variables" %}

```
ODD_LINKS_0_TITLE=Internal Wiki
ODD_LINKS_0_URL=https://wiki.example.com/data-platform
ODD_LINKS_1_TITLE=On-call Runbook
ODD_LINKS_1_URL=https://runbook.example.com/odd
```

{% endtab %}
{% endtabs %}

{% hint style="info" %}
The links are exposed to the UI through the authenticated `GET /api/links` endpoint and are visible to every user signed in to the platform. Use them for navigation hints only — do not embed credentials, session tokens, or one-time secrets in link URLs, since any logged-in user can read them.
{% endhint %}

#### Validation and operator-link risks

Three known limitations apply to `odd.links` and the App Info menu that renders them. None of these is blocking for typical operator-curated link sets, but all three matter when the link source is less trusted (free-text Helm chart overrides, multi-tenant config templates, anything an end-user can influence).

{% hint style="warning" %}
**`odd.links` is not validated at config-load time.** The `AdditionalLinkProperties` record declares `title` and `url` as plain `String` with no `@NotBlank`, no `@URL`, no `@Pattern`, and no `@PostConstruct validate()`. The platform accepts and renders:

* Missing `title` — the menu item appears as an invisible-but-clickable area.
* Missing `url` — the menu item renders as a non-clickable `<a>`.
* `javascript:`, `data:`, `file:`, or `vbscript:` schemes — modern browsers will sandbox or refuse, but the platform does not reject these at config time.
* Relative paths (`wiki.internal`) — the browser interprets them as relative to the current ODD page, producing surprising navigation.

**Treat the `odd.links` config as a security-relevant input.** Validate the URLs in your Helm chart values before applying, restrict edit access to operators only, and never permit non-operators to author the override. A platform-side validator that rejects non-`http(s)` schemes and enforces `@NotBlank` is tracked upstream.
{% endhint %}

{% hint style="warning" %}
**The App Info menu links render `target="_blank"` without `rel="noopener noreferrer"`.** All five link sites in the App Info menu (operator-configured `odd.links` entries, the ODD Platform version link to GitHub, the Documentation link, the Slack link, and the Feedback link) open in a new tab without the `rel` attribute that isolates the destination from `window.opener`. A page at any of those destinations — including the operator-configured links above — can run `window.opener.location = "phishing.example.com"` in the background, replacing the parent ODD tab with an attacker-controlled login page (reverse-tabnabbing). Risk is operator-amplified — an unvalidated link (per the previous caveat) combined with this caveat is a workspace-wide tabnabbing vector. A platform-side `rel` fix is tracked upstream.
{% endhint %}

{% hint style="info" %}
**The App Info menu is not keyboard- or touch-accessible today.** The information-icon button declares `aria-haspopup="true"` and `aria-controls={menuId}` — surfaces that announce keyboard accessibility to assistive technology — but the open handler is wired only on `onMouseEnter`. There is no `onClick`, no `onKeyDown`, and no `onFocus`. Touch-device users (iOS Safari, Android Chrome) do not generate `mouseenter`; keyboard-only and screen-reader users cannot open the menu. The Documentation, Slack, Feedback, and operator-configured `odd.links` destinations are unreachable through the menu for these audiences — direct URLs are the workaround until a platform-side `onClick` / `onKeyDown` fix ships. Operators serving keyboard-only or screen-reader audiences should treat this as a known WCAG 2.1 SC 2.1.1 limitation.
{% endhint %}

## Attachment Storage Configuration

ODD Platform allows users to attach files and links to data entities from the UI. This section covers the operator-facing configuration for **where** those uploaded files are stored. For the user-facing upload workflow (what users can attach, the per-entity Attachments tab, the `DATA_ENTITY_ATTACHMENT_MANAGE` permission), see [Attachments and links](/features/data-discovery/attachments).

{% hint style="danger" %}
**The default `LOCAL` storage mode is ephemeral.** Attachments are written to `/tmp/odd/attachments` inside the ODD Platform container filesystem. Any container or pod restart — routine deployment, node drain, crash, Kubernetes eviction — permanently deletes all uploaded files.

**Use `REMOTE` (S3 / MinIO) storage for any Kubernetes or Docker deployment where users will actually upload attachments.** `LOCAL` mode is suitable only for single-host evaluations or local development where losing attachments on restart is acceptable.
{% endhint %}

### Configuration keys

* `attachment.storage`: storage backend. One of `LOCAL` or `REMOTE`. Defaults to `LOCAL`.
* `attachment.max-file-size`: the per-file upload limit the **UI enforces before upload**, in **megabytes**. Defaults to `20`. The platform surfaces this value to the web UI as a client-side pre-upload size check; the server does **not** re-validate per-file size on the upload path. `spring.codec.max-in-memory-size` (below) bounds only the in-memory buffer for a single request/chunk — and because attachment uploads are chunked and streamed to disk, it is **not** a ceiling on the assembled file. There is therefore **no effective server-side total-file size limit**: a direct (non-UI) API caller can exceed `attachment.max-file-size` by any amount. See the hint below if raising this above 20 MB.
* `attachment.local.path`: filesystem directory where attachments are written when `storage=LOCAL`. Defaults to `/tmp/odd/attachments` (ephemeral — see warning above).
* `attachment.remote.url`: S3-compatible endpoint URL when `storage=REMOTE` (for example `https://s3.us-east-1.amazonaws.com` for AWS S3 or `http://minio:9000` for a MinIO service). For AWS S3 buckets outside `us-east-1`, also set `attachment.remote.region` (below). See the **Known limitations (REMOTE mode)** subsection below for the chunked-upload staging behavior.
* `attachment.remote.access-key`: access key for the S3-compatible bucket.
* `attachment.remote.secret-key`: secret key for the S3-compatible bucket.
* `attachment.remote.bucket`: bucket name used to store attachment objects. The bucket must already exist — ODD Platform does not create it.
* `attachment.remote.region`: AWS S3 region used for request signing (for example `eu-central-1`). **Optional** — when left unset, the MinIO Java SDK's default (`us-east-1`) is used. Set it to your bucket's region when using **AWS S3 outside `us-east-1`**, otherwise uploads fail signature validation with `AuthorizationHeaderMalformed` or `PermanentRedirect`. Self-hosted MinIO and most other S3-compatible services ignore the region and can leave it unset.
* `spring.codec.max-in-memory-size`: platform-wide cap on the in-memory buffer Spring WebFlux uses when reading a **single request body / upload chunk**. Defaults to `20MB`. A single chunk larger than this fails at the codec layer; because uploads are chunked, this does **not** bound the total assembled file. Accepts a size string (`20MB`, `100MB`, `1GB`).

{% hint style="warning" %}
**`attachment.max-file-size` must not exceed `spring.codec.max-in-memory-size`.** Both ship with the same `20 MB` default, so the attachment cap is effective out of the box. If you raise `attachment.max-file-size` to allow larger uploads — for example `100 MB` — you must raise `spring.codec.max-in-memory-size` to at least the size of a single upload **chunk**, otherwise a chunk above `20 MB` fails at the WebFlux codec layer with `DataBufferLimitException`. This codec bound applies per chunk, not to the total file (see the per-file note above): the platform enforces no server-side cap on the assembled file size.
{% endhint %}

### Example: REMOTE storage with S3-compatible backend (MinIO or AWS S3)

{% tabs %}
{% tab title="YAML" %}

```yaml
attachment:
  storage: REMOTE
  max-file-size: 50 # mb
  remote:
    url: {s3_endpoint_url}
    access-key: {access_key}
    secret-key: {secret_key}
    bucket: {bucket_name}
    region: {aws_region} # optional; e.g. eu-central-1 for AWS S3 outside us-east-1
```

{% endtab %}

{% tab title="Environment variables" %}

```
ATTACHMENT_STORAGE=REMOTE
ATTACHMENT_MAX_FILE_SIZE=50
ATTACHMENT_REMOTE_URL={s3_endpoint_url}
ATTACHMENT_REMOTE_ACCESS_KEY={access_key}
ATTACHMENT_REMOTE_SECRET_KEY={secret_key}
ATTACHMENT_REMOTE_BUCKET={bucket_name}
ATTACHMENT_REMOTE_REGION={aws_region}
```

{% endtab %}
{% endtabs %}

### Known limitations (REMOTE mode)

ODD Platform builds its `MinioAsyncClient` with only the endpoint and credentials documented above. The MinIO Java SDK inherits defaults for every other parameter, and the attachment-upload code path carries a small amount of additional behavior that is not configurable. None of the following is currently exposed as an ODD configuration key — plan your deployment around these limits rather than assuming a config flag will fix them.

{% hint style="warning" %}
**HTTP client timeouts are the MinIO SDK defaults (\~5 minutes), not configurable.** ODD Platform does not supply a custom `OkHttpClient` to the MinIO builder, so the SDK's built-in defaults apply: roughly a 5-minute read/write timeout. A single large upload whose end-to-end wall time (network transfer + S3 ingest) exceeds that limit fails with a socket-timeout error even though the content was being streamed successfully. If your users upload near the `attachment.max-file-size` limit over a slow link, keep `attachment.max-file-size` below the size a typical upload can complete inside 5 minutes at your network's real throughput.
{% endhint %}

{% hint style="danger" %}
**Chunked uploads are assembled on the container's local filesystem before they are sent to `REMOTE` storage — a mid-upload container restart loses the staged chunks.** The UI splits large files into chunks and uploads each chunk individually; the platform writes each chunk to a hardcoded local directory — `/tmp/odd/chunks`, **independent of `attachment.local.path`**, so pointing `attachment.local.path` at a durable path does not move chunk staging — and reassembles the full file there before streaming it to the S3-compatible backend. **This is true even when `attachment.storage=REMOTE`.** If the ODD Platform container is restarted, evicted, or rescheduled during an in-flight chunked upload, the local directory is wiped and the partial upload is unrecoverable — the user must re-upload from scratch. In Kubernetes deployments, either mount a persistent volume at the chunk-staging directory (`/tmp/odd/chunks`) or limit the maximum upload size so single-request uploads are the norm. The `LOCAL`-mode ephemeral warning above applies to chunk-staging in `REMOTE` mode as well.
{% endhint %}

{% hint style="warning" %}
**No retry on transient S3 / MinIO errors.** Put, get, and remove operations against the bucket do not retry on transient failures — a single 503 from S3, a connection reset from the network, or a short MinIO outage surfaces as a failed operation with no automatic recovery. If your alerting pipeline treats attachment failures as user-impacting errors, add retry at the infrastructure layer (for example an S3-proxy sidecar with retry) rather than expecting the platform to paper over it.
{% endhint %}

{% hint style="warning" %}
**No IAM-role support today — static access-key / secret-key are the only credentials path.** The platform's MinIO client builder calls `.credentials(accessKey, secretKey)` against the values configured above; it does not call `.credentialsProvider(...)` with the AWS SDK's `DefaultCredentialsProvider`. Operators on AWS EKS using IAM Roles for Service Accounts (IRSA), on ECS task roles, or on any other AWS-native credential-injection mechanism that expects the SDK to walk the default credentials chain — environment variables → web-identity-token → EC2 instance metadata → ECS task-role — get **no automatic credential resolution**. Static `attachment.remote.access-key` + `attachment.remote.secret-key` values must be supplied via `application.yml`, Helm secrets, or the equivalent operator-managed credential store, and rotated on the operator's own cadence. This is itself a credential-hygiene concern in deployments where IAM-role injection is the standard. The upstream fix is a conditional switch — if no static credentials are supplied, call `.credentialsProvider(DefaultAWSCredentialsProviderChain.getInstance())` to enable IAM-role workflows; the doc-side caveat is in place until that lands.
{% endhint %}

### Example: LOCAL storage (single-host / local evaluation only)

{% tabs %}
{% tab title="YAML" %}

```yaml
attachment:
  storage: LOCAL
  max-file-size: 20 # mb
  local:
    path: /var/lib/odd/attachments
```

{% endtab %}

{% tab title="Environment variables" %}

```
ATTACHMENT_STORAGE=LOCAL
ATTACHMENT_MAX_FILE_SIZE=20
ATTACHMENT_LOCAL_PATH=/var/lib/odd/attachments
```

{% endtab %}
{% endtabs %}

If you keep `LOCAL` mode, override `attachment.local.path` to a persistent volume mount rather than the default `/tmp/odd/attachments`, and confirm the volume is actually persistent across restarts in your deployment topology.

## Logging Settings Configuration

Logs provide detailed information about errors in the application helping its users quickly identify and fix problems. Setting up logging is recommended for ensuring operational excellence, system reliability, effective monitoring and troubleshooting.\
Here is a code snippet for setting up logs in ODD Platform:

{% tabs %}
{% tab title="YAML" %}

```yaml
logging:
  level:
    org.springframework.transaction.interceptor: info
    org.jooq.tools.LoggerListener: info
    io.r2dbc.postgresql.QUERY: info
    io.r2dbc.postgresql.PARAM: info
    org.opendatadiscovery.oddplatform.notification: info
    org.opendatadiscovery.oddplatform.housekeeping: info
    org.opendatadiscovery.oddplatform.partition: info
    org.opendatadiscovery.oddplatform.datacollaboration: info
    org.opendatadiscovery.oddplatform.service.ingestion: info
```

{% endtab %}

{% tab title="Environment variables" %}

```
LOGGING_LEVEL_ORG_SPRINGFRAMEWORK_TRANSACTION_INTERCEPTOR=info
LOGGING_LEVEL_ORG_JOOQ_TOOLS_LOGGERLISTENER=info
LOGGING_LEVEL_IO_R2DBC_POSTGRESQL_QUERY=info
LOGGING_LEVEL_IO_R2DBC_POSTGRESQL_PARAM=info
LOGGING_LEVEL_ORG_OPENDATADISCOVERY_ODDPLATFORM_NOTIFICATION=info
LOGGING_LEVEL_ORG_OPENDATADISCOVERY_ODDPLATFORM_HOUSEKEEPING=info
LOGGING_LEVEL_ORG_OPENDATADISCOVERY_ODDPLATFORM_PARTITION=info
LOGGING_LEVEL_ORG_OPENDATADISCOVERY_ODDPLATFORM_DATACOLLABORATION=info
LOGGING_LEVEL_ORG_OPENDATADISCOVERY_ODDPLATFORM_SERVICE_INGESTION=info
```

{% endtab %}
{% endtabs %}

Setting the logging level to `info` allows you to see useful messages about the platform’s functioning without being overwhelmed by too much detail as with `trace` or `debug` or missing important issues as with `warn` or higher level.\
However, feel free to adjust the logging level as needed to get more or less information based on your specific requirements.

## GenAI Configuration

The platform can proxy natural-language questions to an external AI service via three keys under the `genai` prefix (`@ConfigurationProperties("genai")` per `GenAIProperties.java`). The feature is **disabled by default** and is **API-only** today (no in-app UI affordance calls the endpoint).

* `genai.enabled` (boolean, env `GENAI_ENABLED`) — feature toggle. **Default `false`** (set explicitly at `application.yml` line 18). When `false`, `POST /api/genai/ask` returns HTTP 400 with the message "Gen AI is disabled". **Feature toggling**: this value is captured at JVM boot — restart the JVM process for a change to take effect; runtime configuration changes are not honoured. See [Features → Data Collaboration](/features/features#data-collaboration) for the platform-wide boot-immutability caveat.
* `genai.url` (string, env `GENAI_URL`) — base URL of the external AI service. The platform's `genAiWebClient` is built at startup with this as `baseUrl` and POSTs each request to `{genai.url}/query_data`. **No `@ConfigurationProperties` default — the field has no initializer in `GenAIProperties.java`, so its Java default is `null`.** The example in `application.yml` line 19 (`# url: http://localhost:5000`) is commented out, not a default.
* `genai.request_timeout` (integer, env `GENAI_REQUEST_TIMEOUT`) — outbound response timeout, **in minutes**. Wired into `WebClientConfiguration.java:23` as `Duration.ofMinutes(genAIProperties.getRequestTimeout())`. **No `@ConfigurationProperties` default — the Java primitive `int` default is `0`, which means immediate timeout.** The example in `application.yml` line 20 (`# request_timeout: 2`) is commented out, not a default.

{% hint style="warning" %}
**Setting only `genai.enabled=true` will silently misconfigure the feature.** With `url` defaulting to `null` and `request_timeout` defaulting to `0`, the WebClient is built with no `baseUrl` and a `Duration.ofMinutes(0)` timeout — every `POST /api/genai/ask` will fail before the external service has a chance to respond. Always set all three keys when enabling.

`WebClientConfiguration` reads `genai.url` and `genai.request_timeout` once at startup when constructing the `genAiWebClient` Spring bean. Changing those values requires a Platform restart.
{% endhint %}

A working configuration block:

{% tabs %}
{% tab title="application.yml" %}

```yaml
genai:
  enabled: true
  url: "http://my-ai-service.internal:5000"
  request_timeout: 5     # minutes
```

{% endtab %}

{% tab title="Environment variables" %}

```bash
GENAI_ENABLED=true
GENAI_URL=http://my-ai-service.internal:5000
GENAI_REQUEST_TIMEOUT=5
```

{% endtab %}
{% endtabs %}

The platform sends **no authentication** to the external AI service and does **not retry**. See the dedicated [GenAI assistant](/features/active-platform-features/genai) page for the external service contract (`POST /query_data` with JSON `{"question": "..."}`), the platform's `/api/genai/ask` request/response schemas, and the per-error behavior.

## Machine-to-Machine (M2M) Tokens Configuration

ODD Platform supports a static API-key authentication mode for non-UI callers (CI/CD jobs, ingestion pipelines, automation scripts) — also referred to as Machine-to-Machine (M2M) tokens. It is **disabled by default**.

For the full configuration keys, the header contract, the curl example, and security considerations (token rotation, HTTPS, blast radius), see [Server-to-server (S2S) authentication](/configuration-and-deployment/enable-security/authentication/s2s).


# Health and monitoring

Wire liveness/readiness probes to ODD Platform's /actuator/health and scrape metrics from /actuator/prometheus — what the health verdict does and does not cover.

ODD Platform ships with [Spring Boot Actuator](https://docs.spring.io/spring-boot/reference/actuator/index.html) as its monitoring surface. The bundled configuration disables every actuator endpoint by default and enables exactly four: `health`, `prometheus`, `env`, and `info`. The whole `/actuator/**` namespace is served on the platform's regular HTTP port (`8080` by default) and is reachable **without authentication** in every `auth.type` — which is what load balancers, Kubernetes probes, and Prometheus scrapers need, and also why the namespace must be network-restricted in production (see [Security considerations](#security-considerations) below).

## Health endpoint

`GET /actuator/health` returns HTTP `200` with body `{"status":"UP"}` while the platform is healthy, and HTTP `503` with `{"status":"DOWN"}` when any contributing health indicator fails. No authentication, session, or header is required in any authentication mode.

The verdict aggregates Spring Boot's standard autoconfigured health indicators for the components on the platform's classpath — in a default deployment that means connectivity of the platform's PostgreSQL database plus free disk space and a basic liveness ping. The platform registers no custom health indicators of its own, and the bundled configuration explicitly **disables two** of the standard ones:

* `management.health.ldap.enabled: false` — an unreachable LDAP server fails logins, not the health verdict.
* `management.health.redis.enabled: false` — see the warning below.

{% hint style="warning" %}
**What a green health verdict does&#x20;*****not*****&#x20;tell you.**

* **Redis session store.** With [`session.provider: REDIS`](/configuration-and-deployment/odd-platform#redis), a Redis outage fails every authenticated request — but the health endpoint stays `UP`, because the Redis health indicator is disabled in the bundled defaults. If you run the `REDIS` session provider, set `management.health.redis.enabled: true` so the verdict covers your session store.
* **Background subsystems.** A subsystem wedged on a PostgreSQL advisory-lock collision (notifications, housekeeping, partition rotation) keeps reporting healthy — see the [advisory-lock registry](/configuration-and-deployment/odd-platform#advisory-lock-registry) for the failure mode and the audit rule.
* **Ingestion write path.** A `200`/`UP` does not exercise ingestion. And do not point a probe at the ingestion API instead: `POST /ingestion/metrics` returns `201` even for an empty no-op payload — see the [metrics-ingestion caveats](/features/active-platform-features/metrics-ingestion#known-operator-caveats).
  {% endhint %}

## Wiring probes

The images and Compose files distributed with the platform define no health checks themselves — wiring probes is the operator's responsibility. Both examples below target the platform's default port `8080`.

Kubernetes liveness and readiness probes:

```yaml
livenessProbe:
  httpGet:
    path: /actuator/health
    port: 8080
  initialDelaySeconds: 60   # first boot runs database migrations; allow extra time on the first deploy
  periodSeconds: 10
readinessProbe:
  httpGet:
    path: /actuator/health
    port: 8080
  initialDelaySeconds: 30
  periodSeconds: 10
```

Docker Compose health check:

```yaml
services:
  odd-platform:
    image: ghcr.io/opendatadiscovery/odd-platform:latest
    healthcheck:
      test: ["CMD", "wget", "--quiet", "--tries=1", "--spider", "http://localhost:8080/actuator/health"]
      interval: 10s
      timeout: 5s
      retries: 12
      start_period: 60s
```

{% hint style="info" %}
On a fresh database the platform runs its schema migrations during startup, so the first boot takes noticeably longer than subsequent ones. Size `initialDelaySeconds` / `start_period` for the first-boot case, or a restart loop can kill the platform mid-migration.
{% endhint %}

## Prometheus metrics

`GET /actuator/prometheus` exposes the platform's runtime metrics (JVM, HTTP server, connection pools) in the Prometheus text format, backed by the bundled Micrometer Prometheus registry. Like the health endpoint, it requires no authentication. A minimal scrape configuration:

```yaml
scrape_configs:
  - job_name: odd-platform
    metrics_path: /actuator/prometheus
    static_configs:
      - targets: ["odd-platform.your-domain.com:8080"]
```

This endpoint is the platform's *operational* telemetry about itself. It is unrelated to the [Metrics Ingestion](/features/active-platform-features/metrics-ingestion) feature, which ingests data-quality metrics *about your datasets* (and whose optional `metrics.storage: PROMETHEUS` backend is a separate, operator-run Prometheus instance).

## Security considerations

The unauthenticated reachability that makes `/actuator/health` convenient for probes applies to the entire `/actuator/**` namespace — including `env` and `info`, which are also enabled in the bundled configuration. Canonical hardening guidance (separate management port, firewalling the path, restricting the exposed endpoint set) lives at [Management endpoint exposure and credential hygiene](/configuration-and-deployment/odd-platform#management-endpoint-exposure-and-credential-hygiene). If you restrict the exposed set with `management.endpoints.web.exposure.include`, keep `health` (and `prometheus`, if you scrape it) so your probes keep working.


# Collector secrets backend

Load collector secrets (Platform token, DB passwords, cloud credentials) from an external backend — AWS SSM today, pluggable for additional providers — instead of plaintext YAML.

By default, every value in a collector's `collector_config.yaml` — the Platform token, per-plugin database passwords, cloud-provider credentials — lives in plaintext on disk. That is acceptable for local development, but for production deployments the collector SDK can load sensitive values from an external **secrets backend** (also referred to as the **alternative secrets backend**) instead, leaving only the backend pointer in the YAML file.

## Supported providers

| Provider                            | `secrets_backend.provider` value  |
| ----------------------------------- | --------------------------------- |
| AWS Systems Manager Parameter Store | `AWSSystemsManagerParameterStore` |

Only one provider is available today; additional providers can be plugged in via the `BaseSecretsBackend` abstract class in `odd-collector-sdk`.

## How the backend is consumed

When a `secrets_backend` block is present in `collector_config.yaml`, the loader fetches two things from the backend:

1. **Collector settings** — a single parameter whose YAML value is merged into the top-level collector settings (for example `token`, `platform_host_url`, `default_pulling_interval`).
2. **Plugin settings** — one parameter per plugin under a shared prefix; each parameter's YAML value is an individual plugin block.

The local YAML file is still parsed, but **values from the secrets backend win**. The local `plugins` list can contribute plugins whose names do not collide with plugins loaded from the backend, and the local top-level settings can contribute keys that are not set in the backend — but they can never override a key that is set in the backend. Treat the local file as a fallback, not an override.

## Configuration reference

All keys below live under `secrets_backend:` in `collector_config.yaml`.

| Key                                 | Type   | Default                                    | Description                                                          |
| ----------------------------------- | ------ | ------------------------------------------ | -------------------------------------------------------------------- |
| `provider`                          | string | *(required)*                               | Backend provider code. Must be `AWSSystemsManagerParameterStore`.    |
| `region_name`                       | string | *(resolved from env / IMDS — see below)*   | AWS region the SSM parameters live in.                               |
| `collector_settings_parameter_name` | string | `/odd/collector_config/collector_settings` | Full SSM parameter name holding the top-level collector settings.    |
| `collector_plugins_prefix`          | string | `/odd/collector_config/plugins`            | SSM parameter prefix under which one parameter per plugin is stored. |

The `region_name` is resolved in this order: `AWS_REGION` environment variable → `region_name` in `collector_config.yaml` → the EC2 IMDS (for collectors running on EC2 or EKS). If none of these resolves to a region, the collector process still starts, but the first SSM call raises `botocore.exceptions.NoRegionError` and the collector exits before ingestion begins. Set the region explicitly for non-EC2 deployments.

{% hint style="info" %}
The SDK's settings loader uses `extra="allow"`, so any additional keys under `secrets_backend:` are forwarded to the provider constructor. Future providers may introduce their own keys without needing a schema change here.
{% endhint %}

## Parameter naming convention

For the AWS SSM provider, each plugin in the collector is stored as a separate SSM parameter under `collector_plugins_prefix`. The parameter's **name** is not significant to the loader — the SDK fetches every parameter under the prefix with a recursive `GetParametersByPath` call and parses each value as a plugin YAML block. The convention shown in the SSM example below uses the plugin `name` as the final path segment purely for operator readability; what matters is that each plugin's YAML is stored as its own parameter.

The **value** of each parameter is a YAML document with the same schema as a single entry in the `plugins:` list in `collector_config.yaml`.

## Worked example

### Step 1 — Store the collector settings in SSM

Create one `SecureString` parameter named `/odd/collector_config/collector_settings` with this value:

```yaml
default_pulling_interval: 60
platform_host_url: https://odd.internal.example.com
token: <platform_token>
```

### Step 2 — Store each plugin in SSM

For every data source the collector should pull, create one parameter under `/odd/collector_config/plugins/`. For example, a PostgreSQL plugin at `/odd/collector_config/plugins/postgresql_adapter`:

```yaml
type: postgresql
name: postgresql_adapter
description: ""
database: warehouse
host: db.internal.example.com
port: 5432
user: odd_ro
password: <db_password>
```

### Step 3 — Point the collector at the backend

Keep only the backend pointer (and anything you intentionally want the local file to contribute) in `collector_config.yaml`:

```yaml
secrets_backend:
  provider: AWSSystemsManagerParameterStore
  region_name: eu-central-1
  collector_settings_parameter_name: /odd/collector_config/collector_settings
  collector_plugins_prefix: /odd/collector_config/plugins
```

### Step 4 — Run the collector

On startup the collector will:

1. Parse `collector_config.yaml`.
2. Connect to SSM using the configured region.
3. Fetch `/odd/collector_config/collector_settings` and merge its values into the top-level settings (SSM wins on conflicts).
4. Fetch every parameter under `/odd/collector_config/plugins/` and merge its plugins into the plugin list (SSM wins on name conflicts).
5. Validate the resulting config and start pulling.

## Required IAM permissions

The IAM identity the collector runs under — an EKS service account role, an EC2 instance role, or a user with static credentials — needs at least these permissions on the parameters you created:

```json
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "ssm:GetParameter",
        "ssm:GetParametersByPath"
      ],
      "Resource": [
        "arn:aws:ssm:{region}:{account_id}:parameter/odd/collector_config/collector_settings",
        "arn:aws:ssm:{region}:{account_id}:parameter/odd/collector_config/plugins/*"
      ]
    },
    {
      "Effect": "Allow",
      "Action": [
        "kms:Decrypt"
      ],
      "Resource": "arn:aws:kms:{region}:{account_id}:key/{kms_key_id}"
    }
  ]
}
```

The `kms:Decrypt` statement is only needed when the parameters were created as `SecureString` with a customer-managed KMS key (or with the AWS-managed `alias/aws/ssm` key). Plain `String` parameters do not require KMS permissions.

## Known limitations

The AWS SSM backend is a thin wrapper around `boto3`. The following behaviors come from the SDK defaults and cannot currently be overridden from `collector_config.yaml`. Review each against your deployment before relying on the backend in production.

{% hint style="danger" %}
**The backend loads at most 10 plugin parameters from SSM.** The SDK calls `ssm.get_parameters_by_path(..., Recursive=True)` once and reads `response["Parameters"]` without paginating. The AWS default `MaxResults` for this call is 10. A collector whose `collector_plugins_prefix` contains 11 or more plugin parameters will silently start with only the first 10; everything past that point is dropped with no error and no log warning.

Mitigations until the SDK adds pagination:

* Keep the plugin count under 10 per collector. Split larger fleets into multiple collectors, each with its own prefix.
* After deploying, compare the plugin count in SSM against the plugin count logged at collector startup — a mismatch means you have hit the cap.
  {% endhint %}

{% hint style="warning" %}
**No custom SSM endpoint can be configured.** The SDK constructs the SSM client with `boto3.client("ssm", region_name=...)` and does not expose `endpoint_url`. Deployments that need to reach SSM via a VPC interface endpoint, a private DNS override, LocalStack, or any non-default endpoint must rely on system-level DNS / network configuration — there is no `secrets_backend.endpoint_url` key to set.
{% endhint %}

{% hint style="warning" %}
**No timeout or retry overrides.** The backend does not pass a `botocore.config.Config`, so the SDK's default connect timeout, read timeout, and retry mode apply. On a partitioned or slow SSM endpoint the collector can block on startup for the full default timeout before failing. There is no `secrets_backend.connect_timeout` / `read_timeout` / `retries` key.
{% endhint %}

{% hint style="warning" %}
**SSM parameter values are parsed as YAML without schema validation at fetch time.** A malformed YAML document in any parameter under `collector_plugins_prefix` will raise during `safe_load` and abort collector startup with a parsing error, not a message pointing at the offending parameter. Treat SSM parameter edits the same way you would treat edits to `collector_config.yaml` — validate the YAML locally before putting the parameter.
{% endhint %}


# Enable security

ODD's two independent authentication surfaces — the UI/API surface (auth.type) and the ingestion endpoint (auth.ingestion.filter.enabled). Enabling one does not protect the other.

ODD Platform has **two independent authentication surfaces**, each governed by its own configuration flag. Enabling one does not protect the other.

| Surface              | What it protects                                                            | Configuration                                                                                                                                                                                                              |
| -------------------- | --------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| User interface / API | Human users browsing the catalog and programmatic clients calling `/api/**` | `auth.type` (DISABLED / LOGIN\_FORM / OAUTH2 / LDAP) — see [Authentication](/configuration-and-deployment/enable-security/authentication) and [Authorization](/configuration-and-deployment/enable-security/authorization) |
| Ingestion            | Collectors and push adapters calling `/ingestion/**`                        | `auth.ingestion.filter.enabled` (default `false`) — see below                                                                                                                                                              |

A platform with OAuth2 enabled for the UI but the ingestion filter disabled is a platform with a protected catalog UI and an open write endpoint. Operators must configure both.

## Ingestion authentication

The `/ingestion/**` namespace is whitelisted in Spring Security (`SecurityConstants.WHITELIST_PATHS`), so it never traverses the UI authentication chain regardless of `auth.type`. Instead, two dedicated `WebFilter`s protect specific ingestion paths.

| Endpoint                                                                                                                                         | Filter                        | Active when                                     | Behavior                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                       |
| ------------------------------------------------------------------------------------------------------------------------------------------------ | ----------------------------- | ----------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `POST /ingestion/datasources`                                                                                                                    | `IngestionDataSourceFilter`   | **always** (unconditional)                      | Requires `Authorization: Bearer <token>`; looks up the collector by token; responds 401 if the token is missing or unknown                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                     |
| `POST /ingestion/entities`                                                                                                                       | `IngestionDataEntitiesFilter` | only when `auth.ingestion.filter.enabled: true` | Requires `Authorization: Bearer <token>`; validates the token against the datasource's stored token (falls back to the collector's token)                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                      |
| All other `/ingestion/*` paths (e.g. `/ingestion/alert/alertmanager`, `/ingestion/entities/degs/children`, `/ingestion/entities/datasets/stats`) | —                             | —                                               | **Unauthenticated under `auth.type` = `DISABLED`, `OAUTH2`, or `LDAP`** — the `/ingestion/**` glob in `SecurityConstants.WHITELIST_PATHS` carries all sibling paths through `permitAll` (under `DISABLED`, every exchange permits regardless). Under `auth.type=LOGIN_FORM`, sibling paths are instead **session-gated** by the catch-all `pathMatchers("/**").authenticated()` rule — but [LOGIN\_FORM is documented as dev-only](/configuration-and-deployment/enable-security/authentication/login-form), so this distinction does not change the operational guidance below. The filters above match exact path patterns; they do not cover sibling paths. |

{% hint style="danger" %}
**`auth.ingestion.filter.enabled` defaults to `false`.** With the default in place and the platform reachable on the network, any caller who can speak the ingress API can `POST /ingestion/entities` with a spec-valid `DataEntityList`. If the `data_source_oddrn` in the payload matches an existing datasource, fake entities, schemas, lineage edges, owners, and tags are upserted into the catalog and rendered to every user as authoritative metadata. The payload is spec-aligned, so this is not an exploit — it is the documented ingress flow being called by an unauthenticated party. ODDRN values follow predictable patterns (`//postgresql/host:port/databases/...`), so guessing is feasible.
{% endhint %}

Enable the ingestion filter for **any** deployment where the platform is reachable from an untrusted network — which, in practice, is any non-local-dev deployment. Collectors using `odd-collector-sdk` already attach `Authorization: Bearer <token>` on every call, so turning the flag on does not require collector-side changes as long as the collector's token is registered in the platform.

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
  ingestion:
    filter:
      enabled: true
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_INGESTION_FILTER_ENABLED=true
```

{% endtab %}
{% endtabs %}

### Ingestion paths the filter does not cover

Through 0.28.x, `IngestionDataEntitiesFilter` used an exact path matcher (`/ingestion/entities`, POST), so sibling endpoints under `/ingestion/*` — `/ingestion/alert/alertmanager`, `/ingestion/entities/degs/{degOddrn}/children`, `/ingestion/entities/datasets/stats`, `/ingestion/metrics` — stayed outside the filter's coverage even with `auth.ingestion.filter.enabled: true`. **From 0.29.0 this is fixed** ([ADR-0079](/developer-guides/architecture-decision-log/adr-0079-ingestion-authentication-filter-coverage)): a single `IngestionAuthenticationFilter` authenticates the whole `/ingestion/**` surface, so with the flag on **every** sibling route requires a token, not just `/ingestion/entities`. With the flag **off** (the default) the siblings remain reachable as described below.

Whether these uncovered paths are reachable to an unauthenticated caller depends on `auth.type`:

* Under `auth.type=DISABLED`, `OAUTH2`, or `LDAP`, the `/ingestion/**` glob in `SecurityConstants.WHITELIST_PATHS` permits every sibling path before the UI auth chain runs — the endpoints are anonymously reachable on the network.
* Under `auth.type=LOGIN_FORM`, the catch-all `.pathMatchers("/**").authenticated()` rule session-gates the siblings — an anonymous caller is redirected to `/login`. This blocks collectors and push-clients that do not carry a UI session, so LOGIN\_FORM is rarely the right mode for production ingestion regardless.

The full per-endpoint × per-auth-config picture is enumerated in the [Deployment matrix](#deployment-matrix-per-endpoint-per-auth-config) below.

The AlertManager webhook is the most operationally relevant of these — see the warning on the [Configure ODD Platform](/configuration-and-deployment/odd-platform#authentication) page, `Prometheus AlertManager Integration → Authentication` section. Apply perimeter controls (network segmentation, authenticating reverse proxy, mTLS) for any deployment where these endpoints are reachable from outside the trusted network.

The platform-side fix broadening the ingestion filter's coverage shipped in **0.29.0** ([ADR-0079](/developer-guides/architecture-decision-log/adr-0079-ingestion-authentication-filter-coverage)): with `auth.ingestion.filter.enabled=true` these siblings now require a token. The default stays `false`, so the caveats below still apply to any deployment that has not enabled the flag.

## Statistics endpoint — write shape and replay behaviour

The `POST /ingestion/entities/datasets/stats` endpoint listed above carries a write contract that operators need to understand before exposing it on any network. With `auth.ingestion.filter.enabled=true` (0.29.0+) it requires a token; with the default (`false`) it is uncovered by the ingestion filter under every `auth.type` value. Independently of authentication, the platform does not validate the payload's parent-child consistency:

{% hint style="danger" %}
**Cross-dataset write surface.** The platform resolves field statistics writes **by field ODDRN only**, with no JOIN to the declared parent dataset. A payload of the shape

```json
{
  "items": [
    {
      "datasetOddrn": "//A/...",
      "fields": { "<oddrn-of-field-in-dataset-B>": { "stats": ... } }
    }
  ]
}
```

writes the `stats` value to dataset **B**'s field row while triggering full-text-search recompute on dataset **A** (the declared parent). Any caller on the network who knows a field's ODDRN can poison that field's statistics through any other dataset's parent declaration. Downstream consumers (the Quality Dashboard rings, the Dataset Structure tab, BI tools reading `dataset_field.stats`) render the attacker-controlled values without any indicator that the write originated through an unrelated parent.

Combined with the endpoint being unauthenticated by default under `DISABLED`, `OAUTH2`, and `LDAP` (and accessible to any authenticated user with a session under `LOGIN_FORM`), this is a trivial data-integrity attack on any dataset's field statistics. Enabling `auth.ingestion.filter.enabled` (0.29.0+) closes the *unauthenticated* vector, but the cross-dataset write shape is a separate concern — a holder of any valid collector/datasource token can still write across the parent boundary. Apply perimeter controls and treat the ingestion token as a write credential.

**The statistics write leaves no Activity Feed trace.** Unlike a field's internal-name change or a field's tag change — both of which emit an Activity Feed event — the statistics write is not recorded in the activity stream. A caller who poisons a field's statistics through this endpoint produces no entry an operator can find after the fact: there is no "who changed these stats, and when" record to audit. Treat detection of this write as a perimeter-and-monitoring concern (reverse-proxy access logs, network controls), not something the platform's own audit surface will show you.
{% endhint %}

**Replay-with-fewer-tags destroys the absent ones.** The endpoint accepts a tags list per field; the platform compares the incoming list against the existing `EXTERNAL_STATISTICS`-origin tag relations for that field and **deletes** every relation absent from the new payload before creating the new ones. There is no merge-semantics opt-in and no `replace_tags` flag — re-POSTing a stats payload with a shorter tags list silently removes the tags missing from the second call. Treat the endpoint as a destructive replace, not an additive update.

## Deployment matrix — per-endpoint × per-auth-config

The matrix below is the authoritative answer for "which ingestion endpoints are reachable on my deployment?" The per-property bullets on the [Configure ODD Platform](/configuration-and-deployment/odd-platform) page describe one knob each, not their interaction. When a per-property description and this matrix disagree, this matrix wins — it is derived from the runtime code, not the property name.

The columns assume `auth.s2s.enabled` is `false` (the default). When S2S is enabled and a request carries a valid `X-API-Key`, every endpoint accepts the request regardless of `auth.type` or the ingestion filter — see [Server-to-server (S2S) authentication](/configuration-and-deployment/enable-security/authentication/s2s).

`AUTH-token` means the endpoint requires a valid `Authorization: Bearer <token>` header against the platform's collector/datasource token; the request body is rejected at the `WebFilter` if the token is missing or wrong. `OPEN` means an anonymous request is accepted and acted on. `SESSION-gated` means an anonymous request is redirected to `/login`; a UI-session-authenticated caller's request reaches the handler (subject to the `WebFilter` if any).

| Endpoint                                                                      | `auth.type=DISABLED`              | `auth.type=OAUTH2` / `LDAP`       | `auth.type=LOGIN_FORM`                                       |
| ----------------------------------------------------------------------------- | --------------------------------- | --------------------------------- | ------------------------------------------------------------ |
| `POST /ingestion/datasources`                                                 | **AUTH-token** (filter always on) | **AUTH-token** (filter always on) | **AUTH-token** (filter always on)                            |
| `POST /ingestion/entities` — `auth.ingestion.filter.enabled: false` (default) | **OPEN**                          | **OPEN**                          | **SESSION-gated**                                            |
| `POST /ingestion/entities` — `auth.ingestion.filter.enabled: true`            | **AUTH-token** (filter applies)   | **AUTH-token** (filter applies)   | **AUTH-token** (filter applies; session gate also satisfied) |
| `POST /ingestion/entities/datasets/stats` — flag `false` (default)            | **OPEN**                          | **OPEN**                          | **SESSION-gated**                                            |
| `POST /ingestion/entities/datasets/stats` — flag `true` (0.29.0+)             | **AUTH-token**                    | **AUTH-token**                    | **AUTH-token**                                               |
| `POST /ingestion/metrics` — flag `false` (default)                            | **OPEN**                          | **OPEN**                          | **SESSION-gated**                                            |
| `POST /ingestion/metrics` — flag `true` (0.29.0+)                             | **AUTH-token**                    | **AUTH-token**                    | **AUTH-token**                                               |
| `POST /ingestion/alert/alertmanager` — flag `false` (default)                 | **OPEN**                          | **OPEN**                          | **SESSION-gated**                                            |
| `POST /ingestion/alert/alertmanager` — flag `true` (0.29.0+)                  | **AUTH-token**                    | **AUTH-token**                    | **AUTH-token**                                               |
| `GET /ingestion/entities/degs/{degOddrn}/children` — flag `false` (default)   | **OPEN**                          | **OPEN**                          | **SESSION-gated**                                            |
| `GET /ingestion/entities/degs/{degOddrn}/children` — flag `true` (0.29.0+)    | **AUTH-token**                    | **AUTH-token**                    | **AUTH-token**                                               |

**Reading the matrix as an operator:** an `OPEN` cell on a production deployment is a place an unauthenticated caller can act. Either flip `auth.type` to `LOGIN_FORM` (rarely practical for collector traffic — they have no sessions), enable `auth.ingestion.filter.enabled` and/or `auth.s2s.enabled`, or apply perimeter controls (network segmentation, authenticating reverse proxy, mTLS) to bring those cells to a controlled state.

## Authentication and authorization

For details on the UI authentication options and the authorization model that governs what authenticated users can do, see the [Authentication](/configuration-and-deployment/enable-security/authentication) and [Authorization](/configuration-and-deployment/enable-security/authorization) sections. For the cross-cutting question "which user becomes ADMIN under each auth mode and provider", see the unified [Admin promotion across providers](/configuration-and-deployment/enable-security/admin-promotion) reference.


# Authentication

ODD Platform's four supported authentication mechanisms for the UI/API surface — Disabled, Login form, OAuth2/OIDC, and LDAP — plus the S2S API-key surface for programmatic clients.

This section provides detailed explanations on how to enable one of the authentication mechanisms supported by ODD Platform.

{% hint style="danger" %}
**The shipped default is `auth.type: DISABLED` — no authentication at all.** Out of the box, ODD Platform permits every request to the UI and API anonymously: there is no login page, and every caller is treated as an administrator. Nothing in the default configuration prompts you to change this. Before you expose ODD Platform on any network another person can reach, set `auth.type` to one of the modes below.
{% endhint %}

The `auth.type` setting selects how users sign in to the UI and API. It accepts four values — `DISABLED`, `LOGIN_FORM`, `OAUTH2`, and `LDAP` — described on the pages below. Server-to-server (S2S) is a separate API-key mechanism layered on top of whichever mode you choose.

### Contents

* [Disable authentication](/configuration-and-deployment/enable-security/authentication/disabled-authentication) — the shipped default; permit-all, no sign-in
* [Login form](/configuration-and-deployment/enable-security/authentication/login-form)
* [OAUTH2/OIDC](/configuration-and-deployment/enable-security/authentication/oauth2-oidc)
* [LDAP](/configuration-and-deployment/enable-security/authentication/ldap)
* [Server-to-server (S2S)](/configuration-and-deployment/enable-security/authentication/s2s) — API-key access for automated clients. A valid key grants full administrator authority on every endpoint, independent of the `auth.type` mode you run.


# Disabled authentication

Disable platform authentication entirely — the default configuration for local deployments and demo sandboxes where no security is required.

ODD Platform allows to disable authentication at all. This is useful when you want to deploy platform locally and don't need any security configured. This is the default configuration and no additional settings are required.

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    type: DISABLED
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_TYPE=DISABLED
```

{% endtab %}
{% endtabs %}

{% hint style="danger" %}
**DO NOT** use this method in your production environment!
{% endhint %}

The rest of this page enumerates what an anonymous caller on the network can reach under `auth.type: DISABLED`. The intent is not to soften the warning above — it is to give operators the specific surface area so they understand the warning's scope.

## What's anonymously reachable

The DISABLED-mode security configuration accepts every exchange (`.anyExchange().permitAll()`) — every HTTP endpoint on the platform is reachable to an unauthenticated caller. The surfaces below are the load-bearing ones an operator should know about before exposing a DISABLED-mode deployment on any network broader than `localhost`:

* **`GET /api/identity/whoami`** returns a synthetic admin identity: `{ "username": "admin", "permissions": [ … every Permission value defined on the platform … ] }`. The permission set is built from `Permission.values()`, so any new platform capability added in a future release is **automatically** granted to this anonymous synthetic admin — there is no per-permission opt-in. Every UI control gated by a permission unlocks; every state-changing endpoint accepts mutations from any caller on the network.
* **`GET /api/appInfo`** returns the precise platform version (`buildProperties.getVersion()`) and the active `auth.type` value, with no authentication. The `authType` field shape is ODD-specific — a passive network scanner can confirm the deployment IS ODD Platform, learn its version (CVE-scoping), and learn the auth-mode value in one unauthenticated `GET`.
* **`GET /actuator/env`** returns the **schema** of configured properties — which OAuth2 providers are wired (the property-key prefixes), whether LDAP is configured, that a JDBC datasource is configured (the `spring.datasource.url` key, not its value). The actuator namespace `/actuator/**` is whitelisted in Spring Security in every auth mode (not just DISABLED), and the default `management.endpoints.web.exposure.include` setting includes `env`. Property *values* are masked (`******`) for every caller by default (`show-values` defaults to `NEVER`), but the property **keys and sources** are still informative for an attacker mapping the deployment.
* **Every `/api/**` endpoint** is reachable as a mutation surface. Owner CRUD, Policy / Role / Permission mutations, Lookup-table data row mutations, attachment uploads, custom-metadata writes, business-glossary term writes — every state-changing endpoint accepts requests with no auth. The platform's data integrity under DISABLED depends entirely on operator-side network isolation.

## Fingerprint matrix (passive recon)

An unauthenticated caller can determine the platform's auth mode in **one** request by observing the response shape of `GET /api/identity/whoami`. The four mode-distinguishing responses:

| `auth.type`       | Response to anonymous `GET /api/identity/whoami`             | What it tells the caller                          |
| ----------------- | ------------------------------------------------------------ | ------------------------------------------------- |
| `DISABLED`        | `200 OK` + `{ "username": "admin", "permissions": [ ... ] }` | Mode known; full admin reach to anonymous caller. |
| `LOGIN_FORM`      | `302 Found` → `/login`                                       | Mode known; credentials gating exists.            |
| `OAUTH2` / `LDAP` | `401 Unauthorized`                                           | Mode known; OIDC / LDAP auth required.            |

DISABLED is the easiest mode to fingerprint anonymously on the network. The combination with `GET /api/appInfo` (which surfaces the auth-mode value directly) means an anonymous network scan can confirm-ODD + version + auth-mode + reach the admin endpoint in a handful of unauthenticated requests.

## Reserved usernames

The DISABLED-mode synthetic identity uses the literal lowercase string `admin`; the S2S authentication filter uses the literal uppercase string `ADMIN`. The platform's user-to-owner mapping table compares names case-sensitively. Avoid provisioning operator-managed users with either of these literal names in `LOGIN_FORM`, `LDAP`, or any OAuth2 provider — a user named `admin` or `ADMIN` collides with the synthetic identities and inherits whatever owner mapping the synthetic principal resolves to. See the matching note on the [Server-to-server (S2S) authentication](/configuration-and-deployment/enable-security/authentication/s2s#operator-caveats) page.

## Migrating away from DISABLED

When you flip `auth.type` from `DISABLED` to `LOGIN_FORM`, `OAUTH2`, or `LDAP`, the synthetic-admin response from `GET /api/identity/whoami` vanishes — anonymous callers stop seeing the admin grant. For the cross-mode comparison of how each target mode grants ADMIN, see [Admin promotion across providers](/configuration-and-deployment/enable-security/admin-promotion). **Before flipping**, audit:

* Any existing `Owner` rows whose `OIDC_USERNAME` matches the literal `admin` or `ADMIN` — these will collide with the DISABLED synthetic identity (or with S2S — see [S2S](/configuration-and-deployment/enable-security/authentication/s2s)) once the platform starts attributing real user names through the real auth chain.
* Any RBAC `Policy` or `Role` you authored while running DISABLED — they were never consulted under DISABLED (every caller was admin), so they take effect for the first time when the migration completes; mis-configurations that were silent under DISABLED start to bite immediately.
* Network exposure that you tolerated under DISABLED on the assumption that the deployment was only-on-localhost — verify that the network boundary is still where you think it is before the synthetic admin disappears.


# Login form

Simplest auth mode — username/password credentials via auth.login-form-credentials. All login-form users receive ADMIN privileges; not suitable for production deployments.

This is the simplest form of authentication provided by ODD Platform.

User credentials are set by defining the `auth.login-form-credentials` property in the format `username1:password1,username2:password2,...`. All users authenticated through this method receive ADMIN privileges in the platform.

{% hint style="danger" %}
**The shipped configuration contains the default credentials `admin:admin,root:root`.** If you enable `LOGIN_FORM` authentication without overriding `auth.login-form-credentials`, the platform will accept logins from `admin/admin` and `root/root` — and both accounts have full ADMIN privileges. Change these defaults before any non-local deployment.

To override, either set `auth.login-form-credentials` explicitly (YAML or the `AUTH_LOGIN_FORM_CREDENTIALS` environment variable, shown below) or switch to `OAUTH2` or `LDAP` authentication. For any production deployment, prefer OAUTH2 or LDAP — `LOGIN_FORM` stores credentials in plain text in the platform configuration and does not support rotation, session revocation, or MFA.
{% endhint %}

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    type: LOGIN_FORM
    login-form-credentials: susan:susan_password,dave:dave_password
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_TYPE=LOGIN_FORM
AUTH_LOGIN_FORM_CREDENTIALS=susan:susan_password,dave:dave_password
```

{% endtab %}
{% endtabs %}

## Authorization posture under `LOGIN_FORM`

`LOGIN_FORM` is dev/demo-oriented authentication. Three platform-side defaults diverge from the production modes (`OAUTH2`, `LDAP`) in ways that materially change what an operator should expect from a `LOGIN_FORM` deployment — none of them is a bug, but each is load-bearing on operator decisions. For the cross-mode comparison of how every auth mode grants ADMIN (including LOGIN\_FORM's "every user is ADMIN" stance), see [Admin promotion across providers](/configuration-and-deployment/enable-security/admin-promotion).

### Policy and Role tables are not consulted

Every user authenticated through `LOGIN_FORM` is granted `ADMIN` authority at login. The Spring Security chain in this mode does not wire the `AuthorizationCustomizer` that translates the `SecurityConstants.SECURITY_RULES` table into per-request authorization checks; under `LOGIN_FORM`, the chain is `.pathMatchers("/**").authenticated()` and nothing more. The Policies, Roles, and Permission grants an operator authors via the [Management → Policies / Roles UI](/configuration-and-deployment/enable-security/authorization/policies) are stored in the database but never gate the live auth chain — they take effect only after switching `auth.type` to `OAUTH2` or `LDAP`.

**Operator consequence:** evaluating a non-ADMIN Policy in `LOGIN_FORM` mode does not test what will happen in `OAUTH2` / `LDAP`. Do Policy / Role testing on the same auth mode you will run in production.

### CSRF protection is disabled

The `LOGIN_FORM` filter chain unconditionally disables CSRF (`http.csrf(...::disable)`). A signed-in operator visiting an attacker-controlled page can have state-changing `POST` / `PUT` / `DELETE` requests issued to the platform on their behalf, because the browser automatically attaches the session cookie. The platform also does not stamp `SameSite=Strict` or `Secure` cookie attributes on its default session cookies — see [Configure ODD Platform → Session and cookie configuration](/configuration-and-deployment/odd-platform) — so the protections that would normally compensate for missing CSRF defence are also absent in the default deployment.

**Operator consequence:** run `LOGIN_FORM` only behind a TLS-terminating reverse proxy that stamps `Secure` and `SameSite=Strict` externally, or restrict the deployment to a trusted network. Either is acceptable for dev/demo; neither is production-grade.

### `auth.login-form-redirect` is operator-trusted

After a successful sign-in, the platform sends the user to the URL configured in `auth.login-form-redirect` (or to `/` when the property is empty). The redirect target is parsed via `URI.create(...)` with no scheme allowlist, no host allowlist, and no platform-base-URL validation. An operator who templates this value from a less-trusted upstream pipeline (a CI variable, a downstream Helm value derived from arbitrary env-var input) must ensure the provenance of the input.

**Operator consequence:** treat `auth.login-form-redirect` as a high-trust string. Either set it to a fixed value at the deployment manifest, or apply your own allowlist in the configuration pipeline that produces the platform's environment variables.

## Cross-mode user-name collision (activity feed read paths)

The platform's [activity-feed](/features/active-platform-features/activity-feed) read paths join the `USER_OWNER_MAPPING` table on `OIDC_USERNAME` only — the join does **not** discriminate by auth provider. If your deployment has historically used multiple auth modes (for example, started on `LOGIN_FORM` with seed users, then enabled `LDAP` or `OAUTH2`), a user named `alice` who signed in via `LOGIN_FORM` and a user named `alice` who signed in via `LDAP` can resolve to the same `OwnerPojo` when activity-feed rows are rendered. The most recent `USER_OWNER_MAPPING` row for the literal username wins each lookup; results are not deterministic across replicas.

**Operator mitigation today:** never reuse usernames across auth modes when migrating. If you migrate from `LOGIN_FORM` to `LDAP` or `OAUTH2`, delete the `USER_OWNER_MAPPING` rows for the `LOGIN_FORM` usernames before introducing same-named users in the new mode.

**Forensic note:** do not rely on activity-feed Owner attribution for incident response in multi-mode deployments without verifying the auth mode of the actor through the underlying `activity.created_by` value.

A platform-side fix that discriminates the join by `PROVIDER` is tracked upstream. The same caveat applies to deployments running `LDAP` on top of an earlier `LOGIN_FORM` history — see the matching note on the [LDAP](/configuration-and-deployment/enable-security/authentication/ldap#cross-mode-user-name-collision-activity-feed-read-paths) page.


# OAUTH2/OIDC

Configure ODD Platform to authenticate users via OAuth2/OIDC against AWS Cognito, GitHub, Google, Azure AD, Okta, Keycloak, or any custom OIDC-compliant identity provider.

ODD Platform supports different OIDC/OAuth2 providers. Currently there are:

* [AWS Cognito](#aws-cognito)
* [Github](#github)
* [Google](#google)
* [Azure AD](#azure-a-d)
* [Okta](#other-oidc-providers)
* [Keycloak](#other-oidc-providers)
* [Custom OIDC provider](#other-oidc-providers)

It is possible to have multiple providers at the same time (e.g. you want to allow to authenticate users from Github and Google, or from multiple Cognito user pools). Configuration properties name for each provider must fit the pattern `auth.oauth2.client.{client_id}.{client_parameter}`, where `client_id` is provider identifier.

There are some common parameters which are used across all providers:

* `auth.type`. Must be set to OAUTH2
* `auth.oauth2.client.{client-id}.provider`. Provider code, which helps application to understand which provider is used.
* `auth.oauth2.client.{client-id}.client-id`. Client ID obtained from provider
* `auth.oauth2.client.{client-id}.client-secret`. Client secret obtained from provider
* `auth.oauth2.client.{client-id}.client-name`. Custom name, which will be shown on UI in case of multiple providers enabled. (optional)
* `auth.oauth2.client.{client-id}.redirect-uri`. Redirect URL. Must be defined as `{domain}/login/oauth2/code/{client-id}`
* `auth.oauth2.client.{client-id}.scope`. Authorization scopes which are allowed for application

{% hint style="warning" %}
For all OIDC providers **openid** scope must be included!
{% endhint %}

* `auth.oauth2.client.{client-id}.issuer-uri`. URI that can either be an OpenID Connect discovery endpoint or an OAuth 2.0 Authorization Server Metadata endpoint defined by RFC 8414.

{% hint style="info" %}
Given that the issuer uri is composed of a host and a path, ODD Platform tries to fetch information, calling following URLs:

* host/.well-known/openid-configuration/path
* issuer/.well-known/openid-configuration
* host/.well-known/oauth-authorization-server/path

If you don't have issuer uri or if you want to override some values, there are special properties, which should be defined:

* `auth.oauth2.client.{client-id}.authorization-uri.`Authorization URI for the provider.
* `auth.oauth2.client.{client-id}.token-uri.`Token URI for the provider.
* `auth.oauth2.client.{client-id}.user-info-uri.`User info URI for the provider.
* `auth.oauth2.client.{client-id}.jwk-set-uri.`JWK set URI for the provider.

If issuer uri can provide this info above parameters might be skipped.
{% endhint %}

* `auth.oauth2.client.{client-id}.username-attribute`. Defines which token claim should be picked as username in ODD Platform
* `auth.oauth2.client.{client-id}.admin-attribute`. Defines which token claim is responsible for admin principal
* `auth.oauth2.client.{client-id}.admin-principals`. List of users, who will have ADMIN role on login (for detailed explanation please check the [Roles](/configuration-and-deployment/enable-security/authorization/roles) section).
* `auth.oauth2.client.{client-id}.pkce`. Optional Boolean (default unset, i.e. disabled). Enables [Proof Key for Code Exchange (RFC 7636)](https://datatracker.ietf.org/doc/html/rfc7636) for the authorization code flow. When `pkce: true` **and** `client-secret` is empty, the platform registers the client as a **public** OAuth2 client (`client_authentication_method=none`) and PKCE protects the code exchange. When `client-secret` is set, the platform always uses confidential-client authentication and the `pkce` flag has no effect on the registration. Most commonly required by Keycloak — see the [Keycloak with PKCE](#keycloak-with-pkce) example below.

## Admin-detection per-provider matrix

The configuration POJO that backs `auth.oauth2.client.{id}` is uniform across every provider, but each provider's runtime handler reads a different subset of the configured fields. The matrix below summarises how `admin-principals` and `admin-groups` actually behave for every supported provider — the silent-no-op rows in particular catch operators by surprise because the configuration loads without error. For the same comparison across **all** auth modes (not just OAuth2), see [Admin promotion across providers](/configuration-and-deployment/enable-security/admin-promotion).

| Provider        | Admin detection in code                                                                                                                         | Match semantic                                               | Silent caveats                                                                                                                                                    |
| --------------- | ----------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **AWS Cognito** | `admin-principals` (email / configured `username-attribute`) **and** `admin-groups` (against the `cognito:groups` claim)                        | exact match on both                                          | —                                                                                                                                                                 |
| **GitHub**      | `admin-principals` (login) **before** the `organization-name` check; `admin-groups` after, against team names returned by `/user/teams`         | exact (principals); **case-insensitive full match** (groups) | `admin-principals` **bypasses** `organization-name`; GitHub Enterprise Server is **not supported** — `api.github.com` is hard-coded in the handler                |
| **Google**      | `admin-principals` (email by default; overridable via `admin-attribute`)                                                                        | exact match                                                  | **`admin-groups` is a silent no-op** — the field binds without error but the handler never reads it; use `admin-principals` or `admin-attribute`                  |
| **Azure AD**    | `admin-principals` (against `admin-attribute`) and `admin-groups` (against the `roles` claim by default; switch to `groups` via `groups-claim`) | exact match                                                  | —                                                                                                                                                                 |
| **Okta**        | `admin-principals` always (against the `admin-attribute` / `username-attribute` claim); `admin-groups` **only when `groups-claim` is set**      | case-insensitive full match                                  | `admin-groups` is inert unless `groups-claim` is configured — the generic OIDC handler has no default groups claim. `admin-principals` works with no extra config |
| **Keycloak**    | same as Okta — `admin-principals` always; `admin-groups` only when `groups-claim` is set                                                        | case-insensitive full match                                  | same as Okta — `admin-groups` needs `groups-claim`                                                                                                                |
| **Custom OIDC** | `admin-principals` always; `admin-groups` only when `groups-claim` is set                                                                       | case-insensitive full match                                  | no default groups claim — set `groups-claim` to use `admin-groups`; `admin-principals` needs no extra config                                                      |

**Reading the matrix:** if your provider row says "silent caveats", the configured `admin-groups` / `admin-principals` are not enforced the way the property names suggest. The provider-specific sections below repeat each caveat at the point of configuration; this matrix is the single comparison view.

#### AWS Cognito

AWS Cognito provider can be configured using common oauth properties and couple of provider specific properties:

* `auth.oauth2.client.{client-id}.admin-groups`. List of admin groups. Groups are retrieved from `cognito:groups` token claim.
* `auth.oauth2.client.{client-id}.logout-uri`. Application will be redirected to this URI after user logout for removing session on cognito side. Please check [AWS Docs](https://docs.aws.amazon.com/cognito/latest/developerguide/logout-endpoint.html) for more details.

{% hint style="info" %}
`auth.oauth2.client.{client-id}.username-attribute` is `cognito:username` by default
{% endhint %}

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    type: OAUTH2
    oauth2:
        client:
            cognito:
                provider: cognito
                client-id: {client_id}
                client-secret: {client_secret}
                scope: openid
                redirect-uri: {host}/login/oauth2/code/cognito
                client-name: Cognito
                issuer-uri: {issuer_uri}
                logout-uri: {logout_uri}
                admin-groups: admin
                admin-attribute: cognito:username
                admin-principals: john,david
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_TYPE=OAUTH2
AUTH_OAUTH2_CLIENT_COGNITO_PROVIDER=cognito
AUTH_OAUTH2_CLIENT_COGNITO_CLIENT_ID={client_id}
AUTH_OAUTH2_CLIENT_COGNITO_CLIENT_SECRET={client_secret}
AUTH_OAUTH2_CLIENT_COGNITO_SCOPE=openid
AUTH_OAUTH2_CLIENT_COGNITO_REDIRECT_URI={host}/login/oauth2/code/cognito
AUTH_OAUTH2_CLIENT_COGNITO_CLIENT_NAME=Cognito
AUTH_OAUTH2_CLIENT_COGNITO_ISSUER_URI={issuer_uri}
AUTH_OAUTH2_CLIENT_COGNITO_LOGOUT_URI={logout_uri}
AUTH_OAUTH2_CLIENT_COGNITO_ADMIN_GROUPS=admin
AUTH_OAUTH2_CLIENT_COGNITO_ADMIN_ATTRIBUTE=cognito:username
AUTH_OAUTH2_CLIENT_COGNITO_ADMIN_PRINCIPALS=john,david
```

{% endtab %}
{% endtabs %}

#### Github

You can use Github as your OAUTH provider. ODD platform can retrieve info about user organizations and teams and use it for granting ADMIN permissions (for detailed explanation please check the [Roles](/configuration-and-deployment/enable-security/authorization/roles) section). There are some github specific properties, which can be set:

* `auth.oauth2.client.{client-id}.organization-name`. Restricts login only for users from this particular organization
* `auth.oauth2.client.{client-id}.admin-groups`. Grants admin privilegies for users who are members of these teams, which are inside above organization

{% hint style="warning" %}
In order to retrieve organization information from github, **user:read** and **read:org** scopes must be included
{% endhint %}

{% hint style="danger" %}
**`admin-principals` bypasses `organization-name`.** The handler checks `admin-principals` before the `organization-name` gate. A login matched in `admin-principals` is granted ADMIN regardless of organization membership — so an attacker who can register the matching GitHub login on github.com obtains a platform-ADMIN backdoor if a typo or stale entry sits in the list. Audit `admin-principals` for unowned or guessable usernames before relying on `organization-name` for boundary enforcement.
{% endhint %}

{% hint style="warning" %}
**`admin-groups` is a case-insensitive full team-name match — not a substring match.** `admin-groups: [admins]` promotes members of a team named exactly `admins` (case ignored, so `Admins` and `ADMINS` match too) and does **not** match `team-admins`, `admins-readonly`, or `data-admins`. Enter each admin team's name exactly as it appears in GitHub. This is consistent with every other provider — across all modes, `admin-groups` / `admin-principals` matching is full-value, case-insensitive equality (no substring, no prefix); see the [admin-promotion comparison](/configuration-and-deployment/enable-security/admin-promotion).
{% endhint %}

{% hint style="warning" %}
**GitHub Enterprise Server (GHES) is not supported.** The GitHub handler hard-codes `https://api.github.com` for its `/user/orgs` and `/user/teams` calls — there is no configuration knob to point at a GHES instance. Deployments using `https://github.example.com/api/v3` see DNS/cert failures on the post-login enrichment. A configurable base URL is tracked upstream; until then, use a different OAuth provider for GHES-only deployments.
{% endhint %}

{% hint style="warning" %}
**A GitHub username rename orphans the user's owner association.** ODD identifies a GitHub user by the mutable `login` — the claim selected by `user-name-attribute` (`login` in the example below) — not the stable numeric account id, and the owner mapping is keyed on that login. When a user renames their GitHub account they sign in as a **new** identity: their previous owner association is silently orphaned — their **My Objects** empties and their ownership strands under the old name — with no automatic re-link. Plan a manual update of the user-owner mapping around any GitHub login rename. Note also that GitHub releases the old login after 90 days, so it can later be claimed by someone else.
{% endhint %}

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    type: OAUTH2
    oauth2:
        client:
            github:
                provider: github
                client-id: {client_id}
                client-secret: {client_secret}
                scope: user:read,read:org
                redirect-uri: {host}/login/oauth2/code/github
                client-name: Github
                authorization-uri: https://github.com/login/oauth/authorize
                token-uri: https://github.com/login/oauth/access_token
                user-info-uri: https://api.github.com/user
                user-name-attribute: login
                organization-name: my-cool-org
                admin-groups: admin
                admin-attribute: login
                admin-principals: john,david
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_TYPE=OAUTH2
AUTH_OAUTH2_CLIENT_GITHUB_PROVIDER=github
AUTH_OAUTH2_CLIENT_GITHUB_CLIENT_ID={client_id}
AUTH_OAUTH2_CLIENT_GITHUB_CLIENT_SECRET={client_secret}
AUTH_OAUTH2_CLIENT_GITHUB_SCOPE=user:read,read:org
AUTH_OAUTH2_CLIENT_GITHUB_REDIRECT_URI={host}/login/oauth2/code/github
AUTH_OAUTH2_CLIENT_GITHUB_CLIENT_NAME=Github
AUTH_OAUTH2_CLIENT_GITHUB_AUTHORIZATION_URI=https://github.com/login/oauth/authorize
AUTH_OAUTH2_CLIENT_GITHUB_TOKEN_URI=https://github.com/login/oauth/access_token
AUTH_OAUTH2_CLIENT_GITHUB_USER_INFO_URI=https://api.github.com/user
AUTH_OAUTH2_CLIENT_GITHUB_USER_NAME_ATTRIBUTE=login
AUTH_OAUTH2_CLIENT_GITHUB_ORGANIZATION_NAME=my-cool-org
AUTH_OAUTH2_CLIENT_GITHUB_ADMIN_GROUPS=admin
AUTH_OAUTH2_CLIENT_GITHUB_ADMIN_ATTRIBUTE=login
AUTH_OAUTH2_CLIENT_GITHUB_ADMIN_PRINCIPALS=john,david
```

{% endtab %}
{% endtabs %}

#### Google

ODD Platform allows to authenticate users via Google. You can restrict users to login under your organization domain. This is controlled by `auth.oauth2.client.{client-id}.allowed-domain` property.

{% hint style="danger" %}
**`admin-groups` is a silent no-op for the Google provider.** The Google handler does not read the `admin-groups` list — the field binds without error but every member of a configured admin-group remains a regular `USER`. Promote individual operators to ADMIN via `admin-principals` (email by default) or via a custom claim configured through `admin-attribute`. Track upstream for a boot-time warning when `admin-groups` is set with the Google provider.
{% endhint %}

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    type: OAUTH2
    oauth2:
        client:
            google:
                provider: google
                client-id: {client_id}
                client-secret: {client_secret}
                scope: openid,profile,email
                redirect-uri: {host}/login/oauth2/code/google
                client-name: Google
                issuer-uri: https://accounts.google.com
                user-name-attribute: name
                admin-attribute: email
                admin-principals: john@odd.com,david@odd.com
                allowed-domain: odd.com
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_TYPE=OAUTH2
AUTH_OAUTH2_CLIENT_GOOGLE_PROVIDER=google
AUTH_OAUTH2_CLIENT_GOOGLE_CLIENT_ID={client_id}
AUTH_OAUTH2_CLIENT_GOOGLE_CLIENT_SECRET={client_secret}
AUTH_OAUTH2_CLIENT_GOOGLE_SCOPE=openid,profile,email
AUTH_OAUTH2_CLIENT_GOOGLE_REDIRECT_URI={host}/login/oauth2/code/google
AUTH_OAUTH2_CLIENT_GOOGLE_CLIENT_NAME=Google
AUTH_OAUTH2_CLIENT_GOOGLE_ISSUER_URI=https://accounts.google.com
AUTH_OAUTH2_CLIENT_GOOGLE_USER_NAME_ATTRIBUTE=name
AUTH_OAUTH2_CLIENT_GOOGLE_ADMIN_ATTRIBUTE=email
AUTH_OAUTH2_CLIENT_GOOGLE_ADMIN_PRINCIPALS=john@odd.com,david@odd.com
AUTH_OAUTH2_CLIENT_GOOGLE_ALLOWED_DOMAIN=odd.com
```

{% endtab %}
{% endtabs %}

#### Azure AD

ODD Platform supports integration with Azure Active Directory (Azure AD) using OAuth2/OpenID Connect (OIDC). Azure AD applications can be registered in one of two modes:

* **Single-tenant** — only users from one specific Azure AD tenant can sign in. Use this for organisation-internal deployments.
* **Multi-tenant** — users from any Azure AD tenant can sign in. Use this when the platform is hosted as a service for several organisations.

The two modes share the same properties; they differ only in how the `issuer-uri`, `authorization-uri`, `token-uri`, and `logout-uri` are constructed. Examples for both forms are given below.

**Prerequisites: Azure AD app registration**

Before configuring ODD Platform, register an application in Azure AD:

1. Go to **Azure Active Directory** → **App registrations** → **New registration**.
2. Choose the supported account types (single-tenant vs. multi-tenant) that match the deployment.
3. Add a **Web** redirect URI: `{host}/login/oauth2/code/azure`.
4. Under **Certificates & secrets**, generate a client secret and store its value — it cannot be viewed again later.
5. Under **API permissions**, add the following Microsoft Graph **delegated** permissions and grant admin consent: `openid`, `offline_access`, `User.Read`. Add `email` and `profile` as well if the `profile`/`email` scopes are requested below.
6. (Optional) To use `admin-groups`, choose one of the following:
   * **Azure AD App Roles** (default, recommended) — under **App roles**, create the roles you want to grant ADMIN (for example `Admins`, `Managers`), then assign users or groups to those roles. Azure will emit the role values in the `roles` claim of the ID token, which is what ODD Platform reads by default.
   * **Azure AD security groups** — under **Token configuration** → **Add groups claim**, include the `groups` claim in the ID token. You must also set `groups-claim: groups` in the ODD configuration (see the note under `admin-groups` below), because the Azure handler reads from `roles` unless told otherwise.
7. Note the **Application (client) ID** and **Directory (tenant) ID** — both are needed by the configuration below.

**Single-tenant configuration**

Use the tenant-specific `issuer-uri`; `{azure_tenant_id}` is your Directory (tenant) ID. Spring Security will discover `authorization-uri`, `token-uri`, `jwk-set-uri`, and `user-info-uri` from the issuer's OpenID Connect discovery document, so they do not need to be set explicitly. `jwk-set-uri` is still shown in the example because it can be required when the discovery endpoint is unreachable (for example, from air-gapped networks).

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    type: OAUTH2
    oauth2:
        client:
            azure:
                provider: azure
                client-id: {azure_client_id}
                azure-tenant-id: {azure_tenant_id}
                client-secret: {azure_client_secret}
                client-name: Azure AD
                scope:
                  - openid
                  - offline_access
                  - profile
                  - email
                  - https://graph.microsoft.com/User.Read
                redirect-uri: {host}/login/oauth2/code/azure
                issuer-uri: https://login.microsoftonline.com/{azure_tenant_id}/v2.0
                jwk-set-uri: https://login.microsoftonline.com/{azure_tenant_id}/discovery/v2.0/keys
                user-info-uri: https://graph.microsoft.com/oidc/userinfo
                logout-uri: https://login.microsoftonline.com/{azure_tenant_id}/oauth2/v2.0/logout
                user-name-attribute: email
                admin-attribute: email
                admin-principals:
                  - admin1@yourdomain.com
                  - admin2@yourdomain.com
                admin-groups:
                  - Admins
                  - Managers
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_TYPE=OAUTH2
AUTH_OAUTH2_CLIENT_AZURE_PROVIDER=azure
AUTH_OAUTH2_CLIENT_AZURE_CLIENT_ID={azure_client_id}
AUTH_OAUTH2_CLIENT_AZURE_AZURE_TENANT_ID={azure_tenant_id}
AUTH_OAUTH2_CLIENT_AZURE_CLIENT_SECRET={azure_client_secret}
AUTH_OAUTH2_CLIENT_AZURE_CLIENT_NAME=Azure AD
AUTH_OAUTH2_CLIENT_AZURE_SCOPE=openid,offline_access,profile,email,https://graph.microsoft.com/User.Read
AUTH_OAUTH2_CLIENT_AZURE_REDIRECT_URI={host}/login/oauth2/code/azure
AUTH_OAUTH2_CLIENT_AZURE_ISSUER_URI=https://login.microsoftonline.com/{azure_tenant_id}/v2.0
AUTH_OAUTH2_CLIENT_AZURE_JWK_SET_URI=https://login.microsoftonline.com/{azure_tenant_id}/discovery/v2.0/keys
AUTH_OAUTH2_CLIENT_AZURE_USER_INFO_URI=https://graph.microsoft.com/oidc/userinfo
AUTH_OAUTH2_CLIENT_AZURE_LOGOUT_URI=https://login.microsoftonline.com/{azure_tenant_id}/oauth2/v2.0/logout
AUTH_OAUTH2_CLIENT_AZURE_USER_NAME_ATTRIBUTE=email
AUTH_OAUTH2_CLIENT_AZURE_ADMIN_ATTRIBUTE=email
AUTH_OAUTH2_CLIENT_AZURE_ADMIN_PRINCIPALS=admin1@yourdomain.com,admin2@yourdomain.com
AUTH_OAUTH2_CLIENT_AZURE_ADMIN_GROUPS=Admins,Managers
```

{% endtab %}
{% endtabs %}

**Multi-tenant configuration**

For a multi-tenant application, the OpenID Connect discovery document is not served under a tenant-specific URL, so `issuer-uri` cannot be used. Instead, override `authorization-uri`, `token-uri`, `jwk-set-uri`, and `logout-uri` to point at the `organizations` endpoint (use `common` if the app should also accept personal Microsoft accounts). `azure-tenant-id` must still be set to the tenant that owns the app registration.

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    type: OAUTH2
    oauth2:
        client:
            azure:
                provider: azure
                client-id: {azure_client_id}
                azure-tenant-id: {azure_tenant_id}
                client-secret: {azure_client_secret}
                client-name: Azure AD
                scope:
                  - openid
                  - offline_access
                  - profile
                  - email
                  - https://graph.microsoft.com/User.Read
                redirect-uri: {host}/login/oauth2/code/azure
                authorization-uri: https://login.microsoftonline.com/organizations/oauth2/v2.0/authorize
                token-uri: https://login.microsoftonline.com/organizations/oauth2/v2.0/token
                jwk-set-uri: https://login.microsoftonline.com/organizations/discovery/v2.0/keys
                user-info-uri: https://graph.microsoft.com/oidc/userinfo
                logout-uri: https://login.microsoftonline.com/organizations/oauth2/v2.0/logout
                user-name-attribute: email
                admin-attribute: email
                admin-principals:
                  - admin1@yourdomain.com
                  - admin2@yourdomain.com
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_TYPE=OAUTH2
AUTH_OAUTH2_CLIENT_AZURE_PROVIDER=azure
AUTH_OAUTH2_CLIENT_AZURE_CLIENT_ID={azure_client_id}
AUTH_OAUTH2_CLIENT_AZURE_AZURE_TENANT_ID={azure_tenant_id}
AUTH_OAUTH2_CLIENT_AZURE_CLIENT_SECRET={azure_client_secret}
AUTH_OAUTH2_CLIENT_AZURE_CLIENT_NAME=Azure AD
AUTH_OAUTH2_CLIENT_AZURE_SCOPE=openid,offline_access,profile,email,https://graph.microsoft.com/User.Read
AUTH_OAUTH2_CLIENT_AZURE_REDIRECT_URI={host}/login/oauth2/code/azure
AUTH_OAUTH2_CLIENT_AZURE_AUTHORIZATION_URI=https://login.microsoftonline.com/organizations/oauth2/v2.0/authorize
AUTH_OAUTH2_CLIENT_AZURE_TOKEN_URI=https://login.microsoftonline.com/organizations/oauth2/v2.0/token
AUTH_OAUTH2_CLIENT_AZURE_JWK_SET_URI=https://login.microsoftonline.com/organizations/discovery/v2.0/keys
AUTH_OAUTH2_CLIENT_AZURE_USER_INFO_URI=https://graph.microsoft.com/oidc/userinfo
AUTH_OAUTH2_CLIENT_AZURE_LOGOUT_URI=https://login.microsoftonline.com/organizations/oauth2/v2.0/logout
AUTH_OAUTH2_CLIENT_AZURE_USER_NAME_ATTRIBUTE=email
AUTH_OAUTH2_CLIENT_AZURE_ADMIN_ATTRIBUTE=email
AUTH_OAUTH2_CLIENT_AZURE_ADMIN_PRINCIPALS=admin1@yourdomain.com,admin2@yourdomain.com
```

{% endtab %}
{% endtabs %}

#### Notes:

* Ensure the `openid` scope is always included, as it is mandatory for OIDC.
* The `azure-tenant-id` should correspond to the Azure AD tenant that owns the app registration.
* The `jwk-set-uri` is mandatory for Azure to function correctly with ODD Platform when the discovery endpoint is unreachable.
* `logout-uri` is the Azure AD OpenID Connect logout endpoint — `https://login.microsoftonline.com/{azure_tenant_id}/oauth2/v2.0/logout` for single-tenant and `https://login.microsoftonline.com/organizations/oauth2/v2.0/logout` (or the `common` variant if the app also accepts personal Microsoft accounts) for multi-tenant. On logout, ODD Platform redirects the browser here so Azure AD can end its own session and then return the user to the Platform.

{% hint style="warning" %}
`logout-uri` must be set for Azure SSO. The Azure-specific logout handler calls `URI.create(provider.getLogoutUri())`; leaving `logout-uri` unset raises a `NullPointerException` and the logout flow returns a 500 response. Always include `logout-uri` when configuring the `azure` provider.
{% endhint %}

* `admin-principals` is the list of user identifiers (matched against the `admin-attribute` claim, `email` in the examples above) that will be granted the ADMIN role on login.
* `admin-groups` grants the ADMIN role to every user whose token contains one of the listed values. **By default, ODD Platform's Azure handler reads these values from the `roles` claim**, which Azure AD populates from **App roles** assigned to the user. The values in `admin-groups` must match the app role `value` fields, not Azure AD display names.
  * To grant ADMIN based on Azure AD **security group** membership instead, set `groups-claim: groups` in the Azure configuration and add the `groups` claim to the ID token in Azure (**Token configuration** → **Add groups claim**). The `admin-groups` list then matches against values emitted in the `groups` claim (group object IDs by default — switch the Azure claim output to `Group Name` in the Token configuration dialog if you want to match on group display names).
* If an external user's login doesn't provide the email attribute by default, ensure that the user exists as an external guest in Azure AD associated with an email.

**Troubleshooting Tips:**

* If you encounter errors regarding the missing `email` attribute, ensure the user exists in Azure AD as a properly configured external guest user with an email attribute.
* For single-tenant deployments, always verify that `issuer-uri`, `jwk-set-uri`, `user-info-uri`, and `logout-uri` correspond to your tenant ID.
* If logout returns a 500 error or never completes, verify that `logout-uri` is set and matches your single-tenant / multi-tenant choice. An unset `logout-uri` triggers a `NullPointerException` in the Azure logout handler; the browser sees a 500 while the user remains signed in on both sides.
* If `admin-groups` has no effect, check which claim is being read:
  * **App Roles (default)** — decode the ID token at `jwt.ms` or equivalent; confirm the `roles` claim is present and contains the app-role `value` fields that your `admin-groups` list references. If the `roles` claim is absent, verify that you have assigned users to app roles under **Enterprise applications** → your app → **Users and groups**.
  * **Security groups** — confirm that `groups-claim: groups` is set in the ODD configuration (without this, `admin-groups` is matched against `roles`, not `groups`), and that the `groups` claim is emitted by the Azure token configuration.

#### Other OIDC providers

ODD Platform doesn't have any specific parameters for other providers, so they can be easily configured using default parameters. You can check examples below for OKTA and Keycloak OIDC providers.

{% hint style="info" %}
**Okta, Keycloak, and any other "Custom OIDC" provider DO promote to ADMIN via `admin-principals`.** These providers fall through to the generic `CustomOIDCUserHandler`, which evaluates `admin-principals` on every login: a user whose `admin-attribute` (or `username-attribute`) claim matches a configured `admin-principals` entry — case-insensitive, full match — is promoted to ADMIN with no extra configuration. `admin-groups` is also honoured, **but only if you set `groups-claim` explicitly**, because the generic handler has no default groups claim. With neither `admin-principals` nor (`groups-claim` + `admin-groups`) configured, every authenticated user is granted `USER` and promotion is a manual Owner-Role binding (an ADMIN-equivalent [Role](/configuration-and-deployment/enable-security/authorization/roles) bundle) through the Management UI. The Okta and Keycloak YAML examples below set `admin-principals`, consistent with this.
{% endhint %}

{% tabs %}
{% tab title="OKTA YAML" %}

```yaml
auth:
    type: OAUTH2
    oauth2:
        client:
            okta:
                provider: okta
                client-id: {client_id}
                client-secret: {client_secret}
                scope: openid,profile,email
                redirect-uri: {host}/login/oauth2/code/okta
                client-name: Okta
                issuer-uri: {okta_issuer_uri}
                user-name-attribute: email
                admin-attribute: email
                admin-principals: john@odd.com,david@odd.com
```

{% endtab %}

{% tab title="OKTA Environment variables" %}

```
AUTH_TYPE=OAUTH2
AUTH_OAUTH2_CLIENT_OKTA_PROVIDER=okta
AUTH_OAUTH2_CLIENT_OKTA_CLIENT_ID={client_id}
AUTH_OAUTH2_CLIENT_OKTA_CLIENT_SECRET={client_secret}
AUTH_OAUTH2_CLIENT_OKTA_SCOPE=openid,profile,email
AUTH_OAUTH2_CLIENT_OKTA_REDIRECT_URI={host}/login/oauth2/code/okta
AUTH_OAUTH2_CLIENT_OKTA_CLIENT_NAME=Okta
AUTH_OAUTH2_CLIENT_OKTA_ISSUER_URI={issuer_uri}
AUTH_OAUTH2_CLIENT_OKTA_USER_NAME_ATTRIBUTE=email
AUTH_OAUTH2_CLIENT_OKTA_ADMIN_ATTRIBUTE=email
AUTH_OAUTH2_CLIENT_OKTA_ADMIN_PRINCIPALS=john@odd.com,david@odd.com
```

{% endtab %}
{% endtabs %}

{% tabs %}
{% tab title="Keycloak YAML" %}

```yaml
auth:
    type: OAUTH2
    oauth2:
        client:
            keycloak:
                provider: keycloak
                client-id: {client_id}
                client-secret: {client_secret}
                scope: openid,profile,email
                redirect-uri: {host}/login/oauth2/code/keycloak
                client-name: Keycloak
                issuer-uri: {keycloak_issuer_uri}
                user-name-attribute: preferred_username
                admin-attribute: preferred_username
                admin-principals: john,david
```

{% endtab %}

{% tab title="Keycloak Environment variables" %}

```
AUTH_TYPE=OAUTH2
AUTH_OAUTH2_CLIENT_KEYCLOAK_PROVIDER=keycloak
AUTH_OAUTH2_CLIENT_KEYCLOAK_CLIENT_ID={client_id}
AUTH_OAUTH2_CLIENT_KEYCLOAK_CLIENT_SECRET={client_secret}
AUTH_OAUTH2_CLIENT_KEYCLOAK_SCOPE=openid,profile,email
AUTH_OAUTH2_CLIENT_KEYCLOAK_REDIRECT_URI={host}/login/oauth2/code/keycloak
AUTH_OAUTH2_CLIENT_KEYCLOAK_CLIENT_NAME=Keycloak
AUTH_OAUTH2_CLIENT_KEYCLOAK_ISSUER_URI={issuer_uri}
AUTH_OAUTH2_CLIENT_KEYCLOAK_USER_NAME_ATTRIBUTE=preferred_username
AUTH_OAUTH2_CLIENT_KEYCLOAK_ADMIN_ATTRIBUTE=preferred_username
AUTH_OAUTH2_CLIENT_KEYCLOAK_ADMIN_PRINCIPALS=john,david
```

{% endtab %}
{% endtabs %}

#### Keycloak with PKCE

Keycloak realms can be configured to require [Proof Key for Code Exchange (PKCE, RFC 7636)](https://datatracker.ietf.org/doc/html/rfc7636) on the authorization code flow — most commonly for **public** clients (browser-based or SPA-style flows that cannot keep a client secret).

To enable PKCE, set `pkce: true` on the Keycloak provider configuration **and** leave `client-secret` empty. The platform then registers the client as public (`client_authentication_method=none`) and Spring Security performs the code exchange with PKCE.

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    type: OAUTH2
    oauth2:
        client:
            keycloak:
                provider: keycloak
                client-id: {client_id}
                pkce: true
                scope: openid,profile,email
                redirect-uri: {host}/login/oauth2/code/keycloak
                client-name: Keycloak
                issuer-uri: {keycloak_issuer_uri}
                user-name-attribute: preferred_username
                admin-attribute: preferred_username
                admin-principals: john,david
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_TYPE=OAUTH2
AUTH_OAUTH2_CLIENT_KEYCLOAK_PROVIDER=keycloak
AUTH_OAUTH2_CLIENT_KEYCLOAK_CLIENT_ID={client_id}
AUTH_OAUTH2_CLIENT_KEYCLOAK_PKCE=true
AUTH_OAUTH2_CLIENT_KEYCLOAK_SCOPE=openid,profile,email
AUTH_OAUTH2_CLIENT_KEYCLOAK_REDIRECT_URI={host}/login/oauth2/code/keycloak
AUTH_OAUTH2_CLIENT_KEYCLOAK_CLIENT_NAME=Keycloak
AUTH_OAUTH2_CLIENT_KEYCLOAK_ISSUER_URI={issuer_uri}
AUTH_OAUTH2_CLIENT_KEYCLOAK_USER_NAME_ATTRIBUTE=preferred_username
AUTH_OAUTH2_CLIENT_KEYCLOAK_ADMIN_ATTRIBUTE=preferred_username
AUTH_OAUTH2_CLIENT_KEYCLOAK_ADMIN_PRINCIPALS=john,david
```

{% endtab %}
{% endtabs %}

{% hint style="warning" %}
**Confidential clients (with `client-secret` set) and `pkce: true`.** When both `pkce: true` and `client-secret` are configured, the platform falls back to confidential-client authentication using the client secret and **the `pkce` flag has no effect on the OAuth2 client registration** — PKCE parameters are not added to the authorization request. If your Keycloak realm enforces PKCE on a confidential client, configure the client as **public** (omit `client-secret`) and rely on `pkce: true` alone, or disable PKCE enforcement on the realm side.
{% endhint %}

{% hint style="info" %}
The `pkce` property is declared on ODD's generic OAuth2 provider configuration, so it is technically available for any provider — not just Keycloak. In practice, Keycloak is the realm most commonly configured to require PKCE.
{% endhint %}

## Logout token-revocation matrix

When an operator clicks **Sign out** in the ODD UI, the platform invalidates the local server-side session and — depending on the provider — optionally asks the identity provider (IdP) to revoke the OAuth2 access token. Whether the IdP-issued token is actually revoked differs per provider, and the residual-token-validity window can be substantial. Operators on shared or public workstations need to know which providers leave a usable token behind after a "successful" logout.

| Provider                          | Local session invalidated | IdP access token revoked                                                                                                                                 | If not revoked, residual validity                                                            |
| --------------------------------- | ------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------- |
| **AWS Cognito**                   | yes                       | no — the handler redirects to Cognito's `/logout` for session removal but does not call `/oauth2/revoke`                                                 | access token \~1 hour; refresh token up to 90 days, depending on the User Pool configuration |
| **GitHub**                        | yes                       | yes — the handler calls `DELETE /applications/{client_id}/grant` to revoke the OAuth grant on the user's behalf                                          | —                                                                                            |
| **Google**                        | yes                       | yes — the handler `POST`s to `oauth2.googleapis.com/revoke` for the access token                                                                         | —                                                                                            |
| **Azure AD**                      | yes                       | no — Azure AD v2.0 does not expose RFC 7009 token revocation (protocol-level limitation); the handler can only redirect to the OIDC end-session endpoint | access token \~1 hour; refresh token per tenant policy                                       |
| **ODD\_IAM**                      | yes                       | no — session invalidation only by design (the IAM provider does not implement revocation)                                                                | —                                                                                            |
| **Okta / Keycloak / Custom OIDC** | yes                       | no — there is no dedicated logout handler; the platform invalidates only the local session                                                               | per IdP policy on the access token; refresh tokens persist until they expire                 |

**Operator caution.** For any row in the **IdP access token revoked: no** column, a token captured by an attacker before logout — for example, from browser-side credential exfiltration on a shared terminal — remains usable against IdP-protected resources for the remainder of the token's natural validity. The ODD platform's session invalidation does not affect this; the only mitigation in those modes is to wait for the token to expire or to sign out at the IdP directly (via the Cognito hosted UI, the Azure portal session controls, etc.).

A platform-side fix for the Cognito gap — calling `/oauth2/revoke` from the Cognito logout handler — is tracked upstream.

## Post-logout redirect derivation

All five OAuth2 logout handlers (Cognito, Github, Google, Azure, ODD\_IAM) build the `post_logout_redirect_uri` (or, for the providers that use a different name, the equivalent return-URL parameter) from the **inbound request's URI**. The platform reads `scheme`, `host`, `port`, `path`, and `query` from the inbound HTTP request and reconstructs the base URL with `/` as the path — there is no allowlist of trusted hosts, no `platform.base-url`-style configuration property, and no scheme enforcement.

In a typical deployment where the inbound `Host` header is the browser-presented value and the platform's reverse proxy passes it through unchanged, the post-logout redirect points back to the same origin and there is nothing to worry about. The concern surfaces when the reverse proxy trusts user-controlled `Host` or `X-Forwarded-Host` headers, or when the IdP's post-logout-redirect allowlist is wider than the platform's host.

{% hint style="warning" %}
**If your deployment terminates TLS at a reverse proxy that trusts and forwards user-controlled `Host` or `X-Forwarded-Host` headers, the post-logout redirect chain can be hijacked.** An attacker sending `X-Forwarded-Host: attacker.example.com` causes the platform to construct a return-URL targeting the attacker domain; if the IdP's `post_logout_redirect_uri` allowlist is wildcarded (e.g. `*.example.com`), the IdP accepts it and the user lands on `attacker.example.com` after their authenticated logout completes. Mitigations: configure the reverse proxy to **strip or rewrite** the inbound `Host` / `X-Forwarded-Host` headers before forwarding to the platform; configure the IdP's logout allowlist with the most-specific host(s), not wildcards.
{% endhint %}

{% hint style="warning" %}
**This compounds with the revocation matrix above.** For Cognito / Azure / ODD\_IAM (where IdP access tokens are not revoked on platform logout), an open-redirect that lands the user on an attacker-controlled domain still benefits from any captured tokens remaining valid against IdP-protected resources. The two issues form one security cluster: revocation gap + redirect derivation + reverse-proxy header trust. A platform-side `odd.platform-base-url` allowlist that validates the inbound `Host` against a configured value is tracked upstream.
{% endhint %}

## UI feedback on logout outcome

The SPA's **Sign out** action sends the user to `/logout` via a hard navigation; the platform handles the rest. The SPA does not distinguish between "logged out + IdP token revoked" (Google / GitHub) and "logged out + IdP token still valid" (Cognito / Azure / ODD\_IAM) in any UI-visible signal. Operators on shared or public terminals who depend on revocation should not infer it from the absence of an error; sign out from the IdP directly (Cognito hosted UI, Azure portal, etc.) in addition to ODD logout when the workstation is not yours. Per-provider feedback messages in the SPA are tracked upstream.


# LDAP

Configure ODD Platform to authenticate users against an existing LDAP server, including group-to-role mapping and the cross-mode user-name collision caveat for multi-mode deployments.

ODD Platform can be configured to use existing LDAP server for users authentication. There are several properties, that need to be set in order to enable this kind of security.

**Define authentication type**

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    type: LDAP
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_TYPE=LDAP
```

{% endtab %}
{% endtabs %}

#### Connect to LDAP server

There are 3 properties, which are responsible for connecting to LDAP server

* `auth.ldap.url`: LDAP server url (required)
* `auth.ldap.username`: The username (principal) to use when authenticating with the LDAP server
* `auth.ldap.password`: The password (credentials) to use when authenticating with the LDAP server

{% hint style="info" %}
Username and password are not required. If they are not set, operations will be performed by using an anonymous (unauthenticated) context
{% endhint %}

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    ldap:
        url: "ldap://localhost:389"
        username: admin
        password: password
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_LDAP_URL=ldap://localhost:389
AUTH_LDAP_USERNAME=admin
AUTH_LDAP_PASSWORD=password
```

{% endtab %}
{% endtabs %}

{% hint style="warning" %}
**Use `ldaps://` for any server reachable beyond localhost.** The platform passes `auth.ldap.url` to the LDAP client exactly as written and does not enforce a scheme. With an `ldap://` URL — including the `ldap://localhost:389` example above — the bind credentials and every end user's login password travel to the directory in cleartext. No warning is logged at startup. Set the URL to `ldaps://your-server:636` unless the directory is on the same host as the platform.
{% endhint %}

{% hint style="warning" %}
**`auth.ldap.password` is held in plaintext.** The bind password is read straight from configuration and kept as a plain string in the running process; it is not encrypted and is not redacted from the platform's own configuration view. Treat it as a secret at rest: supply it through your deployment's secret mechanism rather than committing it to a values file, and restrict who can read the platform's environment and configuration.
{% endhint %}

#### Perform users search

There are 2 ways of how to retrieve users in LDAP server.

1. Define DN pattern of user names. This is great, when all users are stored under a single node in a directory.
2. Setup LDAP search filter.

{% tabs %}
{% tab title="YAML" %}
**DN pattern**

This is an example of how user DN pattern can be defined. In this case DN for the user will be built by substituting login in the supplied pattern instead of 0.

```yaml
auth:
    ldap:
        dn-pattern: "uid={0},ou=people,dc=mycompany,dc=com"
```

**Search filter**

This is an example of using search filter instead of DN pattern. If a user search base isn’t supplied, the search will be performed from the root.

```yaml
auth:
    ldap:
        user-filter:
            search-base: "ou=people,dc=mycompany,dc=com"
            filter: "(uid={0})"
```

{% endtab %}

{% tab title="Environment variables" %}
**DN pattern**

This is an example of how user DN pattern can be defined. In this case DN for the user will be built by substituting login in the supplied pattern

```
AUTH_LDAP_DN_PATTERN="uid={0},ou=people"
```

**Search filter**

This is an example of using search filter instead of DN pattern. If a user search base isn’t supplied, the search will be performed from the root.

```
AUTH_LDAP_USER_FILTER_SEARCH_BASE="ou=people"
AUTH_LDAP_USER_FILTER_FILTER="uid={0}"
```

{% endtab %}
{% endtabs %}

{% hint style="warning" %}
It is required to set up one of those search methods, otherwise application start will fail
{% endhint %}

#### Define admin groups

ODD platform can get LDAP groups, which the user belongs to. Thus it is possible to define which groups will grant admin privileges. There are several properties that need to be set in order to allow ODD platform to do this:

* `auth.ldap.groups.search-base`: The base DN from which the search for group membership should be performed. By default it will be performed from the root.
* `auth.ldap.groups.filter`: The pattern used to find the groups a user belongs to. ODD platform does not set this default itself — when you leave it unset, the platform never overrides the group search filter, and Spring Security's `DefaultLdapAuthoritiesPopulator` applies its own built-in default of

  `(member={0})`, where the user's DN is substituted for `{0}`.
* `auth.ldap.groups.admin-groups`: List of groups, which members will be granted admin permissions.

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    ldap:
        groups:
            search-base: "dc=mycompany,dc=com"
            filter: "(member={0})"
            admin-groups: admin
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_LDAP_GROUPS_SEARCH_BASE="dc=mycompany,dc=com"
AUTH_LDAP_GROUPS_FILTER="(member={0})"
AUTH_LDAP_GROUPS_ADMIN_GROUPS=admin
```

{% endtab %}
{% endtabs %}

#### Active directory

If you are using Active Directory as LDAP server there are additional properties, that need to be set

* `auth.ldap.active-directory.enabled` : Must be set to `true`
* `auth.ldap.active-directory.domain`: Domain name

{% hint style="warning" %}
**Set `domain` whenever you set `enabled: true`.** The platform does not check that the two go together: a configuration with `active-directory.enabled: true` and no `domain` starts up without an error and then attempts Active Directory binds with no domain, which fail at sign-in time rather than at startup. Always provide both values together.
{% endhint %}

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    ldap:
        active-directory:
            enabled: true
            domain: "example.com"
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_LDAP_ACTIVE_DIRECTORY_ENABLED=true
AUTH_LDAP_ACTIVE_DIRECTORY_DOMAIN="example.com"
```

{% endtab %}
{% endtabs %}

**Final configuration example**

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    type: LDAP
    ldap:
        url: "ldap://localhost:389"
        username: admin
        password: password
        dn-pattern: "uid={0},ou=people,dc=mycompany,dc=com"
        groups:
            search-base: "dc=mycompany,dc=com"
            filter: "(member={0})"
            admin-groups: admin
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_TYPE=LDAP
AUTH_LDAP_URL=ldap://localhost:389
AUTH_LDAP_USERNAME=admin
AUTH_LDAP_PASSWORD=password
AUTH_LDAP_DN_PATTERN="uid={0},ou=people"
AUTH_LDAP_GROUPS_SEARCH_BASE="dc=mycompany,dc=com"
AUTH_LDAP_GROUPS_FILTER="(member={0})"
AUTH_LDAP_GROUPS_ADMIN_GROUPS=admin
```

{% endtab %}
{% endtabs %}

#### Admin promotion (group-name matching)

For the cross-mode comparison of how every auth mode and OAuth provider grants ADMIN, see [Admin promotion across providers](/configuration-and-deployment/enable-security/admin-promotion). The notes below cover LDAP-specific behaviour only.

`auth.ldap.groups.admin-groups` accepts a list of group names whose members the platform promotes to `ADMIN`. A user is promoted when one of their LDAP group names equals a configured value, compared **case-insensitively on the whole name**. The comparison is not a substring or prefix match: each configured token must match an entire group name, ignoring only letter case.

| `admin-groups` value | LDAP group the user belongs to | Promoted to `ADMIN`?  |
| -------------------- | ------------------------------ | --------------------- |
| `Admin`              | `Admin`                        | Yes — same name       |
| `Admin`              | `admin`                        | Yes — case is ignored |
| `Admin`              | `Administrator`                | No — different name   |
| `ops`                | `devops`                       | No — different name   |

Because matching is whole-name, list every admin group explicitly. Adding `ops` does not promote members of `devops` or `dataops`; if those groups should also be admins, name each of them in `admin-groups`.

**When `auth.ldap.groups.admin-groups` is empty or unset**

If `auth.ldap.groups` is configured but `admin-groups` is empty (`admin-groups: []` or simply omitted), every authenticated LDAP user is granted the `USER` role only — there is no path to `ADMIN` via LDAP under this configuration, and no boot warning surfaces the absence. A deployment that uncomments the LDAP block but forgets the `admin-groups` entry has no possible ADMIN user via LDAP. Decide on the `admin-groups` value at the same time you author the rest of the LDAP block, even if your initial value is a single well-known operator group.

A platform-side fix that fail-fast-warns when `auth.ldap.groups` is configured without `admin-groups` is tracked upstream.

#### Cross-mode user-name collision (activity feed read paths)

The platform's [activity-feed](/features/active-platform-features/activity-feed) read paths join the `USER_OWNER_MAPPING` table on `OIDC_USERNAME` only — the join does **not** discriminate by auth provider. If your deployment has historically used multiple auth modes (for example, started on `LOGIN_FORM` with seed users, then enabled `LDAP`), a user named `alice` who signed in via `LOGIN_FORM` and a user named `alice` who signed in via `LDAP` can resolve to the same `OwnerPojo` when activity-feed rows are rendered. The most recent `USER_OWNER_MAPPING` row for the literal username wins each lookup; results are not deterministic across replicas.

**Operator mitigation today:** never reuse usernames across auth modes when migrating. If you migrate from `LOGIN_FORM` to `LDAP`, delete the `USER_OWNER_MAPPING` rows for the `LOGIN_FORM` usernames before introducing same-named LDAP users.

**Forensic note:** do not rely on activity-feed Owner attribution for incident response in multi-mode deployments without verifying the auth mode of the actor through the underlying `activity.created_by` value.

A platform-side fix that discriminates the join by `PROVIDER` is tracked upstream. The same caveat applies to deployments running `LOGIN_FORM` on top of an earlier `LDAP` history — see the matching note on the [Login form](/configuration-and-deployment/enable-security/authentication/login-form#cross-mode-user-name-collision-activity-feed-read-paths) page.


# Server-to-server (S2S)

Configure server-to-server (S2S / M2M) API-key authentication for programmatic clients — CI/CD jobs, automation scripts, and non-human callers — alongside the configured interactive auth mode.

In addition to interactive authentication (Login form, OAuth2/OIDC, LDAP), ODD Platform supports **server-to-server (S2S) API-key authentication** (also called **machine-to-machine (M2M) tokens**) for programmatic clients that cannot go through an interactive login — CI/CD jobs, automation scripts, scheduled ingestion pipelines, and any other non-human callers of the Platform API.

## How it works

* A single long-lived token is configured on the platform via `auth.s2s.token`.
* Clients present the token in the `X-API-Key` HTTP header on every request.
* Requests carrying a valid token run with the built-in `ADMIN` user and ADMIN role, so they can call any endpoint that admins can call — including the ingestion API, management APIs, and entity mutations.
* S2S runs **alongside** the configured interactive auth mechanism, not instead of it. If a request has no `X-API-Key` header (or the value doesn't match), the filter falls through and the normal auth chain (Login form / OAuth2 / LDAP) handles the request. This means enabling S2S does not affect the user login flow.

{% hint style="info" %}
S2S is available when `auth.type` is `LOGIN_FORM`, `OAUTH2`, or `LDAP`. With `auth.type: DISABLED`, the platform is already open and S2S is not needed.
{% endhint %}

{% hint style="info" %}
**S2S (`X-API-Key`) is not the same as the per-collector ingestion token.** ODD Platform has two independent, separately-enabled API-auth mechanisms:

* **S2S** — this page. A single platform-wide key sent in the `X-API-Key` header, enabled by `auth.s2s.enabled`, that authenticates the caller as the built-in `ADMIN` for any endpoint.
* **Ingestion-token authentication** — a per-collector / per-datasource token sent in the `Authorization: Bearer <token>` header, enabled by `auth.ingestion.filter.enabled`, that protects the ingestion endpoints only.

They use different headers and different secrets. Sending `X-API-Key` does nothing if only the ingestion-token filter is enabled; sending `Authorization: Bearer` does nothing on the S2S path. See [Ingestion authentication](/configuration-and-deployment/enable-security#ingestion-authentication) for the per-collector token mechanism.
{% endhint %}

## Configuration

| Property           | Default   | Description                                                                                                                                                                                                                      |
| ------------------ | --------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `auth.s2s.enabled` | `false`   | Turns the S2S filter on. When `true`, `auth.s2s.token` must be set — the platform refuses to start if the token is missing.                                                                                                      |
| `auth.s2s.token`   | *(unset)* | The shared API key. Any request presenting this value in the `X-API-Key` header is authenticated as the built-in `ADMIN` user. Treat this as a high-privilege secret and store it in a secrets manager, not in plaintext config. |

{% tabs %}
{% tab title="YAML" %}

```yaml
auth:
    type: OAUTH2          # or LOGIN_FORM / LDAP
    s2s:
        enabled: true
        token: {long_random_token}
```

{% endtab %}

{% tab title="Environment variables" %}

```
AUTH_TYPE=OAUTH2
AUTH_S2S_ENABLED=true
AUTH_S2S_TOKEN={long_random_token}
```

{% endtab %}
{% endtabs %}

## Using the token

Send the token in the `X-API-Key` header on every request:

```bash
curl -X POST https://{platform_host}/ingestion/entities \
     -H "X-API-Key: {long_random_token}" \
     -H "Content-Type: application/json" \
     -d @payload.json
```

The same header works for any other Platform API endpoint — for example, listing data sources:

```bash
curl https://{platform_host}/api/datasources \
     -H "X-API-Key: {long_random_token}"
```

## Security considerations

* The token is a **single static string** compared for equality — it is not rotated, expired, or scoped. Rotating it requires restarting the platform with a new `auth.s2s.token` value.
* Any client that holds the token gets full ADMIN access to the Platform API. Prefer to scope its distribution narrowly: one token per trusted caller tier, not one token shared across unrelated systems.
* Transport the token only over HTTPS. If the platform is exposed over plain HTTP, anyone on the network path can capture and replay the token.
* If you only need to authenticate the ingestion pipeline (collectors / push adapters), consider combining S2S with `auth.ingestion.filter.enabled: true` so the ingestion endpoints remain protected even when S2S is not enabled — see [Enable security](/configuration-and-deployment/enable-security) and the [deployment matrix](/configuration-and-deployment/enable-security#deployment-matrix-per-endpoint-per-auth-config) for which endpoints each flag covers.

## Operator caveats

{% hint style="warning" %}
**Do not name a real `LOGIN_FORM` or `LDAP` user `ADMIN` (case-sensitive, uppercase).** The S2S filter builds its synthetic principal as the literal uppercase string `ADMIN`. The platform's user-to-owner lookup compares this against the `USER_OWNER_MAPPING` table with case-sensitive equality. If an operator has provisioned a real user named `ADMIN` (uppercase) in `LOGIN_FORM` or `LDAP`, S2S-authenticated callers will resolve to that real user's owner binding — every S2S mutation will be attributed to the real user in the activity feed, and any owner the real user is bound to becomes the S2S caller's owner. Avoid the literal uppercase `ADMIN` (and similarly `admin` lowercase — see the [disabled-authentication](/configuration-and-deployment/enable-security/authentication/disabled-authentication#reserved-usernames) page) when provisioning users in any auth mode.
{% endhint %}

{% hint style="info" %}
**`auth.s2s.enabled: true` has no effect under `auth.type: DISABLED`.** The DISABLED-mode security configuration does not read `auth.s2s.enabled`, so the S2S filter is never wired into the chain in that mode. The property is accepted in YAML without warning, but `X-API-Key` requests under DISABLED behave identically to unauthenticated requests (which DISABLED already permits). If you are pre-configuring `auth.s2s.enabled` for a planned migration to `LOGIN_FORM`, `OAUTH2`, or `LDAP`, the property takes effect only after `auth.type` flips to one of those modes.
{% endhint %}


# Authorization

ODD's RBAC model — permissions, policies, roles, owners, and user-owner association — centred on the user-identity / owner-identity bridge that resolves who-can-do-what.

Authorization in ODD Platform is **RBAC over a fixed permission catalogue**: the platform defines a set of permissions (one per state-changing action), operators bundle permissions into Roles, attach Roles to Owners or to authentication-mode-derived groups, and the runtime checks the caller's effective permissions on every request that touches a permission-gated endpoint. The model is documented in this section across five reading surfaces; the order below is the operator's mental-model build order.

The crucial distinction this section repeatedly returns to: **user identity is separate from owner identity**. A user is who signed in (an OIDC / LDAP / S2S principal); an Owner is a catalog-side row that a user binds to. Permissions can be granted through either side — Owner roles override the user's auth-mode-derived role once a binding is in place — and most of the operator-trust nuances on this page boil down to that bridge.

## Three load-bearing operator-trust facts

Before reading the per-page deep dives, internalise these three platform-wide facts. They are not derivable from any single page if you don't know to look for them, and each shapes operator decisions across every page in this section.

* **Read access on Management catalogs is collaborative by design.** Every `GET /api/*` Management endpoint (Owners, Datasources, Collectors, Namespaces, Titles, Owner-Association requests, Policies, Roles, IdP providers) falls through to the platform's "any authenticated user" rule. There is no `OWNER_READ`, `NAMESPACE_READ`, or equivalent permission to withhold — read-side authorization is enforced at the deployment perimeter, not by the platform's RBAC. See the warning admonition at the end of [Permissions → Management permissions](/configuration-and-deployment/enable-security/authorization/permissions#management-permissions).
* **Token rotation is immediate.** `COLLECTOR_TOKEN_REGENERATE` and `DATA_SOURCE_TOKEN_REGENERATE` invalidate the prior token at the moment the rotation call returns — there is no grace period. The collector process or push client must be redeployed with the new token before its existing ingestion stops. Holders of either permission are operationally privileged in a way the permission name does not communicate. See the operational caveats on the [Permissions](/configuration-and-deployment/enable-security/authorization/permissions#management-permissions) page.
* **`DIRECT_OWNER_SYNC` composes with the freeSolo Owner-name input.** A user holding `DIRECT_OWNER_SYNC` who submits the home-page Owner-association form with an owner name that does not exist in the catalog **mints a new Owner row and self-binds to it in a single POST** — bypassing the request-then-approve workflow and the existing-name discipline. Grant `DIRECT_OWNER_SYNC` only to principals you also trust to mint Owner names (typically a service identity, not an end-user policy). See [Permissions → DIRECT\_OWNER\_SYNC](/configuration-and-deployment/enable-security/authorization/permissions#management-permissions).

## How the UI surfaces missing permissions

The UI's permission-aware components use a **hide-not-disable** convention: affordances the signed-in user does not have permission to use are removed from the DOM entirely, with no greyed-out button, no tooltip, no admin-contact CTA. A user who expects to see an action button or a Management tab but does not should ask their administrator which permission is missing — there is no platform-side signal that a button is hidden because of permission posture as opposed to feature absence.

This convention applies platform-wide to every permission-gated affordance (mutation buttons on data-entity headers, Policy / Role / Owner editors, Management tab visibility, ownership-relation create / delete, attachment upload, etc.). Operators introducing new users to the platform should mention the convention so users have the right mental model when something they expect is missing.

## Recommended reading order

The pages below are listed in the order an operator builds the authorization model mentally — start at Permissions (the catalogue of operations), compose them into Roles (the bundles), assign them via Policies (the conditional rules), bind to Owners (the catalog identities), and finally close the loop with User-owner association (the workflow that ties signed-in users to Owners).

* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the full enumeration of permission keys grouped by resource, the two-endpoint read surface, and the read-collaborative posture on Management catalogs.
* [Roles](/configuration-and-deployment/enable-security/authorization/roles) — how Roles bundle Permissions, the User-role vs Owner-role distinction, and the Owner-role-supersedes-User-role precedence.
* [Policies](/configuration-and-deployment/enable-security/authorization/policies) — the JSON-schema policy structure, the per-resource condition fields, the Title-vocabulary caveat for `:owner:title` conditions, and the authorization hot-path performance characteristics.
* [Owners](/configuration-and-deployment/enable-security/authorization/owners) — what an Owner is, the three creation paths, Owner-name accretion guidance, role attachment, and the lifecycle / API caveats (audit silence, GET ungated, three service-tier side-doors, destructive PUT semantic).
* [User-owner association](/configuration-and-deployment/enable-security/authorization/user-owner-association) — the three write-paths for binding a user to an Owner (user self-request, `DIRECT_OWNER_SYNC` auto-approve, admin direct-bind), the operator workflow on Management → Associations, and the cross-mode user-name collision caveat.

## Related references

* [Admin promotion across providers](/configuration-and-deployment/enable-security/admin-promotion) — how each auth mode and OAuth provider determines which user becomes `ADMIN`.
* [Audit trail scope](/configuration-and-deployment/enable-security/audit-trail-scope) — what the platform audits and (importantly) what it does not, including the schema-rooted absence of an audit trail for Policy / Role / Owner / Term / Namespace / Datasource / Collector lifecycle changes.

## Where to next

* [Enable security](/configuration-and-deployment/enable-security) — the parent section covering the two authentication surfaces (UI + ingestion) and the deployment matrix.
* [Authentication](/configuration-and-deployment/enable-security/authentication) — the auth-mode configuration (DISABLED / LOGIN\_FORM / OAUTH2 / LDAP / S2S) that produces the user identity Authorization gates against.
* [Management → Associations](/features/management) — the operator surface where User-Owner associations are reviewed, approved, and directly created.


# Policies

Policies are JSON-defined permission grants attached to owners through roles. Reference for policy structure, JSON Schema validation, resources, conditions, and the permissions a statement can grant.

ODD Platform allows to manage access to resources by creating policies and attaching them to owners through roles.

Policies are described in JSON format and validated with [JSON Schema](https://json-schema.org).

{% hint style="warning" %}
**Deleting a policy is blocked while a role is still bound to it.** ODD refuses to delete a policy that any role still references — the attempt fails with *"Policy is attached to a role."* To delete a policy, first detach it from every role on the **Roles** tab; once no role references it, the deletion succeeds and the permissions it granted go with it. This mirrors the cascade-delete guards on namespaces and owners — see [Permissions](/configuration-and-deployment/enable-security/authorization/permissions).
{% endhint %}

## JSON policy structure

Each policy is represented by an array of statements and each statement defines a resource with optional conditions and [permissions](/configuration-and-deployment/enable-security/authorization/permissions) which will be allowed for given resource.

{% code title="Basic policy structure" %}

```json
{
  "statements": [
    {
      "resource": {
        "type": "",
        "conditions": {}
      },
      "permissions": []
    },
    {
      "resource": {
        "type": "",
        "conditions": {}
      },
      "permissions": []
    }
  ]
}
```

{% endcode %}

### Resource type

There are 3 possible types of policy resource:

* **DATA\_ENTITY** - Indicates, that current permissions are applied for data entity
* **TERM** - Indicates, that current permissions are applied for dictionary term
* **MANAGEMENT** - Indicates, that current permissions are general and work all over the platform
* **QUERY\_EXAMPLE** - Indicates, that the current permissions are applied for query examples

{% hint style="info" %}
Each type can be combined only with associated permissions and conditions, e.g. if you describe statement for **DATA\_ENTITY** type you can only use data entity's conditions and [permissions](/configuration-and-deployment/enable-security/authorization/permissions).
{% endhint %}

### Conditions

Conditions allow to specify the circumstances under which the policy grants permission.

This is an optional field and in case of absence, permissions will be applied to all resource type entries.

{% hint style="warning" %}
Conditions can't be applied to **MANAGEMENT** resource type
{% endhint %}

In ODD Platform we have pre-defined [condition operators](#condition-operators) and [fields](#condition-fields), which can be used with these operators.

#### Condition operators

Currently we support next operators:

* `all` - all conditions under this operator must be positive
* `any` - at least one condition under this operation must be positive
* `eq` - [condition field](#condition-fields) must be equal to some value
* `not_eq` - [condition field](#condition-fields) must not be equal to some value
* `match` - [condition field](#condition-fields) must match some value
* `not_match` - [condition field](#condition-fields) must not match some value
* `is` - [condition field](#condition-fields) must be true
* `not_is` - [condition field](#condition-fields) must be false

#### **Condition fields**

There are couple of pre-defined fields, which can be used in conditions. Each resource type has its own fields.

**Data entity**

* `dataEntity:oddrn` - data entity's ODDRN
* `dataEntity:internalName` - data entity's business name
* `dataEntity:externalName` - data entity's ingested name
* `dataEntity:type` - data entity's type name
* `dataEntity:class` - data entity's class name
* `dataEntity:datasource:oddrn` - data entity's datasource ODDRN
* `dataEntity:datasource:name` - data entity's datasource name
* `dataEntity:namespace:name` - data entity's namespace name
* `dataEntity:tag:name` - data entity's tag name
* `dataEntity:owner` - data entity's owner
* `dataEntity:owner:title` - data entity's owner title (see [Title vocabulary caveat](#title-vocabulary-caveat-for-ownertitle-conditions) below)

**Term**

* `term:name` - term's name
* `term:namespace:name` - term's namespace name
* `term:tag:name` - term's tag name
* `term:owner` - term's owner
* `term:owner:title` - term's owner title (see [Title vocabulary caveat](#title-vocabulary-caveat-for-ownertitle-conditions) below)

#### Condition examples

1. User must be term's owner, term must be in Open Data Discovery namespace and have tag, which name equals to `Test`.

   ```json
   {
     "all": [
       {
         "is": "term:owner"
       },
       {
         "eq": {
           "term:namespace:name": "Open Data Discovery"
         }
       },
       {
         "match": {
           "term:tag:name": "Test"
         }
       }
     ]
   }
   ```
2. At least one of the conditions must be positive: User must be data entity's owner **OR** data entity shouldn't have tag `PII`.

   ```json
   {
     "any": [
       {
         "is": "dataEntity:owner"
       },
       {
         "not_eq": {
           "dataEntity:tag:name": "PII"
         }
       }
     ]
   }
   ```

## Permissions

Please check the [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) section for all available permissions list.

## Policy examples

#### Data entity policy with conditions

Policy allows to update business name, description and custom metadata if user is data entity's owner and this data entity is in `Open Data Discovery` namespace

```json
{
  "statements": [
    {
      "resource": {
        "type": "DATA_ENTITY",
        "conditions": {
          "all": [
            {
              "is": "dataEntity:owner"
            },
            {
              "eq": {
                "dataEntity:namespace:name": "Open Data Discovery"
              }
            }
          ]
        }
      },
      "permissions": [
        "DATA_ENTITY_INTERNAL_NAME_UPDATE",
        "DATA_ENTITY_CUSTOM_METADATA_CREATE",
        "DATA_ENTITY_CUSTOM_METADATA_UPDATE",
        "DATA_ENTITY_CUSTOM_METADATA_DELETE",
        "DATA_ENTITY_DESCRIPTION_UPDATE"
      ]
    }
  ]
}
```

#### Data entity policy without conditions

All actions are allowed for all data entities

```json
{
  "statements": [
    {
      "resource": {
        "type": "DATA_ENTITY"
      },
      "permissions": [
        "ALL"
      ]
    }
  ]
}
```

#### Dictionary term policy with conditions

Policy allows to update term information and ownership if it has `Customer` tag

```json
{
  "statements": [
    {
      "resource": {
        "type": "TERM",
        "conditions": {
          "eq": {
            "term:tag:name": "Customer"
          }
        }      
      },
      "permissions": [
        "TERM_UPDATE",
        "TERM_OWNERSHIP_CREATE",
        "TERM_OWNERSHIP_UPDATE",
        "TERM_OWNERSHIP_DELETE"
      ]
    }
  ]
}
```

#### Management policy

Policy allows to manage datasources, collectors and namespaces

```json
{
  "statements": [
    {
      "resource": {
        "type": "MANAGEMENT"
      },
      "permissions": [
        "DATA_SOURCE_CREATE",
        "DATA_SOURCE_UPDATE",
        "DATA_SOURCE_DELETE",
        "DATA_SOURCE_TOKEN_REGENERATE",
        "COLLECTOR_CREATE",
        "COLLECTOR_UPDATE",
        "COLLECTOR_DELETE",
        "COLLECTOR_TOKEN_REGENERATE",
        "NAMESPACE_CREATE",
        "NAMESPACE_UPDATE",
        "NAMESPACE_DELETE"
      ]
    }
  ]
}
```

#### Combined policy

Policy allows to edit term information and permits all actions for data entities from `Finance` namespace.

```json
{
  "statements": [
    {
      "resource": {
        "type": "TERM",
        "conditions": {
          "eq": {
            "term:namespace:name": "Finance"
          }
        }
      },
      "permissions": [
        "TERM_UPDATE"
      ]
    },
    {
      "resource": {
        "type": "DATA_ENTITY",
        "conditions": {
          "eq": {
            "dataEntity:namespace:name": "Finance"
          }
        }
      },
      "permissions": [
        "ALL"
      ]
    }
  ]
}
```

## Title vocabulary caveat for `:owner:title` conditions

The `dataEntity:owner:title` and `term:owner:title` condition fields evaluate against the platform's `Title` table — a free-text vocabulary populated by users at ownership-grant time, not a curated allowlist. Two operator-visible behaviours follow from this and apply to every Policy condition referencing those fields.

{% hint style="warning" %}
**Title strings are case-sensitive, exact-match, and not normalised.** The platform's `TitleService.getOrCreate(name)` accepts any string verbatim: no case-folding, no whitespace trimming, no slug-deduping, no `@Pattern` or `@Size` validation. The underlying `title.name` column has no `CHECK` constraint. Two users who type `'Data Steward'`, `'data steward'`, `'DATA STEWARD'`, `' Data Steward '`, or `'data-steward'` into the same role-attach form each accumulate as **distinct rows** in the `Title` table. A Policy condition `dataEntity:owner:title == 'Data Steward'` silently misses every other-casing variant — operators carrying the wrong-cased Title receive access-denied with no platform-visible diagnostic.

The Title table is also written through a side-channel: any caller with `DATA_ENTITY_OWNERSHIP_CREATE` or `TERM_OWNERSHIP_CREATE` can mint a new Title row by typing a never-before-seen string into an ownership-grant form. New Title strings become part of the Policy-condition vocabulary the moment they are written.

**Mitigations operators can apply today** (pending an upstream curated-Title-vocabulary fix): enumerate the variants explicitly with an `any` block of `eq` conditions — `{ "any": [ { "eq": { "dataEntity:owner:title": "Data Steward" } }, { "eq": { "dataEntity:owner:title": "data steward" } }, { "eq": { "dataEntity:owner:title": "DATA STEWARD" } } ] }`. (There is **no `in` operator** — see [Condition operators](#condition-operators) for the supported set; a condition using `in` is rejected by the policy JSON Schema, and the platform returns an error rather than saving the policy.) OR restrict the two `*_OWNERSHIP_CREATE` permissions to a vocabulary-steward role so the Title set stays bounded; OR deploy a periodic SQL job that consolidates obvious typo-variants.
{% endhint %}

{% hint style="info" %}
**There is no Management UI tab for Titles.** The Management surface lists Namespaces, Datasources, Integrations, Collectors, Owners, Tags, Associations, Roles, and Policies — no Titles entry. Operators cannot browse, merge, or delete duplicate or typo'd Titles via the UI today. Title curation requires direct database access against the `title` table until a Titles management surface ships upstream.
{% endhint %}

## Performance characteristics

Every authenticated request that reaches a permission-gated endpoint resolves the caller's Policies before the handler runs. The resolution is **not cached** at the request scope, the user scope, or any other scope — `PolicyService.getCurrentUserPolicies` is invoked from the platform's permission extractors on every authorized HTTP request and executes two JOIN roundtrips against PostgreSQL each time (a 5-table user→owner→user-owner-mapping chain to resolve the caller's roles, then a 2-table role→policies chain to fetch each role's policy set).

**Throughput implication.** For a platform receiving N authenticated requests per second, the authorization hot-path generates approximately `2 × N` PostgreSQL queries per second over and above the application-logic queries served by the matching handler. Size the R2DBC connection pool (`spring.r2dbc.pool.max-size`) and the database CPU budget accordingly — a practical heuristic is to provision 4–5 concurrent JOIN slots per peak authenticated request per second, plus headroom for the application-logic queries each request also triggers.

**Operator-tunable knob today: none.** There is no in-process cache, no `@Cacheable` annotation, no operator setting to tune the cache TTL. An upstream request-scoped cache for `getCurrentUserPolicies` is tracked; until it ships, the per-request cost is the floor.


# Permissions

The five permission classes in ODD Platform — data entity, term, query example, lookup table, and management — with the full enumeration of permission keys and the surfaces each one gates.

There are 5 types of permissions in ODD Platform:

* [Data entity permissions](#data-entity-permissions): Actions related to specific data assets, such as tables, data streams, or dashboards.
* [Term permissions](#term-permissions): Actions concerning the management of the [Business Glossary](/features/data-glossary/business-glossary), e.g. terms and their definitions.
* [Query Example permissions](#query-example-permissions): Actions for creating and managing SQL query examples linked to datasets and terms.
* [Lookup table permissions](#lookup-table-permissions): Actions for creating and maintaining operator-managed reference tables — both the table schema and the rows stored in it.
* [Management permissions](#management-permissions): High-level administrative actions for managing the platform's infrastructure and configuration, such as creating data sources, managing users, or defining access control rules.

{% hint style="info" %}
This list is generated from the [`Permission` enum](https://github.com/opendatadiscovery/odd-platform/blob/main/odd-platform-specification/components.yaml) in the Platform's OpenAPI spec (`odd-platform-specification/components.yaml`). If a new permission appears in the API but is missing from this page, or vice versa, it is a bug — please open an issue or PR.
{% endhint %}

This is the full list of permissions divided by types:

#### Data entity permissions

* `DATA_ENTITY_ADD_TERM`. Allows adding a term to a data entity.
* `DATA_ENTITY_ADD_TO_GROUP`. Allows adding a data entity to a manually created group. **Operator caveat**: the permission is scoped against the **child entity** in the URL, not the parent group — a caller with this permission against entity X can place X into **any** manually-created DEG in the catalog, including DEGs owned by other teams. There is no per-DEG authorisation today, and the mutation emits no Activity Feed event. See [Data Entity Groups & Domains → Managing DEG Membership](/features/data-discovery/groups-domains#managing-deg-membership).
* `DATA_ENTITY_ALERT_CONFIG_UPDATE`. Allows configuring alert settings for a data entity (e.g., backwards-incompatible schema change alert, failed data quality test, failed job, distribution anomaly) and the time period to disable notifications.
* `DATA_ENTITY_ALERT_RESOLVE`. Allows resolving alerts for a data entity.
* `DATA_ENTITY_ATTACHMENT_MANAGE`. Allows adding, deleting, and managing file attachments and links for a data entity. (See [Attachments and links](/features/data-discovery/attachments).)
* `DATA_ENTITY_CUSTOM_METADATA_CREATE`. Allows creating custom metadata field values on a data entity, and minting new INTERNAL field rows in the deployment-wide field catalogue as a side effect of the create path. **Operator caveat**: the auto-create-on-miss side-channel makes this an indirect grant of catalogue-write — a caller can mint new field names visible to every other authenticated user on their next autocomplete keystroke. See [Custom metadata → Known limitations](/features/data-discovery/custom-metadata#known-limitations-and-operator-caveats).
* `DATA_ENTITY_CUSTOM_METADATA_DELETE`. Allows deleting a custom metadata field value from a data entity. The catalogue row is not affected by this operation (the field remains visible in the autocomplete picker on other entities). See [Custom metadata](/features/data-discovery/custom-metadata).
* `DATA_ENTITY_CUSTOM_METADATA_UPDATE`. Allows editing an existing custom metadata field value on a data entity. **Operator caveat**: the platform's update endpoint is declared `upsert*` in the API spec but the underlying SQL is a pure `UPDATE` — issuing a PUT for a field that has not previously been assigned on the target entity silently no-ops (HTTP 200 OK, empty body, "Metadata successfully updated." toast). Pre-flight with a GET, or switch to the Create endpoint on miss. See [Custom metadata → Known limitations](/features/data-discovery/custom-metadata#known-limitations-and-operator-caveats).
* `DATA_ENTITY_DELETE_FROM_GROUP`. Allows removing a data entity from a manually created group. **Operator caveat**: same write-collaborative posture as `DATA_ENTITY_ADD_TO_GROUP` — the permission is bound to the child entity in the URL, not the parent group; `DELETE` is silently idempotent (returns `204` on no-op without an Activity Feed event). See [Data Entity Groups & Domains → Managing DEG Membership](/features/data-discovery/groups-domains#managing-deg-membership).
* `DATA_ENTITY_DELETE_TERM`. Allows removing a term from a data entity.
* `DATA_ENTITY_DESCRIPTION_UPDATE`. Allows editing and deleting a data entity's custom description. **Operator caveat**: description text is persisted verbatim with no write-time HTML sanitisation, and the Markdown renderer is configured with `rehype-raw` and no `rehype-sanitize` — raw HTML embedded in the description renders as live markup for every catalog reader. The same write-collaborative posture applies to five sibling Markdown surfaces (per-column description, term definition, Query Example body, Lookup Table cell values, Slack notification body). See [Entity description → Security caveat](/features/data-discovery/entity-description#security-caveat-stored-xss-family-across-six-markdown-surfaces) for the operator-trust framing.
* `DATA_ENTITY_GROUP_UPDATE`. Allows editing a manually created data entity group.
* `DATA_ENTITY_INTERNAL_NAME_UPDATE`. Allows editing and deleting a data entity's business name. (See [Business names](/features/data-discovery/business-names).)
* `DATA_ENTITY_OWNERSHIP_CREATE`. Allows creating ownership for a data entity.
* `DATA_ENTITY_OWNERSHIP_DELETE`. Allows deleting ownership from a data entity.
* `DATA_ENTITY_OWNERSHIP_UPDATE`. Allows editing the title of a data entity ownership.
* `DATA_ENTITY_STATUS_UPDATE`. Allows changing the lifecycle status of a data entity (e.g., stable, deprecated, deleted, draft, unassigned). (See [Data entity statuses](/features/data-discovery/statuses).)
* `DATA_ENTITY_TAGS_UPDATE`. Allows editing a data entity's tags. **Operator caveat**: this is one of four permissions through which novel tag names mint new rows in the global tag directory — granting it to rank-and-file users widens vocabulary governance beyond `TAG_CREATE`. See [Manual Object Tagging → Known limitations and operator caveats](/features/data-discovery/tagging#known-limitations-and-operator-caveats).
* `DATASET_FIELD_ADD_TERM`. Documented as: allows linking a business glossary term to a specific field within a dataset. **Operator caveat — silently-misgated endpoint pair**: the platform's authorization wiring crosses two endpoints at adjacent lines today. The dataset-field term-add endpoint (`POST /api/datasetfields/{dataset_field_id}/terms`) is enforced against `DATA_ENTITY_ADD_TERM` at runtime, not `DATASET_FIELD_ADD_TERM` — UI gates on the documented permission, so the Add-term button is enabled for `DATASET_FIELD_ADD_TERM` holders but the server returns `403` silently. Separately, the alert-status PUT (`PUT /api/alerts/{alert_id}/status`) is enforced against `DATASET_FIELD_ADD_TERM` rather than `DATA_ENTITY_ALERT_RESOLVE` — granting this permission also grants alert-resolution on any entity. See [Per-column annotation → Known limitations](/features/data-discovery/per-column-annotation#known-limitations-and-operator-caveats) for the wiring-bug pair and the workaround.
* `DATASET_FIELD_DELETE_TERM`. Allows removing a linked business glossary term from a specific field within a dataset. See [Per-column annotation](/features/data-discovery/per-column-annotation).
* `DATASET_FIELD_DESCRIPTION_UPDATE`. Allows editing the description of an individual dataset field. The description is rendered through the same Markdown pipeline as the entity-level description and inherits the same security caveat — see [Entity description → Security caveat](/features/data-discovery/entity-description#security-caveat-stored-xss-family-across-six-markdown-surfaces) and [Per-column annotation](/features/data-discovery/per-column-annotation).
* `DATASET_FIELD_ENUMS_UPDATE`. Allows editing a dataset field's enum values. **Operator caveat**: the endpoint behind this permission is operationally bulk-replace (despite its `createEnumValue` operationId) — a partial submission soft-deletes every pre-existing enum row not present in the body. See [Per-column annotation → Known limitations](/features/data-discovery/per-column-annotation#known-limitations-and-operator-caveats).
* `DATASET_FIELD_INTERNAL_NAME_UPDATE`. Allows editing the business name of an individual dataset field. (See [Business names](/features/data-discovery/business-names) and [Per-column annotation](/features/data-discovery/per-column-annotation).)
* `DATASET_FIELD_TAGS_UPDATE`. Allows adding or removing tags from an individual dataset field. **Operator caveat**: novel tag names mint new rows in the global tag directory through this path; submitting an empty tag list silently clears every operator-curated (INTERNAL-origin) tag on the column. The audit feed event for column-level tag changes is `DATASET_FIELD_TAGS_UPDATED` (full before/after payload). See [Manual Object Tagging → Known limitations and operator caveats](/features/data-discovery/tagging#known-limitations-and-operator-caveats) and [Per-column annotation → Known limitations](/features/data-discovery/per-column-annotation#known-limitations-and-operator-caveats).
* `DATASET_TEST_RUN_SET_SEVERITY`. Allows setting severity for a dataset's quality tests.

#### Term permissions

* `TERM_CREATE`. Allows creating a new term in the business glossary.
* `TERM_DELETE`. Allows deleting a term from the business glossary.
* `TERM_OWNERSHIP_CREATE`. Allows creating ownership for a term.
* `TERM_OWNERSHIP_DELETE`. Allows deleting ownership from a term.
* `TERM_OWNERSHIP_UPDATE`. Allows editing the title of a term ownership.
* `TERM_TAGS_UPDATE`. Allows editing tags for a term. **Operator caveat**: novel tag names mint new rows in the global tag directory through this path. **No activity-feed event is emitted today** when term tags change — compliance / audit workflows depending on tag-change history must instrument this path externally. See [Manual Object Tagging → Known limitations and operator caveats](/features/data-discovery/tagging#known-limitations-and-operator-caveats).
* `TERM_UPDATE`. Allows editing the name, namespace, and definition of a term.

#### Query Example permissions

* `QUERY_EXAMPLE_CREATE`. Allows creating a query example.
* `QUERY_EXAMPLE_DATASET_CREATE`. Allows linking a query example to a dataset.
* `QUERY_EXAMPLE_DATASET_DELETE`. Allows unlinking a query example from a dataset.
* `QUERY_EXAMPLE_DELETE`. Allows deleting a query example.
* `QUERY_EXAMPLE_TERM_CREATE`. Allows linking a query example to a term.
* `QUERY_EXAMPLE_TERM_DELETE`. Allows unlinking a query example from a term.
* `QUERY_EXAMPLE_UPDATE`. Allows editing a query example.

#### Lookup table permissions

* `LOOKUP_TABLE_CREATE`. Allows creating a lookup table.
* `LOOKUP_TABLE_DATA_CREATE`. Allows adding data rows to a lookup table.
* `LOOKUP_TABLE_DATA_DELETE`. Allows deleting data rows from a lookup table.
* `LOOKUP_TABLE_DATA_UPDATE`. Allows editing data rows in a lookup table.
* `LOOKUP_TABLE_DEFINITION_CREATE`. Allows defining the structure (columns) of a lookup table.
* `LOOKUP_TABLE_DEFINITION_DELETE`. Allows deleting the structure (columns) of a lookup table.
* `LOOKUP_TABLE_DEFINITION_UPDATE`. Allows modifying the structure (columns) of a lookup table.
* `LOOKUP_TABLE_DELETE`. Allows deleting a lookup table.
* `LOOKUP_TABLE_UPDATE`. Allows editing the name and description of a lookup table.

#### Management permissions

* `COLLECTOR_CREATE`. Allows registering a new metadata collector.
* `COLLECTOR_DELETE`. Allows deleting a collector.
* `COLLECTOR_TOKEN_REGENERATE`. Allows regenerating the security token for a collector. **Operational caveat**: regeneration invalidates the prior token immediately — there is no grace period. The Collector process must be redeployed with the new token before existing ingestion stops.
* `COLLECTOR_UPDATE`. Allows editing a collector's configuration.
* `DATA_ENTITY_GROUP_CREATE`. Allows creating a new data entity group.
* `DATA_SOURCE_CREATE`. Allows creating a new data source connection.
* `DATA_SOURCE_DELETE`. Allows deleting a data source.
* `DATA_SOURCE_TOKEN_REGENERATE`. Allows regenerating the security token for a data source. **Operational caveat**: regeneration invalidates the prior token immediately — there is no grace period. The push-client must be redeployed with the new token before existing ingestion stops.
* `DATA_SOURCE_UPDATE`. Allows editing an existing data source's configuration.
* `DIRECT_OWNER_SYNC`. Allows associating a user with an owner without an approval request. **Composition caveat**: when the holder submits the home-page form with an owner name that does not exist in the catalog, the platform creates the owner on the requester's behalf and immediately binds them to it — in a single POST. Grant this permission only to principals you also trust to mint owner names (typically a service identity, not an end-user policy). See [User-owner association → How DIRECT\_OWNER\_SYNC changes the user-side flow](/configuration-and-deployment/enable-security/authorization/user-owner-association#how-direct_owner_sync-changes-the-user-side-flow).
* `NAMESPACE_CREATE`. Allows creating a new namespace via `POST /api/namespaces`. **Operator caveat — four sister-service side-doors**: four other parent permissions (`DATA_SOURCE_CREATE`, `DATA_SOURCE_UPDATE`, `TERM_CREATE`, `COLLECTOR_CREATE`, `DATA_ENTITY_GROUP_CREATE`) silently mint namespace rows through their `namespace_name` form field. Granting any of those parent permissions is an indirect grant of namespace-creation rights. See [Namespaces → Auto-create side-door](/features/management/namespaces#auto-create-side-door) for the four-vertex cluster and the operator-side mitigation.
* `NAMESPACE_DELETE`. Allows soft-deleting a namespace. **Operator caveat — cascade-block**: the delete is blocked with `CascadeDeleteException` (HTTP 400, error code `USR004`) when any of four referent tables (live data sources, live collectors, live terms, non-deleted data entities) still references the namespace. See [Namespaces → Cascade-on-delete guard](/features/management/namespaces#cascade-on-delete-guard) for the operator workflow and the partial-unique-index reincarnation behaviour after a successful soft-delete.
* `NAMESPACE_UPDATE`. Allows editing an existing namespace.
* `OWNER_ASSOCIATION_MANAGE`. Allows approving or denying user-owner association requests on the **Management → Associations → New requests** sub-tab. Also gates visibility of the Associations Management tab itself. Does **not** grant the admin direct-bind affordance — that requires `OWNER_RELATION_MANAGE` (see below). See [User-owner association → Approving incoming requests](/configuration-and-deployment/enable-security/authorization/user-owner-association#approving-incoming-requests-new-requests-tab).
* `OWNER_CREATE`. Allows creating a new owner entity via `POST /api/owners`. **Note:** three other service-tier code paths also mint Owner rows without consulting this permission — see [Owners → Three service-tier side-doors](/configuration-and-deployment/enable-security/authorization/owners#3-three-service-tier-side-doors-mint-owner-rows-without-owner_create).
* `OWNER_DELETE`. Allows deleting an owner via `DELETE /api/owners/{id}`. The delete is gated on no remaining ownership relations, term-ownership relations, or user-Owner bindings — operators see a `CascadeDeleteException` if any of those are still attached.
* `OWNER_RELATION_MANAGE`. Allows directly creating or removing the binding between a user and an owner — the **Create association** button in the Management → Associations header, and the per-row **Remove** on the Active associations sub-tab. Operators with this permission bypass the user-self-request and admin-approve workflow entirely. See [User-owner association → Creating a binding directly](/configuration-and-deployment/enable-security/authorization/user-owner-association#creating-a-binding-directly-create-association) and [Removing an existing binding](/configuration-and-deployment/enable-security/authorization/user-owner-association#removing-an-existing-binding-active-associations-tab). **Downstream-impact note:** the binding this permission creates is the single load-bearing anchor for the `/api/dataentities/my[/upstream|/downstream]` lineage triplet — every regression at the binding-resolution step has cross-owner blast radius on the lineage neighbourhood; see [Data Lineage → My-objects triplet](/features/data-lineage#my-objects-triplet-composition-anchor-architecture) for the architecture.
* `OWNER_UPDATE`. Allows editing an existing owner via `PUT /api/owners/{id}`. **Destructive-API caveat:** PUT with an empty (or absent) `roles` array silently removes every existing role binding from the Owner — see [Owners → PUT with empty roles destroys all role bindings](/configuration-and-deployment/enable-security/authorization/owners#4-put-apiownersid-with-empty-or-absent-roles-silently-destroys-all-role-bindings) for the safe-pattern fetch-modify-write workflow.

{% hint style="info" %}
**There is no `OWNER_READ` permission.** `GET /api/owners` is reachable to any authenticated user (and anonymous under `auth.type=DISABLED`) — it is part of the [read-collaborative posture on Management catalogs](#management-permissions) documented in the warning admonition at the bottom of this section.
{% endhint %}

* `POLICY_CREATE`. Allows creating a new access policy.
* `POLICY_DELETE`. Allows deleting an access policy.
* `POLICY_UPDATE`. Allows editing an existing access policy.
* `ROLE_CREATE`. Allows creating a new user role.
* `ROLE_DELETE`. Allows deleting a user role.
* `ROLE_UPDATE`. Allows editing an existing user role.
* `TAG_CREATE`. Allows creating a new tag. **Operator caveat**: `TAG_CREATE` is not the only path that mints new tags — four `*_TAGS_UPDATE` permissions (data entity, dataset field, term) plus collector ingestion all silently create tag rows for novel names. See [Manual Object Tagging → Known limitations and operator caveats](/features/data-discovery/tagging#known-limitations-and-operator-caveats).
* `TAG_DELETE`. Allows deleting a tag.
* `TAG_UPDATE`. Allows editing an existing tag.

{% hint style="warning" %}
**Read access on Management catalogs is granted to every authenticated user by design.** None of the Management permissions above gates the corresponding GET endpoint — withholding `OWNER_CREATE`, `NAMESPACE_CREATE`, `DATA_SOURCE_CREATE`, etc. does **not** restrict reads of the matching catalog. The endpoints below fall through to the platform's catch-all "any authenticated user" rule:

* `GET /api/owners` — every owner row (name, roles, provider mapping).
* `GET /api/owners/providers` — the active identity providers list.
* `GET /api/owner_association_request/activity` — the resolved-associations log (the **History** sub-tab; see [User-owner association → Auditing past association requests](/configuration-and-deployment/enable-security/authorization/user-owner-association#auditing-past-association-requests-history-tab)).
* `GET /api/namespaces` — every namespace, including names that may reveal organisational structure.
* `GET /api/datasources` — every registered data source (URL, ODDRN, namespace).
* `GET /api/collectors` — every collector, including a partially-redacted token until **Regenerate** is invoked.
* `GET /api/titles` — every catalog title vocabulary entry.

Operators who want to restrict read access on a Management catalog cannot do so through this permission set today. Plan deployments accordingly — anything sensitive enough to require read-side RBAC belongs on a different surface.
{% endhint %}

#### Comprehensive permissions

* `ALL`. Includes all permissions above.

## Permission read surface (two-endpoint orchestration)

Integrators consuming the platform's permission catalogue via the API need both of the endpoints below — the two scopes are orthogonal and the API does not unify them into a single call.

| Endpoint                                            | Scope                             | What it returns                                                                                                                                                                 | Example resource types                               |
| --------------------------------------------------- | --------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------- |
| `GET /api/resource/{type}/{id}/permissions`         | Contextual / resource-scoped      | The permissions the caller holds **in the named resource's context** (per-entity, per-term, per-query-example).                                                                 | `DATA_ENTITY`, `TERM`, `QUERY_EXAMPLE`               |
| `GET /api/identity/whoami` → `Identity.permissions` | Non-contextual / management-scope | The permissions the caller holds **globally** for management operations — Policy / Role / Owner / Datasource / Collector / Namespace / Tag / Lookup Table / Query Example CRUD. | (returned as a flat permission list, no resource ID) |

{% hint style="warning" %}
**`PermissionResourceType.MANAGEMENT` is a valid spec enum value but the runtime rejects it on the contextual endpoint.** The OpenAPI `PermissionResourceType` schema declares four values (`DATA_ENTITY`, `TERM`, `QUERY_EXAMPLE`, `MANAGEMENT`). Calling `GET /api/resource/MANAGEMENT/{id}/permissions` returns **HTTP 400 USR001** with the body `Resource type MANAGEMENT does not have context` — management-scope permissions are intentionally returned by the `/api/identity/whoami` endpoint, not the contextual one. SDK code generated from the spec that builds a 4-way switch over `PermissionResourceType` and dispatches all four to the contextual endpoint will see unexpected 400 responses on `MANAGEMENT` calls; route those to `whoami` instead. A spec-side tightening is tracked upstream.
{% endhint %}

### Five categories versus four resource types

The five permission groupings on this page (Data entity / Term / Query Example / Lookup table / Management) are an operator-readable taxonomy — they correspond to where permissions appear in the Management UI and how the runtime services consume them. The `PermissionResourceType` enum in the OpenAPI spec has **four values** because `LOOKUP_TABLE_*` permissions are stored within the Management bucket on the read surface (the runtime treats them as non-contextual / management-scope and returns them from `/api/identity/whoami`, not from `GET /api/resource/LOOKUP_TABLE/...` — there is no `LOOKUP_TABLE` resource type at the API contract).

An integrator dispatching from the four-value enum gets every permission the caller holds; the five-category page taxonomy is the framing operators use when reading the catalogue.

## Surfaces without per-resource permission gating today

Some read surfaces that an operator might assume are gated by a per-resource permission are reachable to any authenticated caller. The Management catalogs above (`GET /api/owners`, `GET /api/namespaces`, `GET /api/datasources`, …) are one such cluster — documented in the read-collaborative-posture warning above. The other cluster operators routinely meet is **dataset structure / version reads**:

* `GET /api/datasets/{data_entity_id}/structure` — the latest schema of any dataset.
* `GET /api/datasets/{data_entity_id}/structure/{version_id}` — any historical schema revision.
* `GET /api/datasets/{data_entity_id}/structure/diff?first_version_id=…&second_version_id=…` — the side-by-side diff between any two revisions.

The path component `{data_entity_id}` is consumed by the controller but **not** used by the underlying query — the query filters on `version_id` alone. Any authenticated caller enumerating `version_id` integers reads any dataset's schema; under `auth.type=DISABLED`, anonymously. The page-side detail (and the multi-tenant operator-mitigation table) lives on [Dataset schema diff → Known limitations](/features/data-discovery/schema-diff#known-limitations-and-operator-caveats).


# Roles

Roles bundle permissions. User roles (auth-chain-derived) versus Owner roles (operator-curated), and the precedence rule that resolves which wins for a given signed-in user.

A **Role** is a named bundle of permissions. ODD Platform has two distinct kinds of Role — **User roles** (derived from the auth chain at sign-in time) and **Owner roles** (operator-curated bundles attached to Owner entities) — and a precedence rule that resolves which kind wins for a given signed-in user.

## User roles

There are two user roles:

* `USER` — a regular user with no permissions by default.
* `ADMIN` — an administrator with every permission.

User-role assignment is derived from your authentication mode's configuration: the platform inspects the auth-mode-specific group / role / principal mapping (Cognito groups, GitHub teams, Azure roles, LDAP groups, Google admin-principals, etc.) at sign-in time and assigns either `ADMIN` or `USER` accordingly. For the full per-provider matrix of how admin promotion works, see [Admin promotion across providers](/configuration-and-deployment/enable-security/admin-promotion).

## Owner roles

Owner roles are operator-curated bundles attached to Owner entities, managed at `Management → Roles`. Unlike User roles (two fixed values: `ADMIN` / `USER`), Owner roles are arbitrary — operators define them per deployment and compose the permissions each role bundle should carry.

### Attaching a Role to an Owner

Role-to-Owner attachment happens on the `Management → Owners` surface — open the Owner row, edit it, and pick the Roles to attach. See [Owners → Owner roles](/configuration-and-deployment/enable-security/authorization/owners#owner-roles) for the operator workflow. The `ROLE_CREATE` / `ROLE_UPDATE` / `ROLE_DELETE` permissions gate role-bundle authoring; the `OWNER_UPDATE` permission gates the role-attachment action itself (it is a write to the Owner entity).

### Precedence: Owner roles override User roles

When a signed-in user is bound to an Owner (via the [User-owner association](/configuration-and-deployment/enable-security/authorization/user-owner-association) workflow) **and that Owner carries at least one role**, the user's effective permissions come from the **Owner's** roles — not from the User role the auth chain assigned at sign-in. A user who signed in as `ADMIN` and then binds to an Owner that carries only a `Data Engineer` role **loses** the ADMIN privilege and runs with the Data Engineer permission bundle.

**The override is conditional on the Owner having roles.** If the bound Owner has **no roles attached**, the platform falls back to the User role the auth chain assigned at sign-in — so binding to a zero-role Owner does *not* strip a signed-in `ADMIN`'s privileges; that user keeps ADMIN. The override applies only when the Owner's role set is non-empty.

For a non-empty Owner role set the override is permanent for the lifetime of the binding: only an unbind (or a re-bind to a different Owner) restores or changes the effective permission set.

{% hint style="danger" %}
**Under `auth.type=DISABLED` authorization is not enforced at all.** Neither User roles nor Owner roles are consulted, and every request runs unrestricted — regardless of any Owner binding or role attachment. The precedence rules above take effect only when authentication is enabled (`LOGIN_FORM`, `OAUTH2`, or `LDAP`). `DISABLED` is the shipped default; see [Disable authentication](/configuration-and-deployment/enable-security/authentication/disabled-authentication) and switch `auth.type` to an enforced mode before exposing the platform on any reachable network.
{% endhint %}

### Setting up an initial admin

To set up a signed-in user who should have full ADMIN privileges through the catalog side, do **both** halves explicitly:

1. **Create an Owner with an ADMIN-equivalent Role bundle attached.** Either create a new Role on Management → Roles that carries `ALL` permissions, or pick an existing ADMIN-equivalent Role; then create the Owner on Management → Owners with that Role attached. Skipping this step and trying to "rely on" the user's sign-in ADMIN authority does not work once the user binds to any Owner that lacks ADMIN — the precedence rule above strips the auth-mode ADMIN at bind time.
2. **Bind the user to that Owner.** The recommended admin path is the **Create association** button on Management → Associations (gated by `OWNER_RELATION_MANAGE`) — this is the admin-direct-bind path that writes the binding immediately, without going through the request-and-approve workflow. See [User-owner association → Creating a binding directly](/configuration-and-deployment/enable-security/authorization/user-owner-association#creating-a-binding-directly-create-association) for the full form fields and behaviour.

The sequence matters: bind the user to an Owner that already carries the ADMIN role bundle. If you bind first and attach the Role second, the binding is effective immediately and the user runs without ADMIN during the gap.

## Where to next

* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the catalog of permission keys you can bundle into Role definitions.
* [Policies](/configuration-and-deployment/enable-security/authorization/policies) — the JSON permission grants attached to owners through roles; note that **deleting a policy is blocked while any role is still bound to it** — detach it from every role first (full note on that page).
* [Owners](/configuration-and-deployment/enable-security/authorization/owners) — how Owner entities work and the per-page caveat list for Owner CRUD.
* [User-owner association](/configuration-and-deployment/enable-security/authorization/user-owner-association) — the binding workflow that triggers the Owner-role-supersedes-User-role precedence.
* [Admin promotion across providers](/configuration-and-deployment/enable-security/admin-promotion) — for the per-auth-mode story of how the User role is initially assigned.


# Owners

Owners are catalog-side data-steward identities, distinct from authenticated users. Reference for the Owner CRUD model, Owner roles, and the operator caveats around lifecycle and audit.

An **Owner** is a catalog-side identity that represents a data steward — a person, team, or service responsible for a data entity or term. Owners are distinct from the authenticated users who sign in to ODD Platform: a signed-in user binds to an Owner through the [User-owner association](/configuration-and-deployment/enable-security/authorization/user-owner-association) workflow, and from that point on the user's actions on data entities (creating ownership, editing custom metadata, marking statuses) are attributed to the Owner rather than to the raw username.

This page is the operator's reference for the Owner model — what an Owner is, how Owners get created, how Owner roles work, and the known caveats around Owner CRUD that operators authoring deployment-time scripts or compliance-grade audit policies should understand.

## What an Owner is

An Owner is a single row in the `owner` table with a `name` (free-text, unique among active Owners) and a `deleted_at` soft-delete marker. Each Owner can carry zero or more **Owner roles** (RBAC bundles defined on the [Roles](/configuration-and-deployment/enable-security/authorization/roles) page) that grant the bound user catalog-wide permissions. Each Owner can be bound to **at most one** active user (the [user-owner association](/configuration-and-deployment/enable-security/authorization/user-owner-association) is a one-to-one relation), and each user can be bound to at most one Owner.

Owners are the unit of ownership on data entities: an entity's ownership relation references an Owner row, not a user, so reassigning a user to a different Owner moves the user's perceived attribution across every entity without rewriting the entities themselves.

You can browse and manage Owners on the [Management → Owners](/features/management) tab.

<figure><img src="https://3630572601-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGZJ5RdCEQxq16TnRL3Tq%2Fuploads%2Fgit-blob-0c2a804da75b6e2c32ee97854154ad6d6b351bf6%2FScreenshot%202022-11-16%20at%2015.52.13.png?alt=media" alt=""><figcaption><p>Owners management</p></figcaption></figure>

## How Owners are created

There are three write-paths that produce a new row in the `owner` table. Two of them are the curated path (a deliberate operator action); the third is an emergent accretion path that operators should be aware of when modelling their deployment's Owner directory.

* **Operator-curated (the `OWNER_CREATE` path).** An operator with the `OWNER_CREATE` permission uses the **Create owner** affordance on Management → Owners, or `POST /api/owners`. The form fields are `name` and an optional `roles` list. This is the path documented in operator playbooks and the path most deployments use during initial setup.
* **User self-service via the home-page widget.** When a signed-in user reaches the [Owner-association widget](/configuration-and-deployment/enable-security/authorization/user-owner-association#for-regular-users) and types an owner name that does **not** exist in the directory, the platform creates the Owner row on submit (the freeSolo + `OwnerService.getOrCreate` composition described under [Choosing an owner name](/configuration-and-deployment/enable-security/authorization/user-owner-association#choosing-an-owner-name)). The user's request then enters the standard self-request / admin-approve flow. No `OWNER_CREATE` permission is required of the requester — the creation rides on the request submission.
* **Admin auto-approve via `DIRECT_OWNER_SYNC`.** A user holding the `DIRECT_OWNER_SYNC` permission can mint a brand-new Owner name and self-bind in a single POST — see [How DIRECT\_OWNER\_SYNC changes the user-side flow](/configuration-and-deployment/enable-security/authorization/user-owner-association#how-direct_owner_sync-changes-the-user-side-flow). The Owner row is created on the requester's behalf with no admin review.

Beyond these three explicit paths, the platform's `OwnerService.getOrCreate` helper is also reachable from service-tier callers that take an owner-name string and need to attach the corresponding Owner row (entity-ownership creation, term-ownership creation). The auto-create behaviour there is detailed in the [Lifecycle and known caveats](#lifecycle-and-known-caveats) section below.

## Owner names accumulate over time

Because the free-text input on the home-page widget does not deduplicate against case or whitespace variants, the Owner directory naturally accretes near-duplicates (`John Smith` / `john smith` / `John Smith` with a trailing space) as new users sign in over the deployment's lifetime. The platform does not collapse these on read — `john smith` and `John Smith` are distinct Owners, each potentially bound to a different user, each potentially carrying different roles.

**Operator hygiene recommendation:** pick a stable owner-name convention for your deployment (canonical casing, no leading/trailing whitespace, no Unicode look-alikes) and communicate it to new users. Periodically audit Management → Owners for near-duplicates and merge or rename them. An operator with the `OWNER_RELATION_MANAGE` permission can also remove individual user-Owner bindings through the [Active associations tab](/configuration-and-deployment/enable-security/authorization/user-owner-association#removing-an-existing-binding-active-associations-tab).

## Owner roles

An Owner carries an optional list of **roles** — RBAC bundles defined on the [Roles](/configuration-and-deployment/enable-security/authorization/roles) page. When a user is bound to an Owner, the Owner's roles **supersede** the user's auth-mode-derived roles for the purposes of catalog-side authorization. This is the platform's mechanism for granting a user catalog-wide permissions (browse-only, edit-glossary, manage-data-entities, etc.) that are independent of the user's identity-provider group memberships.

Attach roles to an Owner from the Management → Owners → Edit form. The `ROLE_CREATE` / `ROLE_UPDATE` / `ROLE_DELETE` permissions gate role management itself.

## Owners on data entities

Ownership of a data entity is recorded as a relationship from the entity to one or more Owner rows, with an optional Owner role (the "title" of that ownership — for example, `Steward`, `Subject Matter Expert`, `On-call`). The relation is curated per-entity on the entity's detail page; the `DATA_ENTITY_OWNERSHIP_CREATE` / `_UPDATE` / `_DELETE` permissions gate those actions.

For the user-facing surface where ownership is curated and displayed, see the [Data entity detail page → Permissions](/features/data-discovery/entity-detail-page) reference.

## Lifecycle and known caveats

The Owners API surface and the Owner-CRUD service tier have four operator-visible behaviours that are not obvious from the per-page documentation alone. Each item below names what an operator might assume, what actually happens, and what to do today.

### 1. Owner CRUD events are not audited at the platform tier

The Owner service creates, updates, soft-deletes, and re-creates Owners inside a transactional context but emits **no Activity Feed event** on any of those operations. The activity table's schema requires a `data_entity_id` foreign key on every row — Owner CRUD has no data-entity context, so adding an activity emission to the existing stream would require a coordinated schema change. The `owner_association_request_activity` stream covers the request workflow (user submits → admin approves/denies) but not the Owner entity's own lifecycle.

Combined with the role-binding hard-delete on the Owner DELETE path and the partial-unique-index pattern that allows soft-deleted names to be re-used by a new Owner row, an operator can delete `Alice`, recreate a new `Owner` row with the name `Alice`, and there is no platform-visible record of the rename or the original deletion except the original row's `deleted_at` timestamp.

For compliance frameworks that require identity-change audit trails (SOX records of identity-management changes, NIST 800-53 AU-2 audit events), use one of the compensating controls in [Audit trail scope → Compliance implications](/configuration-and-deployment/enable-security/audit-trail-scope#compliance-implications-and-compensating-controls).

### 2. `GET /api/owners` is unauthenticated-read; every signed-in user enumerates the directory

The `/api/owners` endpoint's POST / PUT / DELETE verbs are each gated by an `OWNER_*` permission (see the table below), but the GET verb is **not gated**. There is no `OWNER_READ` permission anywhere on the platform; any authenticated user under `LOGIN_FORM`, `OAUTH2`, or `LDAP` can enumerate the entire Owner directory through `GET /api/owners`. Under `auth.type=DISABLED` the endpoint is anonymously reachable.

| Verb                      | Permission gate                   |
| ------------------------- | --------------------------------- |
| `POST /api/owners`        | `OWNER_CREATE`                    |
| `PUT /api/owners/{id}`    | `OWNER_UPDATE`                    |
| `DELETE /api/owners/{id}` | `OWNER_DELETE`                    |
| `GET /api/owners`         | **none** — any authenticated user |

This matches the platform's broader [read-collaborative posture on Management catalogs](/configuration-and-deployment/enable-security/authorization/permissions#management-permissions): all Management read endpoints are reachable to any signed-in user by design. Deployments that need read-side isolation cannot achieve it through `OWNER_*` permissions today.

### 3. Three service-tier side-doors mint Owner rows without `OWNER_CREATE`

In addition to the three explicit Owner-creation paths described above, three other service-tier code paths reach `OwnerService.getOrCreate` and silently mint an Owner row when their input names one that does not exist:

* `POST /api/owner_association_request` — the user-self-request endpoint (any authenticated user). Creating a request with a never-before-seen owner name creates the Owner row before the admin review starts.
* `POST /api/dataentities/{data_entity_id}/ownership` — gated by `DATA_ENTITY_OWNERSHIP_CREATE`. Attaching ownership to an entity with a brand-new owner-name string creates the Owner.
* `POST /api/terms/{term_id}/ownership` — gated by `TERM_OWNERSHIP_CREATE`. Attaching ownership to a glossary term with a brand-new owner-name string creates the Owner.

**Operator consequence:** an operator who grants `DATA_ENTITY_OWNERSHIP_CREATE` to a role expecting it to be a strict "attach to existing Owner" capability actually grants "mint Owner + attach" — the new Owner row appears in `GET /api/owners` immediately and persists across the rename or removal of the entity that triggered its creation. Monitor Owner-directory growth as part of your audit cadence; if `OWNER_CREATE` is reserved to a small operator group, also audit the three side-door endpoints for unintended Owner-name expansion.

### 4. `PUT /api/owners/{id}` with empty (or absent) `roles` silently destroys all role bindings

The `OwnerFormData.roles` field is marked optional in the OpenAPI spec, but the runtime treats absent-or-empty `roles` as a destructive update: the service helper collapses both `null` and `[]` to the empty list, the update transaction calls `deleteOwnerRelationsExcept(ownerId, [])` (which deletes every existing role-binding on this Owner because no existing binding is in the empty set), and then `createRelations(ownerId, [])` (which inserts nothing). The Owner persists; every role-binding is gone.

The UI's read-modify-write pattern always sends the current `roles` array in its PUT request, so the destructive path never surfaces through the Management UI for typical workflows. Direct-API consumers (Terraform providers, CI scripts, automation jobs) calling the endpoint with a partial body — for example, a rename — hit the destructive path on the first omission.

{% hint style="danger" %}
**`PUT /api/owners/{id}` with body `{"name": "new_name"}` removes every role binding on the Owner.** The OpenAPI spec presents `roles` as optional, but the runtime treats absent and empty identically. Always include the current `roles` array verbatim when issuing a PUT request, even for rename-only operations. A platform-side fix that adopts PATCH semantics (with `null` meaning "no change") or marks `roles` required is tracked upstream.
{% endhint %}

Safe-pattern code for direct-API consumers performing a rename:

```bash
OWNER=$(curl -X GET "$ODD/api/owners/$ID" | jq)
NEW_NAME="new_name"
NEW_BODY=$(echo "$OWNER" | jq --arg n "$NEW_NAME" '.name = $n')
curl -X PUT "$ODD/api/owners/$ID" \
     -H "Content-Type: application/json" \
     -d "$NEW_BODY"
```

The fetch-modify-write pattern preserves the existing `roles` array (and any other optional field with the same destructive semantic). UI workflows do not need this pattern — the Management UI already does the fetch-modify-write internally.

## Operator-facing surfaces that depend on user-owner association

A signed-in user without a `user_owner_mapping` row sees every `My`-scoped surface render empty — the platform cannot answer "what changed on the things you own" without the binding. The personalised surfaces that depend on the association:

* The **Activity Feed**'s `My Objects` / `Upstream Dependents` / `Downstream Dependents` tabs (see [Activity Feed → My Objects setup](/features/active-platform-features/activity-feed#my-objects-setup-user-owner-association-prerequisite)).
* The **Alerts** page's `My Objects` / `Downstream` / `Upstream` tabs (see [Alerting → Alert views](/features/active-platform-features/alerting#alert-views-all-my-objects-downstream-upstream)).
* The recommended-entities widgets on the catalog home page.

A platform admin who creates Owners and binds others without creating a mapping for their own account experiences these surfaces as silent-empty during onboarding — a common "platform is broken" first impression. Adding yourself as an Owner on the entities you want surfaced (Management → Associations → Create association) is the fix; the binding only affects what your account sees and does not change anyone else's access.

## Where to next

* [User-owner association](/configuration-and-deployment/enable-security/authorization/user-owner-association) — the user-side workflow for binding to an Owner, the three write-paths in full, the admin operational surface, and the post-association lifecycle.
* [Roles](/configuration-and-deployment/enable-security/authorization/roles) — the RBAC bundle definitions that Owners can carry, and the precedence rules when an Owner role and a user-derived role both apply.
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the full enumeration of permission keys, including the `OWNER_*` rows referenced above.
* [Management → Owners](/features/management) — the operator UI tab where Owners are browsed, created, edited, and deleted.
* [Audit trail scope](/configuration-and-deployment/enable-security/audit-trail-scope) — for the broader picture of what the platform audits and the compensating controls for the negative-half subjects (RBAC, Owner, Term, Namespace, Datasource, Collector lifecycle).


# User-owner association

Link a signed-in user to an Owner entity for owner-scoped permissions — three write-paths — self-request, self-request with auto-approve, and admin direct-bind.

User-owner association links a signed-in user to an [owner](/configuration-and-deployment/enable-security/authorization/owners) entity. Without an association, the user cannot manage data entities and cannot be granted ownership-scoped permissions through an owner's [Role](/configuration-and-deployment/enable-security/authorization/roles) bundles.

The platform supports three write-paths to create the binding:

* **Self-request, then admin approves** — a regular user submits a request from the home page; an administrator approves it on Management → Associations → New requests.
* **Self-request with auto-approve** — a user holding the `DIRECT_OWNER_SYNC` permission submits the same form; the platform auto-approves on the spot.
* **Admin direct-bind** — an administrator holding the `OWNER_RELATION_MANAGE` permission creates the binding directly from Management → Associations using the **Create association** button.

{% hint style="info" %}
User-owner association is a one-to-one relation. A user can be associated with only one owner, and an owner can be associated with only one user at a time.
{% endhint %}

## For regular users

After signing in, scroll to the bottom of the [Catalog Overview](/features/data-discovery/catalog-overview) home page. The **Owner association** widget appears inline as the last block on the page — it is not a modal dialog and has no overlay.

The widget shows a single input — **Owner name** — and a **Send a request** button.

### Choosing an owner name

Type to search the existing owner directory. As you type, the platform searches the catalog; suggested matches against your username appear under **Maybe it's you**.

If no existing owner matches the name you typed, **the platform creates a new owner with exactly that name when you submit**. This is by design — operators want users to be able to bind to a brand-new owner — but it also means typos and casing variants ("John Smith" vs "john smith" vs "John Smith") accumulate in the owner directory.

**Recommendation for operators:** pick a stable owner-name convention for your deployment (case, whitespace, trailing characters) and communicate it to new users. The owner directory can be cleaned up by an administrator from Management → Owners; an administrator with the `OWNER_RELATION_MANAGE` permission can also remove individual bindings via Management → Associations → Active associations (see below).

### After you submit

When you press **Send a request**, your request appears on Management → Associations → **New requests** for an administrator to review.

While your request is pending, the home-page widget is replaced with a **Request is being checked** message.

### If your request is declined

If an administrator declines your request, the next time you reach the home page you see a banner above a fresh request form. You can dismiss the banner with the **X** button, but **the dismissal does not persist** — refreshing the page or signing in again brings the banner back until you submit another request.

There is no per-decline-reason surface; the message is the same regardless of why the request was declined. If you need the reason, ask the administrator directly.

### Changing or removing your association

Once your association is approved, you have no self-service path to change or remove it. The home-page widget now shows your owner's entities and does not offer a **Disassociate** or **Switch owner** action.

To switch to a different owner, or to remove your binding entirely, **ask an administrator with the `OWNER_RELATION_MANAGE` permission to remove the binding** via Management → Associations → Active associations (see [Removing an existing binding](#removing-an-existing-binding-active-associations-tab) below). After removal, the request form reappears on your next sign-in.

## For administrators

The administrative workflow lives at [**Management → Associations**](/features/management) — a top-nav tab with three sub-tabs: **New requests** (incoming pending requests), **Active associations** (existing bindings), and **History** (resolved requests audit).

The **Associations** tab is hidden from operators who do not hold the `OWNER_ASSOCIATION_MANAGE` permission.

### Approving incoming requests (New requests tab)

The **New requests** sub-tab lists every open pending request, one row per user. Each row shows:

| Column         | Source                                      |
| -------------- | ------------------------------------------- |
| **User name**  | The signed-in user's OIDC / LDAP username   |
| **Owner name** | The owner the user requested                |
| **Role**       | Owner roles attached to that owner (if any) |
| **Provider**   | The auth provider the user signed in with   |

Per-row **Accept** and **Reject** buttons each open a confirmation dialog before writing. Accept records the request as APPROVED and writes the user-owner binding; Reject records it as DECLINED. Both actions are written to the audit channel surfaced on the **History** sub-tab and require the `OWNER_ASSOCIATION_MANAGE` permission.

### Creating a binding directly (Create association)

In the **Associations** tab header, operators holding the `OWNER_RELATION_MANAGE` permission see a **Create association** button. (The button is hidden for operators without the permission.)

Clicking it opens a modal form with three required fields:

| Field        | Notes                                                                                                                                                                                                                                     |
| ------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Owner**    | Pick from the existing owner directory — this path does not create new owners.                                                                                                                                                            |
| **User**     | Free-text — type the OIDC / LDAP username verbatim. The platform does not verify the username exists in your identity provider; an incorrect username is accepted at the API level and silently produces a binding nobody can sign in to. |
| **Provider** | Pick from the list of providers active on this deployment.                                                                                                                                                                                |

On submit, the platform writes the binding directly — there is no intermediate "pending" state and no second-administrator approval. The action is gated by the `OWNER_RELATION_MANAGE` permission (not `OWNER_ASSOCIATION_MANAGE`).

{% hint style="warning" %}
**Provider is not always a reliable discriminator.** The Provider value you pick here (and the Provider column shown across the New requests, Active associations, and History tabs) does not isolate a binding to one sign-in method in every deployment. Both `LOGIN_FORM` and `LDAP` logins are stored with an empty provider, so a binding made for one is matched for the other when the username is the same. If your deployment has run more than one auth mode over its lifetime, read the [cross-mode user-name collision](/configuration-and-deployment/enable-security/authentication/login-form#cross-mode-user-name-collision-activity-feed-read-paths) caveat before relying on Provider to keep two same-named users apart.
{% endhint %}

### Removing an existing binding (Active associations tab)

The **Active associations** sub-tab lists every approved binding — one row per user-owner pair, with the columns from the New requests tab plus **Resolved by** (the administrator who approved or created the binding) and **Resolved at**.

Each row has a **Remove** button that opens a confirmation dialog reading *"User X will stop being associated with owner Y."* On confirm, the binding is deleted at the platform tier.

**Remove is the only operator-side path to undo any binding** — including bindings created through the auto-approve short-circuit (`DIRECT_OWNER_SYNC`) and through the admin **Create association** button.

The backend permission gate on this endpoint is `OWNER_RELATION_MANAGE`. On the current UI, the Remove button is enabled when the operator holds `OWNER_ASSOCIATION_MANAGE` — so an operator who holds only `OWNER_RELATION_MANAGE` may see the button but the backend will accept the call, and an operator who holds only `OWNER_ASSOCIATION_MANAGE` may click the button only to have the backend reject it. Until that inconsistency is resolved, grant both permissions to operators who need direct-bind authority.

#### After you remove an association

The confirmation dialog describes the local effect only. The wider consequences for the affected user:

* Their **My objects** view in [Activity Feed](/features/active-platform-features/activity-feed) goes empty.
* Their **My** view in [Alerting](/features/active-platform-features/alerting) goes empty.
* Any ownership-scoped permissions granted through the owner's [Role](/configuration-and-deployment/enable-security/authorization/roles) bundles are no longer applied on their next request.

The user is not notified by the platform. If they reach out about empty dashboards or missing access shortly after, an unbind is the likely cause.

### Auditing past association requests (History tab)

The **History** sub-tab lists resolved requests — both APPROVED and DECLINED — in reverse chronological order. The columns are User name, Owner name, Role, Provider, Resolved by, Status, Resolved at.

This sub-tab is read-only. The underlying activity stream is reachable to any signed-in user — operators auditing who-approved-what should be aware that the resolved-association log is part of the platform's read-collaborative posture on Management surfaces (see [Permissions → Read access on Management catalogs](/configuration-and-deployment/enable-security/authorization/permissions#management-permissions)).

All three write-paths are recorded here, not only the request-approval path. Approving or rejecting a pending request, creating a binding directly with **Create association**, and removing a binding from **Active associations** each write a row to the same audit stream, and the History tab shows them all:

| Write-path                                 | Recorded as |
| ------------------------------------------ | ----------- |
| Approve a pending request                  | Approved    |
| Reject a pending request                   | Declined    |
| **Create association** (admin direct-bind) | Approved    |
| **Remove** a binding                       | Declined    |

A binding created with **Create association** therefore appears in History as an Approved row, and a removal appears as a Declined row — both attributed to the administrator who performed them. The History tab is a complete record of every association decision on the deployment.

## How `DIRECT_OWNER_SYNC` changes the user-side flow

If a user holds the `DIRECT_OWNER_SYNC` permission — typically granted to a Policy that fast-paths users mapped from a trusted OIDC group — the home-page request form behaves the same, but on submit the platform short-circuits the administrator-approval step entirely. The owner row is created if it did not exist, the binding is written, and the request is recorded as APPROVED in one transaction. The button label on the form changes from **Send a request** to **Associate** to reflect the immediate effect.

The administrator never sees the request on the **New requests** sub-tab; it lands directly on **History** as APPROVED with no human reviewer.

{% hint style="warning" %}
**Operator caution.** Granting `DIRECT_OWNER_SYNC` is consequential beyond "speeding up admin approval." The permission also composes with the new-owner-on-submit behaviour described under [Choosing an owner name](#choosing-an-owner-name) — a holder can mint a brand-new owner name and self-bind to it in one POST. Grant it only to principals you also trust to mint owner names (typically a service identity, not an end-user policy). See the [Permissions](/configuration-and-deployment/enable-security/authorization/permissions#management-permissions) page for the full caveat.
{% endhint %}


# Admin promotion across providers

Single reference for ADMIN-promotion divergence across the four auth modes and the six OAuth2 provider sub-shapes — the matrix, the per-provider knobs that look the same but behave differently.

ODD Platform has **four top-level authentication modes** (`DISABLED`, `LOGIN_FORM`, `OAUTH2`, `LDAP`), and the `OAUTH2` mode supports **six provider sub-shapes** (AWS Cognito, GitHub, Google, Azure AD, ODD\_IAM, plus a Custom OIDC fallback that Okta and Keycloak deployments use today). Whether a given user becomes `ADMIN` on login depends on the mode, the provider, and a handful of configuration knobs whose names look the same across providers but **behave differently per provider runtime**.

This page is the single reference for that divergence. Use it to (1) understand what a configured value will actually do on your provider, (2) plan migrations between auth modes without losing or accidentally widening ADMIN grants, and (3) pick a provider for a new deployment based on the precision of the admin grant.

Per-provider operational details live on the provider's own page; this page focuses on the comparison.

## Admin-promotion matrix

| #   | Mode / provider                         | Admin-detection mechanism                                                                                                                              | Match semantic                                            | Notable caveat                                                                                                                                                                                                                                                                                    |
| --- | --------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------ | --------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| 1   | `LDAP`                                  | `auth.ldap.groups.admin-groups` against the user's LDAP group memberships                                                                              | **case-insensitive, full group-name match**               | A token must equal a group name in full (case ignored): `admin-groups: [ops]` promotes members of `ops` / `Ops` / `OPS` but **not** `devops` or `team-ops`. If `admin-groups` is empty, every user is `USER` with no path to ADMIN                                                                |
| 2   | `OAUTH2` → AWS Cognito                  | `admin-groups` (against the `cognito:groups` claim) and `admin-principals` (email / configured username attribute)                                     | case-insensitive, full match                              | The match ignores case (`Admins` and `admins` both match) but requires the whole value — it is not a substring match                                                                                                                                                                              |
| 3   | `OAUTH2` → GitHub                       | `admin-principals` (login) **before** the `organization-name` check; `admin-groups` (team name) **after**, against `/user/teams`                       | case-insensitive, full match (both principals and groups) | `admin-principals` bypasses `organization-name`; a team token must equal a team name in full (e.g. `admins` does **not** match `team-admins`); GitHub Enterprise Server unsupported (`api.github.com` hard-coded)                                                                                 |
| 4   | `OAUTH2` → Google                       | `admin-principals` (email by default; overridable via `admin-attribute`)                                                                               | case-insensitive, full match                              | The match ignores case but requires the whole value. **`admin-groups` is a silent no-op** — the field binds without error but is never read by the Google handler                                                                                                                                 |
| 5   | `OAUTH2` → Azure AD                     | `admin-principals` (against `admin-attribute`); `admin-groups` against the `roles` claim by default (override to `groups` via `groups-claim`)          | case-insensitive, full match                              | The match ignores case but requires the whole value — it is not a substring match                                                                                                                                                                                                                 |
| 6   | `OAUTH2` → ODD\_IAM                     | userinfo flag from the IAM provider                                                                                                                    | flag-based                                                | —                                                                                                                                                                                                                                                                                                 |
| (7) | `LOGIN_FORM`                            | None — every authenticated user is granted `ADMIN` authority unconditionally                                                                           | —                                                         | The `SECURITY_RULES` table is **not consulted** in this mode; authored Policies do not gate the live auth chain. See [Login form → Authorization posture](/configuration-and-deployment/enable-security/authentication/login-form#authorization-posture-under-login_form).                        |
| —   | Okta, Keycloak, any other OIDC provider | Custom OIDC handler — evaluates `admin-principals` always, and `admin-groups` **only if** you set `groups-claim`                                       | case-insensitive, full match                              | `admin-principals` promotes at login with no extra configuration. `admin-groups` is inert unless `groups-claim` is set, because this handler has no default groups claim. If neither is configured, every user is `USER` and ADMIN promotion is a manual Owner-Role binding via the Management UI |
| —   | `DISABLED`                              | Synthetic admin — `GET /api/identity/whoami` returns `{ username: "admin", permissions: [ … every Permission enum value … ] }` to any anonymous caller | —                                                         | The permission set is `Permission.values()` so a new platform capability is automatically granted. See [Disabled authentication → What's anonymously reachable](/configuration-and-deployment/enable-security/authentication/disabled-authentication#whats-anonymously-reachable).                |

## Provider-specific gotchas

Each item below points at the page that owns the operational detail; this list is the cross-cutting summary so an operator scanning for "what bites me on each provider" has one reading surface.

* **LDAP group-name match is full-string + groups-unset silent USER-only.** `admin-groups: [ops]` promotes members of a group named `ops` (case ignored), but **not** `devops` or `team-ops` — the token must equal the group name in full. An empty `admin-groups` silently leaves the deployment with no LDAP ADMIN path. See [LDAP → Admin promotion](/configuration-and-deployment/enable-security/authentication/ldap#admin-promotion-group-name-matching).
* **GitHub `admin-principals` bypasses `organization-name`.** A login in `admin-principals` is granted `ADMIN` regardless of organization membership — a typo or stale entry that matches an attacker-registerable GitHub login is a platform-ADMIN backdoor. See [OAuth — GitHub](/configuration-and-deployment/enable-security/authentication/oauth2-oidc#github).
* **GitHub `admin-groups` is a full team-name match.** Same shape as LDAP — `admin-groups: [admins]` promotes members of a team named `admins` (case ignored), but **not** `team-admins`, `admins-readonly`, or `data-admins`. Enter each admin team's name exactly as it appears in GitHub. See [OAuth — GitHub](/configuration-and-deployment/enable-security/authentication/oauth2-oidc#github).
* **GitHub Enterprise Server not supported.** `api.github.com` is hard-coded in the GitHub handler with no override knob; GHES deployments cannot use the GitHub provider today. See [OAuth — GitHub](/configuration-and-deployment/enable-security/authentication/oauth2-oidc#github).
* **Google `admin-groups` is a silent no-op.** The field binds without error but the Google handler never reads it; promote with `admin-principals` or `admin-attribute`. See [OAuth — Google](/configuration-and-deployment/enable-security/authentication/oauth2-oidc#google).
* **Okta / Keycloak / Custom OIDC do detect `admin-principals`, but `admin-groups` needs `groups-claim`.** The generic Custom OIDC handler promotes a login whose principal is listed in `admin-principals` (case-insensitive, full match). It reads `admin-groups` only when you also set `groups-claim`, because this handler has no default groups claim. With neither set, every login is `USER` and promotion is manual via the Management UI. See [OAuth — Other OIDC providers](/configuration-and-deployment/enable-security/authentication/oauth2-oidc#other-oidc-providers).
* **`LOGIN_FORM` SECURITY\_RULES are inert.** Every authenticated user is `ADMIN`; the Policy/Role table you author via Management UI does not gate the live auth chain in this mode. See [Login form → Authorization posture](/configuration-and-deployment/enable-security/authentication/login-form#authorization-posture-under-login_form).
* **`DISABLED` synthetic admin is anonymous.** No credentials needed; `Permission.values()` dynamically expands so new capabilities auto-enter the grant. See [Disabled authentication → What's anonymously reachable](/configuration-and-deployment/enable-security/authentication/disabled-authentication#whats-anonymously-reachable).

## Migration-mode notes

When you move between auth modes, the admin-detection rules change underneath you. The notes below name the most common transitions:

* **`DISABLED` → any production mode (`LOGIN_FORM`, `OAUTH2`, `LDAP`).** The synthetic-admin response from `/api/identity/whoami` vanishes — anonymous callers stop seeing ADMIN. Before flipping, read [Disabled authentication → Migrating away from DISABLED](/configuration-and-deployment/enable-security/authentication/disabled-authentication#migrating-away-from-disabled) and audit any `Owner` rows whose `OIDC_USERNAME` matches the literal `admin` or `ADMIN` (collision with the synthetic identities). Any RBAC `Policy` or `Role` you authored while DISABLED was active was never consulted — they take effect for the first time after the migration.
* **`LOGIN_FORM` → `OAUTH2` or `LDAP`.** Policies become consulted for the first time (the LOGIN\_FORM chain omits the `AuthorizationCustomizer`). Test the production-mode Policy table BEFORE migrating; under LOGIN\_FORM every user was ADMIN so Policy bugs were invisible. Cross-mode username collisions surface — see the [cross-mode user-name collision](/configuration-and-deployment/enable-security/authentication/login-form#cross-mode-user-name-collision-activity-feed-read-paths) note.
* **`LDAP` → `OAUTH2`.** `admin-groups` matching is full group-name equality (case ignored) under both LDAP and every OAuth2 provider, so the matching semantic does not change. What changes is the source of the names: LDAP matches your directory's group names, GitHub matches GitHub team names, Cognito matches `cognito:groups`, Azure matches the `roles` (or `groups`) claim. Re-enter `admin-groups` using the new provider's group names; the LDAP group names will not match unless they happen to be identical.
* **Adding S2S to any production mode.** The S2S filter's synthetic principal is literal uppercase `ADMIN`. If you have an existing user named `ADMIN`, that user's owner mapping becomes the S2S caller's owner — see [S2S → Operator caveats](/configuration-and-deployment/enable-security/authentication/s2s#operator-caveats).

## Choosing a provider (decision guide)

For a new deployment, the table below summarises the trade-offs operators most often weigh. Across every mode and provider, `admin-groups` / `admin-principals` matching is **case-insensitive, full-value equality** — a configured token grants ADMIN only when it equals a group name (or principal) in full, with case ignored. There is no substring or prefix matching, so a short token like `ops` cannot accidentally promote `devops`. The columns instead compare what is most worth weighing per provider — whether `admin-groups` works at all on that provider, and whether the platform revokes the token at the IdP on sign-out. **Logout revocation** is whether the platform asks the IdP to revoke the access token on sign-out — see the [logout token-revocation matrix](/configuration-and-deployment/enable-security/authentication/oauth2-oidc#logout-token-revocation-matrix) for details.

All providers match `admin-groups` / `admin-principals` the same way — case-insensitive, full-value equality. The column below therefore compares which knobs each provider actually honours, not match precision.

| Mode / provider                          | Admin grant by                                              | Logout revocation                                          | Best fit for                                         |
| ---------------------------------------- | ----------------------------------------------------------- | ---------------------------------------------------------- | ---------------------------------------------------- |
| `LOGIN_FORM`                             | n/a — every user is ADMIN                                   | n/a — local session only                                   | Dev / demo over HTTPS terminating at a trusted proxy |
| `LDAP`                                   | `admin-groups` (group names)                                | n/a — bind-only auth                                       | Existing LDAP / Active Directory shop                |
| `OAUTH2` → AWS Cognito                   | `admin-principals` + `admin-groups`                         | **no** (the platform does not call `/oauth2/revoke` today) | AWS-first deployments; pair with short token TTL     |
| `OAUTH2` → GitHub                        | `admin-principals` + `admin-groups` (team names)            | **yes**                                                    | github.com-hosted (not GHES) teams                   |
| `OAUTH2` → Google                        | `admin-principals` only (`admin-groups` is a no-op)         | **yes**                                                    | Google Workspace organisations                       |
| `OAUTH2` → Azure AD                      | `admin-principals` + `admin-groups`                         | **no** (Azure v2.0 lacks RFC 7009 — protocol-level)        | Microsoft 365 / Entra ID shops                       |
| `OAUTH2` → ODD\_IAM                      | userinfo flag from the IAM provider                         | **no**                                                     | Vendor-managed ODD deployments                       |
| `OAUTH2` → Okta / Keycloak / Custom OIDC | `admin-principals` (+ `admin-groups` if `groups-claim` set) | **no**                                                     | Existing OIDC IdPs                                   |
| `DISABLED`                               | n/a — anonymous synthetic admin                             | n/a                                                        | Local-only dev; **never** for any reachable network  |

If your security posture requires IdP-level token revocation on logout, **Google** and **GitHub** are today's best matches. If you grant ADMIN by group membership, every mode except Google supports `admin-groups` (Custom OIDC requires `groups-claim` to be set). For any production deployment, audit the trade-offs above against your incident-response model before choosing.


# Audit trail scope

ODD's bifurcated audit posture — what the platform records (activity feed + owner-association log), what it does not, and the compensating controls for SOX / HIPAA / GDPR / SOC2 reviews.

ODD Platform's audit posture is **architecturally bifurcated**. There are two recorded streams — the data-entity activity feed and the owner-association request log — and **everything else** (RBAC mutations, owner lifecycle, term lifecycle, namespace lifecycle, datasource lifecycle, collector lifecycle) leaves **no recoverable trace** on the platform side. The gap is not a missing-annotation oversight; it is rooted in the platform's `activity` table schema and would require a coordinated schema migration to close.

This page is the single reference for compliance auditors, security reviewers, and operators with SOX / HIPAA / GDPR / SOC2 obligations who need to know what the platform records, what it does not record, and what compensating controls to apply when the platform's recorded scope does not match an audit requirement.

The [Activity Feed](/features/active-platform-features/activity-feed) page documents the operational UI for the positive-half audit stream; this page covers the scope of both halves — including the negative half — so an operator can make informed decisions before depending on the platform's audit trail for compliance reporting.

## What IS audited (positive half)

| Subject                                                                                                                      | Where it is stored                                                                       | Event vocabulary                                                                                                                                                                                | Operator surface                                                                                              |
| ---------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------- |
| Data entity changes (descriptions, tags, terms, ownership, metadata, alerts, custom-metadata, statuses, dataset-field edits) | `activity` table — partitioned by `created_at`, every row scoped to one `data_entity_id` | 27-value `ActivityEventTypeDto` enum (see the [Activity Feed → Event types](/features/active-platform-features/activity-feed#event-types) section for the full list with operator descriptions) | Per-entity Activity tab and the global [Activity Feed](/features/active-platform-features/activity-feed) page |
| Owner-association request workflow — user submits an association request, admin accepts or declines, sync events             | `owner_association_request_activity` table (dedicated)                                   | 5-value typed enum (`REQUEST_CREATED`, `REQUEST_APPROVED`, `REQUEST_DECLINED`, `REQUEST_MANUALLY_APPROVED`, `REQUEST_MANUALLY_DECLINED`)                                                        | Per-request audit on Management → Associations                                                                |

Both streams are immutable from the API surface — the platform does not expose a "delete activity row" endpoint. They are append-only at the application tier.

## What is NOT audited (negative half — schema-rooted)

The following surfaces have **no recoverable audit trace anywhere on the platform**. None of the corresponding service implementations emit an activity row, an application log line via `@Slf4j`, or any other persistent record. The reason is architectural — see the next section.

* **RBAC mutations.** Creating, updating, or deleting a Policy or a Role. Renaming a Role. Re-binding a Policy to a different Role. Granting or revoking a Permission. The Policy and Role service implementations carry no audit emission and no logging annotation.
* **Owner lifecycle.** Owner CRUD (create / rename / soft-delete). Owner-to-Role binding changes. The Owner service implementation does not emit on these operations even though `OwnerService.update` is the operator's primary lever for changing who is bound to which Role bundle.
* **Term lifecycle.** Business-glossary Term CRUD — creation, rename, definition edits, deletion. (Term *assignments* on data entities ARE audited; the Term entity itself is not.)
* **Namespace lifecycle.** Namespace CRUD. The namespace identifier is referenced across the catalog (scoping tags, datasources, owners), so renaming or deleting a namespace silently affects downstream visibility without trace.
* **Datasource lifecycle.** Datasource creation, configuration edits, deletion. (Ingestion events from a datasource are surfaced through the data-entity-scoped activity stream on each entity the datasource produced; the datasource entity itself is not audited.)
* **Collector lifecycle.** Collector registration, configuration edits, deletion, token rotation. Token rotation in particular leaves no audit record — see the [`COLLECTOR_TOKEN_REGENERATE` permission](/configuration-and-deployment/enable-security/authorization/permissions#management-permissions) caveat.

## Why this gap exists (architectural framing)

The `activity` table's schema requires a `data_entity_id` foreign key on every row — the column is declared `NOT NULL` and constrained to reference an existing row in the `data_entity` table. The table physically cannot store an event that is not scoped to a single data entity. Adding an "RBAC change" event to the existing audit stream would require either a schema migration making `data_entity_id` nullable plus a discriminator column to identify the alternative subject, or a separate per-subject audit table modelled on the existing `owner_association_request_activity` pattern. Neither change exists today.

The 27-value `ActivityEventTypeDto` enum is similarly data-entity-scoped — every event type names a data-entity attribute (ownership, metadata, schema, tag assignment, status, etc.). Extending the enum with RBAC / Owner / Term / Namespace lifecycle values without the schema change is non-load-bearing — the `NOT NULL` foreign key on `data_entity_id` would still reject the row.

The positive-half pattern — the dedicated `owner_association_request_activity` table — demonstrates the architectural escape hatch. Closing the negative-half gap would require analogous tables (or one consolidated `platform_event` table with a subject discriminator) for each missing subject, plus matching service-tier emission and an operator-surface UI for browsing the new streams.

The architectural change is tracked upstream. Until it ships, the compensating controls below are the operator's remaining options.

## Compliance implications and compensating controls

For deployments with audit obligations (SOX, HIPAA, GDPR, SOC2, internal change-management policies), the negative-half gap means the platform's own logs are **insufficient** for reporting on RBAC, Owner, Term, Namespace, Datasource, and Collector changes. Three compensating controls are practical today; pick whichever matches your existing audit infrastructure:

* **Database-level audit.** Enable PostgreSQL's `pgaudit` extension (or your managed Postgres provider's equivalent) and configure it to capture all mutations against the `policy`, `role`, `owner`, `term`, `namespace`, `data_source`, and `collector` tables. This is the most surgical compensating control — it captures the actual write at the storage tier regardless of which API path triggered it. Be aware that pgaudit captures SQL statements; correlating them to operator identity requires the platform to surface the operator's username on the database connection, which depends on your connection-pool topology.
* **Kubernetes / service-mesh API-server audit.** If the platform runs in a Kubernetes cluster with an authenticating ingress (mTLS, ingress-side OAuth proxy), enable audit logging at the ingress / service-mesh layer. This captures the authenticated HTTP call to the platform with operator identity attached, but does not capture which row of which table actually changed.
* **Application-level logs are NOT a substitute.** The RBAC, Owner, Term, Namespace, Datasource, and Collector service implementations do not emit `@Slf4j` log lines on mutations. Adding application-side log levels at runtime does not surface a trail for these subjects. Reserve admin-tier access tightly and rely on database-level or ingress-level audit instead.

**Operator-side hardening recommendations:**

* **Reserve admin-tier permissions narrowly.** The combination of "no audit on RBAC mutations" with the platform's seeded-Role re-creation behaviour means an attacker with brief admin access can delete the seeded `Administrator` role, recreate it with attacker-chosen policy bindings, and leave the deployment in a compromised state with no platform-side trace.
* **Snapshot RBAC state out-of-band.** Periodically export the contents of the `policy`, `role`, `owner_to_role`, and `permission` tables via a read-only database account; diff the snapshots over time. This gives you a manual change log when no audit stream exists.
* **Document the bifurcation in your runbook.** If your incident-response procedure refers to "the platform's audit log", make the runbook explicit about which subjects are covered by the platform's recorded stream and which require a compensating control to investigate.

A platform-side audit-scope expansion — schema migration + enum extension + service-tier emission + an operator-surface UI for the new streams — is tracked upstream. The doc-side caveat on this page remains load-bearing until that work lands.


# Architectural Decision Log

Architecture Decision Records for ODD Platform — the significant decisions the codebase embodies, reconstructed from the source with the code evidence to verify each one.

This log records the **architecture decisions ODD Platform embodies** — the deliberate, structural choices a contributor needs to understand *why* the platform is built the way it is. Each record is **reconstructed from the source code** and cites the `file:line` evidence behind it, so you can verify every claim against the repository.

These are **descriptive**, not prescriptive: they document decisions the code already makes, rather than decreeing new ones. Each record carries a **Status**, the **Context** that motivated the decision, the **Decision** itself, its **Consequences** (trade-offs and what it enables or precludes), and the **Evidence** in the codebase.

## Records

* [ADR-0001 — Contract-first HTTP layer (OpenAPI-generated controller interfaces)](/developer-guides/architecture-decision-log/adr-0001-openapi-generated-controller-interfaces)
* [ADR-0002 — Centralised path-matcher authorization (no @PreAuthorize)](/developer-guides/architecture-decision-log/adr-0002-centralised-path-matcher-authorization)
* [ADR-0004 — GenAI ships disabled by default and is a thin proxy](/developer-guides/architecture-decision-log/adr-0004-genai-disabled-by-default)
* [ADR-0007 — Uniform reactive controller pipeline (Mono\<ResponseEntity>, centralised error translation)](/developer-guides/architecture-decision-log/adr-0007-uniform-reactive-controller-pipeline)
* [ADR-0008 — OpenAPI tags scope the generated API interfaces](/developer-guides/architecture-decision-log/adr-0008-openapi-tag-per-resource-scoping)
* [ADR-0012 — Attachment storage backend is selected at boot](/developer-guides/architecture-decision-log/adr-0012-attachment-storage-backend-boot-selection)
* [ADR-0018 — Outbound-integration config is fail-fast at boot](/developer-guides/architecture-decision-log/adr-0018-fail-fast-outbound-config-at-boot)
* [ADR-0019 — Data Collaboration ships disabled by default](/developer-guides/architecture-decision-log/adr-0019-data-collaboration-disabled-by-default)
* [ADR-0020 — Outbound Slack delivery is decoupled via a Postgres queue](/developer-guides/architecture-decision-log/adr-0020-decoupled-outbound-slack-delivery)
* [ADR-0040 — Notifications ship disabled by default behind one condition](/developer-guides/architecture-decision-log/adr-0040-notifications-disabled-by-default)
* [ADR-0041 — Notification channels activate by the presence of their keys](/developer-guides/architecture-decision-log/adr-0041-notification-per-channel-presence-activation)
* [ADR-0042 — Notification fan-out is fail-soft per channel](/developer-guides/architecture-decision-log/adr-0042-notification-fail-soft-fan-out)
* [ADR-0043 — The notification WAL consumer is a leader-elected singleton](/developer-guides/architecture-decision-log/adr-0043-notification-wal-single-leader)
* [ADR-0044 — Postgres replication artefacts are lazy-created, never dropped](/developer-guides/architecture-decision-log/adr-0044-postgres-artefact-lazy-create-no-drop)
* [ADR-0021 — Activity streams use cursor pagination, not offset/limit](/developer-guides/architecture-decision-log/adr-0021-activity-stream-cursor-pagination)
* [ADR-0022 — Activity view-modes are a single enum parameter, not separate endpoints](/developer-guides/architecture-decision-log/adr-0022-activity-view-modes-single-parameter)
* [ADR-0028 — High-volume tables are range-partitioned ahead of need, at boot and nightly](/developer-guides/architecture-decision-log/adr-0028-range-partition-lifecycle)
* [ADR-0045 — Housekeeping is a separate subsystem from partition management](/developer-guides/architecture-decision-log/adr-0045-housekeeping-partition-separation)
* [ADR-0046 — Housekeeping ships enabled by default (opt-out)](/developer-guides/architecture-decision-log/adr-0046-housekeeping-opt-out-by-default)
* [ADR-0073 — ODDRN is the universal identity for every entity](/developer-guides/architecture-decision-log/adr-0073-oddrn-universal-identity)
* [ADR-0071 — PostgreSQL is the only required runtime dependency](/developer-guides/architecture-decision-log/adr-0071-postgres-only-runtime-dependency)
* [ADR-0070 — Ingestion is one wire contract shared by pull and push producers](/developer-guides/architecture-decision-log/adr-0070-pull-push-ingestion-contract)
* [ADR-0072 — The platform is a contract-first, reactive, two-language stack](/developer-guides/architecture-decision-log/adr-0072-contract-first-reactive-stack)
* [ADR-0003 — The catalog is read-collaborative — only mutations are permission-gated](/developer-guides/architecture-decision-log/adr-0003-read-collaborative-authorization)
* [ADR-0058 — Deletion is soft — DELETED is a status, not a row removal](/developer-guides/architecture-decision-log/adr-0058-soft-delete-deletion-model)
* [ADR-0074 — Authentication is a pluggable mode selected by auth.type, defaulting to DISABLED](/developer-guides/architecture-decision-log/adr-0074-pluggable-auth-modes)
* [ADR-0075 — Heavyweight features ship off by default; operational-hygiene jobs ship on](/developer-guides/architecture-decision-log/adr-0075-feature-gating-posture)
* [ADR-0076 — In-context concept help is an information icon in a hover tooltip](/developer-guides/architecture-decision-log/adr-0076-inline-info-tooltip-affordance)
* [ADR-0078 — Editing a consequential field uses a change-preview confirmation that reduces into the store](/developer-guides/architecture-decision-log/adr-0078-confirm-and-store-reduce-field-edits)
* [ADR-0079 — Ingestion authentication is one gate over /ingestion/\*\*, not per-route filters](/developer-guides/architecture-decision-log/adr-0079-ingestion-authentication-filter-coverage)

## How to read a record

* **Status** — `accepted` (the decision is live in the code), `superseded` (replaced by a later ADR), or `deprecated`.
* **Evidence** — every record points at the source that embodies the decision; if the code changes, the record should change with it.
* New decisions are added here as they are reconstructed and reviewed; see [How to contribute](/developer-guides/how-to-contribute) to propose or correct one.


# ADR-0001: Contract-first HTTP layer

ODD Platform's REST controllers are thin delegates over OpenAPI-generated interfaces — the HTTP contract lives in the spec, and routes change by regenerating it, not by editing controllers.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

ODD Platform exposes a large REST surface (hundreds of endpoints across data entities, ingestion, search, lineage, RBAC, collaboration, and more). A platform that size needs one answer to a structural question: **where does the HTTP contract live, and how is it kept consistent** between the server that implements it and the clients (the web UI, collectors, push adapters) that call it?

There are two broad options: hand-write Spring MVC/WebFlux mappings on each controller, or define the contract once in a specification and generate the wiring from it. Hand-written mappings drift — the spec and the code diverge silently, and each client re-derives the contract by hand. ODD chose the contract-first path.

## Decision

**Every REST controller in `odd-platform-api` is a thin delegate that `implements` an OpenAPI-generated `*Api` interface.** The HTTP method, path, and `produces`/`consumes` annotations live on the generated interface — compiled from `openapi.yaml` into the `org.opendatadiscovery.oddplatform.api.contract.api.*` package by the `odd-platform-api-contract` module's `openApiGenerate` build step — **never on the controller class itself**.

A controller class carries only `@RestController` and `@RequiredArgsConstructor`; each method carries only `@Override` and delegates straight to a service. Consequently, **adding or changing an endpoint is a specification-edit-and-regenerate flow**, not a controller edit.

## Consequences

* `openapi.yaml` (in `odd-platform-specification`) is the **single source of truth** for the HTTP surface. The UI's generated TypeScript client and the server's generated interfaces stay in sync by construction.
* **To add an endpoint:** edit `openapi.yaml`, regenerate, then implement the `@Override`. Putting a `@PostMapping` / `@GetMapping` directly on a controller class does **not** follow the convention — it would create a route that lives outside the contract and silently drift the spec from the code.
* The generated `*Api` interfaces are **build artifacts** and are not committed to the source tree; to read the live contract, read `openapi.yaml`.
* **Two deliberate exceptions, both external-webhook receivers.** `AlertManagerController` is fully hand-coded — it bridges an external Alertmanager webhook payload that is not part of ODD's generated contract. `EventApiController` is also fully hand-coded — it receives the Slack events webhook via a direct `@PostMapping("/api/slack/events")`, again with no generated interface. Both are a single `@RestController` with a direct `@PostMapping` because each bridges an external system's webhook payload that is not part of ODD's contract — the deliberate exceptions that prove the rule.

## Evidence

* `odd-platform-api/.../controller/AlertController.java:11-17` — `@RestController @RequiredArgsConstructor public class AlertController implements AlertApi`; the class declares no `@RequestMapping`, and its methods are `@Override` with no mapping annotations.
* The interface is imported from `org.opendatadiscovery.oddplatform.api.contract.api.AlertApi` — generated by the `odd-platform-api-contract` module's `openApiGenerate` task at build time and absent from the source tree.
* `odd-platform-specification/openapi.yaml` — the contract the `*Api` interfaces are generated from.
* The same shape holds across the module's controllers (data-entity, ingestion, search, and RBAC controllers all `implements` their generated `*Api` with no controller-level mapping annotations). The two deliberate exceptions are the external-webhook receivers, both fully hand-coded with no generated `*Api`: `AlertManagerController.java:15-21` (`@RestController`, no `implements`, `@PostMapping("ingestion/alert/alertmanager")` with a `// TODO: define OpenAPI spec` note) and `EventApiController.java:14-22` (`@RestController`, no `implements`, `@PostMapping("/api/slack/events")` — the Slack events webhook).

## See also

* [How to contribute](/developer-guides/how-to-contribute) — the contribution workflow, including the spec-and-regenerate loop.
* [Build and run ODD Platform](/developer-guides/build-and-run/build-and-run-odd-platform) — building the module that runs the OpenAPI generation.


# ADR-0002: Centralised path-matcher authorization

ODD Platform centralises endpoint authorization in one path-matcher rule table — controllers carry no @PreAuthorize, so the entire access matrix lives in one auditable place.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

ODD Platform exposes hundreds of endpoints, many of which mutate state — creating data sources, editing descriptions, regenerating collector tokens, managing policies and roles. Each needs an authorization decision: *which permission must the caller hold to perform this operation?*

Spring Security offers two broad places to answer that. One is **method-level** annotations — `@PreAuthorize` / `@Secured` on each controller method, keeping the rule next to the code it guards. The other is a **centralised** declaration — every rule registered in one place against the security filter chain, so the whole access matrix can be read at once. The trade-off is locality versus auditability: annotations sit next to the method but scatter the security model across the codebase; a central table concentrates the model at the cost of the controller no longer advertising its own auth posture.

ODD chose the centralised path.

## Decision

**Authorization is declared in one rule table — `SecurityConstants.SECURITY_RULES` — and enforced by a single `AuthorizationCustomizer`.** Each gated endpoint is one row mapping a request matcher to the permission it requires; controllers and the generated `*Api` interfaces carry **no** `@PreAuthorize`, `@Secured`, or programmatic permission checks.

Each row is a `SecurityRule(type, matcher, permission)`: an `AuthorizationManagerType` (whether the decision needs a resource context — `NO_CONTEXT` for global operations, or a resource type such as `DATA_ENTITY` / `TERM` for per-resource policies), a path-and-method matcher, and the `PolicyPermissionDto` the caller must hold.

`AuthorizationCustomizer` wires the chain in a fixed shape:

1. a whitelist of public paths is permitted (`actuator`, static assets, the ingestion surface, and the Slack-events webhook);
2. every `SECURITY_RULES` row is registered as a matcher guarded by that permission's authorization manager;
3. a final `pathMatchers("/**").authenticated()` catch-all closes the surface.

The catch-all is the deliberate floor: **any endpoint not named in `SECURITY_RULES` requires authentication but no specific permission** — it is available to any authenticated user.

## Consequences

* The platform has **one auditable security matrix**. To answer "what does this endpoint require?", read `SECURITY_RULES`; to change an endpoint's authorization, edit that one list.
* Because read (`GET`) endpoints are generally not listed, they fall through the catch-all to "any authenticated user." This is the platform's read-collaborative posture — a separate decision, recorded in its own record.
* The model is **path-string coupled**: a rule matches a literal path pattern. If a controller's URL changes but its `SECURITY_RULES` row is not updated to match, the rule silently stops applying. The single table makes the rules auditable, but nothing at compile time ties a rule to the route it guards — keeping the two in step is a manual discipline.
* A contributor adding a mutating endpoint must add its `SECURITY_RULES` row; reaching for a `@PreAuthorize` annotation instead would not follow the convention and would split the security model across two places.

## Evidence

* `odd-platform-api/.../auth/authorization/AuthorizationCustomizer.java:20-31` — the **sole** consumer of `SECURITY_RULES`: it permits `WHITELIST_PATHS`, loops the rules registering `.matchers(rule.matcher()).access(manager(rule.type(), extractors, permissionService, rule.permission()))`, then closes with `.pathMatchers("/**").authenticated()`.
* `odd-platform-api/.../auth/util/SecurityConstants.java:95-96` — `WHITELIST_PATHS = {"/actuator/**", "/favicon.ico", "/ingestion/**", "/img/**", "/api/slack/events"}`; `:98` — `public static final List<SecurityRule> SECURITY_RULES = List.of(...)`, the rule table (one `new SecurityRule(type, new PathPatternParserServerWebExchangeMatcher(path, METHOD), permission)` per gated endpoint).
* `odd-platform-api/.../auth/util/SecurityRule.java` — `record SecurityRule(AuthorizationManagerType type, ServerWebExchangeMatcher matcher, PolicyPermissionDto permission)`.
* No `@PreAuthorize`, `@Secured`, `@PostAuthorize`, or `@RolesAllowed` annotation exists anywhere in `odd-platform-api/src/main` — the authorization model is entirely table-driven, confirming the annotation-free decision by exhaustive absence.

## See also

* [ADR-0001 — Contract-first HTTP layer](/developer-guides/architecture-decision-log/adr-0001-openapi-generated-controller-interfaces) — controllers are thin delegates over generated interfaces, which is why they carry no authorization annotations either: both routing and authorization live outside the controller class.
* [Policies](/configuration-and-deployment/enable-security/authorization/policies) — how operators author the policies whose permissions these rules check.
* [Permissions](/configuration-and-deployment/enable-security/authorization/permissions) — the permission model the rule table references.


# ADR-0004: GenAI ships disabled by default

ODD Platform ships GenAI off by default — a runtime guard rejects requests until an operator sets genai.enabled and supplies the url and timeout, which have no working defaults.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

The GenAI feature lets a user ask a natural-language question that ODD Platform forwards to an operator-supplied LLM service. That service is external, operator-owned, and has no universal default endpoint — so the feature cannot work until an operator points it at their own service. The platform needs a shipped default that is safe and inert for the operators who never configure it, while still being available to those who do.

## Decision

**GenAI ships disabled by default, and the feature is a thin proxy whose connection has no working defaults.** The shipped `application.yml` sets `genai.enabled: false` verbatim. When disabled, the feature is enforced by a **runtime guard**, not by conditional bean wiring: the GenAI beans are always built, and `GenAIServiceImpl` checks the flag on every call — `if (!genAIProperties.isEnabled())` returns an error (`BadUserRequestException`, "Gen AI is disabled") before any outbound request.

To turn the feature on an operator must do two things, not one: set `genai.enabled: true`, **and** supply the connection details, because the configuration has **no usable defaults**. `GenAIProperties` defaults `url` to `null` and `requestTimeout` to `0` — so a deployment that flips only `enabled` builds a client with no endpoint and a zero-minute (immediate) timeout, and fails at the first request. The defaults are deliberately inert: the platform does not guess an endpoint or a timeout.

When enabled and configured, the platform is a **thin proxy**: `GenAIServiceImpl` forwards the user's question text to the operator's URL (`POST {url}/query_data` with the question as the request body) and returns the service's answer. The platform does not engineer the prompt, perform retrieval-augmentation, or cache the result — those concerns belong to the operator's external service.

## Consequences

* An operator who installs ODD and never touches GenAI runs with the feature inert and safe — every call is rejected by the runtime guard.
* 📌 **Enabling is a two-step the operator must complete.** Setting only `genai.enabled: true` is a misconfiguration the platform accepts at startup and surfaces only at the first request (no endpoint, immediate timeout). Operators must set `genai.url` and `genai.request_timeout` together with `enabled`. The [GenAI](/features/active-platform-features/genai) feature page carries this configuration guidance and the known-limitations note; this record explains *why* the defaults are inert.
* Because the feature is a thin proxy, the security and quality of answers (prompt-injection handling, data exposure to the LLM, output filtering) are properties of the **operator's** external service, not of ODD Platform. The platform's responsibility ends at forwarding the question and returning the response.
* The guard is at request time rather than bean-wiring time, so the GenAI beans exist even when disabled. This keeps the wiring simple (no conditional bean graph) at the cost that "disabled" is enforced by one runtime check rather than by the absence of the beans.

## Evidence

* `odd-platform-api/src/main/resources/application.yml:18` — `genai.enabled: false`, the explicit shipped default.
* `odd-platform-api/.../service/genai/GenAIServiceImpl.java:37-38` — the runtime guard: `if (!genAIProperties.isEnabled()) { return Mono.error(new BadUserRequestException("Gen AI is disabled")); }`, evaluated per request before any outbound call.
* `odd-platform-api/.../config/properties/GenAIProperties.java` — `url` (String) defaults to `null` and `requestTimeout` (int) defaults to `0`; there are no field initializers, so enabling without supplying these yields a non-functional client.
* `odd-platform-api/.../service/genai/GenAIServiceImpl.java:41-47` — the thin-proxy forward: `webClient.post().uri("/query_data").bodyValue(Map.of("question", request.getBody()))…`, returning the external service's body; no prompt construction or retrieval-augmentation in the platform.

## See also

* [GenAI](/features/active-platform-features/genai) — the feature page with the operator configuration steps and the enable-without-config known limitation.


# ADR-0007: Uniform reactive controller pipeline

ODD Platform's reactive controllers share one shape — methods return Mono\<ResponseEntity\<T>> via ResponseEntity::ok, and error translation is centralised in a single advice class.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

ODD Platform's API server is built on Spring WebFlux — every endpoint is reactive. A reactive controller method can be shaped many ways: it can return a bare body type, a `Mono<T>`, a `Flux<T>`, or a `Mono<ResponseEntity<T>>`; it can translate its own errors into HTTP status codes, or defer that to a shared handler. Left unconstrained, a large team ends up with a mix of all of these, and a reader cannot predict the shape of an endpoint they have not seen.

A platform this size benefits from one answer: a single response shape every controller follows, and a single place where exceptions become HTTP responses.

## Decision

**Every controller method returns `Mono<ResponseEntity<T>>`, and the success path maps the result with `.map(ResponseEntity::ok)`** (or `.thenReturn(ResponseEntity.noContent().build())` for void / delete results). Controllers do **not** translate their own exceptions — there is no per-controller `@ExceptionHandler`.

**Error translation is centralised in a single `@RestControllerAdvice` class, `ControllerAdvice`.** It maps the platform's exception hierarchy to status codes in one place: `BadUserRequestException` → 400, `NotFoundException` → 404, `UniqueConstraintException` and `CascadeDeleteException` → 400, validation (`WebExchangeBindException`) → 400, `GenAIException` → 500, framework `ResponseStatusException`s → their own embedded status (an unmatched route stays 404, invalid request input stays 400; added in 0.28.0 — before that the catch-all re-branded them 500), and a catch-all `Exception` → 500. Each is rendered into a consistent `ErrorResponse` body carrying a message, an error code, and `resolvable` / `retryable` flags.

A controller method is therefore a pure delegate: take the request, call the service, wrap the result with `ResponseEntity::ok`. Everything about *how an error becomes an HTTP response* lives in one class.

## Consequences

* Every endpoint has a **predictable shape**. A reader who has seen one controller method knows the form of all of them; a contributor writing a new one follows the same `flatMap(service::call).map(ResponseEntity::ok)` pipeline.
* **Error responses are consistent** across the whole surface — the same body schema, status mapping, and resolvable/retryable semantics, because they all come from `ControllerAdvice`. Adding a new exception type means adding one handler there, not editing controllers.
* A controller needing a **non-200 success** (for example a delete returning 204) opts in explicitly with `noContent()` / `thenReturn(...)`; the default is `ResponseEntity::ok`.
* The trade-off: a controller's source does not show how its exceptions map to HTTP — that knowledge lives in `ControllerAdvice`. The uniformity is bought by accepting that error mapping is read in one central place rather than next to each method.

## Evidence

* `odd-platform-api/.../controller/exception/ControllerAdvice.java` — the single `@RestControllerAdvice`: `@ExceptionHandler` methods for `BadUserRequestException` (400), `NotFoundException` (404), `UniqueConstraintException` (400), `CascadeDeleteException` (400), `WebExchangeBindException` (400), `GenAIException` (500), `ResponseStatusException` (pass-through — the framework's own 4xx/5xx kept, 4xx logged at WARN), and `Exception` (500), each rendered into `ErrorResponse`.
* `odd-platform-api/.../controller/DataEntityController.java` — the platform's largest controller: 40 methods returning `Mono<ResponseEntity<...>>` (34 via `.map(ResponseEntity::ok)`, 3 via `.thenReturn(ResponseEntity...)`), with no controller-level mapping annotations and no `@ExceptionHandler`.
* `odd-platform-api/.../controller/SearchController.java` — 7 methods, all `Mono<ResponseEntity<...>>` ending in `.map(ResponseEntity::ok)`; no controller-level error handling. `TermController.java` shows the same shape across 23 methods.
* Across the module, every controller returning `Mono<ResponseEntity<...>>` uses the standard `ResponseEntity` builders (`ok` / `noContent` / `status`) — there is no controller carrying its own exception translation.

## See also

* [ADR-0001 — Contract-first HTTP layer](/developer-guides/architecture-decision-log/adr-0001-openapi-generated-controller-interfaces) — the controllers implement generated `*Api` interfaces; the uniform `Mono<ResponseEntity<T>>` return type is the shape those generated signatures take.
* [ADR-0002 — Centralised path-matcher authorization](/developer-guides/architecture-decision-log/adr-0002-centralised-path-matcher-authorization) — the companion "one place" decision for authorization; together they keep controllers as thin delegates.


# ADR-0008: OpenAPI tags scope the generated API interfaces

Every ODD Platform OpenAPI operation carries exactly one tag, and the generator emits one Java interface per tag — so a tag is the unit that shapes the generated \*Api interfaces.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

ADR-0001 establishes that controllers implement OpenAPI-generated `*Api` interfaces rather than carrying their own HTTP mappings. That raises a follow-on question the spec must answer: **what determines how those generated interfaces are carved up?** With the `spring` generator, the answer is the OpenAPI **tag** — but only if the spec uses tags consistently. If operations carried several tags, or none, the generated interface boundaries would be ambiguous or arbitrary.

ODD's `openapi.yaml` adopts a deliberate tagging convention so the generated interfaces are predictable.

## Decision

**Every operation carries exactly one tag, and the generator is configured to emit one interface per tag (`useTags: true`).** A tag is therefore the unit that shapes the generated API surface: tag `alert` produces `AlertApi`, tag `search` produces `SearchApi`, tag `dataEntity` produces `DataEntityApi`, and so on. Across all 194 operations in the spec there are no multi-tagged and no untagged operations, so every operation lands in exactly one generated interface — there is no ambiguity about which interface an endpoint belongs to.

**Tags are resource-oriented, and for most resources the tag also lines up with a single URL prefix.** Of the 33 tags, 30 group operations that all sit under one `/api/<resource>` path prefix (for example every `alert` operation is under `/api/alerts`, every `search` operation under `/api/search`). For those resources the tag, the URL prefix, and the generated interface coincide cleanly.

**Three tags deliberately group a resource whose operations span more than one path root**, so the tag is broader than a single URL prefix:

* `dataEntity` (the largest, \~37 operations) spans `/api/dataentities/**` and `/api/dataentitygroups/**` — the entity and its group sub-resource.
* `ownerAssociationRequest` spans `/api/owner_association_request/**` and the owner-mapping operations under `/api/owners/**`.
* `dataCollaboration` spans `/api/datacollaboration/**` and the message-resolution operation under `/api/messages/**`.

For these, the tag is the resource boundary and the generated interface aggregates operations across the related paths. The invariant the spec actually holds is **one tag per operation → one interface per tag**; the "one tag = one URL prefix" alignment is the common case (30 of 33), not a universal rule.

## Consequences

* A contributor editing `openapi.yaml` controls which generated interface an endpoint belongs to by setting its tag; the controller then implements that interface (per ADR-0001). Tag choice is an interface-design decision, not cosmetic.
* The generated `*Api` interfaces are resource-shaped and stable, which keeps controllers small and their grouping predictable.
* For the three multi-root tags, an endpoint's URL prefix does not by itself tell you its interface — the tag does. A reader mapping a path to its generated interface must read the operation's tag, not infer it from the URL.
* Because grouping is driven entirely by the tag, a missing or wrong tag on a new operation would misplace it in the generated surface; the single-tag-per-operation discipline is what keeps the mapping unambiguous.

## Evidence

* `odd-platform-api-contract/build.gradle:10,24` — `generatorName = "spring"` with `configOptions` including `useTags: "true"`, which makes the generator emit one interface per tag; `:16` sets `apiPackage = "org.opendatadiscovery.oddplatform.api.contract.api"` and `:44` wires `compileJava.dependsOn tasks.openApiGenerate`.
* `odd-platform-specification/openapi.yaml` — across all 194 operations, each declares exactly one `tags:` entry (no operation is multi-tagged or untagged); 33 distinct tags are used.
* Clean single-prefix examples: every `alert` operation is under `/api/alerts` (e.g. `getAllAlerts` on `GET /api/alerts`); every `search` operation under `/api/search` (e.g. `search` on `POST /api/search`).
* Multi-root tags: `dataEntity` operations appear under both `/api/dataentities/**` and `/api/dataentitygroups/**`; `ownerAssociationRequest` under `/api/owner_association_request/**` and `/api/owners/**`; `dataCollaboration` under `/api/datacollaboration/**` and `/api/messages/**`.

## See also

* [ADR-0001 — Contract-first HTTP layer](/developer-guides/architecture-decision-log/adr-0001-openapi-generated-controller-interfaces) — controllers implement these generated `*Api` interfaces; this record explains how the spec decides what those interfaces are.


# ADR-0012: Attachment storage backend is selected at boot

ODD Platform picks its attachment storage backend at boot from attachment.storage — LOCAL is the implicit default, REMOTE is S3/MinIO, and switching backends needs a restart.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

Data-entity attachments (uploaded files and remote-URL links) need somewhere to live. ODD Platform supports two backends: a **LOCAL** filesystem path inside the platform container, and a **REMOTE** S3-compatible object store (MinIO or AWS S3). The platform needs a way to choose between them, and a default for operators who set nothing.

The choice is *which moment* the backend is fixed: as a runtime switch the platform could flip per request, or as a boot-time decision baked into the bean graph. ODD chose boot-time wiring — the backend is decided once, when the application context starts.

## Decision

**The attachment storage backend is selected at boot via `@ConditionalOnProperty` on the `attachment.storage` property.** Each backend's beans are conditionally created: the LOCAL implementations carry `@ConditionalOnProperty(value = "attachment.storage", havingValue = "LOCAL", matchIfMissing = true)`, and the REMOTE (MinIO) implementations carry `havingValue = "REMOTE"`. Exactly one backend's beans are instantiated for the lifetime of the process.

**`LOCAL` is the implicit default.** The `matchIfMissing = true` on the LOCAL beans means a deployment that never sets `attachment.storage` runs LOCAL. The shipped `application.yml` also states `storage: LOCAL` explicitly, so the default is visible to an operator reading the config, not only implied by the code.

Because the selection is a `@ConditionalOnProperty` condition evaluated at context startup, **switching backends requires a Platform restart** — there is no runtime toggle.

## Consequences

* An operator chooses the backend with one property and a restart; the rest of the attachment code is backend-agnostic (both implement the same `FileUploadService` / `FilePathConstructor` interfaces).
* 📌 **The default backend is durability-limited, and the operator docs carry the caveat.** Under `LOCAL`, files are written to a container-local path (`attachment.local.path`, default `/tmp/odd/attachments`). On a containerised deployment that path is wiped on any container or pod restart, so a default deployment loses uploaded attachments on restart. This is a consequence operators must plan for — the [Attachments](/features/data-discovery/attachments) page and the [Attachment Storage Configuration](/configuration-and-deployment/odd-platform#attachment-storage-configuration) operator reference carry the full guidance (use `REMOTE` for any deployment where users actually upload files, plus the in-flight chunk-staging and AWS S3 region caveats). This ADR records *why* the boot-time `LOCAL`-default selection exists; those pages tell an operator *what to do about it*.
* Adding a third backend means adding a new `@ConditionalOnProperty(havingValue = "…")` implementation set, not a runtime branch — the selection mechanism scales by adding conditioned bean sets.

## Evidence

* `odd-platform-api/.../service/attachment/local/LocalFileUploadServiceImpl.java:26` and `.../local/LocalFilePathConstructor.java:13` — `@ConditionalOnProperty(value = "attachment.storage", havingValue = "LOCAL", matchIfMissing = true)`; LOCAL is the implicit default.
* `odd-platform-api/.../service/attachment/remote/RemoteFileUploadServiceImpl.java:36` and `.../config/MinioConfig.java:10` — `@ConditionalOnProperty(value = "attachment.storage", havingValue = "REMOTE")`; the MinIO/S3 backend.
* `odd-platform-api/src/main/resources/application.yml:216` — `storage: LOCAL` (the explicit shipped default); `:219` — `local.path: /tmp/odd/attachments` (the container-local default path).
* `odd-platform-api/.../service/attachment/local/LocalFilePathConstructor.java:15-16` — the LOCAL path is bound from `attachment.local.path`, confirming LOCAL writes to a configurable container path.

## See also

* [Attachments](/features/data-discovery/attachments) — the user-facing feature and the storage-mode caveats.
* [Attachment Storage Configuration](/configuration-and-deployment/odd-platform#attachment-storage-configuration) — the operator reference for `LOCAL` vs `REMOTE`, persistence, and the AWS S3 region constraint.


# ADR-0018: Outbound-integration config is fail-fast at boot

ODD Platform validates an outbound integration's config when its bean is built — a missing value fails startup, not the first message; an unconfigured channel is simply off.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

ODD Platform integrates with several outbound systems — Slack (data collaboration and notifications), email/SMTP, generic webhooks, LDAP. Each needs configuration the operator supplies: a token, a URL, a host. There are two moments such configuration can be validated: **at boot**, when the integration's bean is constructed, or **lazily**, when the first request tries to use it.

Lazy validation is the failure mode behind real incidents — a deployment looks healthy, then the first alert that should reach Slack silently never arrives because the token was blank. The operator discovers the misconfiguration in production, from its absence. ODD chose the opposite: surface a misconfigured integration **at startup**, as a deployment error, not as silent runtime degradation.

## Decision

**When an outbound integration&#x20;*****is*****&#x20;configured, the required values are checked as its bean is built, and an empty or invalid value throws — failing application startup.** A blank Slack OAuth token, an empty webhook URL, a blank email sender/host/protocol all abort boot rather than producing a half-built client that fails later.

The check lives in the bean factory: the integration's `@Bean` method validates its inputs and throws `IllegalArgumentException` on an empty value before constructing the client. The same fail-at-boot discipline extends to the `@ConfigurationProperties` classes, whose `@PostConstruct` validators reject structurally invalid configuration (for example, a negative retry count or a missing LDAP URL) as the context starts.

**The deliberate boundary — absence is not an error.** This is *not* "every integration must be configured." Each notification channel's sender bean is gated by `@ConditionalOnProperty` on its own key (`notifications.receivers.slack.url`, `…webhook.url`, `…email.sender`). If an operator never sets a channel's key, the bean is never created — the channel is simply off, silently and by design. Fail-fast applies to an integration the operator *opted into but configured incompletely*; it does not force an operator to configure channels they don't want. The empty-value check inside each bean only runs once that bean is being built, i.e. once the key is present.

## Consequences

* A misconfigured-but-enabled integration is a **startup failure with a named cause** ("Slack OAuth token is empty"), not a silent runtime no-op. The operator learns at deploy time.
* An operator enables exactly the channels they configure: setting a channel's key turns it on (and then its values must be valid); omitting the key leaves it off. There is no "enable notifications, then separately fill in each channel" two-step.
* The trade-off of the absence-is-off rule: a **typo in a channel's key name** reads as "channel intentionally off," not as an error — the bean condition isn't met, so nothing is built and nothing complains. Fail-fast protects the *values* of a channel you turned on; it cannot protect the *spelling* of the key that turns it on.
* The exception type signals where the fault is: an empty value in a bean factory throws `IllegalArgumentException` (a bad argument to bean construction); a structurally invalid `@ConfigurationProperties` value throws from a `@PostConstruct` validator (the deployment's configured state is wrong).

## Evidence

* `odd-platform-api/.../datacollaboration/config/DataCollaborationConfiguration.java:23-24` — the `slackAPIClient()` `@Bean` factory: `if (StringUtils.isEmpty(slackOauthToken)) { throw new IllegalArgumentException("Slack OAuth token is empty"); }` before the Slack client is built.
* `odd-platform-api/.../notification/config/NotificationConfiguration.java` — the notification channel factories validate at construction: `mailSender` throws on blank sender / host / protocol (`:40`, `:44`, `:48`); `slackNotificationSender` throws on empty URL (`:82`); `webhookNotificationSender` on empty URL (`:95`); `emailNotificationSender` on blank recipient list (`:111`); `alertNotificationMessageTranslator` on a negative downstream depth (`:128`) — all `IllegalArgumentException`.
* `odd-platform-api/.../notification/config/NotificationConfiguration.java:37,75,89,102` — the **absence-is-off** boundary: each sender bean carries `@ConditionalOnProperty(name = "notifications.receivers.{slack.url|webhook.url|email.sender}")`, so an unset key means the bean is never created and the channel is silently off; the empty-value check only fires once the key is present.
* `odd-platform-api/.../auth/ODDLDAPProperties.java` and `.../datacollaboration/config/DataCollaborationProperties.java` — `@ConfigurationProperties` classes whose `@PostConstruct` validators throw `IllegalStateException` on structurally invalid configuration (a missing LDAP server URL; a negative message-retry count), applying the same fail-at-boot discipline from the properties-binding side.

## See also

* [Data Collaboration](/features/active-platform-features/data-collaboration) — the Slack integration whose OAuth token is validated at boot.
* [Notifications](/features/active-platform-features/notifications) — the per-channel configuration whose presence enables a channel and whose values are checked when it is built.
* [LDAP](/configuration-and-deployment/enable-security/authentication/ldap) — an authentication integration whose properties are validated as the context starts.


# ADR-0019: Data Collaboration ships disabled by default

ODD Platform ships Data Collaboration off by default — a conditional gates the whole controller on datacollaboration.enabled, so every route returns 404 until an operator opts in.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

Data Collaboration (the in-platform Discussions surface and the Slack message bridge) is a heavyweight, outbound-integration feature: it needs a Slack OAuth token, a background sender, and Postgres coordination artefacts. Most deployments do not use it. The platform needs a default that keeps the feature inert for the operators who never configure it, while making it a single, explicit opt-in for those who do.

## Decision

**Data Collaboration ships with `enabled: false` (under `datacollaboration:`) as the verbatim default, and the whole feature is gated by a `@ConditionalOnDataCollaboration` conditional.** The feature's controller (and its background components) carry that annotation; when the property is not `true`, the conditional does not match, the controller bean is never registered, and **every Data Collaboration route returns 404 Not Found** — there is no degraded mode, no "feature disabled" payload.

The gating is centralised in one `Condition` class that reads the property from Spring's `Environment` (defaulting to `false`), consulted through a single reusable `@ConditionalOnDataCollaboration` meta-annotation. A developer changing the gating semantics touches one place, not each component.

This is one member of the platform's **ship-disabled-by-default family** for heavyweight / outbound-integration features, alongside GenAI (ADR-0004) and Notifications (ADR-0040). Once an operator turns the feature on, the required integration config is validated fail-fast at boot (ADR-0018) — so the deployment story is: feature off → operator opts in → operator must supply the Slack OAuth token or the platform refuses to start.

## Consequences

* A default deployment runs with Data Collaboration entirely absent — no beans, no background workers, no Postgres artefacts created.
* Because gating removes the controller bean rather than guarding each method, a disabled feature responds **404** (route does not exist), not 403 or a disabled-state body. A client cannot distinguish "feature disabled" from "wrong URL" without out-of-band knowledge.
* Enabling is a single property (`datacollaboration.enabled: true`) plus the integration config that ADR-0018 then requires at boot; there is no per-route toggle.
* The single-`Condition` + meta-annotation design keeps the on/off semantics in one file, avoiding the drift that scattered per-bean property checks would produce.

## Evidence

* `odd-platform-api/src/main/resources/application.yml:205` — `enabled: false` (under the `datacollaboration:` key), the verbatim shipped default.
* `odd-platform-api/.../datacollaboration/controller/DataCollaborationController.java:21-22` — `@ConditionalOnDataCollaboration` on the `@RestController` class: no bean when disabled, so its routes 404.
* `odd-platform-api/.../datacollaboration/config/DataCollaborationFeatureCondition.java:18-22` — the single `Condition` reads `FeatureResolver.DATA_COLLABORATION_ENABLED_PROPERTY` from the `Environment` with default `false`.
* `odd-platform-api/.../datacollaboration/config/ConditionalOnDataCollaboration.java` — the reusable `@Conditional(DataCollaborationFeatureCondition.class)` meta-annotation applied across the feature's components.

## See also

* [Data Collaboration](/features/active-platform-features/data-collaboration) — the feature and its configuration.
* [ADR-0020 — Decoupled outbound Slack delivery](/developer-guides/architecture-decision-log/adr-0020-decoupled-outbound-slack-delivery) — how messages are delivered once the feature is enabled.
* [ADR-0004 — GenAI ships disabled by default](/developer-guides/architecture-decision-log/adr-0004-genai-disabled-by-default) and [ADR-0040 — Notifications ship disabled by default](/developer-guides/architecture-decision-log/adr-0040-notifications-disabled-by-default) — the same ship-off-by-default posture for other features.


# ADR-0020: Outbound Slack delivery is decoupled via a Postgres queue

ODD Platform accepts a Slack message with 202, persists it, and delivers it from a background worker that holds a Postgres advisory lock — so delivery needs no message broker, only Postgres.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

When a user posts a Data Collaboration message to Slack, the platform calls an external API (`chat.postMessage`) that can be slow, rate-limited, or temporarily down. Doing that call inline on the request thread would couple the user's HTTP latency to Slack's, and would lose the message if the request failed mid-call. The platform also runs in multi-replica deployments, so naive background delivery would risk two replicas sending the same message twice.

The platform needed durable, decoupled, exactly-once-per-message delivery — ideally without adding a message broker to its runtime dependencies (ODD's posture is Postgres-as-only-runtime-dependency).

## Decision

**The post-message request persists the message and returns `202 Accepted`; a background worker delivers it later under a Postgres advisory lock.** The controller does not call Slack inline — it creates the message row and responds `202` (`ResponseEntity.status(HttpStatus.ACCEPTED)`), signalling "accepted, delivery is asynchronous."

Delivery is handled by `DataCollaborationMessageSenderJob`, which **acquires a Postgres advisory lock** (`leaderElectionManager.acquire(senderMessageAdvisoryLockId, true)`, the blocking form) before draining the queue. The advisory lock is the cross-replica coordination primitive: only the lock-holding replica sends, so a message is delivered once across the whole deployment. The lock id is an operator-tunable property (`datacollaboration.sender-message-advisory-lock-id`, default `120`), drawn from a disjoint per-subsystem namespace so the platform's several single-leader workers don't collide.

The worker drains candidates one at a time, calls the provider client, and on failure **retries up to `datacollaboration.sending-messages-retry-count`** (default `3`, incrementing a per-message try-count) before marking the message failed; on success it records the provider message timestamp. Choosing a Postgres advisory lock over Redis/Kafka/SQS is the load-bearing decision — it keeps delivery coordination inside the database the platform already requires.

## Consequences

* The user's request latency is decoupled from Slack's — the post returns as soon as the message is durably queued, and a transient Slack outage delays delivery rather than failing the request.
* Delivery is **once-per-message cluster-wide** without a broker: the advisory lock serialises sending to a single replica. The same single-leader-via-Postgres-advisory-lock mechanism coordinates the notifications WAL consumer (ADR-0043); the two use distinct lock ids from the shared namespace.
* Because sending is single-leader, adding replicas does **not** increase Slack delivery throughput — outbound delivery is intentionally serialised, not horizontally scaled.
* A caller that received `202` cannot observe final delivery success from that response; terminal state lives on the message row (delivered, or failed after the retry budget). Surfacing post-`202` failure to the user is a known limitation of the decoupled model, not a property of this decision.

## Evidence

* `odd-platform-api/.../datacollaboration/controller/DataCollaborationController.java:34-39` — `postMessageInSlack` creates the message and returns `ResponseEntity.status(HttpStatus.ACCEPTED).body(message)`; no inline Slack call.
* `odd-platform-api/.../datacollaboration/job/DataCollaborationMessageSenderJob.java:93-95` — `acquireLeaderElectionConnection()` calls `leaderElectionManager.acquire(dataCollaborationProperties.getSenderMessageAdvisoryLockId(), true)` (blocking) before the drain loop.
* `odd-platform-api/.../datacollaboration/job/DataCollaborationMessageSenderJob.java:36-67` — the drain loop: poll `getSendingCandidate()`, `postMessage(...)`, and on exception retry (`incrementMessageTryCount`) or `markMessageAsFailed`; `:89-91` — `shouldRetry` bounds retries by `getSendingMessagesRetryCount()`.
* `odd-platform-api/src/main/resources/application.yml:202,204` — `sender-message-advisory-lock-id: 120` and `sending-messages-retry-count: 3` as operator-tunable properties.

## See also

* [Data Collaboration](/features/active-platform-features/data-collaboration) — the feature and its message lifecycle.
* [ADR-0019 — Data Collaboration ships disabled by default](/developer-guides/architecture-decision-log/adr-0019-data-collaboration-disabled-by-default) — the feature must be enabled before this delivery path runs.
* [ADR-0043 — Notification WAL consumer is a leader-elected singleton](/developer-guides/architecture-decision-log/adr-0043-notification-wal-single-leader) — the same Postgres-advisory-lock single-leader mechanism, applied to notification delivery.


# ADR-0040: Notifications ship disabled by default behind one condition

ODD Platform ships notifications off by default — one Condition reads notifications.enabled and a single meta-annotation gates every component, so the whole subsystem turns on from one switch.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

The Notifications subsystem is heavyweight: it consumes the Postgres write-ahead log via a replication slot, runs a background subscriber, and fans alerts out to external channels. It spans several Spring components (a bean-wiring `@Configuration`, a startup subscriber, a message processor). Most deployments don't need it. The platform needs it off by default, turned on by a single switch, with no risk that one component activates while another stays dormant.

## Decision

**The Notifications subsystem ships `notifications.enabled: false` and is gated by a single `Condition` class consulted through one `@ConditionalOnNotifications` meta-annotation applied to every Notifications component.** The condition (`NotificationsFeatureCondition`) reads `notifications.enabled` from Spring's `Environment`, defaulting to `false`. The reusable `@ConditionalOnNotifications` annotation wraps `@Conditional(NotificationsFeatureCondition.class)` and is placed on all three top-level components — the `@Configuration` that wires the senders, the startup subscriber, and the alert message processor. When the property is not `true`, none of the three register and the WAL subscriber never starts.

The design is **single-source-of-truth gating**: one property, one condition class, one meta-annotation. A developer changing the gating semantics (say, sourcing the flag from a feature-flag service) edits one file rather than each component's annotation. This is the meta-annotation variant of the platform's ship-disabled-by-default family — the same posture as GenAI (ADR-0004, inline) and Data Collaboration (ADR-0019, which uses the identical meta-annotation idiom).

## Consequences

* A default deployment runs with notifications entirely absent — no subscriber, no WAL replication slot created, no senders wired.
* The subsystem turns on as a unit: setting `notifications.enabled: true` activates all three components together, so there is no partially-enabled state where (for example) the processor exists but the subscriber doesn't.
* Enabling the subsystem is necessary but not sufficient to receive notifications — individual channels then activate by the presence of their own keys (ADR-0041). The two together form a two-stage opt-in.
* Centralising the flag in one condition class avoids the drift that scattered per-component property checks would cause; the trade-off is one extra indirection (a meta-annotation) over a bare `@ConditionalOnProperty`, chosen deliberately because the flag has three consumers.

## Evidence

* `odd-platform-api/src/main/resources/application.yml:173` — `enabled: false` under the `notifications:` key (line 172), the verbatim shipped default.
* `odd-platform-api/.../notification/config/NotificationsFeatureCondition.java:11-13` — reads `FeatureResolver.NOTIFICATIONS_ENABLED_PROPERTY` from the `Environment` with default `false`.
* `odd-platform-api/.../notification/config/ConditionalOnNotifications.java:9-12` — the meta-annotation: `@Conditional(NotificationsFeatureCondition.class)`.
* The annotation is applied to all three components: `NotificationConfiguration.java:27` (`@Configuration`), `NotificationSubscriberStarter.java:17` (startup subscriber), `AlertNotificationMessageProcessor.java:15` (alert processor).

## See also

* [ADR-0041 — Notification channels activate by the presence of their keys](/developer-guides/architecture-decision-log/adr-0041-notification-per-channel-presence-activation) — the second stage of the opt-in, once the subsystem is enabled.
* [ADR-0004 — GenAI ships disabled by default](/developer-guides/architecture-decision-log/adr-0004-genai-disabled-by-default) and [ADR-0019 — Data Collaboration ships disabled by default](/developer-guides/architecture-decision-log/adr-0019-data-collaboration-disabled-by-default) — the same ship-off-by-default posture.


# ADR-0041: Notification channels activate by the presence of their keys

Each notification channel — Slack, webhook, email — turns on by the presence of its own config key; an unset key means no bean and no delivery, with no separate per-channel enable flag.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

Once the Notifications subsystem is enabled (ADR-0040), an operator still has to choose *where* alerts go: Slack, a generic webhook, email, or some combination. The platform needs a way to activate exactly the channels an operator wants — without a separate enable flag per channel that could drift out of step with whether the channel is actually configured.

## Decision

**Each channel activates by the presence of its own configuration key.** The three sender beans each carry `@ConditionalOnProperty` on the key that channel needs — `notifications.receivers.slack.url`, `notifications.receivers.webhook.url`, `notifications.receivers.email.sender`. Setting the key creates the bean (the channel is on); leaving it unset means no bean is created and that channel is silently absent. There is no separate `slack.enabled` / `email.enabled` flag — **the configuration key is the toggle.**

This composes with ADR-0040 into a **two-stage opt-in**: the subsystem must be enabled (`notifications.enabled: true`), and then each channel is activated by populating its key. An operator who enables notifications but sets no channel keys gets a running subsystem that delivers nowhere.

The presence test is for the key being set; a key set to an *empty* value is caught separately by the fail-fast empty-value check inside the sender's bean factory (ADR-0018), which aborts startup rather than building a broken sender.

## Consequences

* Operators configure only the channels they want, by populating only those keys — the common case is "set one key, get one channel."
* Adding a new channel is an add-a-bean-method change carrying its own `@ConditionalOnProperty`, not a change to a central channel registry.
* The trade-off is implicitness: an operator who *omits* a channel's key gets no warning (it is indistinguishable from deliberately not wanting that channel). A *malformed* (empty) key is the case the fail-fast check catches; an *absent* key is by-design silent.
* Channel activation is independent — one configured channel works regardless of whether the others are set.

## Evidence

* `odd-platform-api/.../notification/config/NotificationConfiguration.java:37` — `@ConditionalOnProperty(name = "notifications.receivers.email.sender")` on the `mailSender` bean; `:102` — the same key on the `emailNotificationSender` bean (the email channel needs two beans, both presence-gated on one key).
* `odd-platform-api/.../notification/config/NotificationConfiguration.java:75` — `@ConditionalOnProperty(name = "notifications.receivers.slack.url")` on `slackNotificationSender`; `:89` — `@ConditionalOnProperty(name = "notifications.receivers.webhook.url")` on `webhookNotificationSender`.
* `odd-platform-api/src/main/resources/application.yml:180-186` — the `notifications.receivers.{slack.url|webhook.url|email.sender}` keys ship empty, so no channel is active by default.

## See also

* [ADR-0040 — Notifications ship disabled by default behind one condition](/developer-guides/architecture-decision-log/adr-0040-notifications-disabled-by-default) — the subsystem gate; this record is the per-channel second stage.
* [ADR-0018 — Outbound-integration config is fail-fast at boot](/developer-guides/architecture-decision-log/adr-0018-fail-fast-outbound-config-at-boot) — the empty-value check that turns a malformed channel key into a startup failure.


# ADR-0042: Notification fan-out is fail-soft per channel

When ODD Platform fans an alert out to its notification channels, a failure in one channel is logged and the rest still receive it — one broken channel never blocks the others.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

A single alert can fan out to several notification channels (Slack, webhook, email). Any one of them can fail transiently — a webhook endpoint is down, an SMTP server times out. The platform has to decide what happens to the *other* channels, and to the *next* alert, when one send fails: stop the whole fan-out, or carry on.

## Decision

**Fan-out is fail-soft per channel: a send failure is caught, logged at ERROR naming the channel, and the loop continues to the next channel.** `AlertNotificationMessageProcessor.process` iterates the configured senders and calls each inside a `try/catch (NotificationSenderException)`; on exception it logs the failing channel's `receiverId()` and proceeds to the next sender. The exception does not propagate, so the next sender still runs and the next WAL message is still processed.

The decision encodes "one bad channel does not block the others" as the operational stance. The alternative — let the first failure abort the fan-out — would couple every channel's delivery to the least reliable one, and would stall WAL progress behind a single bad endpoint.

## Consequences

* A misconfigured or down channel does not stop the others: Slack still gets the alert if the webhook is failing, and the WAL keeps advancing rather than wedging behind a failed send.
* 📌 **Partial failure is operator-visible only in logs.** Because the failure is caught and logged rather than surfaced, the platform keeps no delivery-status record, counter, or alert for a channel that is silently failing — an operator learns of a dead channel only by inspecting ERROR logs. Closing that blind spot (a delivery audit trail or a failure metric) would be an additive change that does not alter the fail-soft stance.
* The stance is consistent with the platform's broader "best-effort across a list of independent operations" convention (the same continue-on-failure shape used by the partition-management orchestrator).

## Evidence

* `odd-platform-api/.../notification/processor/AlertNotificationMessageProcessor.java:26-35` — the fan-out loop: `for (… notificationSender : notificationSenders) { try { notificationSender.send(notificationMessage); } catch (NotificationSenderException e) { log.error(…"Error occurred while sending notification via %s"…, notificationSender.receiverId()…); } }` — caught, logged, loop continues; no rethrow.
* `odd-platform-api/.../notification/processor/AlertNotificationMessageProcessor.java:19` — `private final List<NotificationSender<AlertNotificationMessage>> notificationSenders;` — the fan-out target is the list of activated channel senders (per ADR-0041).

## See also

* [ADR-0041 — Notification channels activate by the presence of their keys](/developer-guides/architecture-decision-log/adr-0041-notification-per-channel-presence-activation) — what populates the list of senders this fan-out iterates.
* [ADR-0043 — Notification WAL consumer is a leader-elected singleton](/developer-guides/architecture-decision-log/adr-0043-notification-wal-single-leader) — the WAL loop whose progress fail-soft fan-out protects.


# ADR-0043: The notification WAL consumer is a leader-elected singleton

ODD Platform consumes the Postgres WAL for notifications from one thread on one replica, elected by a Postgres advisory lock — so a multi-replica deployment emits each alert once, with no broker.

## Status

**Accepted.** Reconstructed from the codebase on 2026-05-30; the decision is live in the source today.

## Context

Notifications are driven by the Postgres write-ahead log: when an alert row is written, a logical-replication consumer reads it and fans it out. In a multi-replica deployment, if every replica consumed the WAL, every alert would be delivered N times. The platform needs exactly-once-cluster-wide consumption — and, in keeping with its Postgres-as-only-runtime-dependency posture, without introducing an external coordinator (ZooKeeper/Consul/etcd) for leader election.

## Decision

**The WAL consumer runs on a single thread that holds a Postgres advisory lock; only the lock-holding replica consumes.** At application startup (`ApplicationReadyEvent`), `NotificationSubscriberStarter` submits the subscriber to a single-thread executor whose thread is named `notification-subscriber-thread`. The subscriber's first action is `leaderElectionManager.acquire(walProperties.getAdvisoryLockId(), true)` — the **blocking** form, so a replica that is not the leader blocks here and never reads the WAL. Only the replica that holds the advisory lock opens the logical-replication stream and processes messages.

The advisory lock id is operator-tunable (`notifications.wal.advisory-lock-id`, default `100`), drawn from the same disjoint per-subsystem namespace as the Data Collaboration sender (ADR-0020). On the leader, consumption is single-threaded by construction (one executor thread), so WAL messages are processed in order. If the leader dies, it drops the lock and a waiting replica acquires it and takes over.

This is the **same single-leader-via-Postgres-advisory-lock mechanism** as ADR-0020's outbound Slack sender; the two are instances of one cluster-coordination convention, each keyed by a distinct lock id.

## Consequences

* Each alert is consumed once cluster-wide: non-leader replicas block on the lock and never double-deliver, with no external coordinator — Postgres is the only dependency.
* Consumption does not scale horizontally — adding replicas adds standby leaders, not parallel consumers; throughput is bounded by the single consumer thread. This is intentional (ordering + exactly-once over throughput).
* Failover is automatic via advisory-lock release semantics: killing the leader frees the lock and a standby takes over on its next acquire attempt.
* Because the single thread both reads the WAL and drives fan-out, a sender that blocks the thread would stall consumption — which is exactly why fan-out is fail-soft (ADR-0042), so one slow/broken channel cannot wedge the WAL.

## Evidence

* `odd-platform-api/.../notification/NotificationSubscriberStarter.java:21-23` — `Executors.newSingleThreadExecutor(r -> new Thread(r, "notification-subscriber-thread"))`; `:30-35` — `@EventListener(ApplicationReadyEvent.class)` submits the subscriber at startup.
* `odd-platform-api/.../notification/NotificationSubscriber.java:47` — `leaderElectionManager.acquire(walProperties.getAdvisoryLockId(), true)` (blocking acquire) wraps the replication-stream loop; non-leaders block here.
* `odd-platform-api/.../leaderelection/PostgreSQLLeaderElectionManagerImpl.java:21-23` — `acquire(...)` prepares and `execute()`s `SELECT pg_advisory_lock(<id>)` — the **blocking** Postgres lock function (not the `try_` variant), so the call returns only once the lock is held; the connection is then returned and kept open to hold the lock for the session.
* `odd-platform-api/src/main/resources/application.yml:177` — `advisory-lock-id: 100` under `notifications.wal`, the operator-tunable lock id.

## See also

* [ADR-0020 — Outbound Slack delivery is decoupled via a Postgres queue](/developer-guides/architecture-decision-log/adr-0020-decoupled-outbound-slack-delivery) — the same single-leader Postgres-advisory-lock mechanism, applied to outbound delivery (distinct lock id).
* [ADR-0042 — Notification fan-out is fail-soft per channel](/developer-guides/architecture-decision-log/adr-0042-notification-fail-soft-fan-out) — keeps a bad channel from stalling this single consumer thread.
* [ADR-0044 — Postgres replication artefacts are lazy-created, never dropped](/developer-guides/architecture-decision-log/adr-0044-postgres-artefact-lazy-create-no-drop) — the slot and publication this consumer relies on.


---

[Next Page](/llms-full.txt/1)